
The whole hunk
from line 15, old and new numbered
/
lines
from line 15
1515* **Free wins** cut spend without touching quality: prompt caching, token hygiene, a prompt audit against the model you are running, [batch processing](https://platform.claude.com/docs/en/build-with-claude/batch-processing) at 50% off for work that can wait up to 24 hours, and [workspace spend limits](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the backstop.
1616* **Tradeoffs** exchange cost for intelligence: model choice, effort, output caps and task budgets, and multi-model architectures.
1717
18Each lever comes with measured results and the rule for when it pays. In Anthropic's measurements, prompt caching was the largest lever by a wide margin: it cut agent-loop cost by a factor of 2.5 to 3.7 on this guide's benchmarks and cut a small triage agent's bill by 83%, or 88% with input trimming added. The multi-model levers are narrower; a second model paid off in two shapes, an advisor and an orchestrator.
18Each lever comes with measured results and the rule for when it pays. In Anthropic's measurements, prompt caching was the largest lever by a wide margin: it cut agent-loop cost by a factor of 2.7 to 5.3 on this guide's benchmarks and cut a small triage agent's bill by 83%, or 88% with input trimming added. The multi-model levers are narrower; a second model paid off in two shapes, an advisor and an orchestrator.
1919
2020## Start here
2121
2222Match your situation to a row.
2323
24| Your situation | Do this | Where |
25| ------------------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
26| Any workload, any model | Turn on prompt caching and trim unneeded tokens; both are free | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) · [Trim tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
27| A person waits between turns | Use the 1-hour cache duration; it is cheaper once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
28| Costs are too high; quality is fine | Sweep effort down on your current model | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
29| You are not on the latest model | Upgrade; the current model solves more, usually at lower cost per solved task | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
30| You are choosing or switching models | Compare on cost per completed task, not per token | [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
31| Quality isn't good enough | If you lowered effort, restore it; otherwise try the next tier up at `low` effort | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) · [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
32| Attempts end with `stop_reason: max_tokens` | Raise `max_tokens`; 64,000 covered every turn measured and cost nothing extra per solved task | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
33| You can check outputs (tests, a verifier) | Run everything at low effort and re-run failures at the default (`high`); on the coding benchmark measured, the pass rate held at about half the cost | [Re-run failures](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
34| Agent loops with a few very costly runs | Set a task budget (beta; not currently available on Claude Sonnet 5), a Claude Managed Agents session budget, and a workspace spend limit | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
35| A lower-cost model stalls only on hard decisions | Add a frontier advisor. It pays off when priced well above the executor and actually consulted, so first price the advisor's model alone at low effort and measure the consult rate | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
36| The work exceeds one context window | Delegate partitions to cheaper workers | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
24| Your situation | Do this | Where |
25| ------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
26| Any workload, any model | Turn on prompt caching and trim unneeded tokens; both are free | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) · [Trim tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
27| A person waits between turns | Use the 1-hour cache duration once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour. On Claude Fable 5.1, keep the 5-minute cache warm while pauses run minutes, and buy the 1-hour duration when pauses run toward an hour | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
28| Costs are too high; quality is fine | Sweep effort down on your current model | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
29| You are not on the latest model | Upgrade; the current model solves more tasks, at a cost per solved task from about 40% lower to about 20% higher | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
30| You are choosing or switching models | Compare on cost per completed task, not per token | [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
31| Quality isn't good enough | If you lowered effort, restore it; otherwise try the next tier up at `low` effort | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) · [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
32| Attempts end with `stop_reason: max_tokens` | Raise `max_tokens`; 64,000 covered all but 2 of 14,000 turns measured at the default effort, and 128,000 cost nothing extra per solved task | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
33| You can check outputs (tests, a verifier) | Run everything at low effort and re-run failures at the default (`high`); on the coding benchmark measured, the pass rate held at about half the cost | [Re-run failures](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
34| Agent loops with a few very costly runs | Set a task budget (beta; check the support table for which models), a Claude Managed Agents session budget, and a workspace spend limit | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
35| A lower-cost model stalls only on hard decisions | Add a frontier advisor. It pays off when priced well above the executor and actually consulted, so first price the advisor's model alone at low effort and measure the consult rate | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
36| The work exceeds one context window | Delegate partitions to cheaper workers | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
3737
3838These results are Anthropic-internal ([Benchmarks referenced](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs)) and directional, not guarantees, so measure on your own workload with the [four-step method](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#measure-on-your-own-workload).
3939
from line 49
4949
5050**What good looks like.** Over a full day of real traffic, agent loops read a median 84% of their input from the cache, and the top 10% of harnesses, coding or not, read 94% or more[17](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Deep in a task, a well-built loop pays full price on under 1% of its input. Below about 80%, look for something breaking the cache (see [What breaks the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#what-breaks-the-cache)).
5151
52Across Anthropic's measured runs, cache reads are routinely the largest single component of task cost, making caching worth more than most model-choice decisions. Anthropic priced WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) and DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) runs with and without caching:
52Across Anthropic's measured runs, cache reads are routinely the largest single component of task cost, making caching worth more than most model-choice decisions. Anthropic priced the DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) runs with and without caching:
5353
54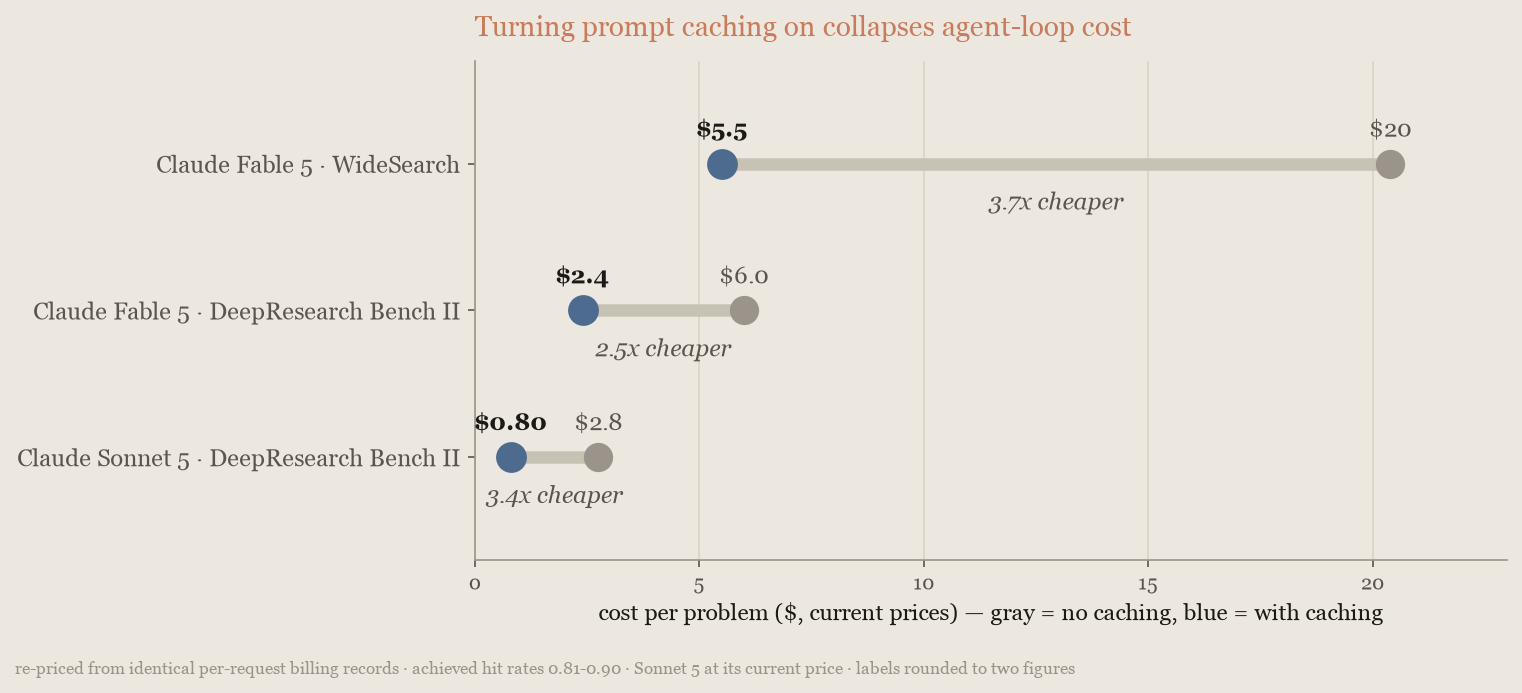
54
5555
56The cache's default lifetime is 5 minutes and an agent loop's turns are seconds apart, so the discount applies to most tokens on every turn. The caching chart's runs achieved 81% to 90% hit rates. The saving varies with episode depth, because shorter loops re-read less, but caching stayed the largest single lever on every model and benchmark measured.
56The cache's default lifetime is 5 minutes and an agent loop's turns are seconds apart, so the discount applies to most tokens on every turn. The caching chart's runs read 79% to 90% of their input tokens from the cache. The saving varies with episode depth, because shorter loops re-read less, but caching stayed the largest single lever on every model and benchmark measured.
5757
5858#### Pick the cache duration
5959
from line 63
6363
6464* More than about 1 gap in 20 falls between 5 minutes and an hour, and gaps over an hour are rare: use the 1-hour duration.
6565* Turns arrive seconds apart: stay on the 5-minute default. When nothing paused, it cost 15% less than the 1-hour setting on Claude Sonnet 5 and 11% less on Claude Opus 5.
66* Gaps over an hour are common: stay on the default. A gap over an hour expires both durations, and the 1-hour setting then re-writes the prefix at 2x the input price instead of 1.25x, so it loses on each of those gaps. It pays off only when, beyond the 1-in-20 share, gaps between 5 minutes and an hour are at least about two-thirds as frequent as gaps over an hour (each in-band gap saves about 1.15x the prefix; each gap over an hour costs about 0.75x).
66* Gaps over an hour are common: stay on the default. A gap over an hour expires both durations, and the 1-hour setting then re-writes the prefix at its higher write price, so it loses on each of those gaps. Of your pauses longer than 5 minutes, if about 60% or more also run past an hour, stay on the default; the 1-hour duration pays only when at least about 40% of long pauses end within the hour.
6767
68Anthropic measured the triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) with pauses inserted before some turns to simulate a person's delay[16](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). On both models measured, the 1-hour cache became the cheaper setting once about 1 turn in 30 followed a pause, so the 1-in-20 rule leaves a margin, and the gap widens quickly past the crossover because every paused turn on the 5-minute setting re-writes the whole prefix. Every current model uses the same cache multipliers, so the crossover is in the same range on the other models; the exact share depends on how much of a session the model re-reads. Accuracy stayed within run-to-run noise in every cell. The turn after a pause kept its warm-cache latency on the 1-hour setting. The following chart plots cost per session against the share of paused turns on Claude Sonnet 5:
68Anthropic measured the triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) with pauses inserted before some turns to simulate a person's delay[16](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). On both models measured, the 1-hour cache became the cheaper setting once about 1 turn in 30 followed a pause, so the 1-in-20 rule leaves a margin, and the gap widens quickly past the crossover because every paused turn on the 5-minute setting re-writes the whole prefix. Every current model uses the same cache-write multipliers, and every model but Claude Fable 5.1 and Claude Mythos 5.1 the same read price, so the crossover is in the same range on the other models; Fable 5.1 is the case covered next. Accuracy stayed within run-to-run noise in every cell. The turn after a pause kept its warm-cache latency on the 1-hour setting. The following chart plots cost per session against the share of paused turns on Claude Sonnet 5:
6969
7070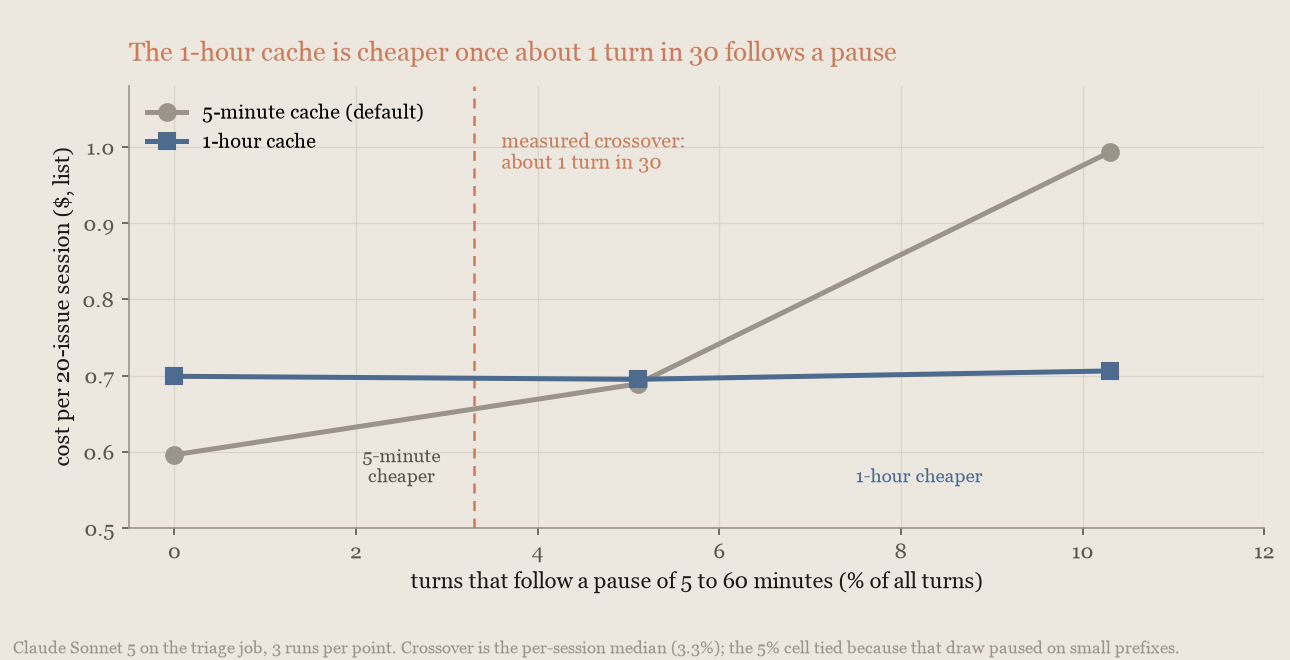
7171
72Anthropic also measured extra requests that keep the 5-minute cache warm. They saved nothing measurable over the 1-hour duration at any share of paused turns and cost more with a pause before every turn, so use the duration instead.
72Anthropic also measured extra requests that keep the 5-minute cache warm. On Claude Sonnet 5 and Claude Opus 5 they saved nothing measurable over the 1-hour duration at any share of paused turns and cost more with a pause before every turn, so use the duration instead.
7373
74On Claude Fable 5.1 the cheapest setting is a different one. Its [cache read](https://platform.claude.com/docs/en/about-claude/pricing#prompt-caching) costs 0.025x the input price ($0.25 per million tokens) while its cache writes keep the standard multipliers, so a keep-alive request that re-reads the prefix is cheap and the 1-hour duration's write premium is the larger bill. Anthropic measured the triage job on Claude Fable 5.1 with the same three settings[19](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Keeping the 5-minute cache warm cost 13% to 20% less per session than the 1-hour cache whenever pauses ran for minutes; only with pauses near 45 minutes did the 1-hour cache win, by about 12 cents a session. On Claude Fable 5.1, keep the 5-minute cache warm while a person is away for minutes, and buy the 1-hour duration when pauses run toward an hour:
75
76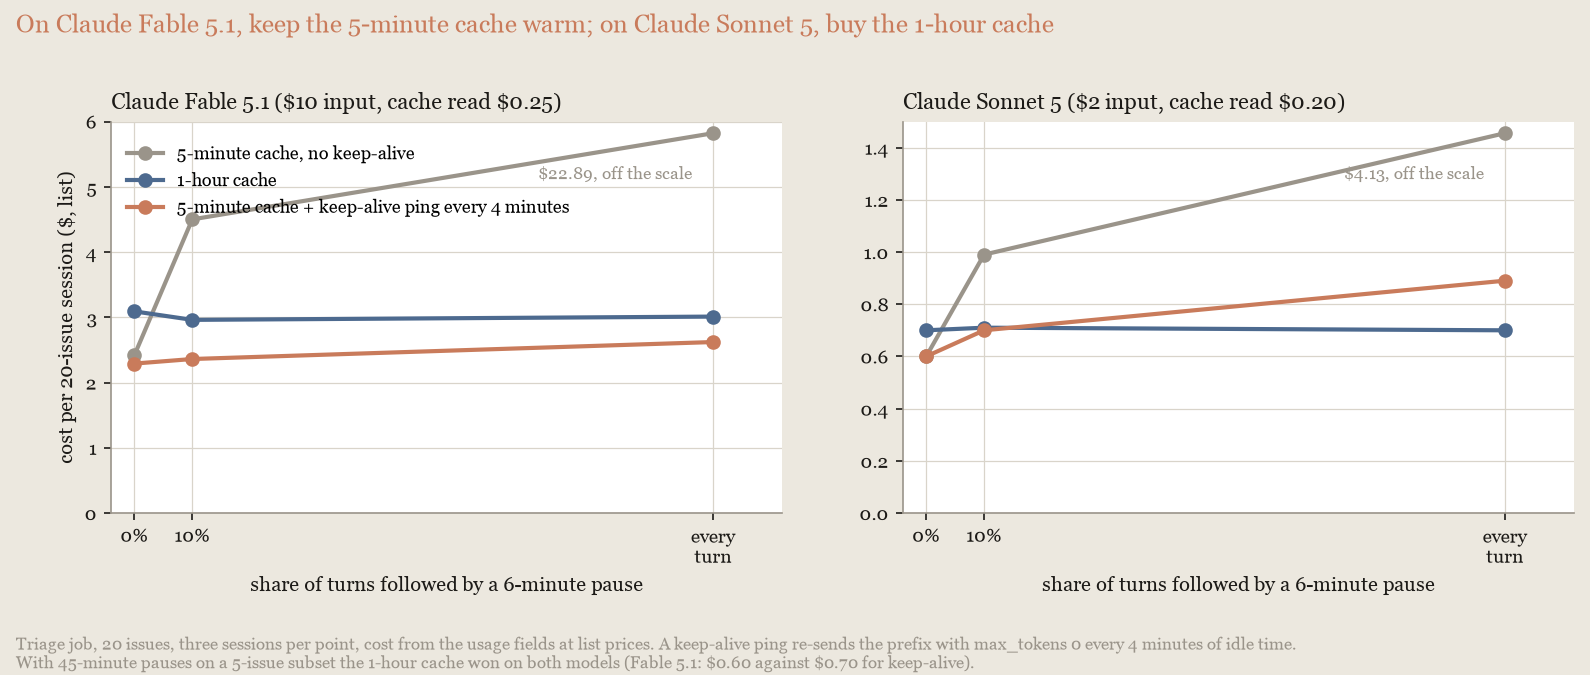
77
78To keep the cache warm, send the previous request again with `max_tokens` set to 0 within 4 minutes of the previous request's start, and every 4 minutes after that, dropping `stream` if it was set. Count from the request's start, not its response's end: the [cache's 5-minute lifetime](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#how-prompt-caching-works) runs from the start of the request that wrote or refreshed the entry, so time the response spent generating counts against it. That is the [pre-warming request](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#pre-warming-the-cache): it refreshes the cache's lifetime, generates nothing, and bills only the cache read. Do not change a byte of the prefix, and do not use `max_tokens: 1`, which samples a token for no reason. Re-send the request's headers as well as its body: if your requests carry an `anthropic-beta` header (for a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets), say), the keep-alive request needs the same header, or the beta-gated fields in the replayed body are rejected. A `max_tokens: 0` request is rejected when the request sets `thinking.type: "enabled"` (the default adaptive thinking on Claude Fable 5.1 is fine), structured outputs, or a forced tool choice ([its limitations](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#limitations)); on those workloads, buy the 1-hour duration instead.
79
80<CodeGroup exclude="shell:CLI, python, typescript, csharp, go, java, php, ruby">
81 ```bash cURL
82 # Within 4 minutes of the last request's start (time spent generating counts
83 # against the cache's lifetime), re-send that request with max_tokens set to
84 # 0, dropping stream (a max_tokens: 0 request cannot stream). Send the same
85 # headers as the original request, including any anthropic-beta header.
86 jq '.max_tokens = 0 | del(.stream)' last_request.json | \
87 curl https://api.anthropic.com/v1/messages \
88 -H "x-api-key: $ANTHROPIC_API_KEY" \
89 -H "anthropic-version: 2023-06-01" \
90 -H "content-type: application/json" \
91 --data-binary @-
92 ```
93</CodeGroup>
94
7495#### Turn on caching
7596
7697Setup takes little work. [Automatic caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#automatic-caching) places breakpoints for you; otherwise, the [Claude API skill](https://platform.claude.com/docs/en/agents-and-tools/agent-skills/claude-api-skill) that ships with Claude Code can add caching to an existing integration from one prompt. The following excerpt shows the skill adding it to the harness that produced these measurements:
from line 121
100121
101122Several things can break your cache during a task. Anything that changes per request, such as a timestamp or a queue position, placed ahead of the stable prefix turns every request into a full cache write: on the triage run in [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), a 25-token status line at the front of the system prompt cost $4.24 per run instead of $0.59, more than running with caching off. Keep per-request text in the newest user turn.
102123
103The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On Claude Opus 5 (and Claude Fable 5, Claude Mythos 5, and Claude Opus 4.8), change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. The same page covers mid-conversation tool changes, in beta on those models. Otherwise, make such changes only where you would re-cache anyway, such as at a [compaction](https://platform.claude.com/docs/en/build-with-claude/compaction) boundary, and on the first request after the compaction rather than the one that triggers it.
124The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On the most recent models, change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. Check that page for which models support it. On models that support it, a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) leaves the cached prefix intact too. The stakes are highest on Claude Fable 5.1 and Claude Mythos 5.1: a break re-writes the prefix at 1.25x the input price instead of reading it at 0.025x, so on a 100,000-token prefix one broken turn costs $1.25 instead of $0.03, 50 times the read, against 12.5 times ($0.63 instead of $0.05) on Claude Opus 5.
104125
105126Anthropic measured this on the triage agent's long sessions[18](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). An effort change and an added tool made mid-session rewrote 39,000 and 60,000 cached tokens, and those sessions cost $0.95 per session. The same two changes on the first request after compaction cost $0.75, and on the request that triggered the compaction $0.92, because the compaction's summarization pass then re-processed the 81,000-token context at the cache-write price: that summarization pass cost $0.21, against $0.04 when the same changes came one request later, with accuracy within run-to-run noise in every arm:
106127
107128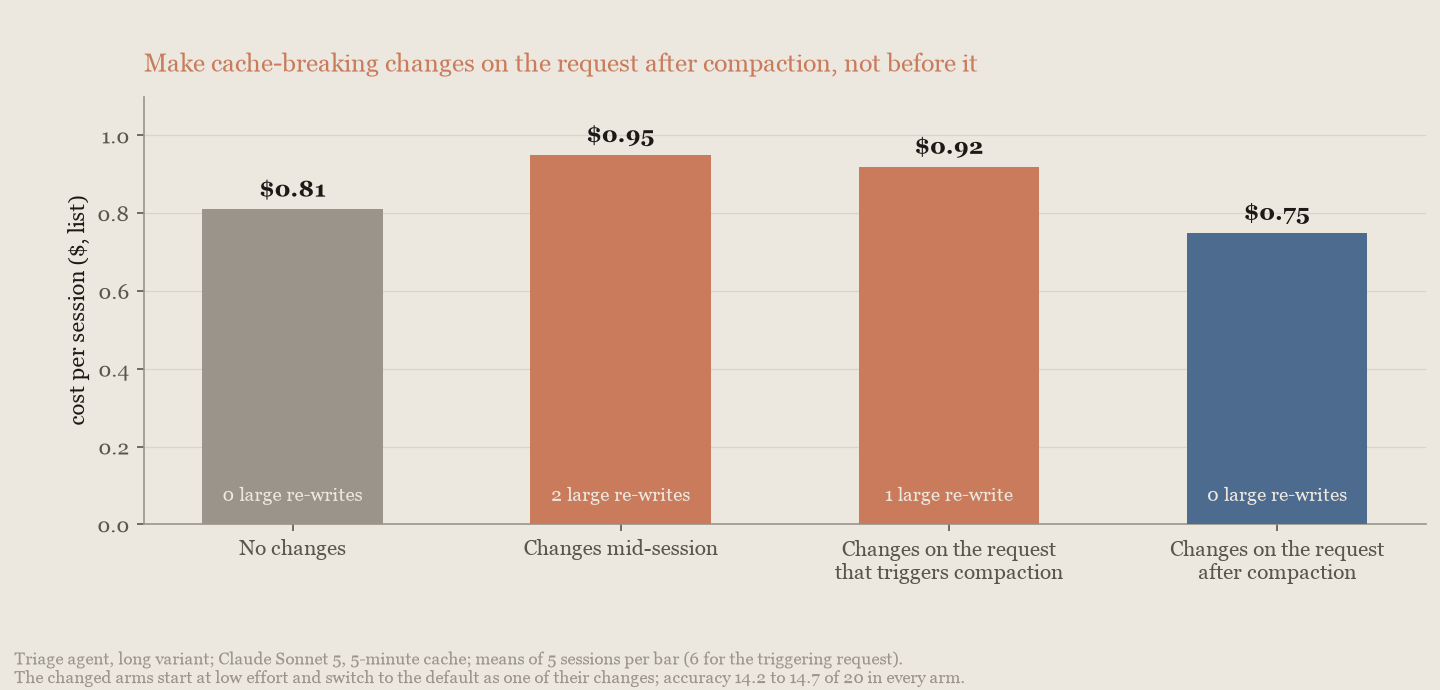
108129
109Changing a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) partway through invalidates any cached prefix that contains the budget value, so set it once, on the first request. Every [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching) pass invalidates the prefix from the point it clears and the next request pays to re-cache everything after it, so clear in a few large batches rather than many small ones. Make every cache-invalidating change at natural breaks, then confirm cache reads have not dropped; if they have, [cache diagnostics](https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics) shows where the prefix diverged.
130Changing a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) partway through invalidates any cached prefix that contains the budget value, so set it once, on the first request. Every [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching) pass invalidates the prefix from the point it clears and the next request pays to re-cache everything after it, so clear in a few large batches rather than many small ones. On Claude Fable 5.1 and Claude Mythos 5.1 each of these costs 50 times the read price per token, so they matter most there. Make every cache-invalidating change at natural breaks, then confirm cache reads have not dropped; if they have, [cache diagnostics](https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics) shows where the prefix diverged.
110131
111132### Trim input and context tokens
112133
113Most agent requests carry tokens that never influence the answer. Trimming them costs nothing in output quality, although not every lever here saved money when measured. Two places to look:
134Most agent requests carry tokens that never influence the answer. Trimming them rarely costs output quality, although not every lever here saved money when measured. Two places to look:
114135
115136* **Input trimming.** [Dynamic filtering](https://platform.claude.com/docs/en/agents-and-tools/tool-use/web-fetch-tool#dynamic-filtering) in the web fetch tool keeps boilerplate out of fetched pages, [image resizing](https://platform.claude.com/docs/en/build-with-claude/vision#evaluate-image-size) right-sizes vision inputs, and [tool search with deferred loading](https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool) loads tool definitions only when needed (measured later in this section). [Programmatic tool calling](https://platform.claude.com/docs/en/agents-and-tools/tool-use/programmatic-tool-calling) lets Claude run several tool calls from code so only the filtered result enters the context; its documentation reports 24% fewer input tokens on agentic search benchmarks, with a higher score. [Manage tool context](https://platform.claude.com/docs/en/agents-and-tools/tool-use/manage-tool-context) compares tool search, programmatic tool calling, prompt caching, and context editing.
116137* **Context lifecycle.** [Context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing) clears stale tool results, and [automatic compaction](https://platform.claude.com/docs/en/build-with-claude/compaction) with its threshold stops long loops from carrying their whole history forward.
from line 144
123144
124145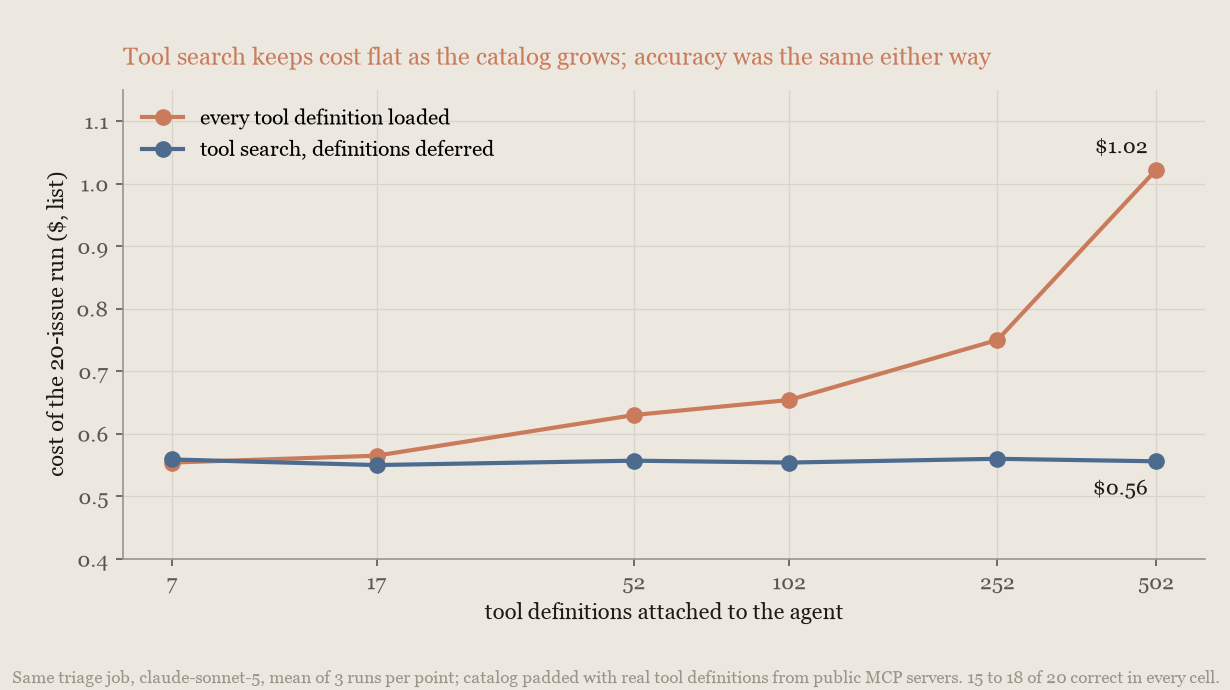
125146
126With every definition loaded, the run cost rose from $0.55 to $1.02, tracking the schema tokens on each request. With tool search, it stayed at $0.56 at every catalog size, 45% less at 502 tools. Accuracy was 15 to 18 of 20 in every cell either way, and the model never called a wrong tool, so at this scale the catalog costs money, not correctness. The same holds for tools that come through the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector): with a public GitHub MCP server attached, deferring its toolset (`default_config: {defer_loading: true}`) cut the run 20% at the same accuracy.
147With every definition loaded, the run cost nearly doubled as the catalog grew, tracking the schema tokens on each request. With tool search it stayed flat at every catalog size, 45% less at 502 tools. Accuracy was 15 to 18 of 20 in every cell either way, and the model never called a wrong tool, so at this scale the catalog costs money, not correctness. The same holds for tools that come through the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector): with a public GitHub MCP server attached, deferring its toolset (`default_config: {defer_loading: true}`) cut the run 20% at the same accuracy.
127148
128149#### Keep data files out of the prompt
129150
from line 152
131152
132153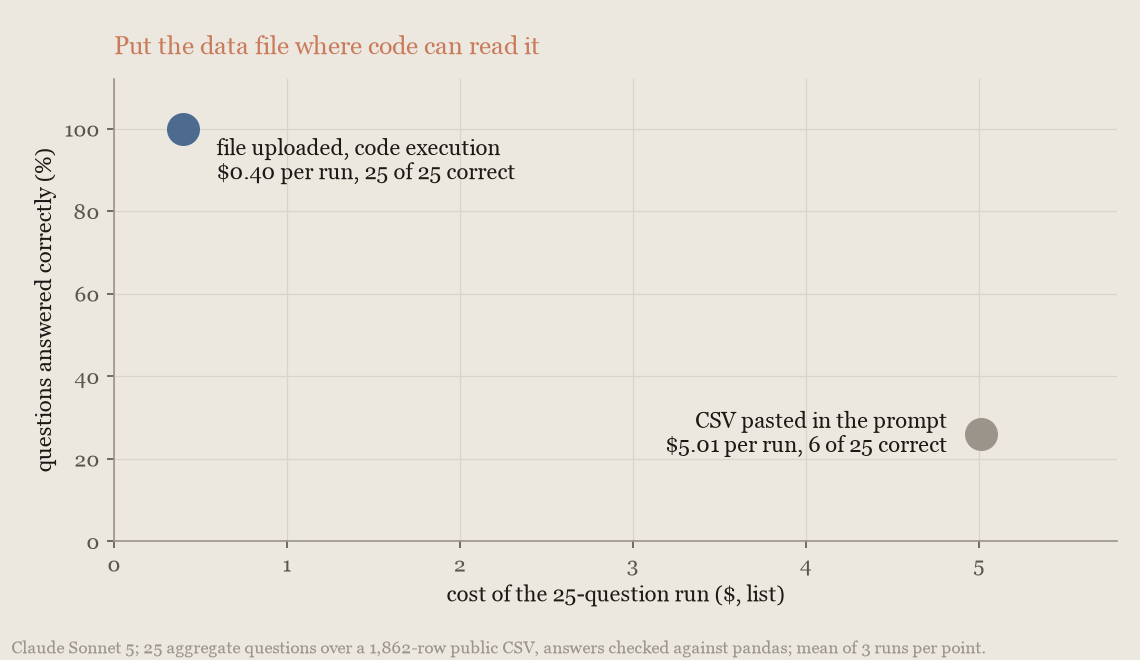
133154
134Pasted into the prompt, the table is about 91,000 input tokens on every request, and Claude Sonnet 5 answered 6 of 25 questions correctly at $5.01 per run. Uploaded, with code execution, it answered 25 of 25 at $0.40. Claude Opus 5 showed the same pattern (6 of 25 at $13.45 against 25 of 25 at $1.91).
155Pasted into the prompt, the table is about 91,000 input tokens on every request, and Claude Sonnet 5 answered 6 of 25 questions correctly. Uploaded, with code execution, it answered all 25, and the run cost about a twelfth as much. Claude Opus 5 showed the same pattern.
135156
136157#### Manage the context lifecycle
137158
138The context levers are where the two runs diverge:
159The context levers only pay on a session long enough to need them:
139160
140161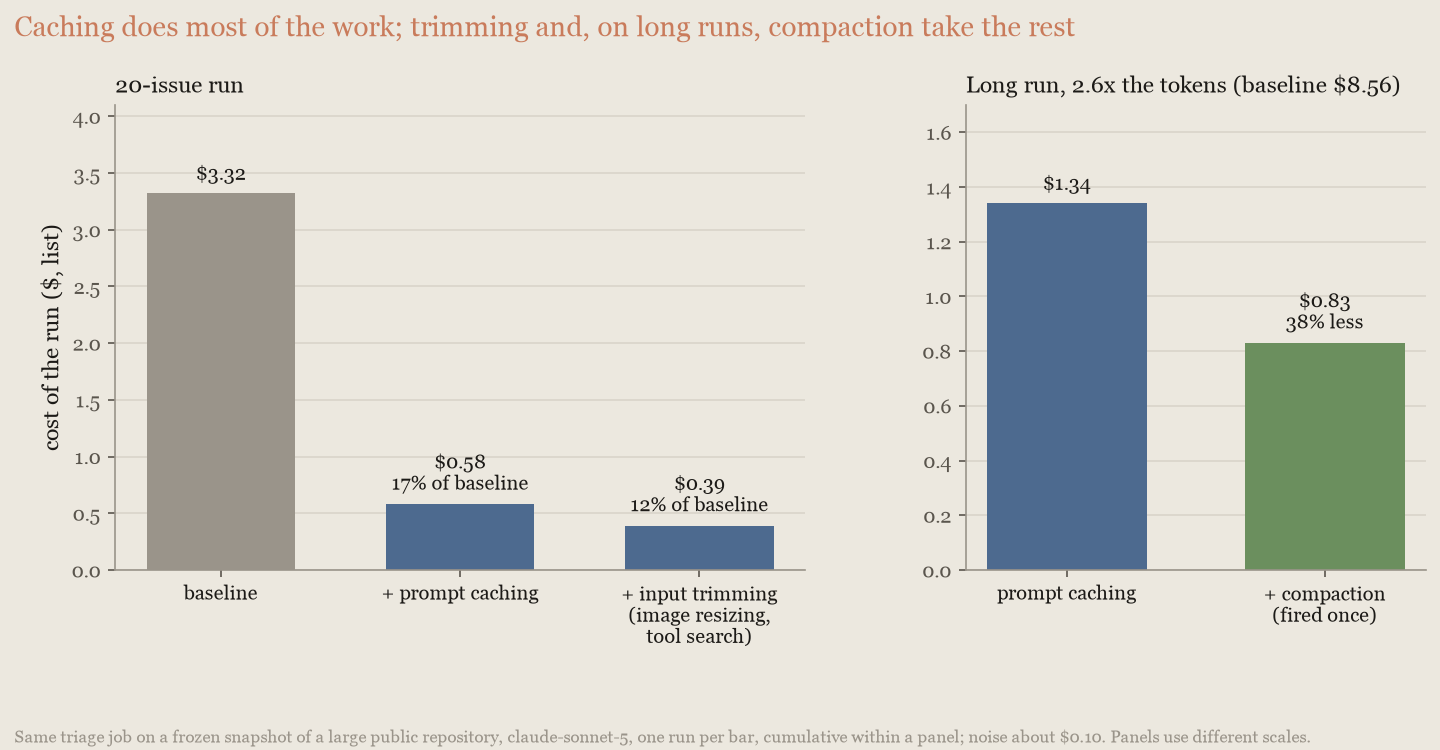
141162
142The context levers only pay on a session long enough to need them. On the 20-issue run, context editing cost 74% more, and compaction and the prune changed nothing. On the long run, context editing changed nothing, compaction saved 32%, and the prune saved 39%. The prune is a few lines you write yourself: at each task boundary, replace large stale tool results with a one-line extract. It caches well because the edits sit at the tail of the conversation, where the next task adds new content anyway: 89% cache reads on the first request after a boundary and 81% on the requests between boundaries. Run-wide, the prune and context editing cache equally well. The prune is cheaper because context editing rewrites content mid-task that the prune deletes (about two thirds of the gap) and because it keeps the context about half the size (the other third). If you use context editing, [clear in a few large batches](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching). The prune, adapted from the harness:
163On the 20-issue run they saved nothing, and context editing cost 74% more. On the long run the prune saved 39% and compaction 32%, while context editing changed nothing. The prune is a few lines you write yourself: at each task boundary, replace large stale tool results with a one-line extract. It caches well because the edits sit at the tail of the conversation, where the next task adds new content anyway: 89% cache reads on the first request after a boundary and 81% on the requests between boundaries. Run-wide, the prune and context editing cache about equally well. The prune is cheaper because context editing rewrites content mid-task that the prune deletes (about two thirds of the gap) and because it keeps the context about half the size (the other third). If you use context editing, [clear in a few large batches](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching). The prune, adapted from the harness:
143164
144165```python
145166import re
from line 237
216237
217238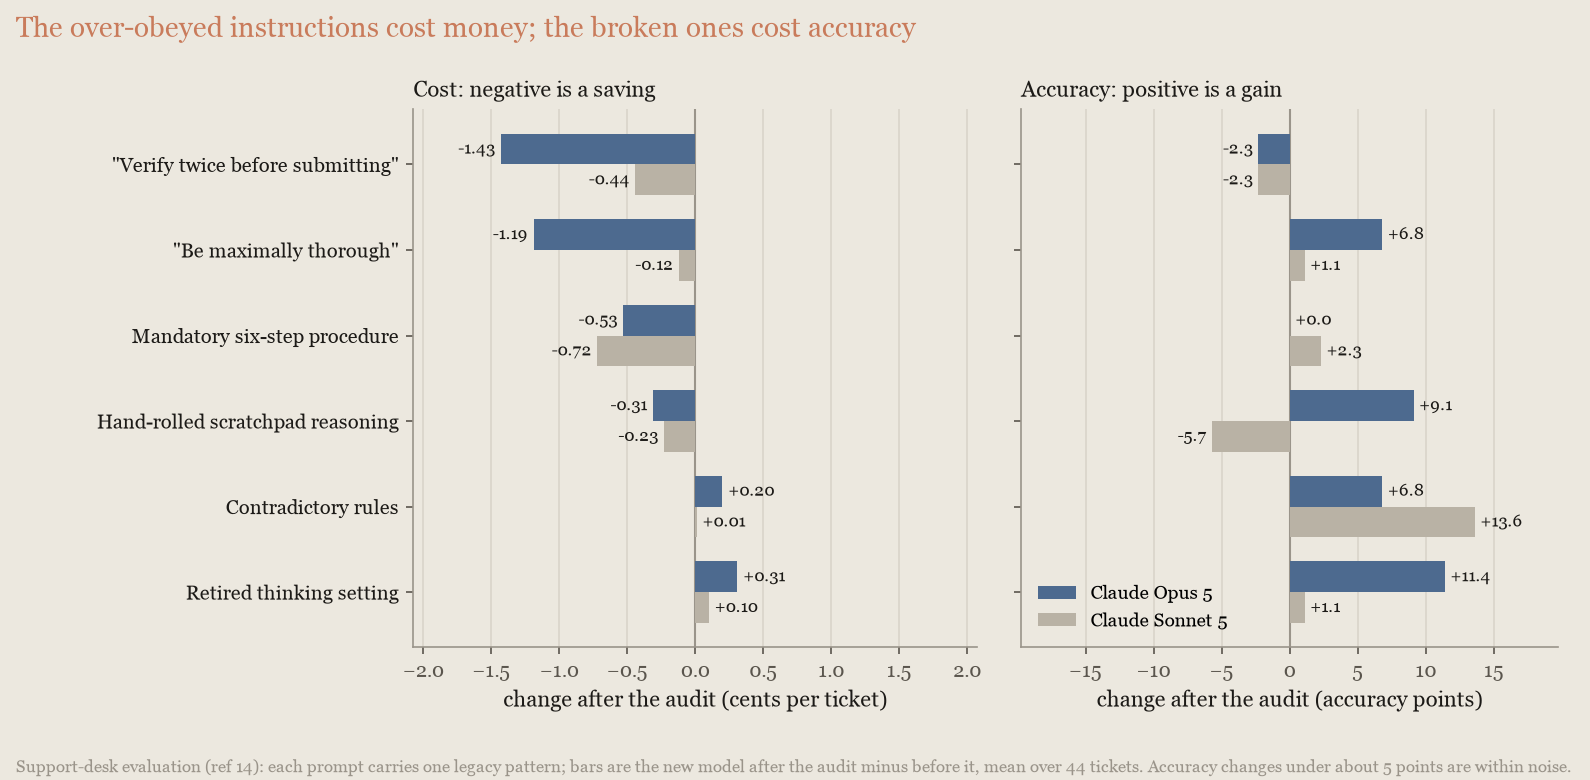
218239
219The same patterns appear in tool descriptions and skills, and are worth removing there too.
240The same patterns tend to appear in tool descriptions and skills, which are worth auditing too.
220241
221242## Trade cost against intelligence
222243
223These levers set where a single model sits between cost and intelligence: model choice, effort, re-running failures at a higher setting, and the budgets and caps it works within. Start with an effort sweep on your current model ([Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort)). From lowest to highest cost and capability, the current models are Claude Haiku 4.5, Claude Sonnet 5, Claude Opus 5, and Claude Fable 5 (the frontier model); [Models overview](https://platform.claude.com/docs/en/models/overview) has the full lineup and prices.
244These levers set where a single model sits between cost and intelligence: model choice, effort, re-running failures at a higher setting, and the budgets and caps it works within. Start with an effort sweep on your current model ([Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort)). From lowest to highest cost and capability, the current models are Claude Haiku 4.5, Claude Sonnet 5, Claude Opus 5, and Claude Fable 5.1 (the frontier model); [Models overview](https://platform.claude.com/docs/en/models/overview) has the full lineup and prices.
224245
225246### Compare models on cost per task
226247
227Price lists are written per token, and per token the frontier model looks expensive: Claude Fable 5's per-token price is several times Claude Sonnet 5's. You pay for completed tasks, though, so compare models on cost per completed task. A more capable model finishes a task with less work: fewer turns, less searching, less re-reading of its own context, and less backtracking. The per-token premium is routinely overwhelmed by doing less of everything.
248Price lists are written per token, and per token the frontier model looks expensive: Claude Fable 5.1's per-token price is several times Claude Sonnet 5's. You pay for completed tasks, though, so compare models on cost per completed task. A more capable model finishes a task with less work: fewer turns, less searching, less re-reading of its own context, and less backtracking. The per-token premium is often overwhelmed by doing less of everything.
228249
229Anthropic measured this directly on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a research-report benchmark hard enough to separate the models:
250Anthropic measured this on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, priced as a customer is billed:
230251
231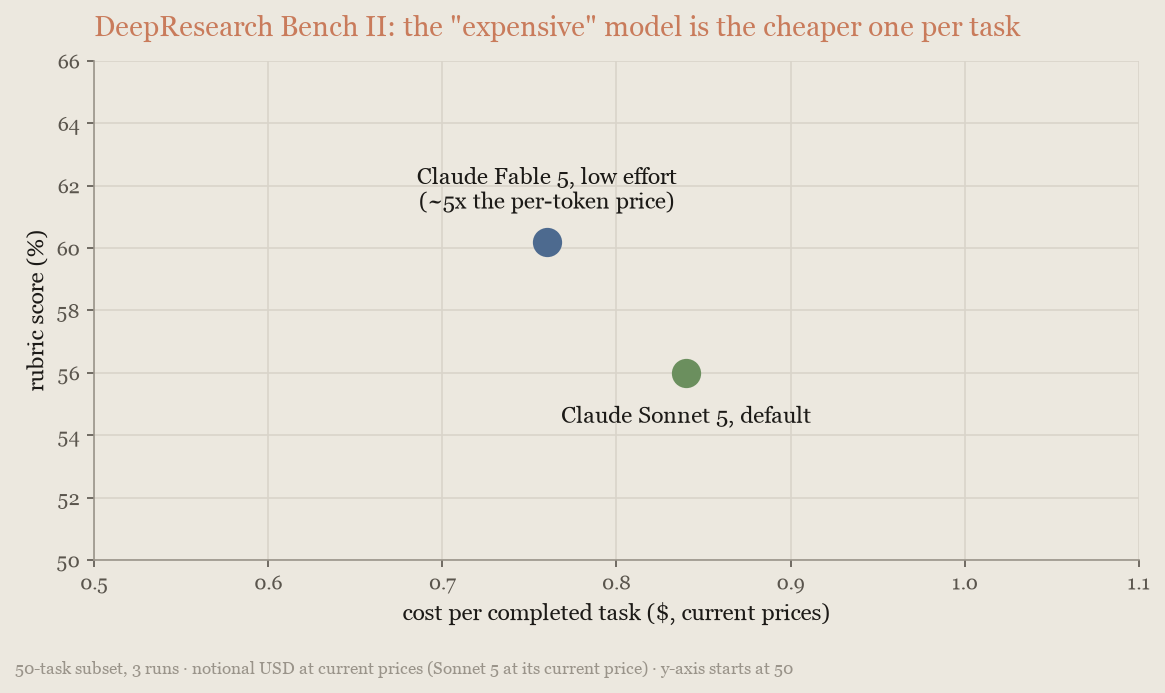
252
232253
233The frontier model at `low` effort was more accurate and about 10% cheaper per task than the mid-tier model, despite the per-token gap. It does not always win, though. On this page's SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, which both models largely saturate and whose scores are not comparable to the public leaderboard, Claude Opus 5 alone matched Claude Fable 5 alone (91.7% compared with 91.3%, inside run-to-run noise) at about 60% of its cost. On harder work, such as the DeepResearch Bench II tasks, Fable's advantage reappears.
254Claude Fable 5.1 at `low` effort solved 88.6% of tasks for $0.54 per solved task, against 77.4% for $0.84 from Claude Sonnet 5 at its default: 11 more points for 35% less per solved task, despite a per-token price five times higher. It does not always win, though. On the same subset, which both models largely saturate and whose scores are not comparable to the public leaderboard, Claude Opus 5 alone matched Claude Fable 5.1 alone at the default (91.7% compared with 92.1%, inside run-to-run noise) at about 15% less per solved task ($1.01 against $1.19), and Opus 5 at `low` solved 84.0% for $0.25. And on long research loops the frontier model does more work, not less: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Fable 5.1 at `low` scored 10 points above Sonnet 5 (66% against 56%) at about four times the cost per task ($4.66 against $1.20), because it runs a longer research loop over a larger context. Claude Opus 5 at its default scored 71% on the same basis for $6.71 per task, above Fable 5.1 at its default (65% for $7.12), so on research too Fable 5.1 earns its price only at `low`.
234255
235For most agent workloads, start with Claude Opus 5: per token it costs half what Fable 5 does and 2.5 times what Sonnet 5 does, and on that coding subset it matched Fable's accuracy. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a tenth of Opus 5's cost per question, with 63% accuracy compared with 92% for Opus, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
256For most agent workloads, start with Claude Fable 5.1 at `low` effort and raise effort where it misses. Per token it costs twice what Claude Opus 5 does on uncached input, but half as much on cached input ($0.25 against $0.50 per million), and in an agent loop cached input is the largest term. On the coding benchmark in [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions), Fable 5.1 at `medium` matched Opus 5 at its default for about a third of the cost per attempt ($2.91 against $8.50). On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a chart-reading benchmark, Fable 5.1 at `low` scored 62.5 for $0.15 a chart, compared with 49 for $0.38 from Opus 5 at `low`. On the SWE-bench Pro subset, Claude Opus 5 at its default remains the cheaper way to the top score, as noted earlier. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a tenth of Opus 5's cost per question, with 63% accuracy compared with 92% for Opus, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
236257
237258The ranking flips by workload, and no price list tells you which way. Price every candidate in cost per completed task on your own traffic, including Claude Opus 5 and the frontier model at reduced effort.
238259
from line 265
244265
245266### Upgrade the model
246267
247If you are a model or two behind, the cheapest lever is the model string. Anthropic ran recent Claude Opus and Claude Sonnet models through the same harness on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, each at its shipped defaults, and priced each at list rates:
268If you are a model or two behind, the cheapest lever is the model string. Anthropic ran recent Claude Opus, Claude Sonnet, and Claude Fable models through the same harness on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, each at its shipped defaults and priced at list rates, and ran the Opus line again on Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs):
248269
249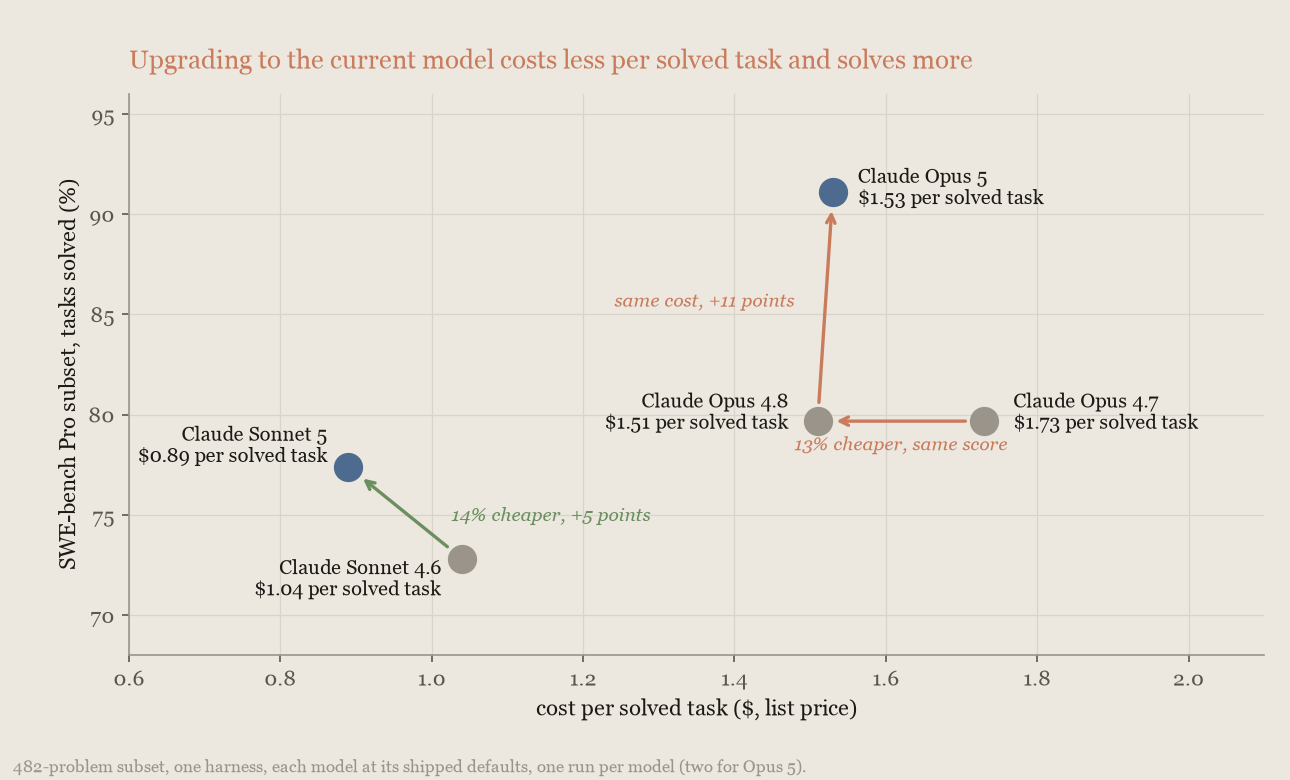
270
250271
251Anthropic prices the Opus line identically per token across versions, so any saving comes from efficiency: Opus 4.8 takes fewer turns and rereads less than Opus 4.7, so each solved task costs 13% less, and Opus 5 then solves 11 more points of tasks at the same cost. Sonnet 5's savings come from its lower per-token price, which more than offsets the extra tokens it uses per task compared with Sonnet 4.6.
272Anthropic prices the Opus line identically per token across versions, so any difference comes from how much work each model does per task: priced as a customer is billed, Claude Opus 4.8 solves the same share of tasks as Claude Opus 4.7 for 14% less per solved task, and Claude Opus 5 then solves 12 more points of tasks at 21% more per solved task. Claude Opus 5 at `low` effort beats Opus 4.8's default on this benchmark for about 30% of its cost per solved task, so the cheapest upgrade is the new model at a lower setting. Sonnet 5's saving comes from its lower per-token price, which more than offsets the extra tokens it uses per task compared with Sonnet 4.6: 15% less per solved task for 5 more points. The frontier tier gained the same way: Claude Fable 5.1 matches Claude Fable 5's score for 43% less per solved task, most of it the lower cache-read price. That direction is not guaranteed: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same upgrade costs 41% more per task at `high` (79% more at `low`) for its 2 to 3 extra points on the tasks clean in every arm (reference 7), because the new model does more work per task there. The input and output prices are the same and the cache read is 4x cheaper, so measure the upgrade on your own workload before assuming it saves.
252273
274On harder work the gap widens. On Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), where the tasks are hard enough that pass rate rather than tokens sets the bill, Claude Opus 4.7, Opus 4.8, and Opus 5 each spend $8 to $15 per task but solve 7%, 15%, and 41% of tasks, so cost per solved task falls from $183 to $63 to $28 up the ladder. The 21% premium Claude Opus 5 carries over Opus 4.8 on the saturated coding subset becomes a 56% saving on Terminal-Bench 3, where the older model mostly fails: the more your workload defeats the old model, the more the upgrade saves per result.
275
253276Compare on cost per solved task, not per token: the same text costs about 30% more tokens on Claude Opus 4.7 and later, so a per-token comparison makes the newer models look more expensive by construction.
254277
255278### Tune effort
from line 279
256279
257280Effort is the most direct way to tune a model to your task. The `effort` parameter governs how much thinking, tool calling, and self-verification the model does, and the default (`high`) suits demanding tasks. Cost scales with all that activity; accuracy scales only with the part your task needs. Below the model's ceiling, the highest effort levels pay for depth the task never uses.
258281
259On the research and knowledge-work benchmarks (WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), DeepWideSearch[6](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and GDPval[2](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), all with Claude Fable 5), the curve of accuracy against cost is nearly flat: `low` gave up 1 to 3 points for a third to a half off the cost per task, `medium` matched the default's accuracy at 70% to 85% of its cost, and the default bought nothing measurable over `medium` on any of the four. On DeepWideSearch, `low` also matched an orchestrator with a Claude Sonnet 5 worker at 20% lower cost: lowering effort beat an architecture change.
282On the research and knowledge-work benchmarks (WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), DeepWideSearch[6](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and GDPval[2](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), all with Claude Fable 5), the curve of accuracy against cost is nearly flat: `low` gave up 1 to 3 points for a third to a half off the cost per task, `medium` matched the default's accuracy at about 70% to 87% of its cost, and the default bought nothing measurable over `medium` on any of the four. On DeepWideSearch, `low` also matched an orchestrator with a Claude Sonnet 5 worker at 29% lower cost: lowering effort beat an architecture change.
260283
261Lower settings are also faster, which matters when latency is the constraint. In these runs, `low` took 4.5 minutes per problem on DeepWideSearch, compared with 7.9 minutes at the default. On the [corpus benchmark](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work), whose input does not fit in any single context window, Fable 5 took 7.9, 9.1, and 11.4 hours per episode at `low`, `medium`, and the default.
284Lower effort settings are often faster, which matters when latency is the constraint. In these runs, `low` took 4.5 minutes per problem on DeepWideSearch, compared with 7.9 minutes at the default. On the [corpus benchmark](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work), whose input does not fit in any single context window, Fable 5.1 took 15.2, 17.5, and 19.9 hours per episode at `low`, `medium`, and `high`.
262285
263Long-horizon coding is the other shape. On SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Opus 5 gave up about 2 points at `medium` for half the cost and about 8 points at `low` for a quarter of it: a real tradeoff, which [re-running failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) turns back into a saving. This chart plots accuracy against cost for the research and knowledge-work benchmarks and for SWE-bench Pro:
286Long-horizon coding is where effort genuinely buys accuracy. On SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Opus 5 gave up about 2 points at `medium` for half the cost and about 8 points at `low` for a quarter of it: a real tradeoff, which [re-running failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) turns back into a saving. This chart plots accuracy against cost for the research and knowledge-work benchmarks and for SWE-bench Pro:
264287
265288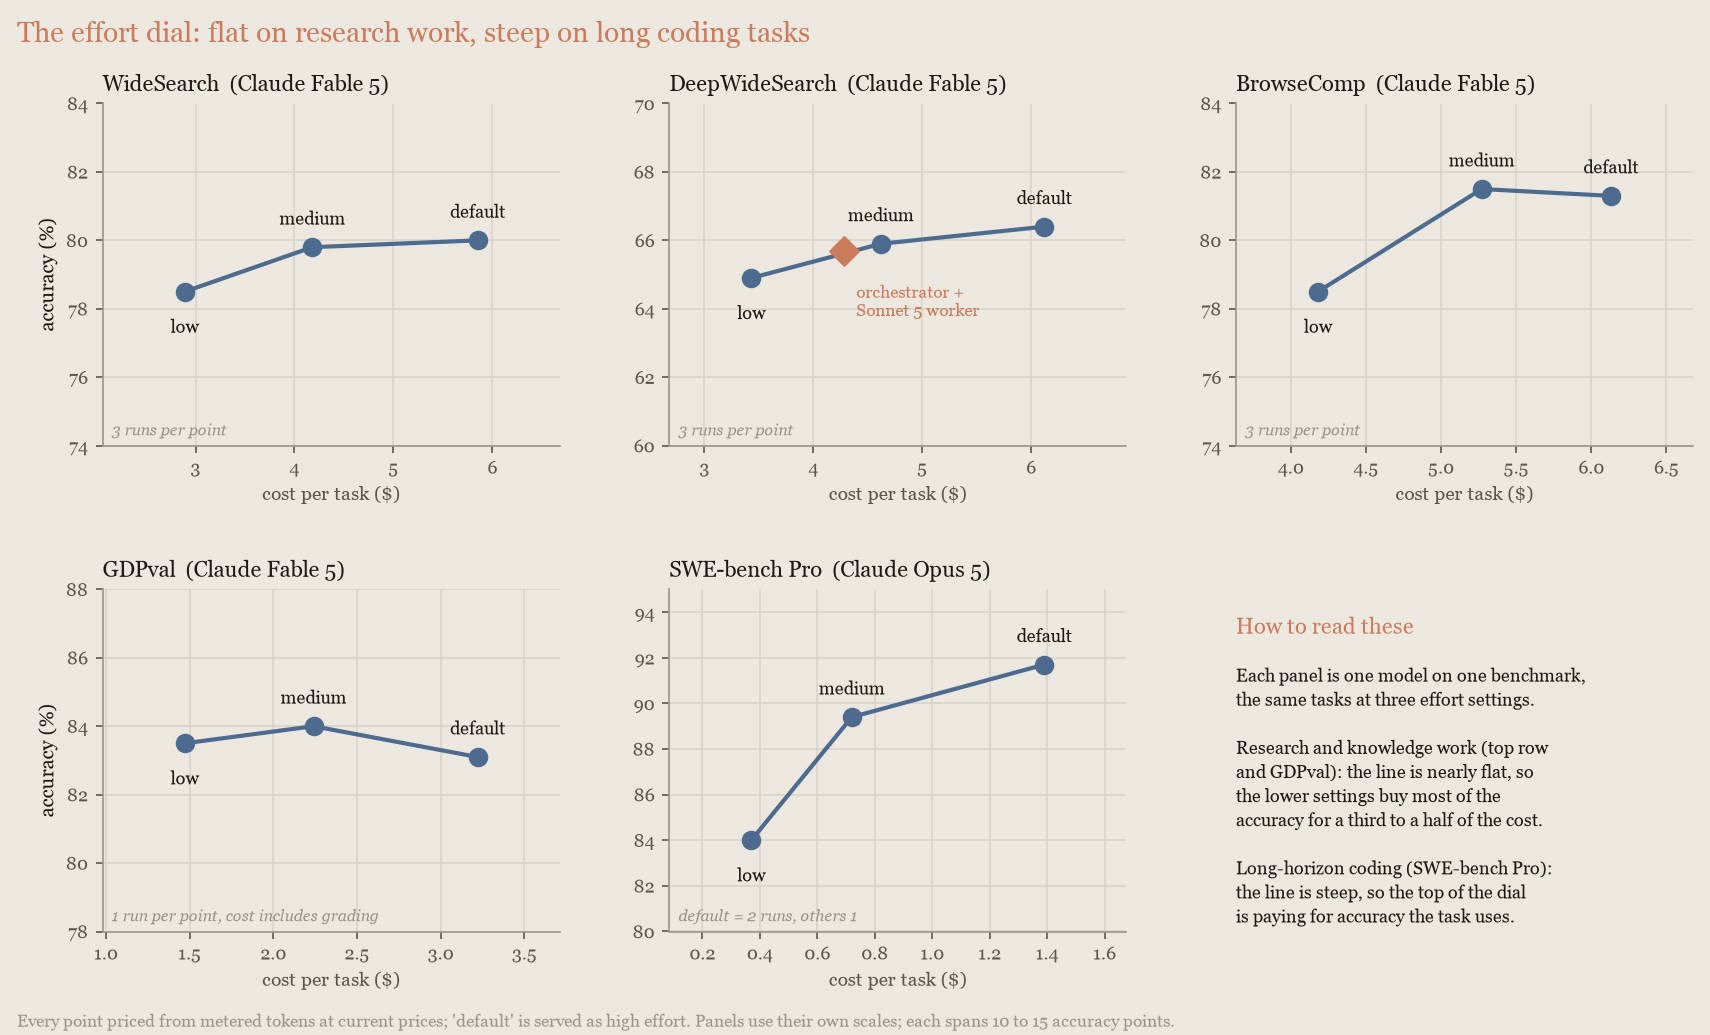
266289
267290Two consequences follow. First, draw this curve for your own workload before you add a second model: in these internal measurements, a multi-model configuration that looked cheaper than the default single model cost more than that same model at lower effort. Second, this curve is the single-model baseline any multi-model strategy must beat, so [step 2 of measuring on your own workload](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#measure-on-your-own-workload) baselines across effort levels.
268291
269Lower effort does cost accuracy on workloads that reach the model's ceiling, where accuracy genuinely scales with reasoning depth. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), where each report rewards deep reasoning per subtopic, every effort step bought about 2.4 points of rubric score; there is no free cost cut on that curve:
292Hard work does not automatically need high effort. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Fable 5.1 scored nearly the same at `low`, `medium`, and `high` while the cost per task rose from $4.66 to $7.12, so raising the effort in this case does not increase the quality of the output noticeably; on the 21 tasks clean in every arm (reference 7), Claude Fable 5 was flat across effort too, though the chart's 33-task basis, which drops each model's own cut-short attempts, shows it climbing. Measure the curve on the model you ship, not the one you measured last:
270293
271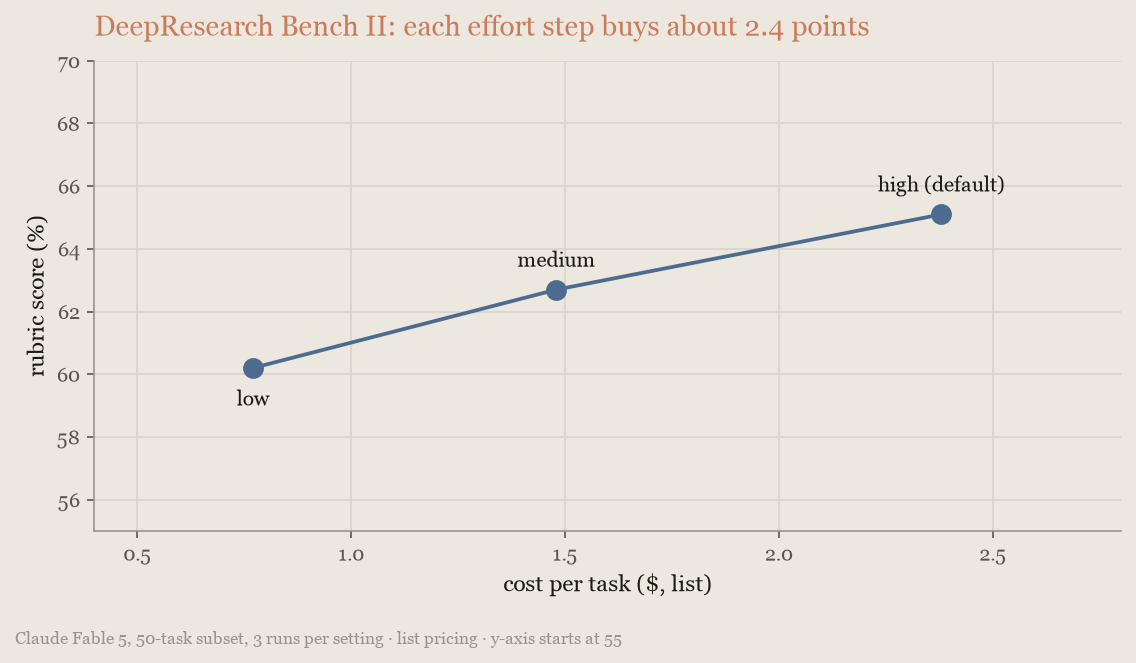
294
272295
273The task description alone does not reveal which kind of workload you have, so sweep two or three effort levels on a sample of your own traffic and read the answer off the curve. Test each level in a separate session: changing effort mid-session invalidates the cache (see [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context)) and distorts the comparison. For parameter details, see [Effort](https://platform.claude.com/docs/en/build-with-claude/effort).
296The task description alone does not reveal which kind of workload you have, so sweep two or three effort levels on a sample of your own traffic and read the answer off the curve. Test each level in a separate session: changing top-level effort mid-session invalidates the cache (see [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context)) and distorts the comparison. For parameter details, see [Effort](https://platform.claude.com/docs/en/build-with-claude/effort).
274297
275298### Re-run failures at higher effort
276299
277300When a task's outcome is checkable, the cheapest policy on the effort curve is not a fixed setting: run every task at a low setting and re-run only the failures at a higher one.
278301
279Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5 at `low`, 16% of tasks failed; with those re-run at the default, about 93% passed for about $0.70 each, against 91.7% for $1.39 running everything at the default: the same pass rate for half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 94% for about $0.95. Most of the small lift is the second attempt (re-running the default's own failures at the default scores about the same, for more money), so use this policy for the saving, not the lift:
302Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5 at `low`, 16% of tasks failed; with those re-run at the default, about 93% passed for about $0.45 each, against 91.7% for $0.93 running everything at the default: the same pass rate for half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 94% for about $0.61. Most of the small lift is the second attempt (re-running the default's own failures at the default scores about the same, for more money), so use this policy for the saving, not the lift:
280303
281304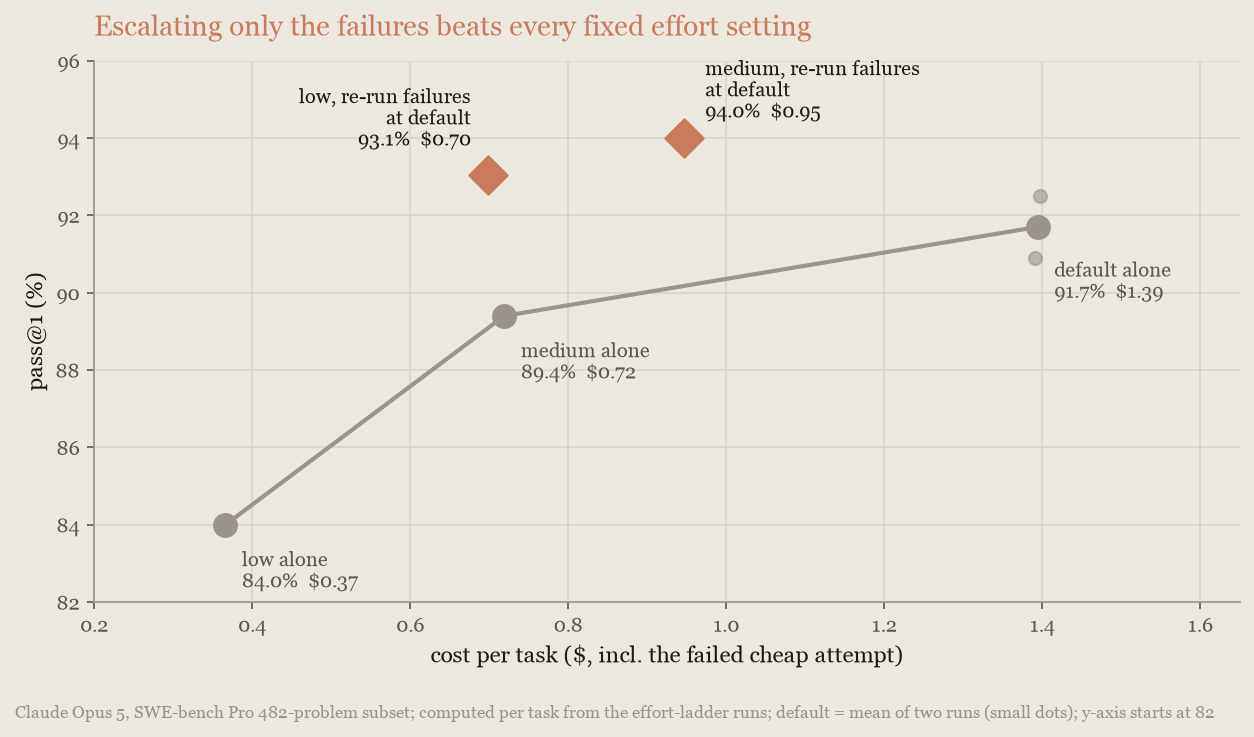
282305
from line 309
286309
287310Most agentic task runs are cheap, but a minority spend many times the median cost on searching, re-verifying, and over-testing. A [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) targets that tail. The model sees a live token countdown for the whole task and self-regulates, trimming low-value searches, skipping redundant verification, and wrapping up instead of spiraling.
288311
289Anthropic measured pass rate and cost per task on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) with Claude Fable 5 as the budget tightened:
312Anthropic measured pass rate and cost per task on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) with Claude Fable 5.1 as the budget tightened:
290313
291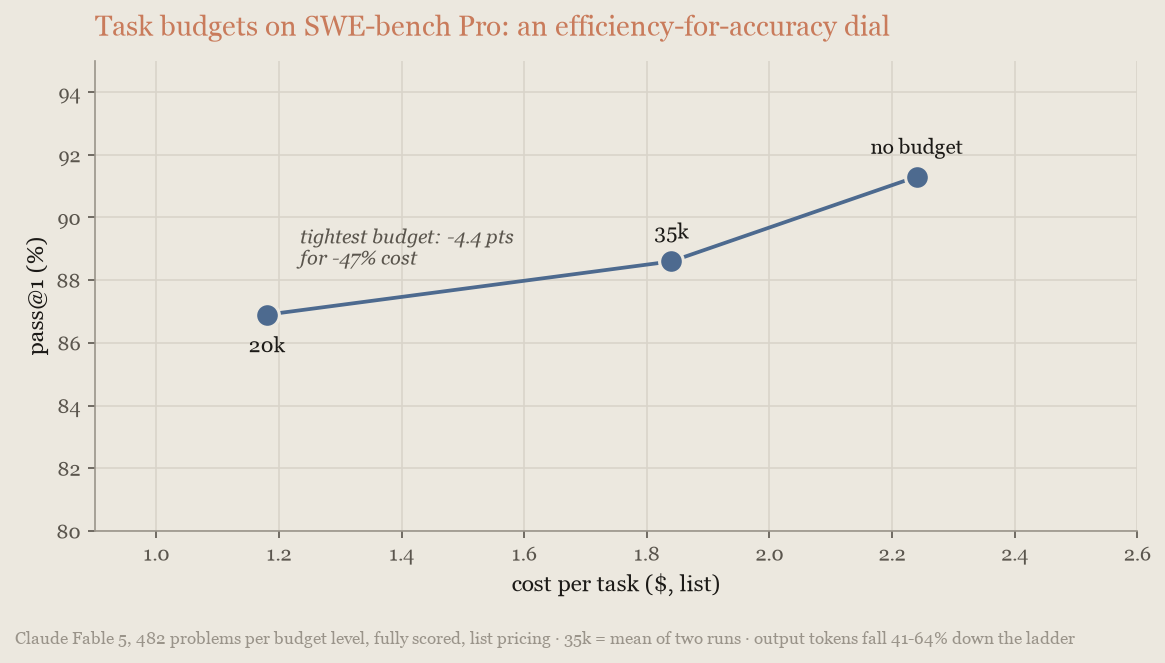
314
292315
293A generous budget gave up about 2.7 points of pass rate for an 18% cost saving, and the tightest allowed budget gave up 4.4 points for a 47% saving. Budgets bought efficiency here, not accuracy.
316A generous budget cut cost per task 44% for about 3 points of pass rate, at the edge of run-to-run noise, and the tightest allowed budget cut it 58% for 6 points. Budgets bought efficiency here, at a price in pass rate that grows as the budget tightens.
294317
295Three controls do three different jobs. A task budget saves money, because the model sees it. `max_tokens` is a safety cap that saves nothing. On Claude Managed Agents, a session budget is the hard dollar stop behind both. Set all three: a task budget, a high `max_tokens`, and a session cap for the run you never want on a bill, with a [workspace spend limit](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the final backstop.
318Three controls do three different jobs. A task budget saves money, because the model sees it. `max_tokens` is a safety cap: lowering it cut cost per attempt without lowering cost per solved task. On Claude Managed Agents, a session budget is the hard dollar stop behind both. Set all three: a task budget, a high `max_tokens`, and a session cap for the run you never want on a bill, with a [workspace spend limit](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the final backstop.
296319
297* **Task budgets** are in beta (beta header `task-budgets-2026-03-13`) on Claude Opus 5, Claude Fable 5, Claude Opus 4.8, and Claude Opus 4.7, but not Claude Sonnet 5; check the [support table](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support) first. Start near your loop's 90th-percentile token usage, then tighten ([Choosing a budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets#choosing-a-budget) shows how to collect that distribution). Budgets below the current 20,000-token floor are rejected, and very tight budgets can produce refusal-like behavior. Set the budget once, on the first request, because a mid-task change [invalidates the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context). The budget is advisory, steering the model rather than stopping it, so verify adherence on your workload.
298* **`max_tokens`** caps a single response, invisibly to the model, so lowering it does not make the model economize. The turns that needed the room are discarded and still billed. On an internal repository-task benchmark[12](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a 16,384-token cap ended 15% of Claude Opus 5's attempts and a third of Claude Fable 5's, none of them solved. Capped runs spent less per attempt but bought proportionally fewer solves, so cost per solved task was the same as at 64,000. At that setting nothing was cut off, and Fable solved 54.6% of tasks instead of 36.6% on the problems both runs scored (on a separate cut of the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, described in reference 12, 92% instead of 90%). Retrying capped attempts only adds cost: at the same cap they never succeeded, and at a higher one you also pay for the wasted attempt. Set `max_tokens` to 64,000 for agentic work (128,000, the maximum, at `xhigh` or `max` effort), [stream responses](https://platform.claude.com/docs/en/build-with-claude/streaming) that large, treat [`stop_reason: max_tokens`](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#max-tokens) as a failure, and save money with effort and task budgets, which the model can see.
299* **Session budgets on Claude Managed Agents** are the hard stop. A [session budget](https://platform.claude.com/docs/en/managed-agents/budgets) is a dollar cap on one session at list rates for tokens, searches, and session time. At the cap, the session pauses with `stop_reason: budget_reached`; raising the budget resumes it. It is platform-enforced, works on any model with a list price (including Claude Sonnet 5), and combines with the advisory task budget. Deployments apply the same field to every run.
320* **Task budgets** are in beta (beta header `task-budgets-2026-03-13`) on the most recent models; check the [support table](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support) for which. Start near your loop's 90th-percentile token usage, then tighten ([Choosing a budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets#choosing-a-budget) shows how to collect that distribution). Budgets below the current 20,000-token floor are rejected, and very tight budgets can produce refusal-like behavior. Set the budget once, on the first request, because a mid-task change [invalidates the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context). The budget is advisory, steering the model rather than stopping it, so verify adherence on your workload.
321* **`max_tokens`** caps a single response, invisibly to the model, so lowering it does not make the model economize. The turns that needed the room are discarded and still billed. On an internal repository-task benchmark[12](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a 16,384-token cap ended 15% of Claude Opus 5's attempts and 43% of Claude Fable 5.1's at the default effort, and only 9 of the 117 capped Fable attempts still passed. Capped runs spent less per attempt but bought proportionally fewer solves, so cost per solved task was about the same as at 64,000 ($21 against $22). At 64,000, 2 of about 14,000 turns at the default effort were still cut off, and Fable 5.1 solved 58.5% of tasks instead of 36.3% (on a separate cut of the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, described in reference 12, no difference: 94 of 100 at either cap). Retrying capped attempts rarely helps: at the same cap most of them fail again, and at a higher one you also pay for the wasted attempt. Set `max_tokens` to 64,000 for agentic work, or to 128,000, the maximum, when a single cut-off attempt is costly; at 128,000 Fable 5.1 solved 60.0% for the same cost per solved task. [Stream responses](https://platform.claude.com/docs/en/build-with-claude/streaming) that large, treat [`stop_reason: max_tokens`](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#max-tokens) as a failure, and save money with effort and task budgets, which the model can see.
322* **Session budgets on Claude Managed Agents** are the hard stop. A [session budget](https://platform.claude.com/docs/en/managed-agents/budgets) is a dollar cap on one session at list rates for tokens, searches, and session time. At the cap, the session pauses with `stop_reason: budget_reached`; raising the budget resumes it. It is platform-enforced, works on any model with a list price, including models where task budgets are not yet available, and combines with the advisory task budget. Deployments apply the same field to every run.
300323
301324Ask for shorter answers. Output tokens cost five times input tokens on Claude Sonnet 5, and in an agent loop every token the model writes comes back as input on every later turn, so you pay for a long answer again and again. Anthropic ran the triage job under three final-answer instructions, three runs each, with the same model and tools. The original asked for two lines:
302325
from line 350
327350
328351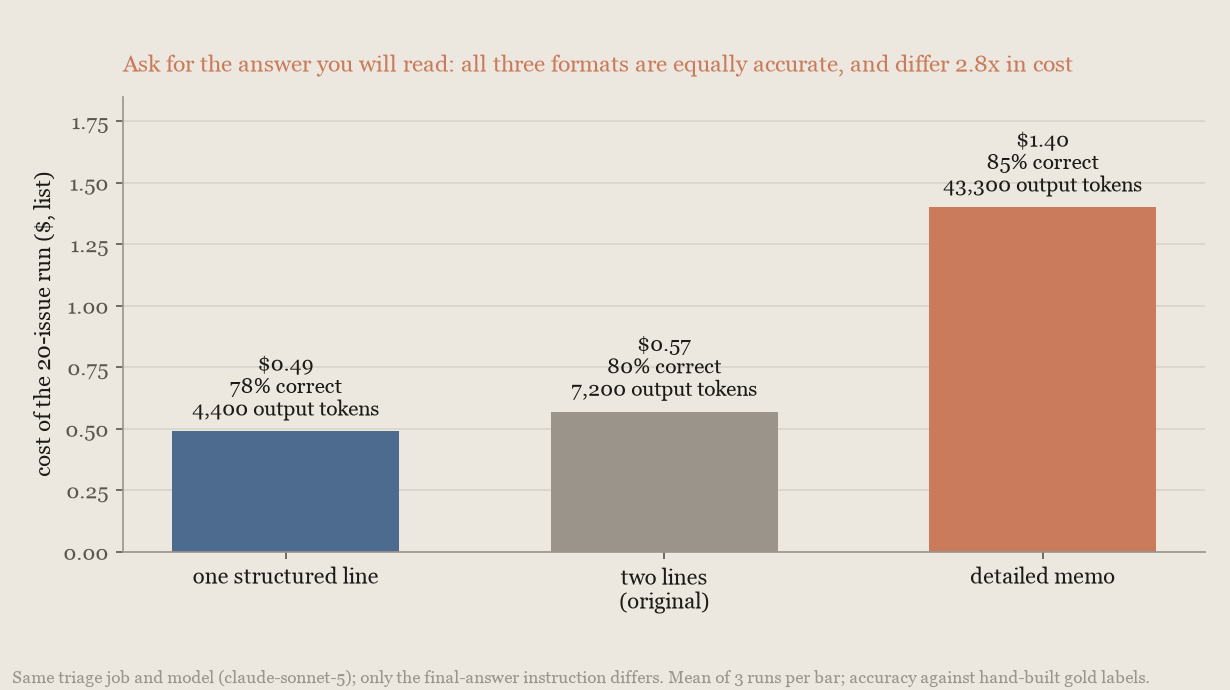
329352
330The one-line answer used 39% fewer output tokens and cost $0.49 for the run against $0.57, with the same accuracy against the gold labels (78% compared with 80%, inside run-to-run noise). The memo used six times the output tokens of the original and cost $1.40, 2.8 times the one-line answer, for 85%, also inside the noise. The three formats are equally accurate; they differ in what you pay. Ask for the answer you will read, not the one that looks thorough.
353The one-line answer used 39% fewer output tokens than the two-line original and cost 14% less per run. The memo used six times the output tokens and cost 2.8 times the one-line answer. All three scored within run-to-run noise of each other against the gold labels, so the formats differ in what you pay far more than in what they get right. Ask for the answer you will read, not the one that looks thorough.
331354
332The first of two `max_tokens` charts plots cost per attempt and per solved task at each cap:
355At the lower `max_tokens` cap both models spend less per attempt but solve proportionally fewer tasks, so cost per solved task barely moves:
333356
334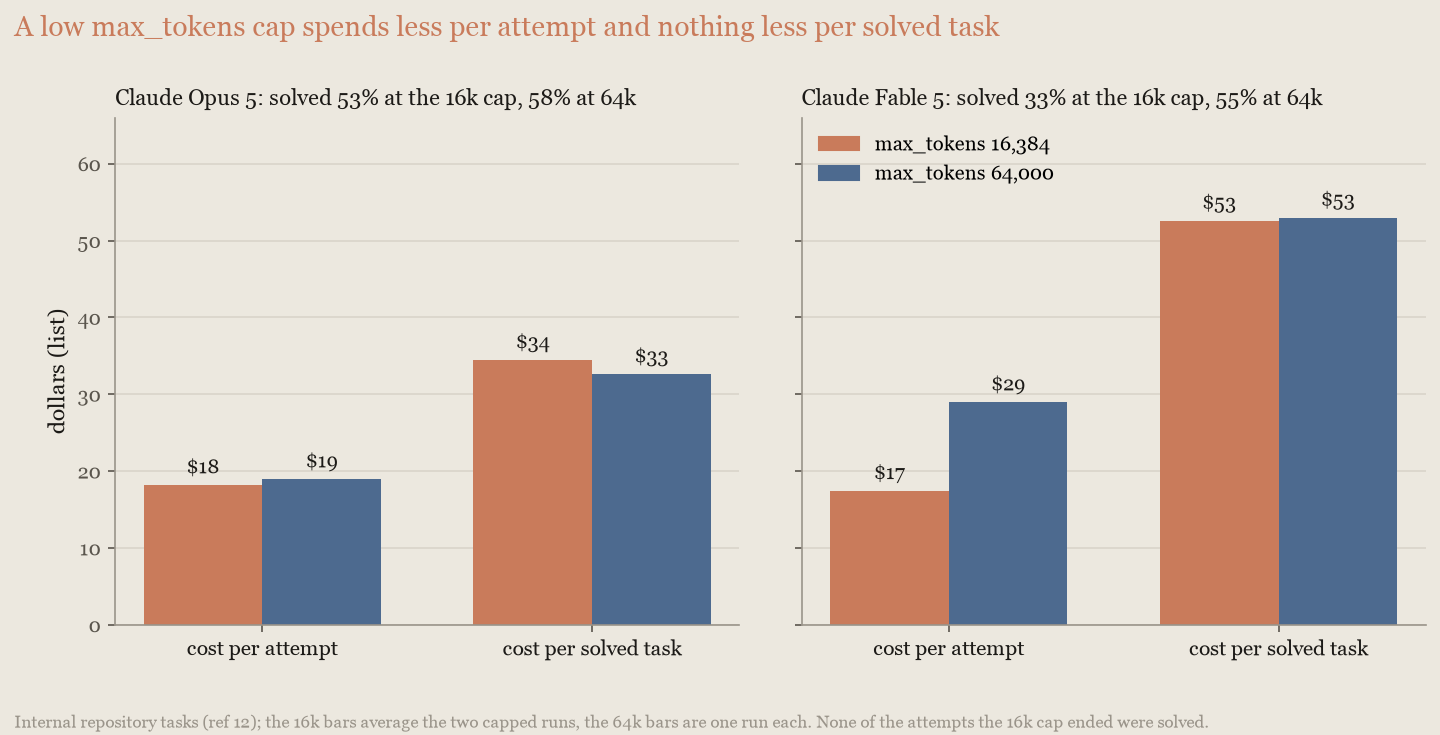
357
335358
336The second plots per-turn output length against the caps:
359Almost every turn finishes far below either cap. The rare long turn is what the higher cap buys:
337360
338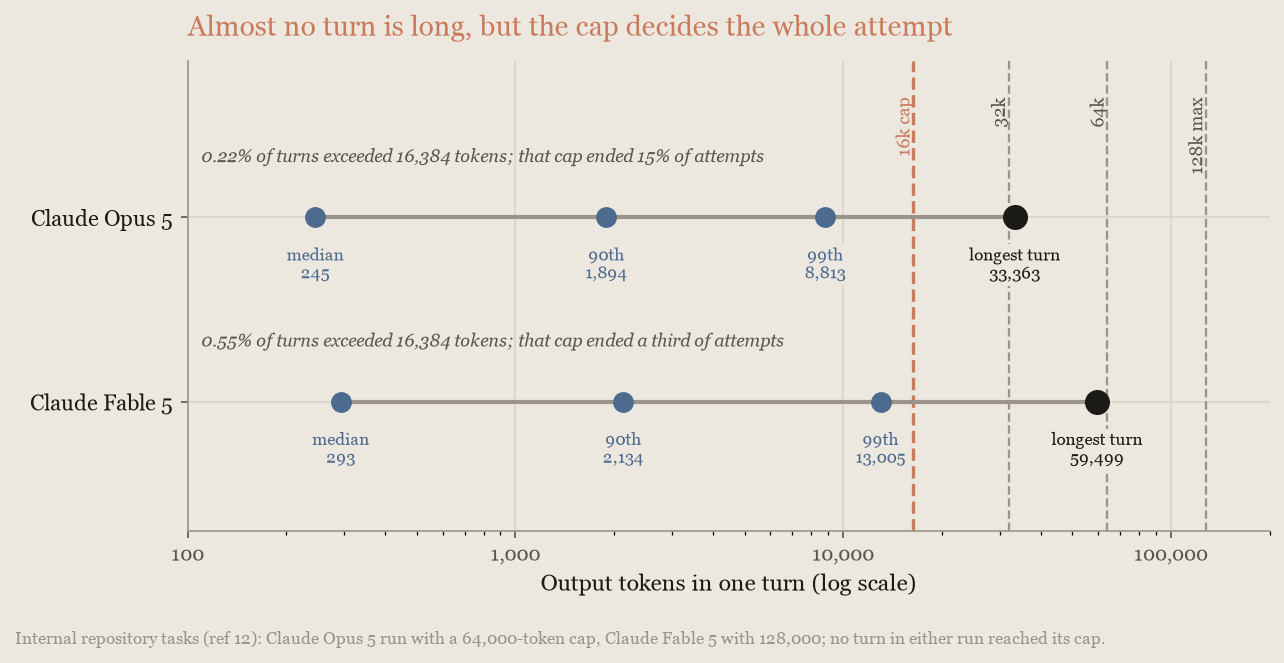
361
339362
340363## Combine models
341364
from line 377
354377
355378To use it, add the [advisor tool](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool) to your request. This beta feature runs the whole strategy server-side in one `/v1/messages` request: the executor emits a tool call, Anthropic runs the advisor inference, and the executor continues with the advice; you write no orchestration code. On Claude Managed Agents, [give the session an advisor](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration#give-the-session-an-advisor) by adding an `advisor` entry to the agent's `multiagent` roster; the session's primary thread consults it the same way. Claude Code supports it too; see [escalating hard decisions with the advisor tool](https://code.claude.com/docs/en/advisor).
356379
357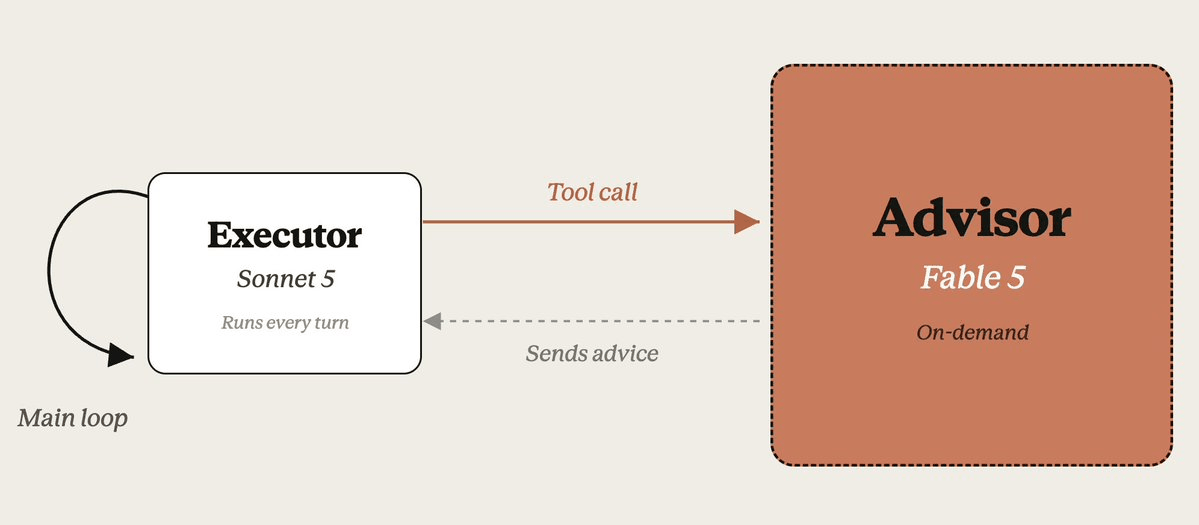
380
358381
359382**What sets the payoff.** The advisor sees the task only through the executor's calls, so two things decide how much it helps.
360383
361384The first is the gap between the models. The advisor can only hand over capability the executor lacks: on GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a Claude Haiku 4.5 executor gained a great deal from a Claude Opus 5 advisor, a Claude Sonnet 5 executor gained a few points, and a frontier executor almost nothing.
362385
363The second, and the fragile one, is whether the executor actually asks (the consult rate). An executor at low effort can stop detecting that it is stuck: a pairing that consults on most tasks at the default effort can fall to consulting on almost none when effort is lowered, and then scores below the executor alone. The rate also varies by task: on DeepSWE[10](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a low-effort Sonnet 5 executor kept asking and gained 23 points; on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same executor stopped. When the executor does ask, it recovers most of the gap. Across the pairings in the following chart, the advisor closed 50% to 90% of the gap to the stronger model and you pay for the stronger model only on the consultations, which is what makes the cost cases possible:
386The second, and the fragile one, is whether the executor actually asks (the consult rate). An executor at low effort can stop detecting that it is stuck: a pairing that consults on most tasks at the default effort can fall to consulting on almost none when effort is lowered, and then scores below the executor alone. The rate also varies by task: on DeepSWE[10](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a low-effort Sonnet 5 executor kept asking and gained 23 points; on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same executor stopped. When the executor does ask, it recovers much of the gap. Across the pairings in the following chart whose executor kept asking, the advisor closed at least half the gap to the stronger model (the coding pairing beat the stronger model outright), and you pay for the stronger model only on the consultations, which is what makes the cost cases possible:
364387
365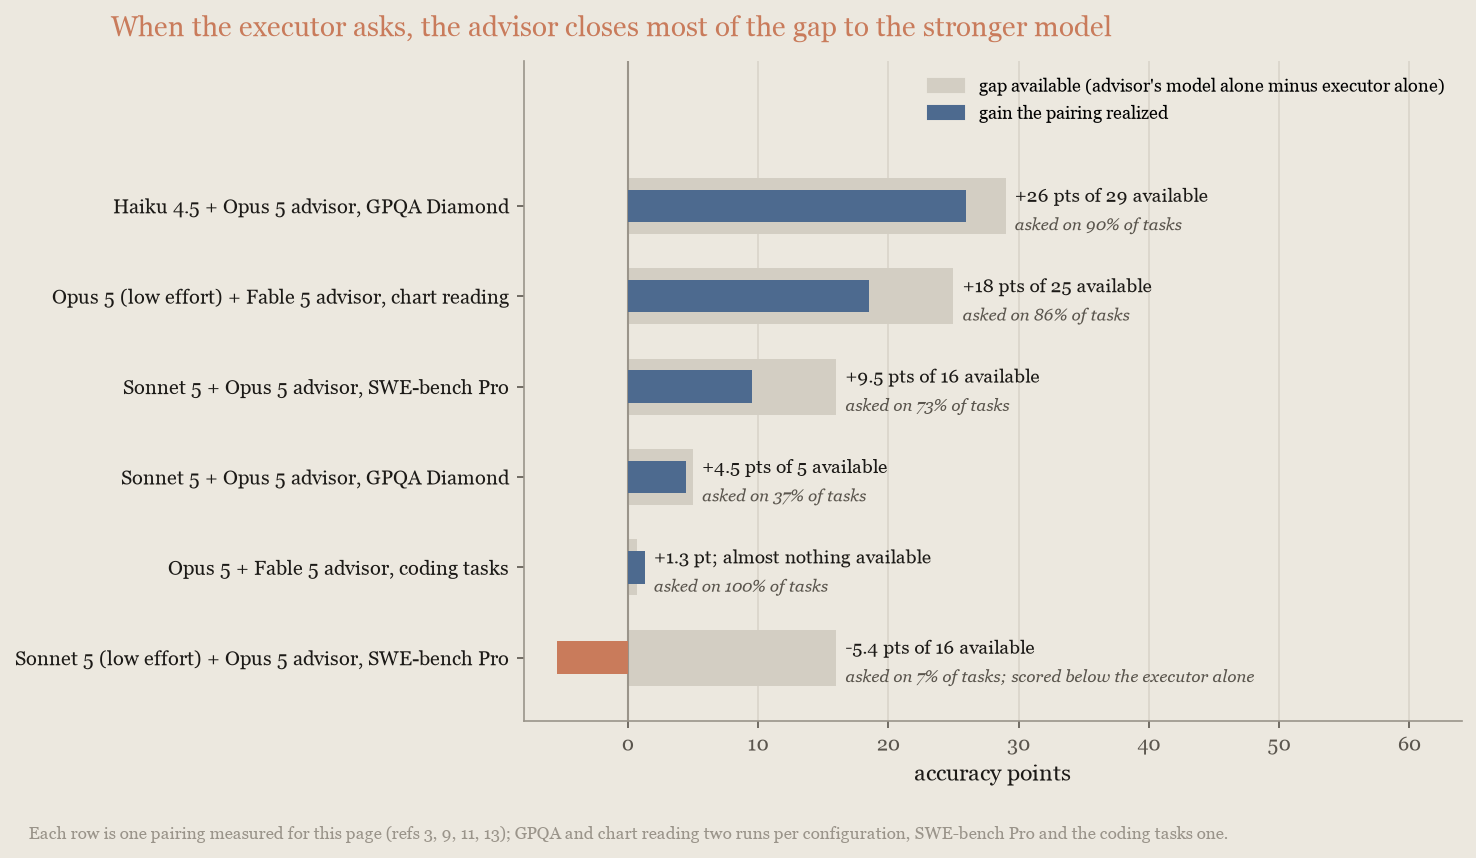
388
366389
367390The consult rate responds to prompting. With only the tool's built-in description, executors under-call, especially on coding work, so the [advisor tool documentation](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#prompting-for-coding-and-agent-tasks) gives a system prompt that asks for one call before substantive work and one before finishing, about two to three calls per task. The coding pairing measured next ran at that cadence, about two consultations on every task. That page also covers nudging an under-calling executor and capping calls client-side to bound cost. So watch the consult rate: prompt for it, measure it, and restore the executor's effort if it collapses.
368391
369392**When it pays on cost.** An advisor saves money when a few short consultations, billed at the advisor's rate, replace running the advisor's model for the whole task. That works best when the advisor's model is priced well above the executor's, so the most cost-effective configuration is a frontier advisor over a mid-tier executor. A pairing can hold its own even at the top of the range, because advice also saves executor tokens: an executor told the right approach explores fewer dead ends, which can cover the consultations.
370393
371On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5 executor with a Claude Fable 5 advisor was the most accurate configuration measured: 85.7% of attempts solved for $8.40 per attempt. It sits above the line through each model's own effort settings, but only a point or two over the best of them (Opus alone at the default setting, 84.4% for $8.50, and Fable alone at `medium`, 83.4% for $8.20), which a single run does not separate from noise. Fable alone at `medium` effort reaches about the same accuracy as the pairing (83.4% compared with 85.7%) for about the same money ($8.20 compared with $8.40 per attempt):
394On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5 executor with a Claude Fable 5.1 advisor was the most accurate configuration measured, at $7.69 per attempt. It sits above the line through each model's own effort settings: 3.5 points over Opus 5 alone at the default setting for slightly less money, a gap that five attempts per task do separate from noise, and about 2.5 points over the advisor's model alone for about half again the money:
372395
373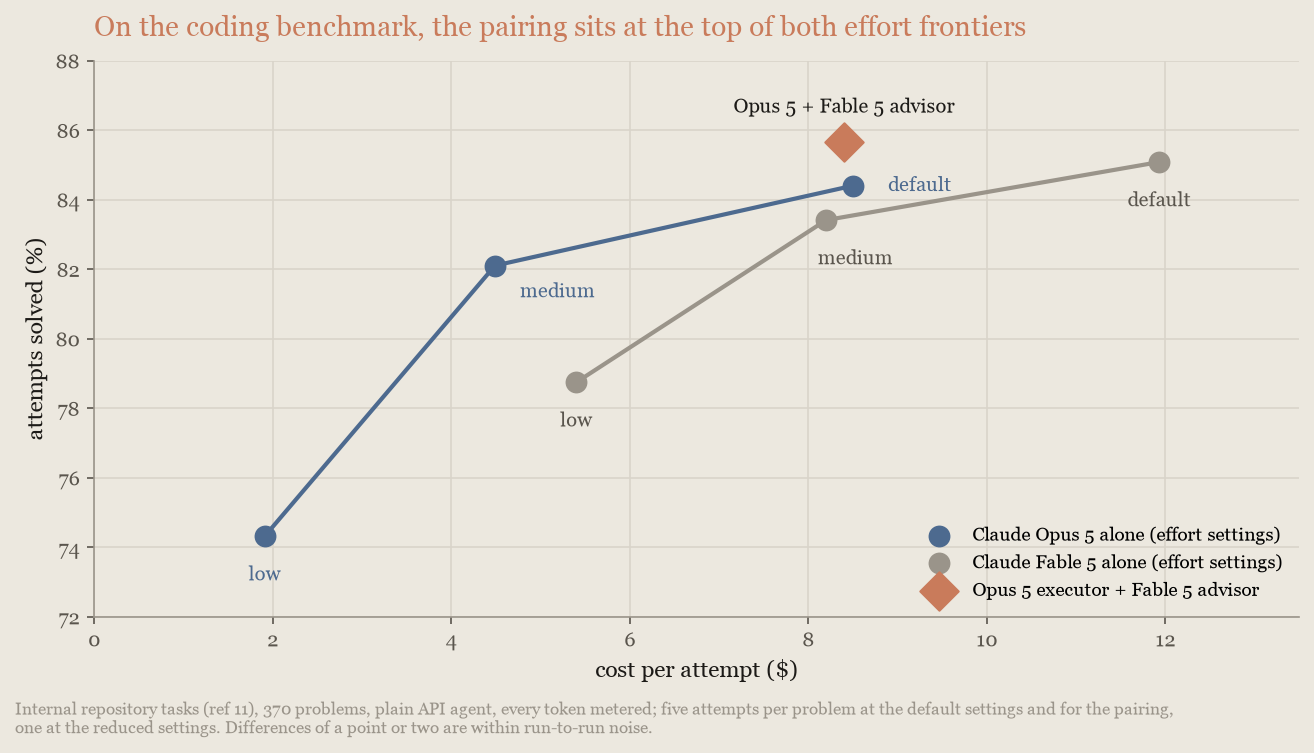
396
374397
375An earlier measurement through [Claude Code's advisor mode](https://code.claude.com/docs/en/advisor) produced the same ordering. Read this result as a shape to test on your workload, not a saving: at the top of the range the advisor buys a little accuracy at the frontier price, and the cost case belongs to pairings with a wider capability gap, such as the following chart-reading case. The latency cost is the consultations themselves: about two extra frontier-model calls per task on this benchmark, each on the task's critical path.
398An earlier measurement through [Claude Code's advisor mode](https://code.claude.com/docs/en/advisor) produced the same ordering. Read this result as a shape to test on your workload: the advisor buys a few points at about the executor's own price. A wider capability gap does not guarantee a better deal. The latency cost is the consultations themselves: about two extra frontier-model calls per task on this benchmark, each on the task's critical path.
376399
377**When it pays instead of raising effort.** Where the capability gap is wider and a workload's accuracy responds to effort, a low-effort executor that consults an advisor can be a cheaper step up than raising the executor's own effort, because the advisor is paid for only on tasks that need it.
400**When the stronger model alone is the better step.** Where a workload's accuracy responds to effort, compare the pairing with the advisor's model alone at a reduced setting before building it: the advisor is paid for only on tasks that need it, but a consult that fires on most tasks costs more than running the stronger model itself. On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same pairing matched Claude Fable 5.1 alone at `medium` within run-to-run noise (65.0 against 67.5) at about 2.6 times the cost per task, because the advisor was consulted on nearly every task. Measure your own consult rate first: if the executor asks on most of its tasks, you are paying advisor rates across the whole workload, and running the advisor's model itself is the cheaper way to the same score.
378401
379On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a public chart-reading benchmark run on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with its advisor, a Claude Opus 5 executor at `low` effort with a Claude Fable 5 advisor scored 67.5 for $0.60 per task. That is above the line through either model's own effort settings (Opus alone went from 49 to 75 between `low` and `medium` for $0.38 to $0.94), although the executor's own `medium` and default settings still hold the top scores, at 1.6 and 3.3 times the price:
380
381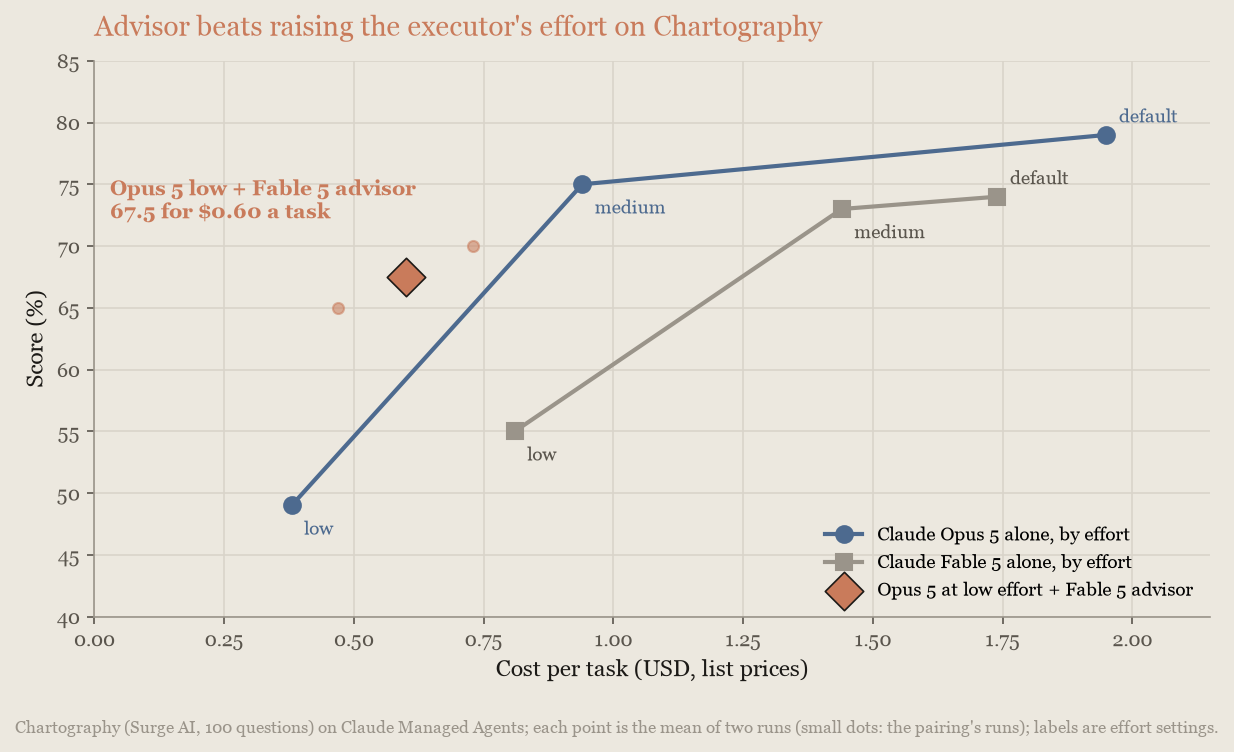
382
383The low-effort executor consulted the advisor on 86% of tasks, the condition the SWE-bench Pro pairing failed to meet. Measure the consult rate in your agent loop before relying on this configuration.
384
385402Whatever the pairing, first price the advisor's model alone at low effort; that is the baseline to beat. Recheck at every model release, because releases move both the capability gap and the price ratio.
386403
387404**When it fits.** The advisor strategy suits workloads where turns are mostly mechanical but an excellent plan matters: coding agents, computer use, and multistep research pipelines. It fits poorly when every turn genuinely needs frontier capability, when there is nothing to plan (single-turn Q\&A), or when your executor is already close to the advisor's capability.
from line 407
390407
391408In the orchestrator strategy, the frontier model holds the loop. It decomposes the task, dispatches subtasks to lower-cost worker models, and merges their results. The orchestrator's own transcript stays short because workers absorb the token-heavy exploration, so most tokens are billed at worker rates while the plan and synthesis still come from the frontier model.
392409
393To build one, use [multiagent orchestration](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration) in Claude Managed Agents: configure a coordinator agent (the orchestrator) and a roster of worker agents, each with its own model. For a complete working example with a Claude Fable 5 coordinator and Claude Sonnet 5 workers, see the Claude Cookbook recipe [Coordinator pattern: big models for planning, small models for execution](https://github.com/anthropics/claude-cookbooks/blob/main/managed_agents/CMA_plan_big_execute_small.ipynb).
410To build one, use [multiagent orchestration](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration) in Claude Managed Agents: configure a coordinator agent (the orchestrator) and a roster of worker agents, each with its own model. For a complete working example with a frontier coordinator and Claude Sonnet 5 workers, see the Claude Cookbook recipe [Coordinator pattern: big models for planning, small models for execution](https://github.com/anthropics/claude-cookbooks/blob/main/managed_agents/CMA_plan_big_execute_small.ipynb).
394411
395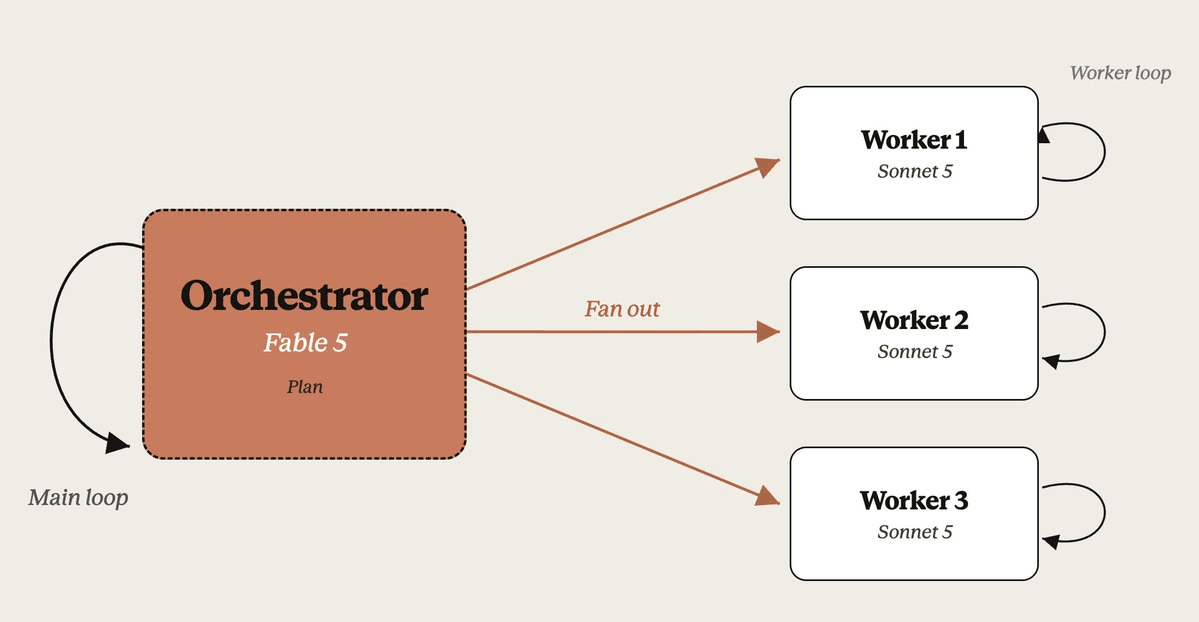
412
396413
397This pattern saves wall-clock time when workers can run in parallel: on the corpus benchmark[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), an episode took a little over 2 hours with the coordinator running the platform's documented limit of 25 concurrent workers, compared with 11.4 hours solo. It saved money in only two measured situations. On work a single model could handle alone, the same model at lower effort was cheaper every time.
414This pattern saves wall-clock time when workers can run in parallel: on the corpus benchmark[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), an episode took about 2.3 hours with the coordinator running the platform's documented limit of 25 concurrent workers, compared with 15 to 20 hours solo. It saved money in only two measured situations. On work a single model could handle alone, the same model at lower effort was cheaper every time.
398415
399416**Case 1: insurance against the cost tail on routine work.** A frontier model running alone occasionally spirals on a routine problem it would normally solve. Because you cannot tell in advance which those will be, a few such runs dominate the bill. A coordinator that hands routine work to a lower-cost worker caps that tail, because any spiraling now happens at worker rates.
400417
401Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost a little under half as much as Fable alone on average and about a third as much at the 90th percentile ($12 compared with $33), and the solo model's single most expensive run, at $84, was also wrong:
418Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost about half as much as Claude Fable 5 alone on average and about a third as much at the 90th percentile ($12 compared with $33), and the solo model's single most expensive run, at $84, was also wrong:
402419
403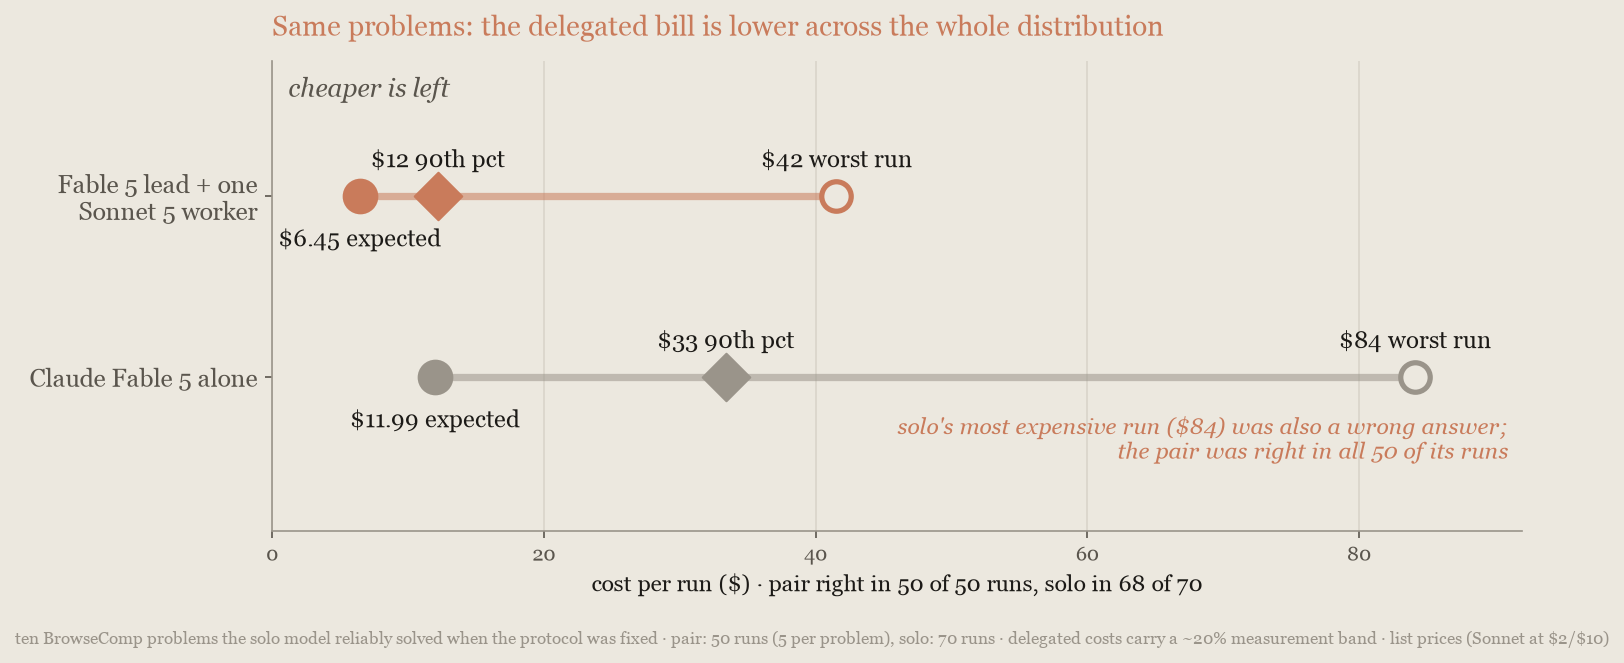
420
404421
405422Delegation paid on the routine, normally solvable share of the work, the opposite of the intuition that workers are for hard problems. On the full, harder BrowseComp set, the economics reversed. If your traffic has a long cost tail on routine tasks, this is the orchestrator case to measure first.
406423
407424**Case 2: work larger than one context window.** A solo model must work through an input that large serially, one context window at a time, paying to re-read its own state on every pass. Workers each read their own partition, in parallel and at worker rates. Reading-heavy work that still fits in one context window is a model-choice problem, not a delegation problem: on reading cost alone, the orchestrator comes out ahead only when no single context can hold the work.
408425
409Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5 solo cost $720 to $764 per episode at every effort setting, and only its accuracy moved. The coordinator configuration cost more than 60% less than any of those settings and scored 2 to 6 points below Fable at `medium` or the default, while beating a Claude Sonnet 5 solo baseline outright:
426Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5.1 solo cost $468 to $552 per episode across the three effort settings, and only its accuracy moved. The coordinator configuration, a Claude Fable 5.1 lead over 25 Claude Sonnet 5 workers, cost about half as much as those settings (47% to 55% less) and scored 10 to 12 points below them, in about 2.3 hours per episode against 15 to 20, while beating a Claude Sonnet 5 solo baseline outright:
410427
411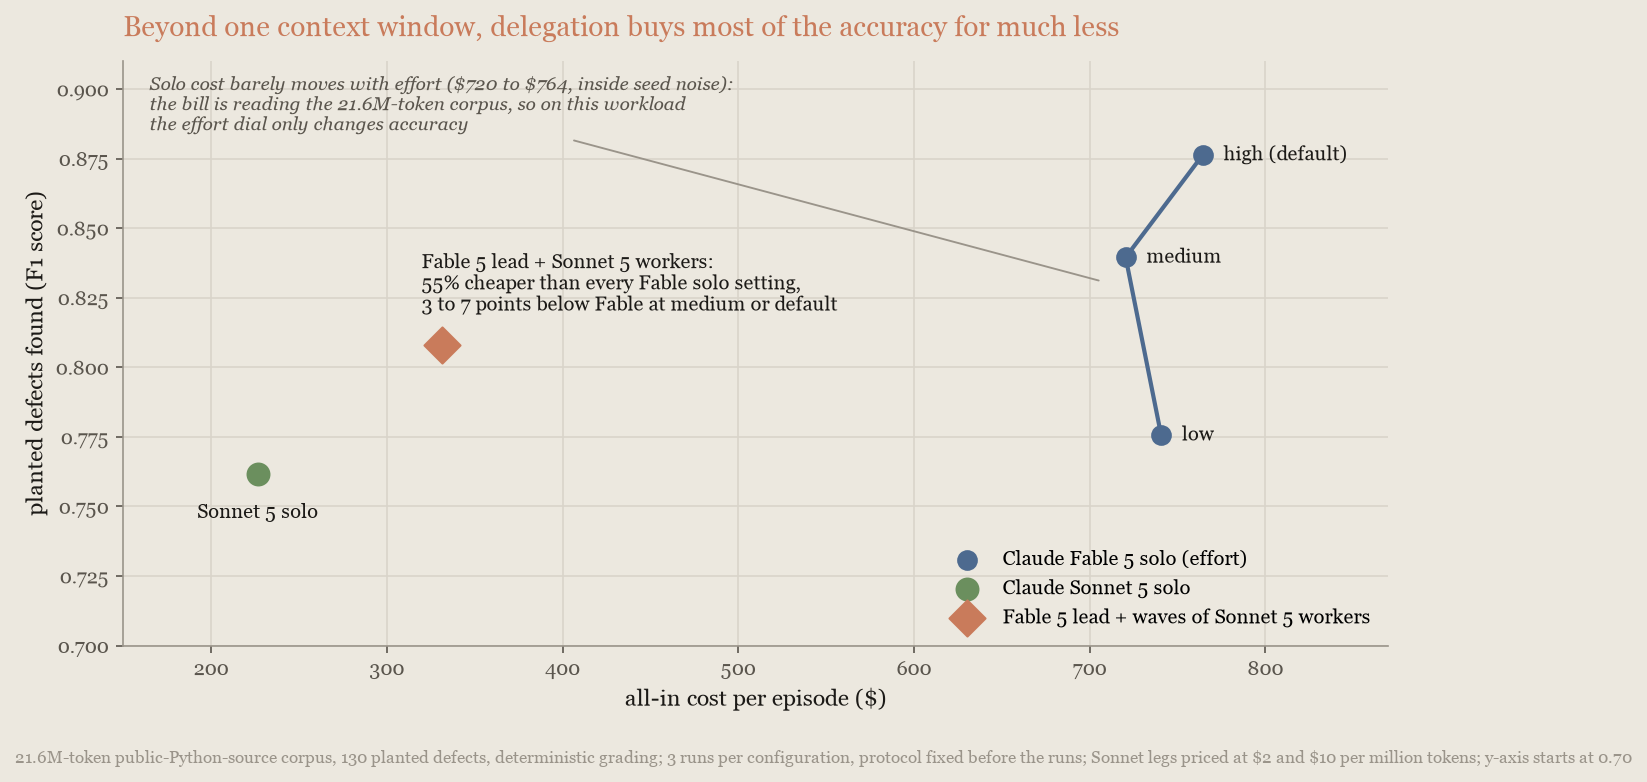
428
412429
413The token accounting shows why. Both bills are mostly corpus reading served from the cache: the coordinator configuration read about 570 million cached tokens per episode, nearly three times the solo model's roughly 200 million, and still cost less than half as much, because its reads were billed at Claude Sonnet 5's cache-read rate rather than Claude Fable 5's. Fable 5 at default effort still holds peak accuracy, at 2.8 times the coordinator configuration's cost, so delegation here buys most of the accuracy, not all of it.
430The token accounting shows the scale of the reading: the coordinator configuration read about 560 million cached tokens per episode, about one and a half times the solo model's roughly 365 million, nearly all of them at Claude Sonnet 5's cache-read rate, and still cost about half as much overall. Fable 5.1 at `high` effort still holds peak accuracy, at about 2.2 times the coordinator configuration's cost, so delegation here buys most of the accuracy, not all of it.
414431
415432**When delegation doesn't pay.** An orchestrator buys something only when there is bulk to hand off: many independent pieces, ideally too many for one context window. When the work is one dependent chain, or fits in a single context, the orchestrator pays for a plan, a handoff, and a merge that a single model gets for free. In every such case measured, the coordinator's model alone at lower effort came out ahead.
416433
417BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) shows the boundary inside one benchmark. Delegation paid on the routine slice and lost on the full, harder set, where the frontier model alone reached the coordinator configuration's accuracy at 22% to 30% lower cost. Independent external work reports the same pattern[5](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). If the work is one chain, fits in one context without a long cost tail, or a single model at lower effort already meets your bar, don't build an orchestrator.
434The boundary is task difficulty, not the benchmark: on the full, harder BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) set, Claude Fable 5 alone reached the coordinator configuration's accuracy at 22% to 30% lower cost. Independent external work reports the same pattern[5](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). If the work is one chain, fits in one context without a long cost tail, or a single model at lower effort already meets your bar, don't build an orchestrator.
418435
419436### Choose between the strategies
420437
from line 448
431448
432449## Measure on your own workload
433450
434The numbers on this page reflect list prices at the time of measurement and drift as models and prices change. Your escalation rate, how cleanly tasks split, and transcript length move them too. The method stays the same:
451The numbers on this page reflect list prices at the time of measurement and will drift as models and prices change. Your escalation rate, how cleanly tasks split, and transcript length move them too. The method stays the same:
435452
4361. Pull a few tasks from production logs, weighted like real traffic, and [write outcome checks](https://platform.claude.com/docs/en/test-and-evaluate/develop-tests) for each: tests pass, ticket closed, row count correct. Record cost per task beside the score: price the five priced token counts in each response's `usage` at their own rates, summed across the task's requests (the [Usage and Cost API](https://platform.claude.com/docs/en/manage-claude/usage-cost-api) reports the aggregate). The 1-hour cache write bills at 2x the input price, and the 5-minute write at 1.25x.
4531. Pull a few tasks from production logs, weighted like real traffic, and [write outcome checks](https://platform.claude.com/docs/en/test-and-evaluate/develop-tests) for each: tests pass, ticket closed, row count correct. Record cost per task beside the score: price the five priced token counts in each response's `usage` at their own rates (uncached input, 5-minute and 1-hour cache writes at 1.25x and 2x the input price, cache reads, and output), summed across the task's requests (the [Usage and Cost API](https://platform.claude.com/docs/en/manage-claude/usage-cost-api) reports the aggregate).
4374542. Baseline the model tiers across effort levels, not only the default, and plot score against spend. A multi-model configuration must beat the single model's whole curve.
4384553. If the curve shows a gap effort can't close, add the multi-model strategy that fits and re-run the suite.
4394564. Run the winner in shadow on a traffic slice before cutover, then keep the suite running.
from line 459
442459
443460<CodeGroup>
444461 ```bash cURL
445 # Per-million-token prices from the pricing page; change these two for another model.
462 # Per-million-token prices from the pricing page; change these three for another model.
446463 INPUT_PER_MTOK=5.00 # Claude Opus 5
464 CACHE_READ_PER_MTOK=0.50 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
447465 OUTPUT_PER_MTOK=25.00
448466
449467 response=$(curl --fail-with-body -sS https://api.anthropic.com/v1/messages \
from line 474
456474 "messages": [{"role": "user", "content": "Hello, Claude"}]
457475 }')
458476
459 cost=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
477 cost=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson read_price "$CACHE_READ_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
460478 .usage
461479 | (.input_tokens * $in_price
462480 + (.cache_creation.ephemeral_1h_input_tokens // 0) * $in_price * 2.00 # 1-hour cache write
463481 + (.cache_creation.ephemeral_5m_input_tokens // 0) * $in_price * 1.25 # 5-minute cache write
464 + (.cache_read_input_tokens // 0) * $in_price * 0.10 # cache read
482 + (.cache_read_input_tokens // 0) * $read_price # cache read
465483 + .output_tokens * $out_price) / 1e6
466484 ' <<<"$response")
467485 printf 'Request cost: $%.6f\n' "$cost"
from line 486
468486 ```
469487
470488 ```bash CLI
471 # Per-million-token prices from the pricing page; change these two for another model.
489 # Per-million-token prices from the pricing page; change these three for another model.
472490 INPUT_PER_MTOK=5.00 # Claude Opus 5
491 CACHE_READ_PER_MTOK=0.50 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
473492 OUTPUT_PER_MTOK=25.00
474493
475494 USAGE=$(ant messages create \
from line 497
478497 --message '{role: user, content: "Hello, Claude"}' \
479498 --transform usage)
480499
481 COST=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
500 COST=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson read_price "$CACHE_READ_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
482501 (.input_tokens * $in_price
483502 + (.cache_creation.ephemeral_1h_input_tokens // 0) * $in_price * 2.00 # 1-hour cache write
484503 + (.cache_creation.ephemeral_5m_input_tokens // 0) * $in_price * 1.25 # 5-minute cache write
485 + (.cache_read_input_tokens // 0) * $in_price * 0.10 # cache read
504 + (.cache_read_input_tokens // 0) * $read_price # cache read
486505 + .output_tokens * $out_price) / 1e6
487506 ' <<<"$USAGE")
488507 printf 'Request cost: $%.6f\n' "$COST"
from line 508
489508 ```
490509
491510 ```python Python
492 # Per-million-token prices from the pricing page; change these two for another model.
511 # Per-million-token prices from the pricing page; change these three for another model.
493512 INPUT_PER_MTOK = 5.00 # Claude Opus 5
513 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
514 CACHE_READ_PER_MTOK = 0.50
494515 OUTPUT_PER_MTOK = 25.00
495516
496517 client = anthropic.Anthropic()
from line 526
505526 writes_5m = cache_writes.ephemeral_5m_input_tokens if cache_writes else 0
506527 cost = (
507528 usage.input_tokens * INPUT_PER_MTOK
508 # 1-hour cache writes bill at 2x the input price, 5-minute at 1.25x; reads at 0.1x.
529 # 1-hour cache writes bill at 2x the input price, 5-minute at 1.25x; reads at the cache-read price.
509530 + writes_1h * INPUT_PER_MTOK * 2.0
510531 + writes_5m * INPUT_PER_MTOK * 1.25
511 + (usage.cache_read_input_tokens or 0) * INPUT_PER_MTOK * 0.10
532 + (usage.cache_read_input_tokens or 0) * CACHE_READ_PER_MTOK
512533 + usage.output_tokens * OUTPUT_PER_MTOK
513534 ) / 1_000_000
514535 print(f"Request cost: ${cost:.6f}")
from line 536
515536 ```
516537
517538 ```typescript TypeScript
518 // Per-million-token prices from the pricing page; change these two for another model.
539 // Per-million-token prices from the pricing page; change these three for another model.
519540 const INPUT_PER_MTOK = 5.0; // Claude Opus 5
541 const CACHE_READ_PER_MTOK = 0.5; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
520542 const OUTPUT_PER_MTOK = 25.0;
521543
522544 const client = new Anthropic();
from line 552
530552 (usage.input_tokens * INPUT_PER_MTOK +
531553 (usage.cache_creation?.ephemeral_1h_input_tokens ?? 0) * INPUT_PER_MTOK * 2 + // 1-hour cache write
532554 (usage.cache_creation?.ephemeral_5m_input_tokens ?? 0) * INPUT_PER_MTOK * 1.25 + // 5-minute cache write
533 (usage.cache_read_input_tokens ?? 0) * INPUT_PER_MTOK * 0.1 + // cache read
555 (usage.cache_read_input_tokens ?? 0) * CACHE_READ_PER_MTOK + // cache read
534556 usage.output_tokens * OUTPUT_PER_MTOK) /
535557 1_000_000;
536558 console.log(`Request cost: $${cost.toFixed(6)}`);
from line 559
537559 ```
538560
539561 ```csharp C#
540 // Per-million-token prices from the pricing page; change these two for another model.
562 // Per-million-token prices from the pricing page; change these three for another model.
541563 const double InputPerMtok = 5.00; // Claude Opus 5
564 const double CacheReadPerMtok = 0.50; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
542565 const double OutputPerMtok = 25.00;
543566
544567 AnthropicClient client = new();
from line 579
556579 usage.InputTokens * InputPerMtok
557580 + (usage.CacheCreation?.Ephemeral1hInputTokens ?? 0) * InputPerMtok * 2.00 // 1-hour cache write
558581 + (usage.CacheCreation?.Ephemeral5mInputTokens ?? 0) * InputPerMtok * 1.25 // 5-minute cache write
559 + (usage.CacheReadInputTokens ?? 0) * InputPerMtok * 0.10 // cache read
582 + (usage.CacheReadInputTokens ?? 0) * CacheReadPerMtok // cache read
560583 + usage.OutputTokens * OutputPerMtok
561584 ) / 1_000_000;
562585 Console.WriteLine($"Request cost: ${cost:F6}");
from line 586
563586 ```
564587
565588 ```go Go
566 // Per-million-token prices from the pricing page; change these two for another model.
589 // Per-million-token prices from the pricing page; change these three for another model.
567590 const (
568 inputPerMTok = 5.00 // Claude Opus 5
569 outputPerMTok = 25.00
591 inputPerMTok = 5.00 // Claude Opus 5
592 cacheReadPerMTok = 0.50 // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
593 outputPerMTok = 25.00
570594 )
571595
572596 // ...
from line 611
587611 cost := (float64(usage.InputTokens)*inputPerMTok +
588612 float64(usage.CacheCreation.Ephemeral1hInputTokens)*inputPerMTok*2.00 + // 1-hour cache write
589613 float64(usage.CacheCreation.Ephemeral5mInputTokens)*inputPerMTok*1.25 + // 5-minute cache write
590 float64(usage.CacheReadInputTokens)*inputPerMTok*0.10 + // cache read
614 float64(usage.CacheReadInputTokens)*cacheReadPerMTok + // cache read
591615 float64(usage.OutputTokens)*outputPerMTok) / 1_000_000
592616 fmt.Printf("Request cost: $%.6f\n", cost)
593617 ```
594618
595619 ```java Java
596 // Per-million-token prices from the pricing page; change these two for another model.
620 // Per-million-token prices from the pricing page; change these three for another model.
597621 static final double INPUT_PER_MTOK = 5.00; // Claude Opus 5
622 static final double CACHE_READ_PER_MTOK = 0.50; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
598623 static final double OUTPUT_PER_MTOK = 25.00;
599624
600625 void main() {
from line 637
612637 double cost = (usage.inputTokens() * INPUT_PER_MTOK
613638 + writes1h * INPUT_PER_MTOK * 2.00 // 1-hour cache write
614639 + writes5m * INPUT_PER_MTOK * 1.25 // 5-minute cache write
615 + usage.cacheReadInputTokens().orElse(0L) * INPUT_PER_MTOK * 0.10 // cache read
640 + usage.cacheReadInputTokens().orElse(0L) * CACHE_READ_PER_MTOK // cache read
616641 + usage.outputTokens() * OUTPUT_PER_MTOK) / 1_000_000;
617642 IO.println("Request cost: $%.6f".formatted(cost));
618643 }
from line 644
619644 ```
620645
621646 ```php PHP
622 // Per-million-token prices from the pricing page; change these two for another model.
647 // Per-million-token prices from the pricing page; change these three for another model.
623648 const INPUT_PER_MTOK = 5.00; // Claude Opus 5
649 const CACHE_READ_PER_MTOK = 0.50; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
624650 const OUTPUT_PER_MTOK = 25.00;
625651
626652 $client = new Client();
from line 660
634660 $usage->inputTokens * INPUT_PER_MTOK
635661 + ($usage->cacheCreation?->ephemeral1hInputTokens ?? 0) * INPUT_PER_MTOK * 2.00 // 1-hour cache write
636662 + ($usage->cacheCreation?->ephemeral5mInputTokens ?? 0) * INPUT_PER_MTOK * 1.25 // 5-minute cache write
637 + ($usage->cacheReadInputTokens ?? 0) * INPUT_PER_MTOK * 0.10 // cache read
663 + ($usage->cacheReadInputTokens ?? 0) * CACHE_READ_PER_MTOK // cache read
638664 + $usage->outputTokens * OUTPUT_PER_MTOK
639665 ) / 1_000_000;
640666 printf("Request cost: \$%.6f\n", $cost);
from line 667
641667 ```
642668
643669 ```ruby Ruby
644 # Per-million-token prices from the pricing page; change these two for another model.
670 # Per-million-token prices from the pricing page; change these three for another model.
645671 INPUT_PER_MTOK = 5.00 # Claude Opus 5
672 CACHE_READ_PER_MTOK = 0.50 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
646673 OUTPUT_PER_MTOK = 25.00
647674
648675 client = Anthropic::Client.new
from line 683
656683 usage.input_tokens * INPUT_PER_MTOK +
657684 usage.cache_creation&.ephemeral_1h_input_tokens.to_i * INPUT_PER_MTOK * 2.00 + # 1-hour cache write
658685 usage.cache_creation&.ephemeral_5m_input_tokens.to_i * INPUT_PER_MTOK * 1.25 + # 5-minute cache write
659 usage.cache_read_input_tokens.to_i * INPUT_PER_MTOK * 0.10 + # cache read
686 usage.cache_read_input_tokens.to_i * CACHE_READ_PER_MTOK + # cache read
660687 usage.output_tokens * OUTPUT_PER_MTOK
661688 ) / 1_000_000
662689 puts format("Request cost: $%.6f", cost)
from line 694
667694
668695The following table lists the levers in the order to try them:
669696
670| Lever | Saving in these runs | Quality cost | Latency | Where |
671| ------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------ | ------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
672| Prompt caching | Cost cut by a factor of 2.5 to 3.7 on agent loops; 83% on the triage run | None | Faster | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) |
673| 1-hour cache duration | Cheaper than the 5-minute default once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour; with no pauses the default cost 15% less on Claude Sonnet 5 and 11% less on Claude Opus 5 | None | Stays warm after a pause | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
674| Input trimming | A further 5 percentage points on the triage run | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
675| Prune stale tool results at task boundaries | 39% on the long triage run (compaction 32%); nothing on short loops | None measured | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
676| Tool search | 45% with 500 tool definitions attached; 20% with a GitHub MCP server | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
677| Data files through code execution | 92% on a 25-question data task | A gain, 25 of 25 instead of 6 of 25 | Faster | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
678| Batch API | 50% | None | Results within 24 hours | [Batch work that can wait](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#batch-work-that-can-wait) |
679| Prompt audit against the current model | 14% on both migrations measured | None; a gain on one | Faster (fewer tool rounds) | [Audit prompts against the current model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#audit-prompts-against-the-current-model) |
680| Upgrade the model | Opus 4.7 to Opus 5: about 12% less per solved task, 11 more points; Sonnet 4.6 to Sonnet 5: 14% less, 5 more points | A gain | Neutral | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
681| Lower effort | Knowledge work: `medium` 15% to 30%, `low` a third to a half; long coding: `medium` about half, `low` about three quarters | 1 to 3 points on knowledge work, 2 to 8 on long coding | Faster | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
682| Re-run failures | About half, at the same pass rate | None | Two runs on the tasks that fail | [Re-run failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
683| Task budget | 18% to 47% | 3 to 4 points | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
684| Ask for shorter answers | 39% of output tokens, 14% of cost on the triage run | None | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
685| Raising `max_tokens` | None per solved task, but more tasks solved | Gains of 2 to 18 points | Neutral | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
686| Advisor | Depends on the capability gap and the consult rate; the chart-reading pairing scored above both models' effort curves, the coding pairing only marginally | Small gains | About two extra calls per task | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
687| Orchestrator | More than 60% below the frontier model beyond one context window; about half on routine tails | 2 to 6 points below the frontier model | Much faster on large inputs | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
697| Lever | Saving in these runs | Quality cost | Latency | Where |
698| ------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------- | ------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
699| Prompt caching | Cost cut by a factor of 2.7 to 5.3 on agent loops; 83% on the triage run | None | Faster | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) |
700| 1-hour cache duration | Cheaper than the 5-minute default once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour, except on Claude Fable 5.1, where keeping the 5-minute cache warm is cheaper while pauses run minutes and the 1-hour duration wins when pauses run toward an hour; with no pauses the default cost 15% less on Claude Sonnet 5 and 11% less on Claude Opus 5 | None | Stays warm after a pause | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
701| Input trimming | A further 5 percentage points on the triage run | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
702| Prune stale tool results at task boundaries | 39% on the long triage run (compaction 32%); nothing on short loops | None measured | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
703| Tool search | 45% with 500 tool definitions attached; 20% with a GitHub MCP server | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
704| Data files through code execution | 92% on a 25-question data task | A gain, 25 of 25 instead of 6 of 25 | Faster | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
705| Batch API | 50% | None | Results within 24 hours | [Batch work that can wait](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#batch-work-that-can-wait) |
706| Prompt audit against the current model | 14% on both migrations measured | None; a gain on one | Faster (fewer tool rounds) | [Audit prompts against the current model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#audit-prompts-against-the-current-model) |
707| Upgrade the model | Opus 4.8 to Opus 5: 12 more points at 21% more per solved task (Opus 5 at `low` beats Opus 4.8 for about 30% of the cost); Sonnet 4.6 to Sonnet 5: 15% less per solved task, 5 more points; Fable 5 to Fable 5.1: 43% less per solved task at about the same score | A gain | Neutral | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
708| Lower effort | Knowledge work: `medium` 13% to 31%, `low` a third to a half; long coding: `medium` about half, `low` about three quarters | 1 to 3 points on knowledge work, 2 to 8 on long coding | Faster | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
709| Re-run failures | About half, at the same pass rate | None | Two runs on the tasks that fail | [Re-run failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
710| Task budget | 44% to 58% | 3 to 6 points | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
711| Ask for shorter answers | 39% of output tokens, 14% of cost on the triage run | None | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
712| Raising `max_tokens` | None per solved task, but more tasks solved | Gains of up to 22 points on the internal set; none on the public pair | Neutral | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
713| Advisor | Depends on the capability gap and the consult rate; the coding pairing scored 3.5 points over Opus 5 alone and about 2.5 over Fable 5.1 alone, the chart-reading pairing matched the advisor's model alone at `medium` for about 2.6 times the price | Small gains | About two extra calls per task | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
714| Orchestrator | About half against the frontier model, both beyond one context window and on routine tails (the latter measured on Claude Fable 5) | 10 to 12 points below the frontier model | Much faster on large inputs | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
688715
689716## Benchmarks referenced
690717
691718Except where a reference says otherwise, measurements are Anthropic-internal runs of these benchmarks. Unless noted, costs are USD at the list prices in effect when each benchmark ran; Claude Sonnet 5 figures use $2 and $10 per million input and output tokens. Charts labeled "notional USD" price each request's token counts at those rates rather than reporting invoices.
692719
6931. **WideSearch:** Wong et al., "WideSearch: Benchmarking Agentic Broad Info-Seeking," arXiv:2508.07999, 2025. Broad web-research tasks graded on a many-row table's completeness and accuracy; 200 problems, 3 runs per configuration, run August 1 to 2, 2026. The caching chart re-prices the effort chart's default-effort runs from their per-request billing records; per-problem costs differ slightly because the two charts use different cost accounting. The cost-concentration chart is a separate 20-problem run, 3 runs per problem, run August 3 to 4, 2026, costed from per-request billing records.
7201. **WideSearch:** Wong et al., "WideSearch: Benchmarking Agentic Broad Info-Seeking," arXiv:2508.07999, 2025. Broad web-research tasks graded on a many-row table's completeness and accuracy; 200 problems, 3 runs per configuration, run August 1 to 2, 2026. The cost-concentration chart is a separate 20-problem run, 3 runs per problem, run August 3 to 4, 2026, costed from per-request billing records.
6947212. **GDPval:** OpenAI, "GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks," 2025. Knowledge-work deliverables graded against task rubrics; a 210-task run of the released gold set, one attempt per task, run August 2, 2026. A Claude model grades, so absolute scores may differ from published results.
6953. **SWE-bench Pro:** Scale AI, "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", 2025. A 482-problem subset selected for compatibility with Anthropic's evaluation harness; scores are not comparable to the public leaderboard. Claude Opus 5 at the default effort averages two runs; reduced-effort settings are single runs; all ran August 4, 2026, as did the task-budget arms. Escalation figures come task by task from those runs: `low` first, then the default on its failures, solved 92.5% to 93.6% across run pairings for about $0.70; `medium` first, 93.8% to 94.2% for about $0.95; the default re-run on its own failures, 94.0% for $1.58; everything at the default, 90.9% to 92.5% for $1.39. The Claude Sonnet 5 executor pairings on the advisor chart come from the same measurement series on this subset: the Sonnet-plus-Opus pairing was run twice (August 7 and August 8, 2026, a run and an exact replication), the low-effort pairing once (August 8, 2026), and Claude Sonnet 5 alone twice (77.4%, the baseline for both Pro rows); the task-budget figures are one run per budget on the same subset. The Claude Fable 5 figure in [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) is a single run from July 2, 2026, also the task-budget chart's unbudgeted baseline; every budgeted run completed all 482 problems without harness errors. The upgrade ladder is one run per model at its shipped defaults (two each for Opus 5 and Sonnet 5), run the same week in one harness and organization.
7223. **SWE-bench Pro:** Scale AI, "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", 2025. A 482-problem subset selected for compatibility with Anthropic's evaluation harness; scores are not comparable to the public leaderboard. Claude Opus 5 at the default effort averages two runs; reduced-effort settings are single runs; all ran August 4, 2026. Escalation figures come task by task from those runs: `low` first, then the default on its failures, solved 92.5% to 93.6% across run pairings for about $0.45; `medium` first, 93.8% to 94.2% for about $0.61; the default re-run on its own failures, 94.0% for $1.06; everything at the default, 90.9% to 92.5% for $0.93. Costs on this subset are priced as a customer's organization is metered: each request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, checked against a customer ledger; the evaluation organization's own metering, which bills cache in 8,192-token pages, gave figures 1.4 to 1.8 times higher. The Claude Sonnet 5 executor pairings on the advisor chart come from the same measurement series on this subset: the Sonnet-plus-Opus pairing was run twice (August 7 and August 8, 2026, a run and an exact replication), the low-effort pairing once (August 8, 2026), and Claude Sonnet 5 alone twice (77.4%, the baseline for both Pro rows). The Claude Fable 5 point in Upgrade the model is the mean of three runs at the default effort, run August 26, 2026, priced the same way. The Claude Fable 5.1 task-budget figures are one run per budget (two at 35,000 tokens) on the same subset at the default effort, run August 26, 2026, with an unbudgeted run the same day (92.1%, $1.10 per task) as the baseline; an earlier set at `low` effort, run August 21, 2026, scored 88.6% unbudgeted at $0.48 per task. The [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) comparison pairs that single run with the two pooled Claude Sonnet 5 runs from the same subset; at Fable 5.1's default effort the pair reads the other way, 41% more per solved task than Sonnet 5. The upgrade ladder is one run per model at its shipped defaults (two each for Opus 5 and Sonnet 5, and the Fable 5 point as described above), the Opus and Sonnet runs the same week in one harness and organization.
6967234. **BrowseComp:** Wei et al., "BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents," OpenAI, 2025. Effort figures use a 500-problem cut, one to three runs per setting, run August 3, 2026, with the default point pooling two runs from July 26 to 27, 2026. The cost-insurance chart uses 10 reliably solved problems from a 26-problem slice, 50 delegated runs (August 1 to 2, 2026) and 70 solo runs (50 from August 2 to 3, 2026; 20 archived from July 12 to 13 and August 1, 2026), $6.45 compared with $11.99 per run in expectation; delegated figures carry a measurement band of about 20%.
6977245. **Agent-architecture scaling:** Kim et al., "Towards a Science of Scaling Agent Systems," arXiv:2512.08296, 2025. Independent external study, cited only for the direction of the finding on when delegation does not pay, not for any figure.
6987256. **DeepWideSearch:** "DeepWideSearch: Benchmarking Depth and Width in Agentic Information Seeking," arXiv:2510.20168, 2025. The 220 questions span 15 domains, each combining many-row collection with multi-hop retrieval; measured on the benchmark's standing row set, 3 runs per configuration, run August 2, 2026 (the single-worker team point ran July 26 to 27, 2026).
6997. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs (August 2 to 3, 2026), scored on tasks no configuration refused. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Anthropic did not run Claude Opus 5 on this benchmark, so it is absent from the [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) chart. The Sonnet 5 cost differs slightly between the caching chart (inference cost, with and without caching) and that chart (all-in cost, caching on); both come from the same runs.
7008. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is an August 13, 2026, run in which the Claude Fable 5 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers; its three episodes scored F1 0.842, 0.805, and 0.810 for $263, $299, and $261. The solo configurations ran August 3 to 4, 2026, on the same corpus build. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
7267. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs per setting, on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with the platform's own web search and fetch tools (August 26 to 27, 2026); scored on the 33 tasks no configuration refused, with attempts the production safety classifiers cut short removed; costs are what a customer is billed, the platform's requests plus web-search fees. Scores are each model's mean on the 33-task basis with its own pre-empted tasks removed; on the 21 tasks clean in every arm, Claude Fable 5.1 holds a 2-to-3-point lead over Claude Fable 5 at every effort level and both models are flat across effort. The caching chart re-prices the same requests with every input token at the uncached rate. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Claude Opus 5 at its default effort ran on the same surface and subset, three runs, on August 28, 2026: 68.8% on the raw 50 tasks, 70.8% on the 33-task basis, and 71.1% on the 21-task set, at $6.71 per task ($23.72 without caching); none of its attempts was cut short by the safety classifiers, under a safeguards deployment newer than the one the other models ran under.
7278. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is a run in which the Claude Fable 5.1 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers, run August 30, 2026; its three episodes scored F1 0.764, 0.825, and 0.791 after the extras audit (raw 0.751, 0.821, and 0.781) for $225, $234, and $283. The Claude Sonnet 5 solo configuration ran August 3 to 4, 2026; the Claude Fable 5.1 solo configurations ran August 24 to 25, 2026, under the platform's launch serving settings, three seeds per effort setting, on the same corpus build. The sandbox image carried installed copies of part of the corpus, and Claude Fable 5.1's final assembly step compared against them in 7 of 9 episodes; re-grading without those additions moved the affected seeds by up to 3 points. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
7017289. **GPQA Diamond:** Rein et al., "GPQA: A Graduate-Level Google-Proof Q\&A Benchmark," 2023. The 198-question Diamond subset, two runs per configuration, run August 7, 2026, model-graded against reference answers, advisor tokens metered per request. A platform safety check refused two biology questions on the Sonnet and Opus executors; excluding them changes no comparison by more than one point.
70272910. **DeepSWE:** Datacurve, "DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks," arXiv:2607.07946, 2026. The set has 113 original tasks across five languages with program-based verifiers. Pairings are two runs each, run August 7, 2026, with advisor tokens metered per request, and used a client-side advisor loop rather than the advisor tool, with identical accounting. Single-model effort sweeps are single runs priced from token counts, a cache-aware approximation. Costs per task are run totals divided by 113.
70311. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures (Opus 5 alone, Fable 5 alone, and the pairing) were measured August 9 to 10, 2026, at the default effort with a 128,000-token output cap, one run per configuration: five attempts per task at the default settings and for the pairing, one at `low` and `medium`; the pairing averaged about two advisor consultations per attempt; costs are per attempt. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
70412. **Internal repository-task benchmark (cap measurement):** A separate Anthropic-internal set of about 130 repository tasks, run August 8 to 10, 2026, with a plain API agent loop, one attempt per task. The 16,384-token figures average two runs per model; the 64,000-token figures are single runs (124 tasks scored for Opus 5; 108 for Claude Fable 5, the environment having skipped the rest before the model ran). About half the Fable attempts the 16,384 cap had ended solved at 64,000; a further Fable run at 128,000 scored 56.1%, within noise of the 64,000 run. The SWE-bench Pro cap figures are one Claude Fable 5 run per cap (August 10, 2026) at the default effort on a 100-problem subset stratified from reference 3's 482-problem set, not comparable to its scores. The chart's per-turn distributions come from the Opus run at 64,000 and the Fable run at 128,000, so neither is cut off by its own cap.
70513. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 8 to 10, 2026, with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. Two runs per configuration, pooled; run-to-run spreads were 4 to 10 points. Costs exclude sandbox time, which added under 1%. The consult-rate comparison comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
73011. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures were measured with a 128,000-token output cap, one run per configuration: Opus 5 alone at the default effort August 9 to 10, 2026, Claude Fable 5.1 alone at five explicitly set effort values August 20, 2026, and the pairing August 24 to 25, 2026. Attempts per task: five for the pairing and the Opus-alone control, one for the single-model points; the pairing averaged about two advisor consultations per attempt; costs are per attempt. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
73112. **Internal repository-task benchmark (cap measurement):** A separate Anthropic-internal set of about 130 repository tasks, run August 8 to 10, 2026 (Claude Opus 5) and August 20, 2026 (Claude Fable 5.1), with a plain API agent loop, one attempt per task. The Claude Fable 5.1 runs are 135 tasks per cap at the default effort set explicitly: the 16,384-token figure averages two runs (36.3% on both); the 64,000 and 128,000 figures are single runs (58.5% and 60.0%). Six problems drew a safety refusal in every run and count as failures. The Opus 5 16,384-token figure averages two runs and its 64,000 figure is a single run (124 tasks scored). The SWE-bench Pro cap figures are one Claude Fable 5.1 run per cap at the default effort, run August 26, 2026, on a 100-problem subset stratified from reference 3's 482-problem set, not comparable to its scores; the two caps scored the same at the default. The chart's per-turn distributions come from the Opus run at 64,000 and the Claude Fable 5.1 run at 128,000; no Opus turn reached its cap, and one Fable 5.1 turn reached 128,000 (0.46% of its turns exceeded 16,384).
73213. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 8 to 10, 2026, with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. Two runs per configuration, pooled; run-to-run spreads were 4 to 10 points. Costs exclude sandbox time, which added under 1%. The Claude Fable 5.1 solo runs are from August 24, 2026, under the platform's launch serving settings, two runs per setting; six attempts hit the 15-minute session cap and score 0, and two charts per run were answered by Claude Opus 5 after a safety refusal. The Claude Opus 5 low-effort executor with a Claude Fable 5.1 advisor ran twice on August 30, 2026, under the same settings (63.0 and 67.0, mean 65.0, at $0.72 a chart; the advisor was consulted on 88% of tasks in each run, and 4 of its 219 replies came from Claude Opus 5 instead, each after a production safety filter stopped the advisor's own reply). The consult-rate comparison for the earlier pairings comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
70673314. **Support-desk prompt-audit evaluation:** An Anthropic-constructed set of 44 support tickets with deterministic grading, run in early August 2026 and reported on August 8, 2026, under six system prompts, each adding to the same clean prompt one pattern common in prompts written for Claude Opus 4.8 and Claude Sonnet 4.6. Each chart point is one of three cases (older model, newer model on the same prompt, newer model after the audit) averaged over the six prompts and 44 tickets. The Opus 5 accuracy gain has a 95% confidence interval of 3 to 8 points; the Sonnet accuracy differences are within noise.
70773415. **Data-file question set:** An Anthropic-constructed set of 25 aggregate questions over a 1,862-row slice of a public liquor-sales CSV, with ground truth computed by pandas and exact-match grading, run on Claude Sonnet 5 and Claude Opus 5 with thinking disabled (the in-context arm cannot complete at the default), a 4,000-token output cap, and no prompt caching, three runs per configuration, run August 19, 2026. The file arm uploads the CSV through the Files API and uses the `code_execution_20260120` tool.
70816. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 23, 2026, on Claude Sonnet 5 and Claude Opus 5 on the Messages API with the same harness, the Claude Opus 5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute pauses on a 5-issue subset on both models; 45-minute pauses on a 5-issue subset on Claude Sonnet 5 only). Three runs per cell, cost computed from each response's `usage` fields on a customer-billed organization at list prices, accuracy against the same gold labels. The crossover is about 3.3% of turns on both models: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 and 36 Claude Opus 5 twenty-issue sessions in the analysis (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). The 5% cell tied on Claude Sonnet 5 because that draw's pauses fell on small prefixes. The page's 1-in-20 rule sits above the measured crossover. Anthropic measured keep-alive requests that refresh the 5-minute cache as a comparator only. They matched the 1-hour setting at best and cost more with a pause before every turn, so do not use them.
73516. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 23, 2026, on Claude Sonnet 5 and Claude Opus 5 on the Messages API with the same harness, the Claude Opus 5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute pauses on a 5-issue subset on both models; 45-minute pauses on a 5-issue subset on Claude Sonnet 5 only). Three runs per cell, cost computed from each response's `usage` fields on a customer-billed organization at list prices, accuracy against the same gold labels. The crossover is about 3.3% of turns on both models: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 and 36 Claude Opus 5 twenty-issue sessions in the analysis (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). The 5% cell tied on Claude Sonnet 5 because that draw's pauses fell on small prefixes. The page's 1-in-20 rule sits above the measured crossover. Anthropic measured keep-alive requests that refresh the 5-minute cache as a comparator only. They matched the 1-hour setting at best and cost more with a pause before every turn, so do not use them on these two models; on Claude Fable 5.1 the arithmetic reverses (reference 19).
70973617. **Cache-read share in production:** Aggregated first-party Claude API usage for the 14 days ending August 23, 2026, direct API product only, Anthropic-internal organizations excluded, no organization identified. An organization-day counts as an agent loop when its requests carry tool definitions and tool results, its prompts hold 9 or more prior tool calls on average, caching was used, and it made at least 10 such requests (the API has no conversation identifier, so this stands in for conversation length): 303,003 organization-days across 106,487 organizations, median cache-read share 84.2% of all input tokens, upper quartile 91.7%. Use-case labels (the organization's declared use case, or otherwise its classified one) cover 74% of those organization-days and 99% of their tokens; coding organizations supply 87% of agentic input tokens and read a median 88.5% (90.9% at 25 or more prior tool calls), upper quartile 93.4%, with about 72% of coding organization-days at 80% or more; support, research, and data agents read 84% to 85%. The top decile of organization-days reads 95.9% or more for coding and 94.2% to 94.8% for support, research, data, and other agents. The request-level split at 25 or more prior tool calls comes from a six-hour sample: coding 92% read, 7% write, under 1% uncached. Unlabeled organizations, mostly small, read a median 11%. Organization-days with no tool definitions read a median 34.6%. An independent query over the same window that reconstructs conversations of 10 or more requests, rather than scoring organization-days, puts the median at 90.2%; the difference is scope, not data.
71073718. **Compaction timing measurement:** The triage agent's long variant from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 24, 2026, on Claude Sonnet 5 with the 5-minute cache, cost from the usage fields at list prices, five sessions per arm: a no-change arm at the default effort throughout ($0.81 per session), and two arms that start at low effort and make the same two cache-breaking changes, a switch to the default effort and one added tool, either mid-session at requests 12 and 17 ($0.95) or together on the first request after the first compaction ($0.75). A fourth arm of six sessions, run August 25, 2026, made the same two changes on the request that triggered the first compaction ($0.92 per session): that request's summarization pass wrote the 81,000-token context to the cache instead of reading it, so that pass cost $0.21 against $0.04 for the same pass in the boundary arm. Sessions first compacted at request 21 to 25 (16 of the 21 sessions at request 22), once the prompt passed the 80,000-token compaction trigger, and two no-change sessions compacted a second time near the end. The boundary arm's lower total than the no-change arm reflects its low-effort requests before the change and those second compactions rather than caching: the two arms' re-write costs differ by under a cent. The mid-session arm paid $0.23 per session in cache re-writes; the difference between the mid-session and boundary arms was $0.20 with a 95% confidence interval of $0.11 to $0.29. One mid-session session ran cheap ($0.82) after its model mis-called the search tool following compaction and got empty results; it is included, and without it the arm averages $0.98. Accuracy averaged 14.2 of 20 labels in each August 24 arm and 14.7 in the August 25 arm; cache reads were 91% of prompt tokens with no changes, 85% mid-session, 91% at the boundary, and 86% with the changes on the triggering request.
73819. **Cache duration measurement on Claude Fable 5.1:** The same 20-issue triage job and harness as reference 16, run August 23 and August 26, 2026, on the Claude Fable 5.1 launch snapshot at its launch prices ($10 input, $12.50 5-minute write, $20 1-hour write, $0.25 cache read, $50 output per million tokens), three settings per schedule: the 5-minute cache, the 1-hour cache, and the 5-minute cache kept warm by a `max_tokens: 0` request on the unchanged prefix every 4 minutes of idle time (the August 23 runs pinged with `max_tokens: 1`; every August 26 ping refreshed the cache and billed no output). Schedules: no pauses, 10% of turns, and every turn at 6 minutes on all 20 issues, and 45-minute pauses on the 5-issue subset; three runs per cell, cost computed from each response's `usage` fields at list prices, accuracy against the same gold labels (12 to 17 exact labels of 20). Per-session means on August 26 for the 5-minute, 1-hour, and keep-alive settings: no pauses $2.42, $3.09, $2.29; 10% paused $4.50, $2.96, $2.36; every turn $22.89, $3.01, $2.62; the August 23 cells agree within 6%. The 45-minute figures ($1.68, $0.59, and $0.71 per 5-issue session) are from a clean re-run on August 26 after a cache-billing incident spoiled that day's first cells; the August 23 runs gave $1.67, $0.58, and $0.70. The crossover between the 5-minute and 1-hour settings is 3.1% of turns, the same measure as reference 16.
73920. **Terminal-Bench 3:** the public terminal-agent benchmark's 74 tasks, run on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with two custom tools, a shell and a file editor that the evaluation harness runs in each task's own container, in place of the platform's built-in tools, and otherwise at the platform's default settings for external accounts, two runs per model at `high` effort, August 27 to 28, 2026. Scores are raw pass rates over the 148 attempts per model; single runs swing by 5 to 11 points. Costs are what a customer would be billed at list prices, re-priced request by request from the runs' usage records with the 5-minute cache lifetime. Claude Opus 4.7 ended 11 of its 148 attempts at its output cap.
711740
712741## Next steps
713742
from line 770
741770 </Card>
742771
743772 <Card title="Webinar: Building on the Claude Platform" icon="play" href="https://www.anthropic.com/webinars/building-on-the-claude-platform-claude-fable-5-and-model-orchestration-patterns">
744 Watch a walkthrough of Claude Fable 5 and the advisor and orchestrator patterns.
773 Watch a walkthrough of the advisor and orchestrator patterns.
745774 </Card>
746775</CardGroup>
747776