Sweep 22 Sep 2026 · 17:19Z Build v2.1.280 501 read Stable v2.1.267 Latest v2.1.280 Next v2.1.280 Feeds RSS JSON llms.txt Unofficial
One capture · api

One read of Claude Developer Platform

69 pages moved out of 688 read.

api-20260901T180808Z

Pages moved 69 significant first
Pages read 688 in this capture
Captured 18:08 UTC
Corpus hash 7e990c93076e corpus-hash

What this read moved

1–25 of 69

This capture is too large to show at once. Changes 1-25 of 69 are below, significant first; the rest are on the following screens.

about-claude/models/choosing-a-model Changed · +20 / -19 lines

from line 1
11---
22title: Choosing the right model
33url: https://platform.claude.com/docs/en/about-claude/models/choosing-a-model
4description: "Selecting the optimal Claude model for your application involves balancing three key considerations: capabilities, speed, and cost. This guide helps you make an informed decision based on your specific requirements."
4description: Choosing a Claude model means balancing capabilities, speed, and cost. This guide covers the questions to ask, two ways to pick a starting model, and how to test the choice.
55---
66 
77## Establish key criteria
from line 11
1111* **Capabilities:** What specific features or capabilities will you need the model to have to meet your needs?
1212* **Speed:** How quickly does the model need to respond in your application? Claude Opus 5 and Claude Opus 4.8 support [fast mode](https://platform.claude.com/docs/en/build-with-claude/fast-mode) (research preview), which delivers up to 2.5x higher output speed at premium pricing.
1313* **Cost:** What's your budget for both development and production usage?
14* **Effort:** Recent Opus and Sonnet models support an [effort parameter](https://platform.claude.com/docs/en/build-with-claude/effort) that trades intelligence for latency and cost within a single model. Tuning effort is often a better lever than switching models. On Claude Opus 5, start with the default (`high`) and adjust up or down based on your evals. On Claude Opus 4.8 and Claude Opus 4.7, the `xhigh` effort level, between `high` and `max`, is the best setting for most coding and agentic use cases.
14* **Effort:** Several Claude models support an [effort parameter](https://platform.claude.com/docs/en/build-with-claude/effort) that trades intelligence for latency and cost within a single model. Tuning effort is often a better lever than switching models. On Claude Fable 5.1 and Claude Opus 5, start with the default (`high`) and adjust up or down based on your evals. On Claude Opus 4.8 and Claude Opus 4.7, the `xhigh` effort level, between `high` and `max`, is the best setting for most coding and agentic use cases.
1515 
16Knowing these answers in advance will make narrowing down and deciding which model to use much easier.
17 
1816***
1917 
2018## Choose the best model to start with
from line 43
45432. [Optimize your prompts](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5) for this model.
46443. Evaluate if performance meets your requirements.
47454. Consider increasing efficiency by lowering [effort](https://platform.claude.com/docs/en/build-with-claude/effort) or downgrading models over time with greater workflow optimization.
465. If your evals at `xhigh` or `max` effort still fall short on demanding reasoning or long-horizon agentic work, move to [Claude Fable 5.1](https://platform.claude.com/docs/en/models/fable-5-1/whats-new-fable-5-1).
4847 
4948This approach is best for:
5049 
from line 53
5453* Applications where accuracy outweighs cost considerations
5554* Advanced coding and high-autonomy agentic work
5655 
57<Note>
58 The [effort parameter](https://platform.claude.com/docs/en/build-with-claude/effort) defaults to `high` on Claude Opus 5 and Claude Opus 4.8, including in Claude Code and the Messages API. On Claude Opus 5, start at the default and step up to `xhigh` for the most demanding coding and agentic work. On Claude Opus 4.8, use `xhigh` for coding, high-autonomy work, and the most intelligence-demanding tasks.
59</Note>
56**Claude Opus 5** (`claude-opus-5`) is built for complex agentic coding and enterprise work, with deep reasoning, long-horizon tasks, and test-time compute scaling.
6057 
61**Claude Opus 5** (`claude-opus-5`) is a step-change improvement over Claude Opus 4.8, strong on deep reasoning, agentic and long-horizon tasks, and test-time compute scaling. Claude Opus 5 supports a 1M token context window by default and up to 128k output tokens, and is priced at $5 USD per million input tokens and $25 USD per million output tokens.
58**Claude Fable 5.1** (`claude-fable-5-1`) is Anthropic's most capable widely released model. It extends Claude Fable 5 with stronger long-running agentic coding, knowledge work, and research at the same input and output prices, with cache reads at a quarter of the cost. **Claude Mythos 5.1** (`claude-mythos-5-1`) offers the same capabilities to [Project Glasswing](https://anthropic.com/glasswing) participants only. Both models use always-on [adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking). See [What's new in Claude Fable 5.1](https://platform.claude.com/docs/en/models/fable-5-1/whats-new-fable-5-1) for details.
6259 
63**Claude Fable 5** (`claude-fable-5`) is Anthropic's most capable widely released model, delivering next-generation intelligence for long-running agents. **Claude Mythos 5** (`claude-mythos-5`) is available through [Project Glasswing](https://anthropic.com/glasswing). Both models support a 1M token context window by default, up to 128k output tokens, and always-on [adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking). See [Introducing Claude Fable 5 and Claude Mythos 5](https://platform.claude.com/docs/en/models/fable-5/introducing-claude-fable-5-and-claude-mythos-5) for launch details.
60Claude Fable 5 and Claude Mythos 5 are also available. See [Introducing Claude Fable 5 and Claude Mythos 5](https://platform.claude.com/docs/en/models/fable-5/introducing-claude-fable-5-and-claude-mythos-5) for details. For context windows, output limits, and prices, see the [model comparison table](https://platform.claude.com/docs/en/models/overview#latest-models-comparison).
6461 
65Claude Fable 5 and Claude Mythos 5 are priced at $10 USD per million input tokens and $50 USD per million output tokens.
66 
6762## Model selection matrix
6863 
69| When you need... | Consider starting with... | Example use cases |
70| ------------------------------------------------------------------------------------------------------------ | ------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
71| The highest available capability | Claude Fable 5 | Long-running agents, deep reasoning, long-horizon agentic tasks, advanced research |
72| Complex agentic coding and enterprise work | Claude Opus 5 | Multihour autonomous coding agents, large-scale refactoring, complex systems engineering, advanced research, knowledge work, vision-heavy workflows, computer use |
73| Frontier intelligence at scale, built for coding, agents, and enterprise workflows | Claude Sonnet 5 | Code generation, data analysis, content creation, visual understanding, agentic tool use |
74| Near-frontier performance with lightning-fast speed and extended thinking at the most economical price point | Claude Haiku 4.5 | Real-time applications, high-volume intelligent processing, cost-sensitive deployments needing strong reasoning, sub-agent tasks |
64Most workloads start with Claude Opus 5.
7565 
66| When you need... | Consider starting with... | Example use cases |
67| ------------------------------------------------------------------------- | ------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
68| The highest available capability | Claude Fable 5.1 | Agent sessions that run for hours, multistep deep research, analysis carried through to a finished document, spreadsheet, or deck |
69| Complex agentic coding and enterprise work | Claude Opus 5 | Multihour autonomous coding agents, large-scale refactoring, complex systems engineering, vision-heavy workflows, computer use |
70| Speed and capability for everyday coding, agent, and enterprise workloads | Claude Sonnet 5 | Code generation, data analysis, content creation, visual understanding, agentic tool use |
71| The lowest latency and price, with extended thinking | Claude Haiku 4.5 | Real-time applications, high-volume intelligent processing, cost-sensitive deployments needing strong reasoning, sub-agent tasks |
72 
7673***
7774 
7875## Decide whether to upgrade or change models
from line 99
10299 See detailed specifications and pricing for the latest Claude models
103100 </Card>
104101 
102 <Card title="What's new in Claude Fable 5.1" icon="sparkle" href="https://platform.claude.com/docs/en/models/fable-5-1/whats-new-fable-5-1">
103 Built for demanding reasoning and long-horizon agentic work
104 </Card>
105 
105106 <Card title="What's new in Claude Opus 5" icon="sparkle" href="https://platform.claude.com/docs/en/models/opus-5/whats-new-opus-5">
106 Explore the latest improvements in Claude Opus 5
107 Explore the improvements in Claude Opus 5
107108 </Card>
108109 
109110 <Card title="What's new in Claude Sonnet 5" icon="sparkle" href="https://platform.claude.com/docs/en/models/sonnet-5/whats-new-sonnet-5">
110 The best combination of speed and intelligence
111 For everyday workloads that balance speed and capability
111112 </Card>
112113 
113114 <Card title="Start building" icon="code" href="https://platform.claude.com/docs/en/get-started">

about-claude/models/optimizing-for-cost-and-intelligence Changed · +190 / -161 lines

from line 15
1515* **Free wins** cut spend without touching quality: prompt caching, token hygiene, a prompt audit against the model you are running, [batch processing](https://platform.claude.com/docs/en/build-with-claude/batch-processing) at 50% off for work that can wait up to 24 hours, and [workspace spend limits](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the backstop.
1616* **Tradeoffs** exchange cost for intelligence: model choice, effort, output caps and task budgets, and multi-model architectures.
1717 
18Each lever comes with measured results and the rule for when it pays. In Anthropic's measurements, prompt caching was the largest lever by a wide margin: it cut agent-loop cost by a factor of 2.5 to 3.7 on this guide's benchmarks and cut a small triage agent's bill by 83%, or 88% with input trimming added. The multi-model levers are narrower; a second model paid off in two shapes, an advisor and an orchestrator.
18Each lever comes with measured results and the rule for when it pays. In Anthropic's measurements, prompt caching was the largest lever by a wide margin: it cut agent-loop cost by a factor of 2.7 to 5.3 on this guide's benchmarks and cut a small triage agent's bill by 83%, or 88% with input trimming added. The multi-model levers are narrower; a second model paid off in two shapes, an advisor and an orchestrator.
1919 
2020## Start here
2121 
2222Match your situation to a row.
2323 
24| Your situation | Do this | Where |
25| ------------------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
26| Any workload, any model | Turn on prompt caching and trim unneeded tokens; both are free | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) · [Trim tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
27| A person waits between turns | Use the 1-hour cache duration; it is cheaper once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
28| Costs are too high; quality is fine | Sweep effort down on your current model | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
29| You are not on the latest model | Upgrade; the current model solves more, usually at lower cost per solved task | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
30| You are choosing or switching models | Compare on cost per completed task, not per token | [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
31| Quality isn't good enough | If you lowered effort, restore it; otherwise try the next tier up at `low` effort | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) · [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
32| Attempts end with `stop_reason: max_tokens` | Raise `max_tokens`; 64,000 covered every turn measured and cost nothing extra per solved task | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
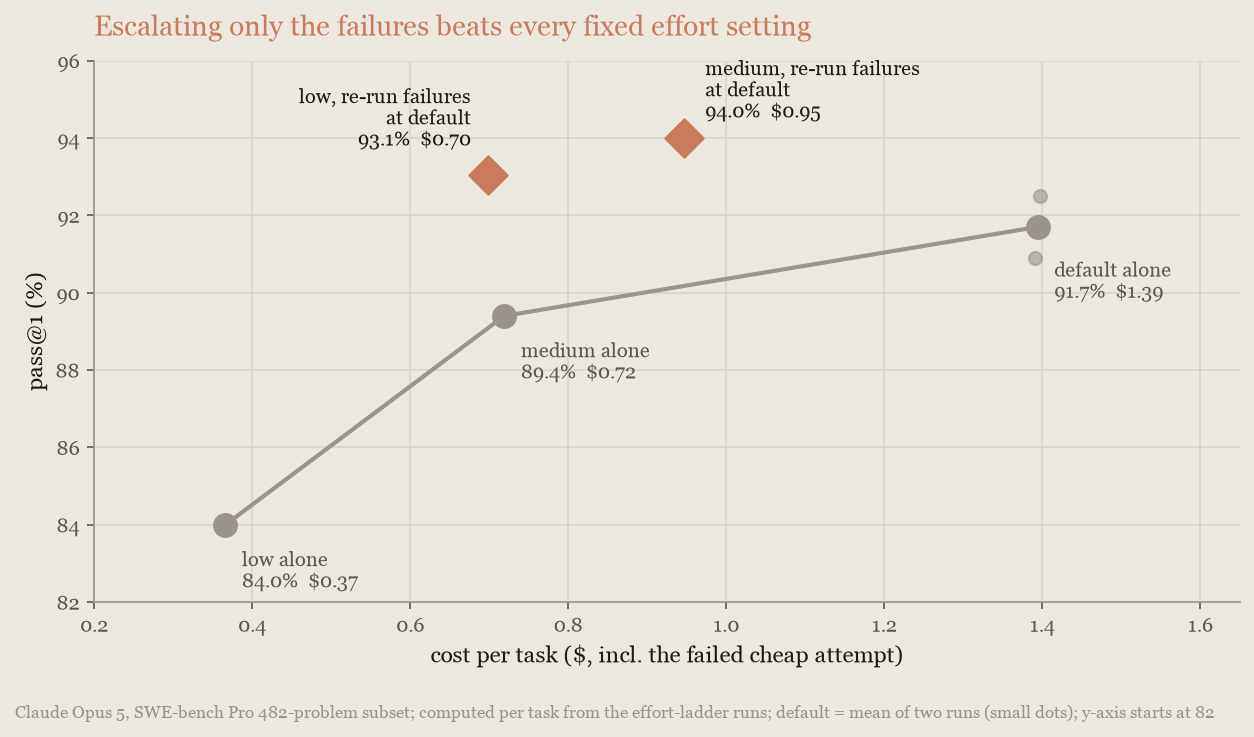
33| You can check outputs (tests, a verifier) | Run everything at low effort and re-run failures at the default (`high`); on the coding benchmark measured, the pass rate held at about half the cost | [Re-run failures](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
34| Agent loops with a few very costly runs | Set a task budget (beta; not currently available on Claude Sonnet 5), a Claude Managed Agents session budget, and a workspace spend limit | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
35| A lower-cost model stalls only on hard decisions | Add a frontier advisor. It pays off when priced well above the executor and actually consulted, so first price the advisor's model alone at low effort and measure the consult rate | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
36| The work exceeds one context window | Delegate partitions to cheaper workers | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
24| Your situation | Do this | Where |
25| ------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
26| Any workload, any model | Turn on prompt caching and trim unneeded tokens; both are free | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) · [Trim tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
27| A person waits between turns | Use the 1-hour cache duration once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour. On Claude Fable 5.1, keep the 5-minute cache warm while pauses run minutes, and buy the 1-hour duration when pauses run toward an hour | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
28| Costs are too high; quality is fine | Sweep effort down on your current model | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
29| You are not on the latest model | Upgrade; the current model solves more tasks, at a cost per solved task from about 40% lower to about 20% higher | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
30| You are choosing or switching models | Compare on cost per completed task, not per token | [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
31| Quality isn't good enough | If you lowered effort, restore it; otherwise try the next tier up at `low` effort | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) · [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) |
32| Attempts end with `stop_reason: max_tokens` | Raise `max_tokens`; 64,000 covered all but 2 of 14,000 turns measured at the default effort, and 128,000 cost nothing extra per solved task | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
33| You can check outputs (tests, a verifier) | Run everything at low effort and re-run failures at the default (`high`); on the coding benchmark measured, the pass rate held at about half the cost | [Re-run failures](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
34| Agent loops with a few very costly runs | Set a task budget (beta; check the support table for which models), a Claude Managed Agents session budget, and a workspace spend limit | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
35| A lower-cost model stalls only on hard decisions | Add a frontier advisor. It pays off when priced well above the executor and actually consulted, so first price the advisor's model alone at low effort and measure the consult rate | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
36| The work exceeds one context window | Delegate partitions to cheaper workers | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
3737 
3838These results are Anthropic-internal ([Benchmarks referenced](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs)) and directional, not guarantees, so measure on your own workload with the [four-step method](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#measure-on-your-own-workload).
3939 
from line 49
4949 
5050**What good looks like.** Over a full day of real traffic, agent loops read a median 84% of their input from the cache, and the top 10% of harnesses, coding or not, read 94% or more[17](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Deep in a task, a well-built loop pays full price on under 1% of its input. Below about 80%, look for something breaking the cache (see [What breaks the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#what-breaks-the-cache)).
5151 
52Across Anthropic's measured runs, cache reads are routinely the largest single component of task cost, making caching worth more than most model-choice decisions. Anthropic priced WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) and DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) runs with and without caching:
52Across Anthropic's measured runs, cache reads are routinely the largest single component of task cost, making caching worth more than most model-choice decisions. Anthropic priced the DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) runs with and without caching:
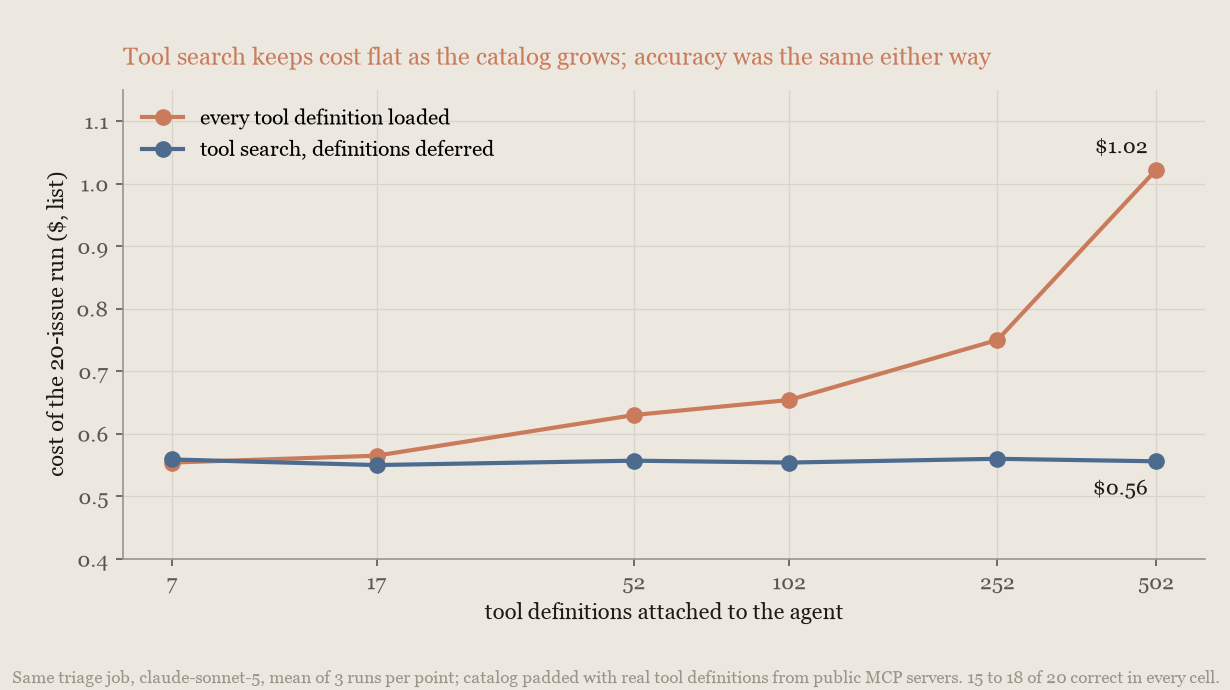
5353 
54![Dumbbell chart, cost per problem with and without prompt caching: each configuration's cost falls by a factor of 2.5 to 3.7](https://platform.claude.com/docs/images/cost-intel-caching.png)
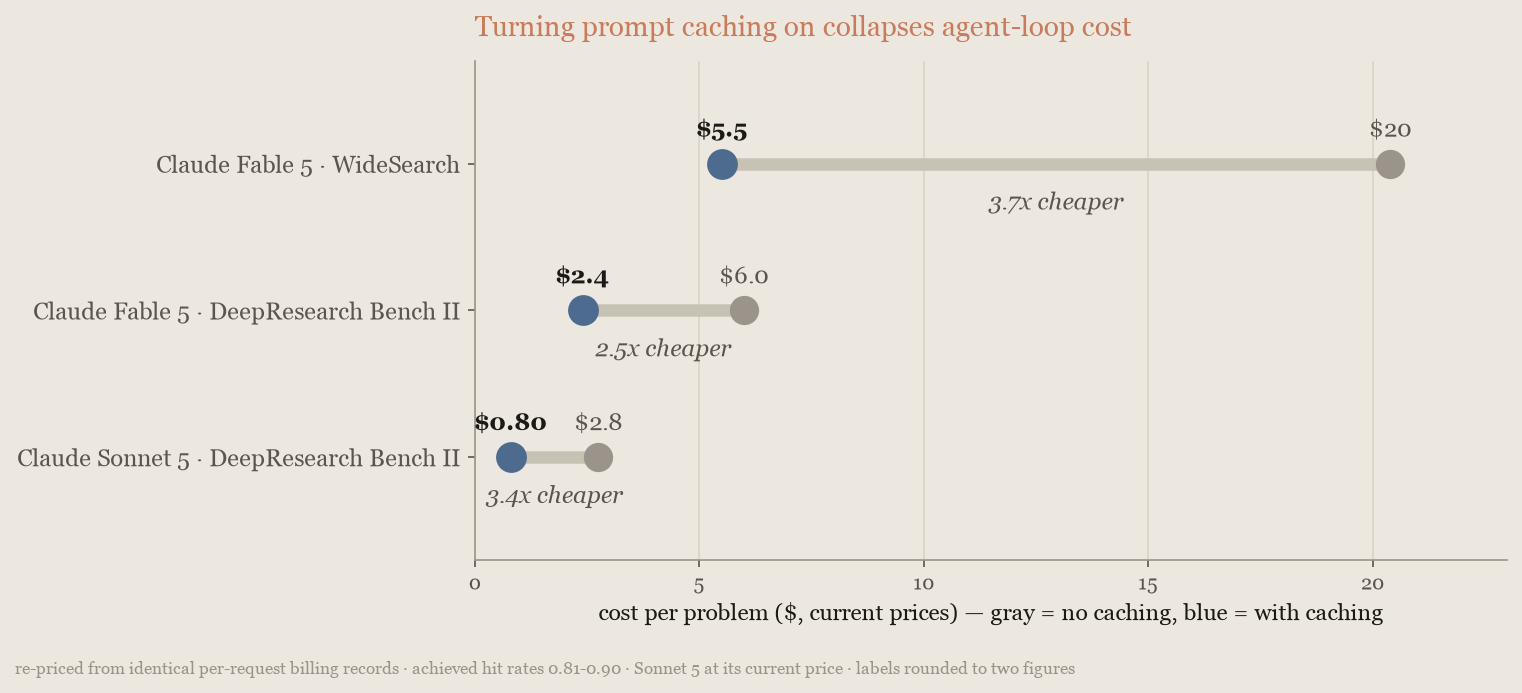
54![Dumbbell chart, DeepResearch Bench II: with caching, Claude Fable 5.1 falls from $37.94 to $7.12 per task and Claude Sonnet 5 from $3.20 to $1.20](https://platform.claude.com/docs/images/cost-intel-caching.png)
5555 
56The cache's default lifetime is 5 minutes and an agent loop's turns are seconds apart, so the discount applies to most tokens on every turn. The caching chart's runs achieved 81% to 90% hit rates. The saving varies with episode depth, because shorter loops re-read less, but caching stayed the largest single lever on every model and benchmark measured.
56The cache's default lifetime is 5 minutes and an agent loop's turns are seconds apart, so the discount applies to most tokens on every turn. The caching chart's runs read 79% to 90% of their input tokens from the cache. The saving varies with episode depth, because shorter loops re-read less, but caching stayed the largest single lever on every model and benchmark measured.
5757 
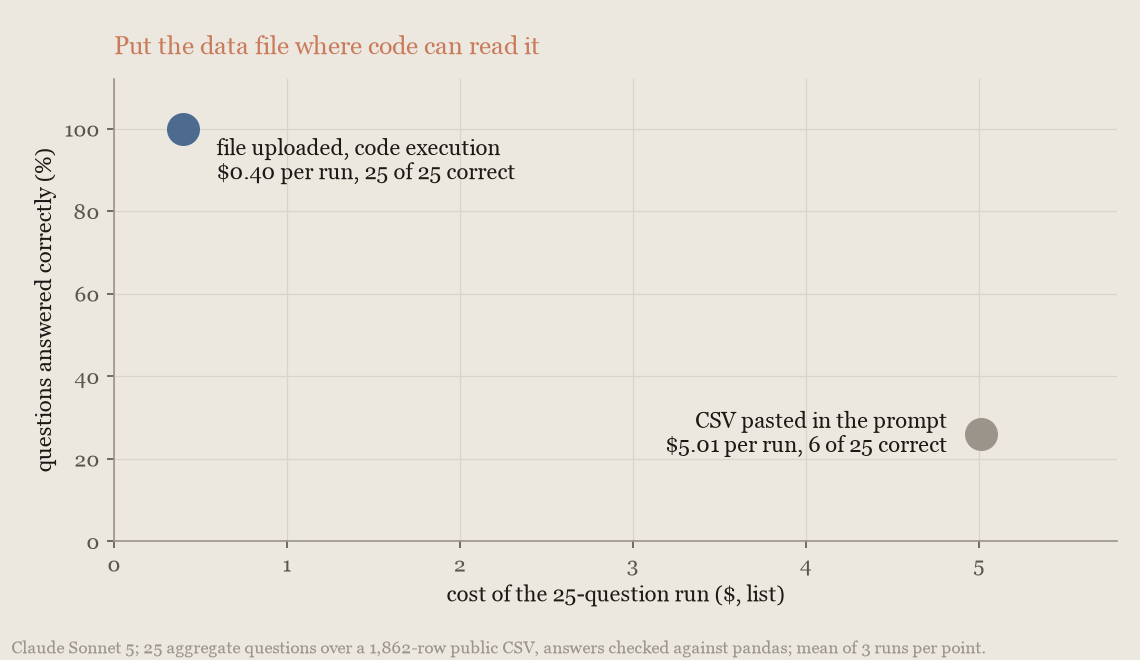
5858#### Pick the cache duration
5959 
from line 63
6363 
6464* More than about 1 gap in 20 falls between 5 minutes and an hour, and gaps over an hour are rare: use the 1-hour duration.
6565* Turns arrive seconds apart: stay on the 5-minute default. When nothing paused, it cost 15% less than the 1-hour setting on Claude Sonnet 5 and 11% less on Claude Opus 5.
66* Gaps over an hour are common: stay on the default. A gap over an hour expires both durations, and the 1-hour setting then re-writes the prefix at 2x the input price instead of 1.25x, so it loses on each of those gaps. It pays off only when, beyond the 1-in-20 share, gaps between 5 minutes and an hour are at least about two-thirds as frequent as gaps over an hour (each in-band gap saves about 1.15x the prefix; each gap over an hour costs about 0.75x).
66* Gaps over an hour are common: stay on the default. A gap over an hour expires both durations, and the 1-hour setting then re-writes the prefix at its higher write price, so it loses on each of those gaps. Of your pauses longer than 5 minutes, if about 60% or more also run past an hour, stay on the default; the 1-hour duration pays only when at least about 40% of long pauses end within the hour.
6767 
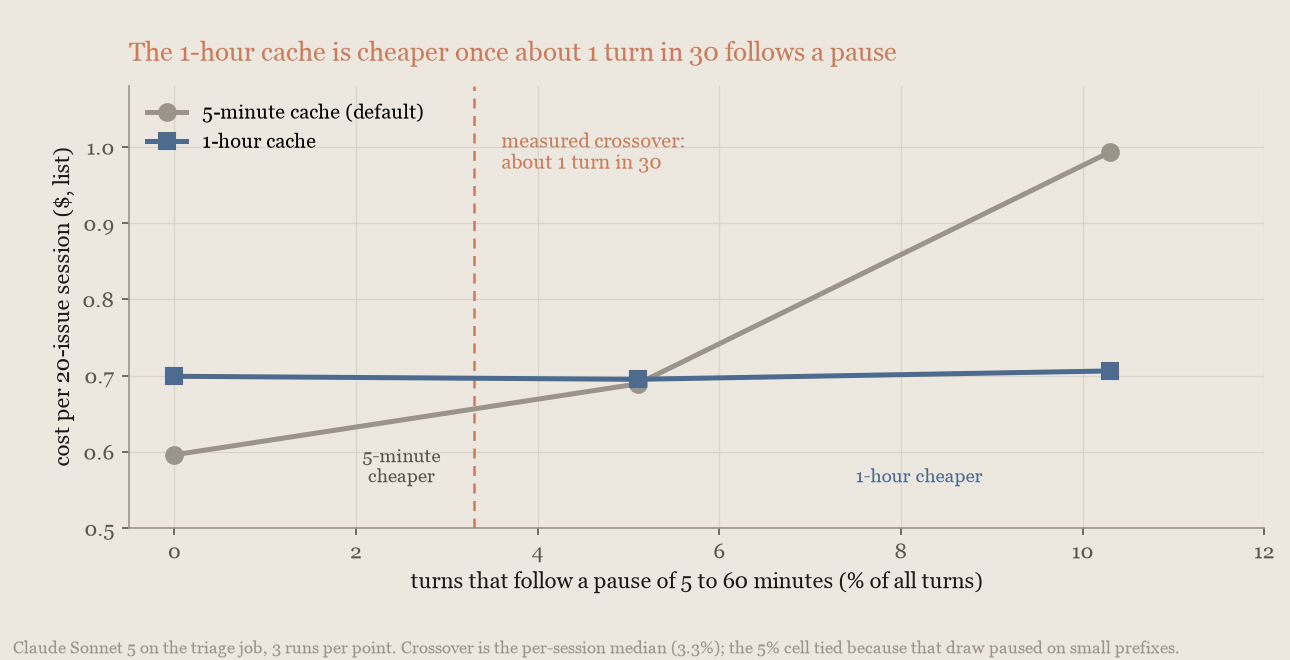
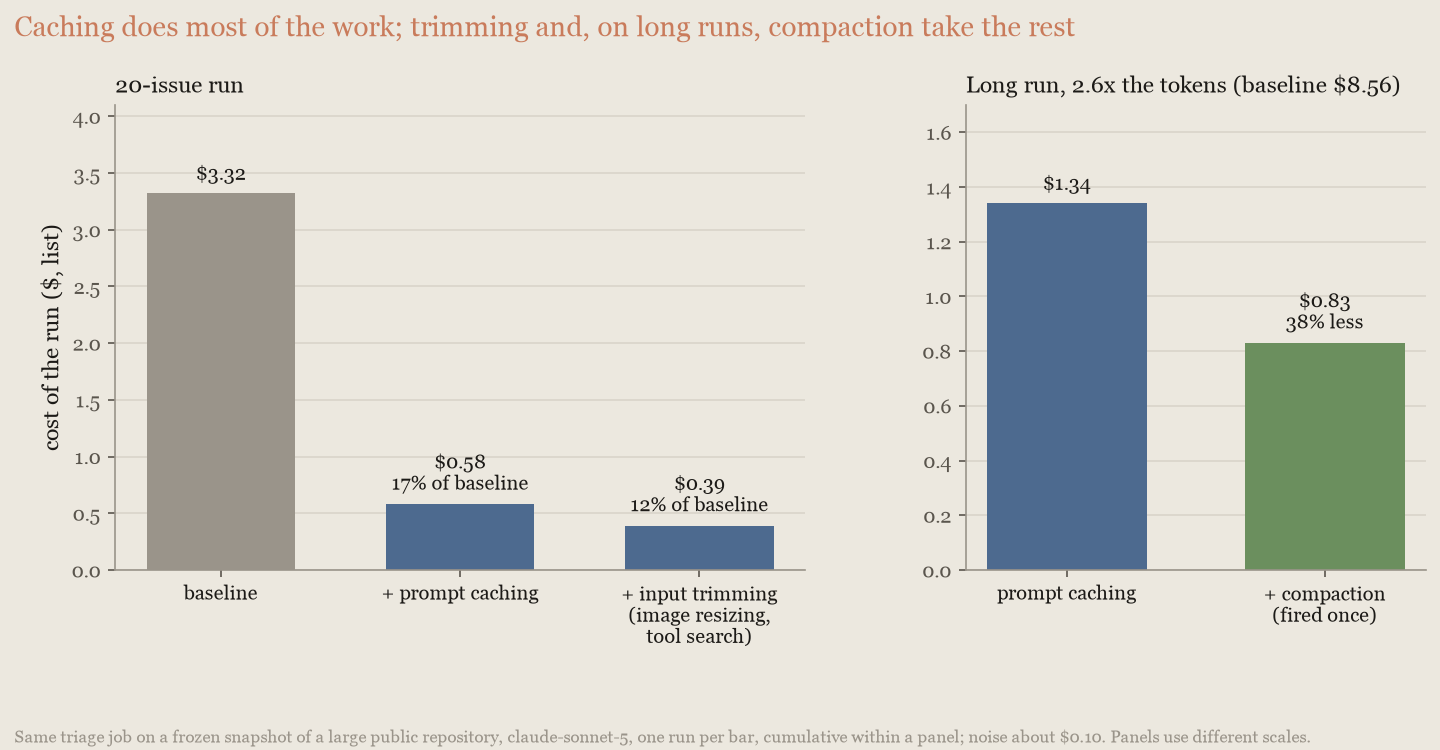
68Anthropic measured the triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) with pauses inserted before some turns to simulate a person's delay[16](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). On both models measured, the 1-hour cache became the cheaper setting once about 1 turn in 30 followed a pause, so the 1-in-20 rule leaves a margin, and the gap widens quickly past the crossover because every paused turn on the 5-minute setting re-writes the whole prefix. Every current model uses the same cache multipliers, so the crossover is in the same range on the other models; the exact share depends on how much of a session the model re-reads. Accuracy stayed within run-to-run noise in every cell. The turn after a pause kept its warm-cache latency on the 1-hour setting. The following chart plots cost per session against the share of paused turns on Claude Sonnet 5:
68Anthropic measured the triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) with pauses inserted before some turns to simulate a person's delay[16](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). On both models measured, the 1-hour cache became the cheaper setting once about 1 turn in 30 followed a pause, so the 1-in-20 rule leaves a margin, and the gap widens quickly past the crossover because every paused turn on the 5-minute setting re-writes the whole prefix. Every current model uses the same cache-write multipliers, and every model but Claude Fable 5.1 and Claude Mythos 5.1 the same read price, so the crossover is in the same range on the other models; Fable 5.1 is the case covered next. Accuracy stayed within run-to-run noise in every cell. The turn after a pause kept its warm-cache latency on the 1-hour setting. The following chart plots cost per session against the share of paused turns on Claude Sonnet 5:
6969 
7070![Line chart: cost per triage session by share of turns after a pause; the 1-hour cache is cheaper past about 1 turn in 30](https://platform.claude.com/docs/images/cost-intel-cache-ttl.png)
7171 
72Anthropic also measured extra requests that keep the 5-minute cache warm. They saved nothing measurable over the 1-hour duration at any share of paused turns and cost more with a pause before every turn, so use the duration instead.
72Anthropic also measured extra requests that keep the 5-minute cache warm. On Claude Sonnet 5 and Claude Opus 5 they saved nothing measurable over the 1-hour duration at any share of paused turns and cost more with a pause before every turn, so use the duration instead.
7373 
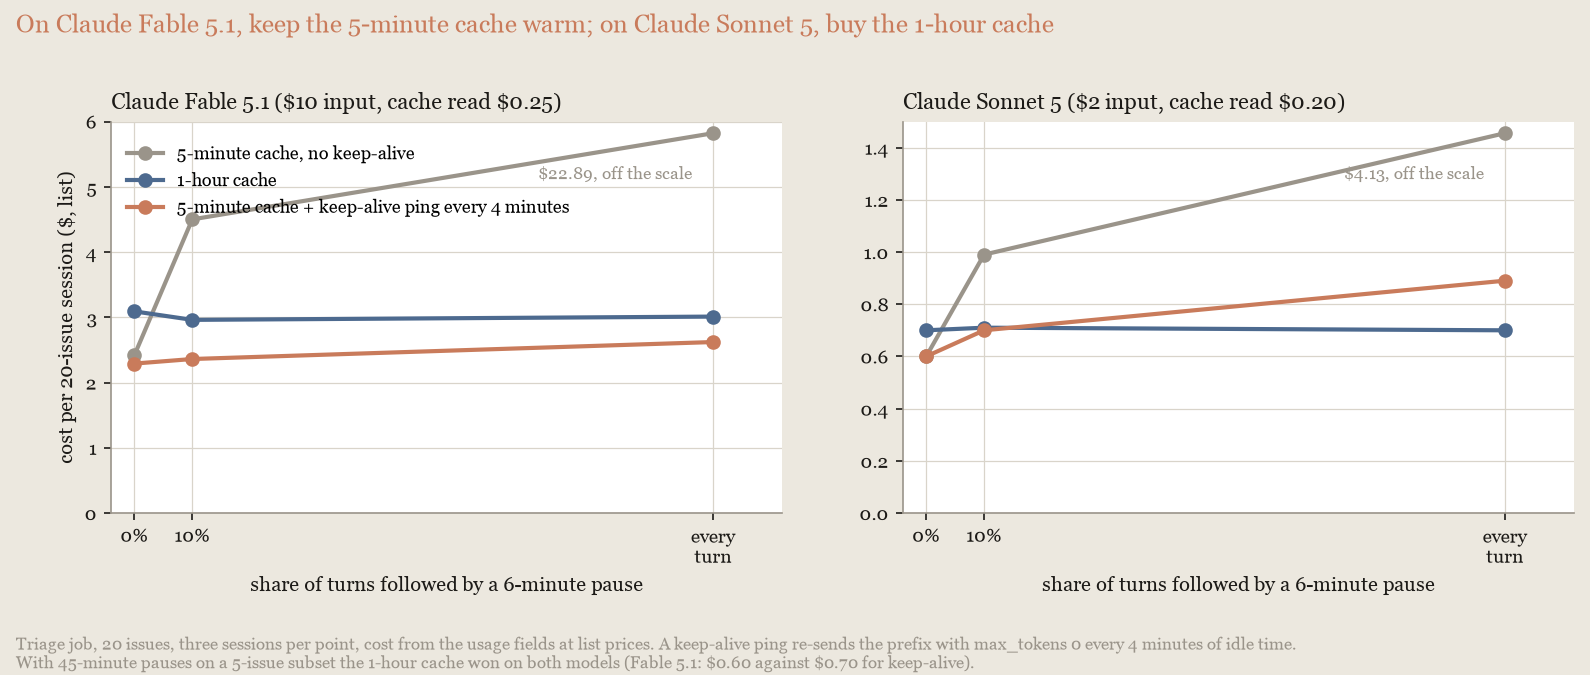
74On Claude Fable 5.1 the cheapest setting is a different one. Its [cache read](https://platform.claude.com/docs/en/about-claude/pricing#prompt-caching) costs 0.025x the input price ($0.25 per million tokens) while its cache writes keep the standard multipliers, so a keep-alive request that re-reads the prefix is cheap and the 1-hour duration's write premium is the larger bill. Anthropic measured the triage job on Claude Fable 5.1 with the same three settings[19](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Keeping the 5-minute cache warm cost 13% to 20% less per session than the 1-hour cache whenever pauses ran for minutes; only with pauses near 45 minutes did the 1-hour cache win, by about 12 cents a session. On Claude Fable 5.1, keep the 5-minute cache warm while a person is away for minutes, and buy the 1-hour duration when pauses run toward an hour:
75 
76![Line chart: measured cost per triage session by share of paused turns on Claude Fable 5.1 and Claude Sonnet 5; on Fable 5.1 keep-alive stays under the 1-hour cache, on Sonnet 5 the 1-hour cache wins once pauses are common](https://platform.claude.com/docs/images/cost-intel-cache-keepalive.png)
77 
78To keep the cache warm, send the previous request again with `max_tokens` set to 0 within 4 minutes of the previous request's start, and every 4 minutes after that, dropping `stream` if it was set. Count from the request's start, not its response's end: the [cache's 5-minute lifetime](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#how-prompt-caching-works) runs from the start of the request that wrote or refreshed the entry, so time the response spent generating counts against it. That is the [pre-warming request](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#pre-warming-the-cache): it refreshes the cache's lifetime, generates nothing, and bills only the cache read. Do not change a byte of the prefix, and do not use `max_tokens: 1`, which samples a token for no reason. Re-send the request's headers as well as its body: if your requests carry an `anthropic-beta` header (for a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets), say), the keep-alive request needs the same header, or the beta-gated fields in the replayed body are rejected. A `max_tokens: 0` request is rejected when the request sets `thinking.type: "enabled"` (the default adaptive thinking on Claude Fable 5.1 is fine), structured outputs, or a forced tool choice ([its limitations](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#limitations)); on those workloads, buy the 1-hour duration instead.
79 
80<CodeGroup exclude="shell:CLI, python, typescript, csharp, go, java, php, ruby">
81 ```bash cURL
82 # Within 4 minutes of the last request's start (time spent generating counts
83 # against the cache's lifetime), re-send that request with max_tokens set to
84 # 0, dropping stream (a max_tokens: 0 request cannot stream). Send the same
85 # headers as the original request, including any anthropic-beta header.
86 jq '.max_tokens = 0 | del(.stream)' last_request.json | \
87 curl https://api.anthropic.com/v1/messages \
88 -H "x-api-key: $ANTHROPIC_API_KEY" \
89 -H "anthropic-version: 2023-06-01" \
90 -H "content-type: application/json" \
91 --data-binary @-
92 ```
93</CodeGroup>
94 
7495#### Turn on caching
7596 
7697Setup takes little work. [Automatic caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#automatic-caching) places breakpoints for you; otherwise, the [Claude API skill](https://platform.claude.com/docs/en/agents-and-tools/agent-skills/claude-api-skill) that ships with Claude Code can add caching to an existing integration from one prompt. The following excerpt shows the skill adding it to the harness that produced these measurements:
from line 121
100121 
101122Several things can break your cache during a task. Anything that changes per request, such as a timestamp or a queue position, placed ahead of the stable prefix turns every request into a full cache write: on the triage run in [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), a 25-token status line at the front of the system prompt cost $4.24 per run instead of $0.59, more than running with caching off. Keep per-request text in the newest user turn.
102123 
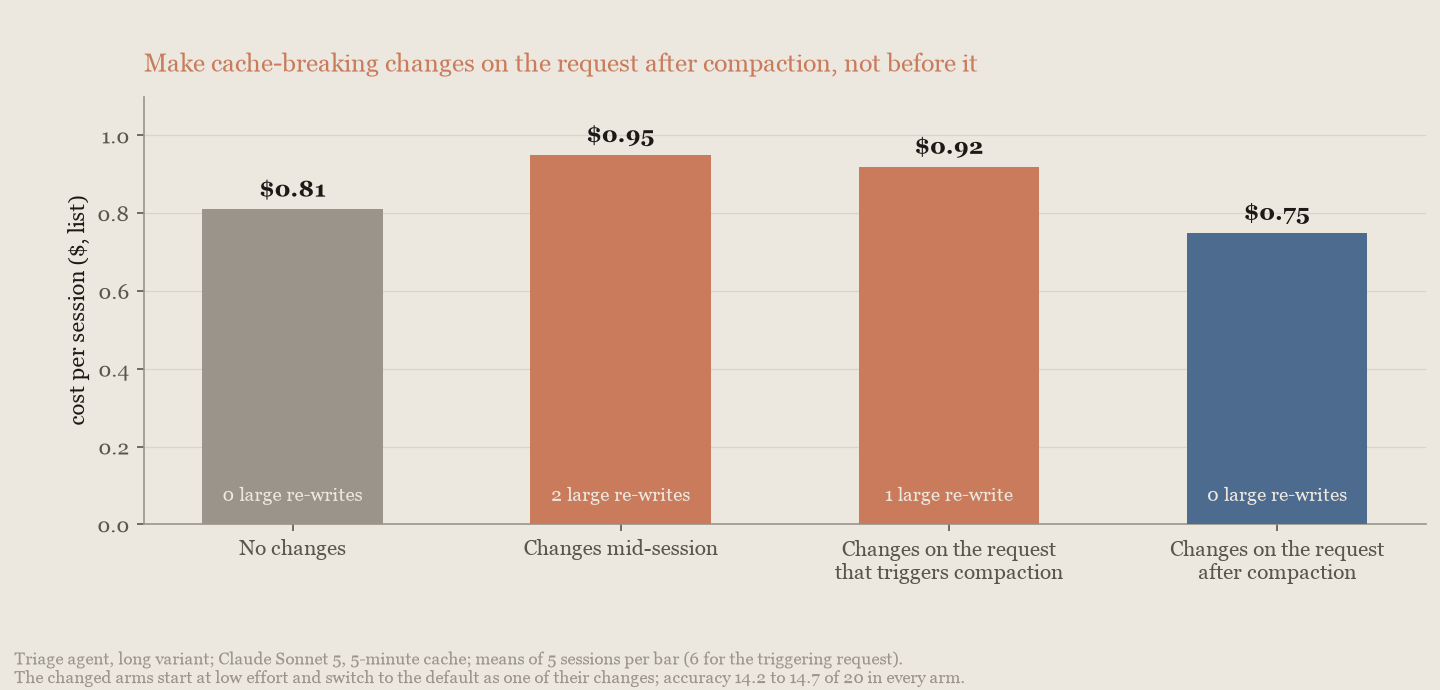
103The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On Claude Opus 5 (and Claude Fable 5, Claude Mythos 5, and Claude Opus 4.8), change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. The same page covers mid-conversation tool changes, in beta on those models. Otherwise, make such changes only where you would re-cache anyway, such as at a [compaction](https://platform.claude.com/docs/en/build-with-claude/compaction) boundary, and on the first request after the compaction rather than the one that triggers it.
124The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On the most recent models, change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. Check that page for which models support it. On models that support it, a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) leaves the cached prefix intact too. The stakes are highest on Claude Fable 5.1 and Claude Mythos 5.1: a break re-writes the prefix at 1.25x the input price instead of reading it at 0.025x, so on a 100,000-token prefix one broken turn costs $1.25 instead of $0.03, 50 times the read, against 12.5 times ($0.63 instead of $0.05) on Claude Opus 5.
104125 
105126Anthropic measured this on the triage agent's long sessions[18](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). An effort change and an added tool made mid-session rewrote 39,000 and 60,000 cached tokens, and those sessions cost $0.95 per session. The same two changes on the first request after compaction cost $0.75, and on the request that triggered the compaction $0.92, because the compaction's summarization pass then re-processed the 81,000-token context at the cache-write price: that summarization pass cost $0.21, against $0.04 when the same changes came one request later, with accuracy within run-to-run noise in every arm:
106127 
107128![Bar chart, cost per triage session: $0.81 no changes, $0.95 mid-session changes, $0.92 on the compaction request, $0.75 after](https://platform.claude.com/docs/images/cost-intel-compaction-timing.png)
108129 
109Changing a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) partway through invalidates any cached prefix that contains the budget value, so set it once, on the first request. Every [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching) pass invalidates the prefix from the point it clears and the next request pays to re-cache everything after it, so clear in a few large batches rather than many small ones. Make every cache-invalidating change at natural breaks, then confirm cache reads have not dropped; if they have, [cache diagnostics](https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics) shows where the prefix diverged.
130Changing a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) partway through invalidates any cached prefix that contains the budget value, so set it once, on the first request. Every [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching) pass invalidates the prefix from the point it clears and the next request pays to re-cache everything after it, so clear in a few large batches rather than many small ones. On Claude Fable 5.1 and Claude Mythos 5.1 each of these costs 50 times the read price per token, so they matter most there. Make every cache-invalidating change at natural breaks, then confirm cache reads have not dropped; if they have, [cache diagnostics](https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics) shows where the prefix diverged.
110131 
111132### Trim input and context tokens
112133 
113Most agent requests carry tokens that never influence the answer. Trimming them costs nothing in output quality, although not every lever here saved money when measured. Two places to look:
134Most agent requests carry tokens that never influence the answer. Trimming them rarely costs output quality, although not every lever here saved money when measured. Two places to look:
114135 
115136* **Input trimming.** [Dynamic filtering](https://platform.claude.com/docs/en/agents-and-tools/tool-use/web-fetch-tool#dynamic-filtering) in the web fetch tool keeps boilerplate out of fetched pages, [image resizing](https://platform.claude.com/docs/en/build-with-claude/vision#evaluate-image-size) right-sizes vision inputs, and [tool search with deferred loading](https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool) loads tool definitions only when needed (measured later in this section). [Programmatic tool calling](https://platform.claude.com/docs/en/agents-and-tools/tool-use/programmatic-tool-calling) lets Claude run several tool calls from code so only the filtered result enters the context; its documentation reports 24% fewer input tokens on agentic search benchmarks, with a higher score. [Manage tool context](https://platform.claude.com/docs/en/agents-and-tools/tool-use/manage-tool-context) compares tool search, programmatic tool calling, prompt caching, and context editing.
116137* **Context lifecycle.** [Context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing) clears stale tool results, and [automatic compaction](https://platform.claude.com/docs/en/build-with-claude/compaction) with its threshold stops long loops from carrying their whole history forward.
from line 144
123144 
124145![Line chart: with all tools loaded, run cost rises from $0.55 to $1.02 at 502 tools; with tool search it stays at $0.56](https://platform.claude.com/docs/images/cost-intel-tool-search.png)
125146 
126With every definition loaded, the run cost rose from $0.55 to $1.02, tracking the schema tokens on each request. With tool search, it stayed at $0.56 at every catalog size, 45% less at 502 tools. Accuracy was 15 to 18 of 20 in every cell either way, and the model never called a wrong tool, so at this scale the catalog costs money, not correctness. The same holds for tools that come through the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector): with a public GitHub MCP server attached, deferring its toolset (`default_config: {defer_loading: true}`) cut the run 20% at the same accuracy.
147With every definition loaded, the run cost nearly doubled as the catalog grew, tracking the schema tokens on each request. With tool search it stayed flat at every catalog size, 45% less at 502 tools. Accuracy was 15 to 18 of 20 in every cell either way, and the model never called a wrong tool, so at this scale the catalog costs money, not correctness. The same holds for tools that come through the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector): with a public GitHub MCP server attached, deferring its toolset (`default_config: {defer_loading: true}`) cut the run 20% at the same accuracy.
127148 
128149#### Keep data files out of the prompt
129150 
from line 152
131152 
132153![Scatter chart: with the file uploaded and code execution, 25 of 25 correct at $0.40; pasted into the prompt, 6 of 25 at $5.01](https://platform.claude.com/docs/images/cost-intel-data-files.png)
133154 
134Pasted into the prompt, the table is about 91,000 input tokens on every request, and Claude Sonnet 5 answered 6 of 25 questions correctly at $5.01 per run. Uploaded, with code execution, it answered 25 of 25 at $0.40. Claude Opus 5 showed the same pattern (6 of 25 at $13.45 against 25 of 25 at $1.91).
155Pasted into the prompt, the table is about 91,000 input tokens on every request, and Claude Sonnet 5 answered 6 of 25 questions correctly. Uploaded, with code execution, it answered all 25, and the run cost about a twelfth as much. Claude Opus 5 showed the same pattern.
135156 
136157#### Manage the context lifecycle
137158 
138The context levers are where the two runs diverge:
159The context levers only pay on a session long enough to need them:
139160 
140161![Bar chart by run length: context editing adds 74% on the short run; compaction saves 32% and pruning 39% on the long](https://platform.claude.com/docs/images/cost-intel-hygiene.png)
141162 
142The context levers only pay on a session long enough to need them. On the 20-issue run, context editing cost 74% more, and compaction and the prune changed nothing. On the long run, context editing changed nothing, compaction saved 32%, and the prune saved 39%. The prune is a few lines you write yourself: at each task boundary, replace large stale tool results with a one-line extract. It caches well because the edits sit at the tail of the conversation, where the next task adds new content anyway: 89% cache reads on the first request after a boundary and 81% on the requests between boundaries. Run-wide, the prune and context editing cache equally well. The prune is cheaper because context editing rewrites content mid-task that the prune deletes (about two thirds of the gap) and because it keeps the context about half the size (the other third). If you use context editing, [clear in a few large batches](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching). The prune, adapted from the harness:
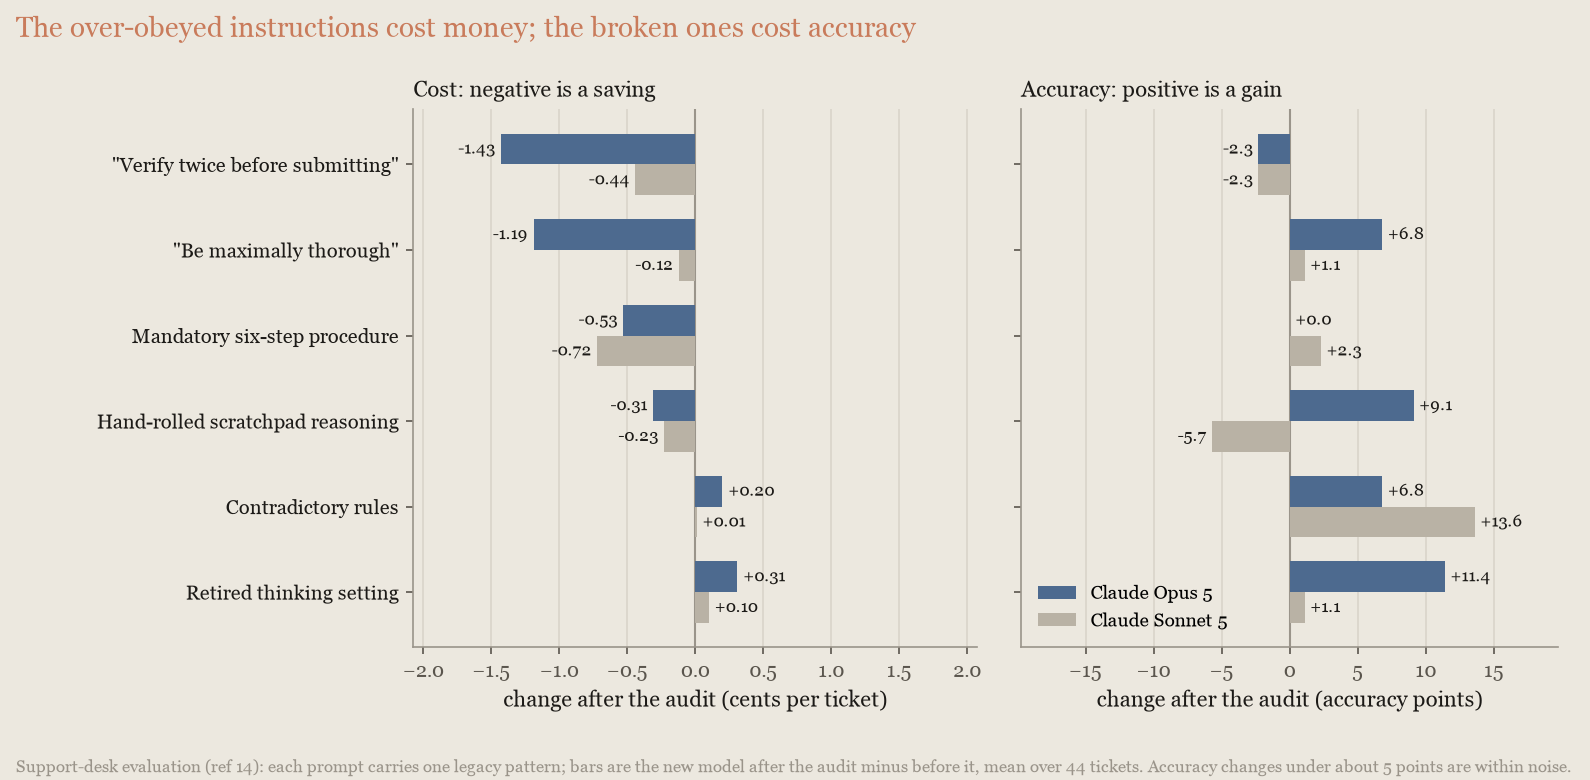
163On the 20-issue run they saved nothing, and context editing cost 74% more. On the long run the prune saved 39% and compaction 32%, while context editing changed nothing. The prune is a few lines you write yourself: at each task boundary, replace large stale tool results with a one-line extract. It caches well because the edits sit at the tail of the conversation, where the next task adds new content anyway: 89% cache reads on the first request after a boundary and 81% on the requests between boundaries. Run-wide, the prune and context editing cache about equally well. The prune is cheaper because context editing rewrites content mid-task that the prune deletes (about two thirds of the gap) and because it keeps the context about half the size (the other third). If you use context editing, [clear in a few large batches](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching). The prune, adapted from the harness:
143164 
144165```python
145166import re
from line 237
216237 
217238![Bar charts per legacy pattern: over-obeyed instructions cost money; broken settings and contradictory rules cost accuracy](https://platform.claude.com/docs/images/cost-intel-prompt-audit-patterns.png)
218239 
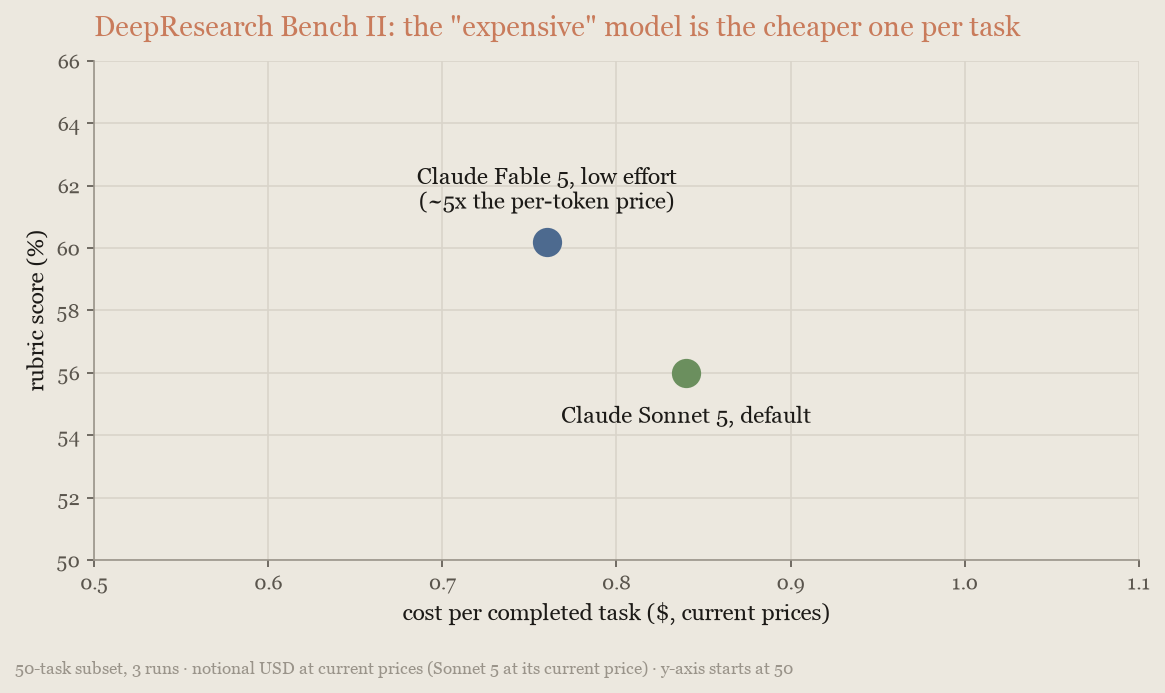
219The same patterns appear in tool descriptions and skills, and are worth removing there too.
240The same patterns tend to appear in tool descriptions and skills, which are worth auditing too.
220241 
221242## Trade cost against intelligence
222243 
223These levers set where a single model sits between cost and intelligence: model choice, effort, re-running failures at a higher setting, and the budgets and caps it works within. Start with an effort sweep on your current model ([Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort)). From lowest to highest cost and capability, the current models are Claude Haiku 4.5, Claude Sonnet 5, Claude Opus 5, and Claude Fable 5 (the frontier model); [Models overview](https://platform.claude.com/docs/en/models/overview) has the full lineup and prices.
244These levers set where a single model sits between cost and intelligence: model choice, effort, re-running failures at a higher setting, and the budgets and caps it works within. Start with an effort sweep on your current model ([Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort)). From lowest to highest cost and capability, the current models are Claude Haiku 4.5, Claude Sonnet 5, Claude Opus 5, and Claude Fable 5.1 (the frontier model); [Models overview](https://platform.claude.com/docs/en/models/overview) has the full lineup and prices.
224245 
225246### Compare models on cost per task
226247 
227Price lists are written per token, and per token the frontier model looks expensive: Claude Fable 5's per-token price is several times Claude Sonnet 5's. You pay for completed tasks, though, so compare models on cost per completed task. A more capable model finishes a task with less work: fewer turns, less searching, less re-reading of its own context, and less backtracking. The per-token premium is routinely overwhelmed by doing less of everything.
248Price lists are written per token, and per token the frontier model looks expensive: Claude Fable 5.1's per-token price is several times Claude Sonnet 5's. You pay for completed tasks, though, so compare models on cost per completed task. A more capable model finishes a task with less work: fewer turns, less searching, less re-reading of its own context, and less backtracking. The per-token premium is often overwhelmed by doing less of everything.
228249 
229Anthropic measured this directly on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a research-report benchmark hard enough to separate the models:
250Anthropic measured this on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, priced as a customer is billed:
230251 
231![Scatter chart, DeepResearch Bench II: Claude Fable 5 at low effort costs less per task and scores higher than Claude Sonnet 5](https://platform.claude.com/docs/images/cost-intel-cost-per-task.png)
252![Scatter chart, SWE-bench Pro: Claude Fable 5.1 at low effort solves 11 points more than Claude Sonnet 5 for 35% less per solved task; Claude Opus 5 at low effort is cheaper still](https://platform.claude.com/docs/images/cost-intel-cost-per-task.png)
232253 
233The frontier model at `low` effort was more accurate and about 10% cheaper per task than the mid-tier model, despite the per-token gap. It does not always win, though. On this page's SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, which both models largely saturate and whose scores are not comparable to the public leaderboard, Claude Opus 5 alone matched Claude Fable 5 alone (91.7% compared with 91.3%, inside run-to-run noise) at about 60% of its cost. On harder work, such as the DeepResearch Bench II tasks, Fable's advantage reappears.
254Claude Fable 5.1 at `low` effort solved 88.6% of tasks for $0.54 per solved task, against 77.4% for $0.84 from Claude Sonnet 5 at its default: 11 more points for 35% less per solved task, despite a per-token price five times higher. It does not always win, though. On the same subset, which both models largely saturate and whose scores are not comparable to the public leaderboard, Claude Opus 5 alone matched Claude Fable 5.1 alone at the default (91.7% compared with 92.1%, inside run-to-run noise) at about 15% less per solved task ($1.01 against $1.19), and Opus 5 at `low` solved 84.0% for $0.25. And on long research loops the frontier model does more work, not less: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Fable 5.1 at `low` scored 10 points above Sonnet 5 (66% against 56%) at about four times the cost per task ($4.66 against $1.20), because it runs a longer research loop over a larger context. Claude Opus 5 at its default scored 71% on the same basis for $6.71 per task, above Fable 5.1 at its default (65% for $7.12), so on research too Fable 5.1 earns its price only at `low`.
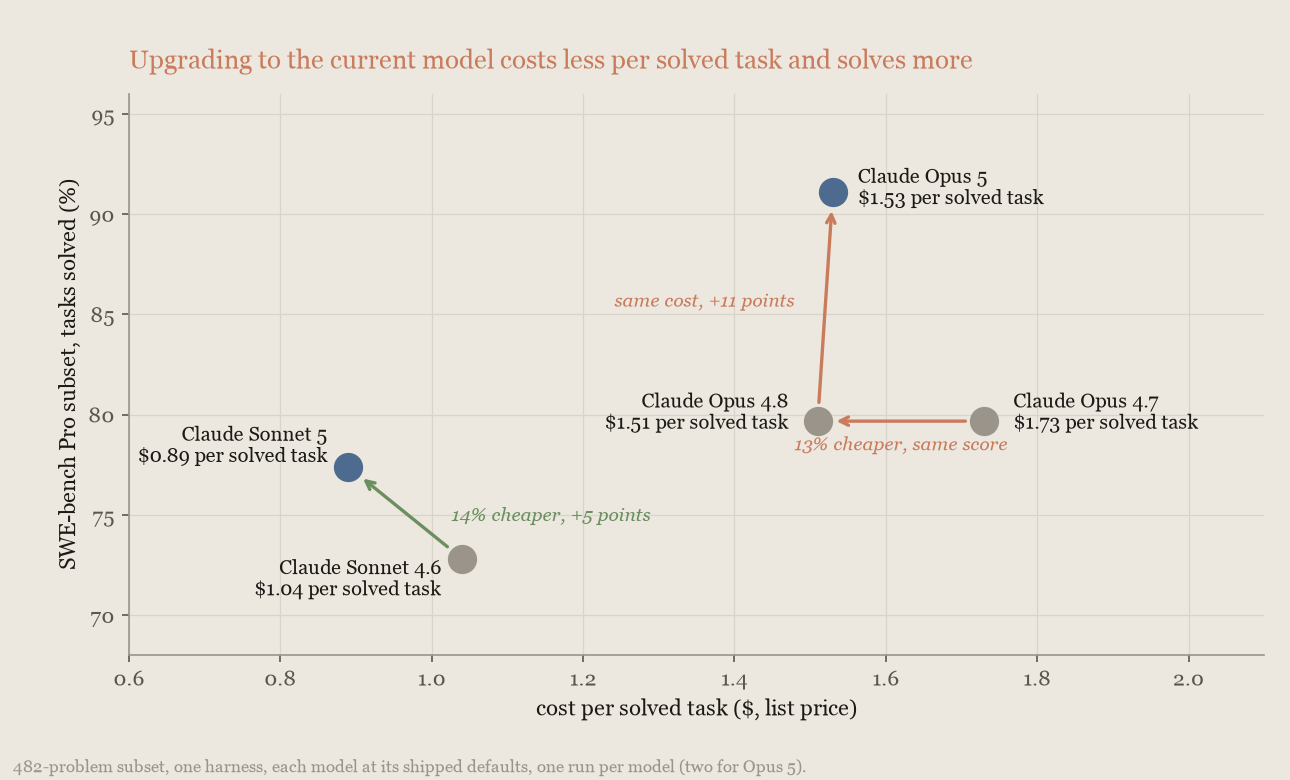
234255 
235For most agent workloads, start with Claude Opus 5: per token it costs half what Fable 5 does and 2.5 times what Sonnet 5 does, and on that coding subset it matched Fable's accuracy. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a tenth of Opus 5's cost per question, with 63% accuracy compared with 92% for Opus, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
256For most agent workloads, start with Claude Fable 5.1 at `low` effort and raise effort where it misses. Per token it costs twice what Claude Opus 5 does on uncached input, but half as much on cached input ($0.25 against $0.50 per million), and in an agent loop cached input is the largest term. On the coding benchmark in [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions), Fable 5.1 at `medium` matched Opus 5 at its default for about a third of the cost per attempt ($2.91 against $8.50). On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a chart-reading benchmark, Fable 5.1 at `low` scored 62.5 for $0.15 a chart, compared with 49 for $0.38 from Opus 5 at `low`. On the SWE-bench Pro subset, Claude Opus 5 at its default remains the cheaper way to the top score, as noted earlier. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a tenth of Opus 5's cost per question, with 63% accuracy compared with 92% for Opus, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
236257 
237258The ranking flips by workload, and no price list tells you which way. Price every candidate in cost per completed task on your own traffic, including Claude Opus 5 and the frontier model at reduced effort.
238259 
from line 265
244265 
245266### Upgrade the model
246267 
247If you are a model or two behind, the cheapest lever is the model string. Anthropic ran recent Claude Opus and Claude Sonnet models through the same harness on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, each at its shipped defaults, and priced each at list rates:
268If you are a model or two behind, the cheapest lever is the model string. Anthropic ran recent Claude Opus, Claude Sonnet, and Claude Fable models through the same harness on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, each at its shipped defaults and priced at list rates, and ran the Opus line again on Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs):
248269 
249![Scatter chart: the current model in each family solves more tasks than its predecessor, usually at lower cost per solved task](https://platform.claude.com/docs/images/cost-intel-upgrade-ladder.png)
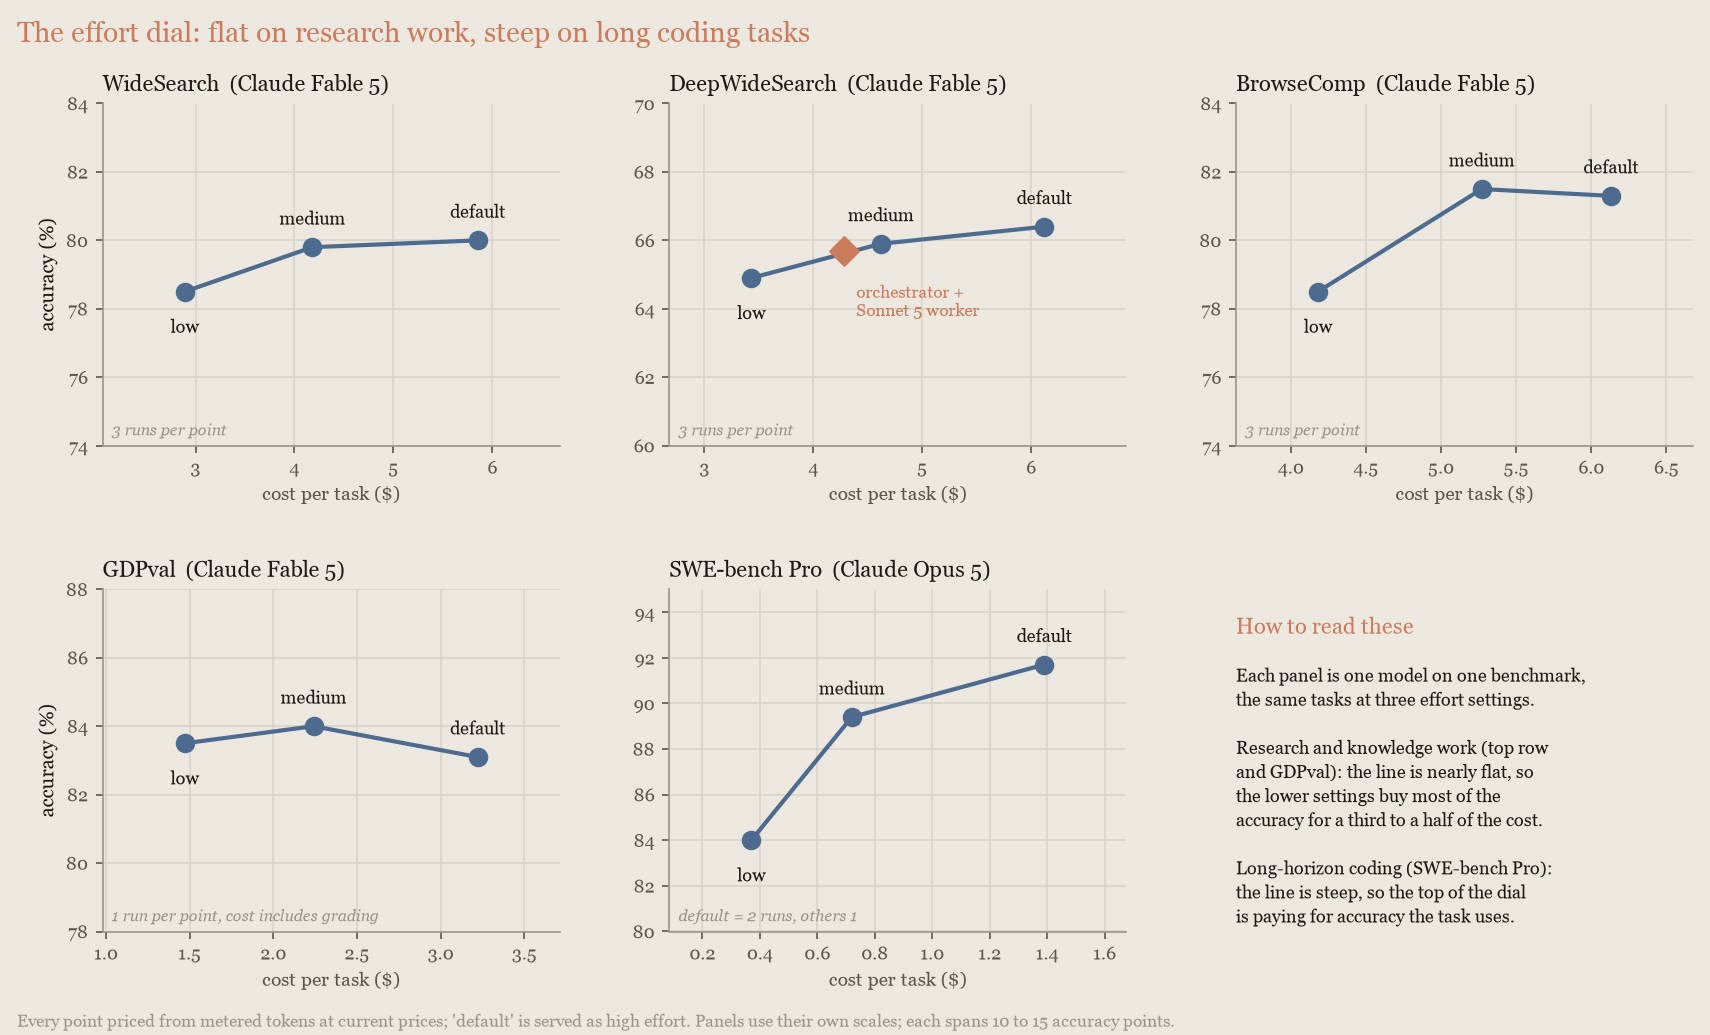
270![Two charts of cost per solved task against tasks solved: on SWE-bench Pro every model solves most tasks and the upgrade steps are small; on Terminal-Bench 3 the Opus ladder falls from $183 to $63 to $28 per solved task](https://platform.claude.com/docs/images/cost-intel-upgrade-ladder.png)
250271 
251Anthropic prices the Opus line identically per token across versions, so any saving comes from efficiency: Opus 4.8 takes fewer turns and rereads less than Opus 4.7, so each solved task costs 13% less, and Opus 5 then solves 11 more points of tasks at the same cost. Sonnet 5's savings come from its lower per-token price, which more than offsets the extra tokens it uses per task compared with Sonnet 4.6.
272Anthropic prices the Opus line identically per token across versions, so any difference comes from how much work each model does per task: priced as a customer is billed, Claude Opus 4.8 solves the same share of tasks as Claude Opus 4.7 for 14% less per solved task, and Claude Opus 5 then solves 12 more points of tasks at 21% more per solved task. Claude Opus 5 at `low` effort beats Opus 4.8's default on this benchmark for about 30% of its cost per solved task, so the cheapest upgrade is the new model at a lower setting. Sonnet 5's saving comes from its lower per-token price, which more than offsets the extra tokens it uses per task compared with Sonnet 4.6: 15% less per solved task for 5 more points. The frontier tier gained the same way: Claude Fable 5.1 matches Claude Fable 5's score for 43% less per solved task, most of it the lower cache-read price. That direction is not guaranteed: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same upgrade costs 41% more per task at `high` (79% more at `low`) for its 2 to 3 extra points on the tasks clean in every arm (reference 7), because the new model does more work per task there. The input and output prices are the same and the cache read is 4x cheaper, so measure the upgrade on your own workload before assuming it saves.
252273 
274On harder work the gap widens. On Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), where the tasks are hard enough that pass rate rather than tokens sets the bill, Claude Opus 4.7, Opus 4.8, and Opus 5 each spend $8 to $15 per task but solve 7%, 15%, and 41% of tasks, so cost per solved task falls from $183 to $63 to $28 up the ladder. The 21% premium Claude Opus 5 carries over Opus 4.8 on the saturated coding subset becomes a 56% saving on Terminal-Bench 3, where the older model mostly fails: the more your workload defeats the old model, the more the upgrade saves per result.
275 
253276Compare on cost per solved task, not per token: the same text costs about 30% more tokens on Claude Opus 4.7 and later, so a per-token comparison makes the newer models look more expensive by construction.
254277 
255278### Tune effort
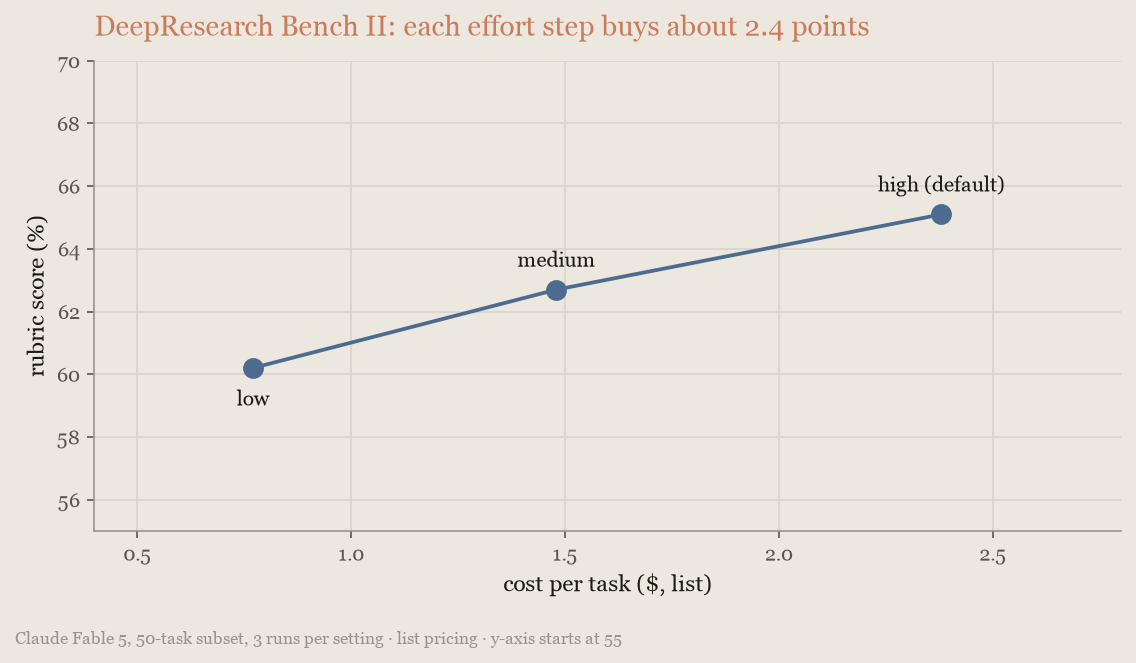
from line 279
256279 
257280Effort is the most direct way to tune a model to your task. The `effort` parameter governs how much thinking, tool calling, and self-verification the model does, and the default (`high`) suits demanding tasks. Cost scales with all that activity; accuracy scales only with the part your task needs. Below the model's ceiling, the highest effort levels pay for depth the task never uses.
258281 
259On the research and knowledge-work benchmarks (WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), DeepWideSearch[6](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and GDPval[2](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), all with Claude Fable 5), the curve of accuracy against cost is nearly flat: `low` gave up 1 to 3 points for a third to a half off the cost per task, `medium` matched the default's accuracy at 70% to 85% of its cost, and the default bought nothing measurable over `medium` on any of the four. On DeepWideSearch, `low` also matched an orchestrator with a Claude Sonnet 5 worker at 20% lower cost: lowering effort beat an architecture change.
282On the research and knowledge-work benchmarks (WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), DeepWideSearch[6](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and GDPval[2](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), all with Claude Fable 5), the curve of accuracy against cost is nearly flat: `low` gave up 1 to 3 points for a third to a half off the cost per task, `medium` matched the default's accuracy at about 70% to 87% of its cost, and the default bought nothing measurable over `medium` on any of the four. On DeepWideSearch, `low` also matched an orchestrator with a Claude Sonnet 5 worker at 29% lower cost: lowering effort beat an architecture change.
260283 
261Lower settings are also faster, which matters when latency is the constraint. In these runs, `low` took 4.5 minutes per problem on DeepWideSearch, compared with 7.9 minutes at the default. On the [corpus benchmark](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work), whose input does not fit in any single context window, Fable 5 took 7.9, 9.1, and 11.4 hours per episode at `low`, `medium`, and the default.
284Lower effort settings are often faster, which matters when latency is the constraint. In these runs, `low` took 4.5 minutes per problem on DeepWideSearch, compared with 7.9 minutes at the default. On the [corpus benchmark](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work), whose input does not fit in any single context window, Fable 5.1 took 15.2, 17.5, and 19.9 hours per episode at `low`, `medium`, and `high`.
262285 
263Long-horizon coding is the other shape. On SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Opus 5 gave up about 2 points at `medium` for half the cost and about 8 points at `low` for a quarter of it: a real tradeoff, which [re-running failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) turns back into a saving. This chart plots accuracy against cost for the research and knowledge-work benchmarks and for SWE-bench Pro:
286Long-horizon coding is where effort genuinely buys accuracy. On SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Opus 5 gave up about 2 points at `medium` for half the cost and about 8 points at `low` for a quarter of it: a real tradeoff, which [re-running failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) turns back into a saving. This chart plots accuracy against cost for the research and knowledge-work benchmarks and for SWE-bench Pro:
264287 
265288![Line charts of accuracy against cost by effort on five benchmarks: nearly flat on four research tasks, steep on SWE-bench Pro](https://platform.claude.com/docs/images/cost-intel-effort-sweep.png)
266289 
267290Two consequences follow. First, draw this curve for your own workload before you add a second model: in these internal measurements, a multi-model configuration that looked cheaper than the default single model cost more than that same model at lower effort. Second, this curve is the single-model baseline any multi-model strategy must beat, so [step 2 of measuring on your own workload](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#measure-on-your-own-workload) baselines across effort levels.
268291 
269Lower effort does cost accuracy on workloads that reach the model's ceiling, where accuracy genuinely scales with reasoning depth. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), where each report rewards deep reasoning per subtopic, every effort step bought about 2.4 points of rubric score; there is no free cost cut on that curve:
292Hard work does not automatically need high effort. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Fable 5.1 scored nearly the same at `low`, `medium`, and `high` while the cost per task rose from $4.66 to $7.12, so raising the effort in this case does not increase the quality of the output noticeably; on the 21 tasks clean in every arm (reference 7), Claude Fable 5 was flat across effort too, though the chart's 33-task basis, which drops each model's own cut-short attempts, shows it climbing. Measure the curve on the model you ship, not the one you measured last:
270293 
271![Line chart of rubric score against cost per task on DeepResearch Bench II: every effort step buys about 2.4 points](https://platform.claude.com/docs/images/cost-intel-effort-limit.png)
294![Line chart of rubric score against cost per task on DeepResearch Bench II: on Claude Fable 5.1 higher effort bought no score, only cost](https://platform.claude.com/docs/images/cost-intel-effort-limit.png)
272295 
273The task description alone does not reveal which kind of workload you have, so sweep two or three effort levels on a sample of your own traffic and read the answer off the curve. Test each level in a separate session: changing effort mid-session invalidates the cache (see [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context)) and distorts the comparison. For parameter details, see [Effort](https://platform.claude.com/docs/en/build-with-claude/effort).
296The task description alone does not reveal which kind of workload you have, so sweep two or three effort levels on a sample of your own traffic and read the answer off the curve. Test each level in a separate session: changing top-level effort mid-session invalidates the cache (see [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context)) and distorts the comparison. For parameter details, see [Effort](https://platform.claude.com/docs/en/build-with-claude/effort).
274297 
275298### Re-run failures at higher effort
276299 
277300When a task's outcome is checkable, the cheapest policy on the effort curve is not a fixed setting: run every task at a low setting and re-run only the failures at a higher one.
278301 
279Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5 at `low`, 16% of tasks failed; with those re-run at the default, about 93% passed for about $0.70 each, against 91.7% for $1.39 running everything at the default: the same pass rate for half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 94% for about $0.95. Most of the small lift is the second attempt (re-running the default's own failures at the default scores about the same, for more money), so use this policy for the saving, not the lift:
302Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5 at `low`, 16% of tasks failed; with those re-run at the default, about 93% passed for about $0.45 each, against 91.7% for $0.93 running everything at the default: the same pass rate for half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 94% for about $0.61. Most of the small lift is the second attempt (re-running the default's own failures at the default scores about the same, for more money), so use this policy for the saving, not the lift:
280303 
281304![Chart, SWE-bench Pro: running low or medium and re-running failures at the default beats every fixed effort setting on cost](https://platform.claude.com/docs/images/cost-intel-escalation.png)
282305 
from line 309
286309 
287310Most agentic task runs are cheap, but a minority spend many times the median cost on searching, re-verifying, and over-testing. A [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) targets that tail. The model sees a live token countdown for the whole task and self-regulates, trimming low-value searches, skipping redundant verification, and wrapping up instead of spiraling.
288311 
289Anthropic measured pass rate and cost per task on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) with Claude Fable 5 as the budget tightened:
312Anthropic measured pass rate and cost per task on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) with Claude Fable 5.1 as the budget tightened:
290313 
291![Line chart on SWE-bench Pro: pass@1 falls gently as task budgets tighten while cost per task drops by nearly half](https://platform.claude.com/docs/images/cost-intel-budget-pareto.png)
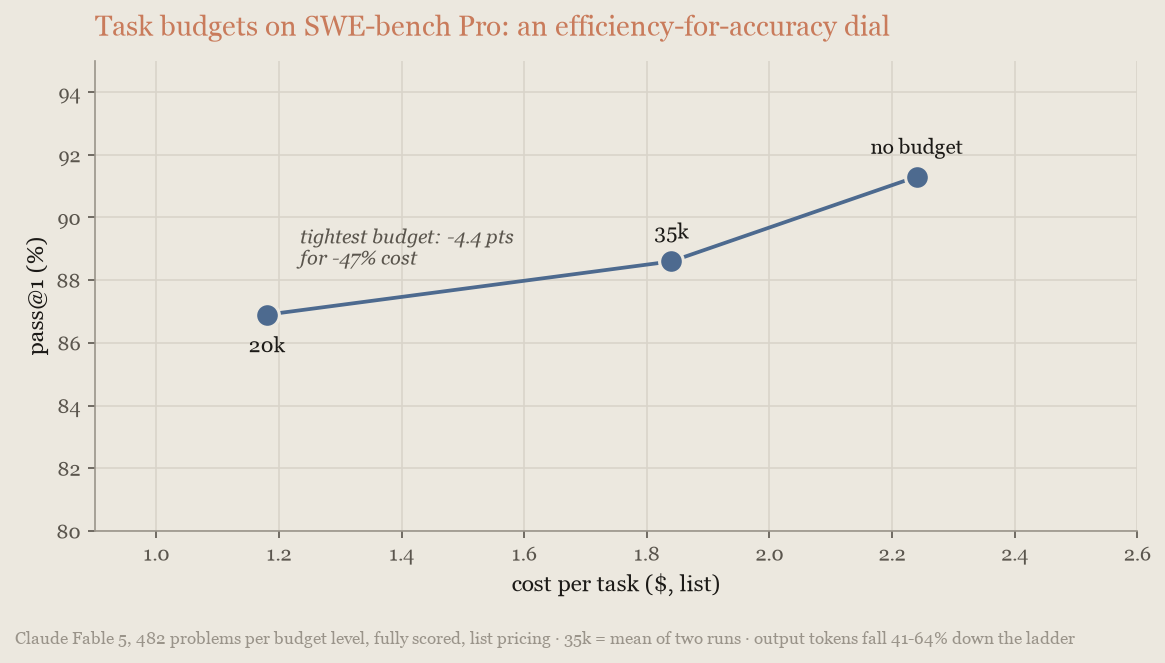
314![Line chart on SWE-bench Pro: pass@1 falls a few points as task budgets tighten while cost per task drops by 44% to 58%](https://platform.claude.com/docs/images/cost-intel-budget-pareto.png)
292315 
293A generous budget gave up about 2.7 points of pass rate for an 18% cost saving, and the tightest allowed budget gave up 4.4 points for a 47% saving. Budgets bought efficiency here, not accuracy.
316A generous budget cut cost per task 44% for about 3 points of pass rate, at the edge of run-to-run noise, and the tightest allowed budget cut it 58% for 6 points. Budgets bought efficiency here, at a price in pass rate that grows as the budget tightens.
294317 
295Three controls do three different jobs. A task budget saves money, because the model sees it. `max_tokens` is a safety cap that saves nothing. On Claude Managed Agents, a session budget is the hard dollar stop behind both. Set all three: a task budget, a high `max_tokens`, and a session cap for the run you never want on a bill, with a [workspace spend limit](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the final backstop.
318Three controls do three different jobs. A task budget saves money, because the model sees it. `max_tokens` is a safety cap: lowering it cut cost per attempt without lowering cost per solved task. On Claude Managed Agents, a session budget is the hard dollar stop behind both. Set all three: a task budget, a high `max_tokens`, and a session cap for the run you never want on a bill, with a [workspace spend limit](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the final backstop.
296319 
297* **Task budgets** are in beta (beta header `task-budgets-2026-03-13`) on Claude Opus 5, Claude Fable 5, Claude Opus 4.8, and Claude Opus 4.7, but not Claude Sonnet 5; check the [support table](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support) first. Start near your loop's 90th-percentile token usage, then tighten ([Choosing a budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets#choosing-a-budget) shows how to collect that distribution). Budgets below the current 20,000-token floor are rejected, and very tight budgets can produce refusal-like behavior. Set the budget once, on the first request, because a mid-task change [invalidates the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context). The budget is advisory, steering the model rather than stopping it, so verify adherence on your workload.
298* **`max_tokens`** caps a single response, invisibly to the model, so lowering it does not make the model economize. The turns that needed the room are discarded and still billed. On an internal repository-task benchmark[12](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a 16,384-token cap ended 15% of Claude Opus 5's attempts and a third of Claude Fable 5's, none of them solved. Capped runs spent less per attempt but bought proportionally fewer solves, so cost per solved task was the same as at 64,000. At that setting nothing was cut off, and Fable solved 54.6% of tasks instead of 36.6% on the problems both runs scored (on a separate cut of the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, described in reference 12, 92% instead of 90%). Retrying capped attempts only adds cost: at the same cap they never succeeded, and at a higher one you also pay for the wasted attempt. Set `max_tokens` to 64,000 for agentic work (128,000, the maximum, at `xhigh` or `max` effort), [stream responses](https://platform.claude.com/docs/en/build-with-claude/streaming) that large, treat [`stop_reason: max_tokens`](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#max-tokens) as a failure, and save money with effort and task budgets, which the model can see.
299* **Session budgets on Claude Managed Agents** are the hard stop. A [session budget](https://platform.claude.com/docs/en/managed-agents/budgets) is a dollar cap on one session at list rates for tokens, searches, and session time. At the cap, the session pauses with `stop_reason: budget_reached`; raising the budget resumes it. It is platform-enforced, works on any model with a list price (including Claude Sonnet 5), and combines with the advisory task budget. Deployments apply the same field to every run.
320* **Task budgets** are in beta (beta header `task-budgets-2026-03-13`) on the most recent models; check the [support table](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support) for which. Start near your loop's 90th-percentile token usage, then tighten ([Choosing a budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets#choosing-a-budget) shows how to collect that distribution). Budgets below the current 20,000-token floor are rejected, and very tight budgets can produce refusal-like behavior. Set the budget once, on the first request, because a mid-task change [invalidates the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context). The budget is advisory, steering the model rather than stopping it, so verify adherence on your workload.
321* **`max_tokens`** caps a single response, invisibly to the model, so lowering it does not make the model economize. The turns that needed the room are discarded and still billed. On an internal repository-task benchmark[12](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a 16,384-token cap ended 15% of Claude Opus 5's attempts and 43% of Claude Fable 5.1's at the default effort, and only 9 of the 117 capped Fable attempts still passed. Capped runs spent less per attempt but bought proportionally fewer solves, so cost per solved task was about the same as at 64,000 ($21 against $22). At 64,000, 2 of about 14,000 turns at the default effort were still cut off, and Fable 5.1 solved 58.5% of tasks instead of 36.3% (on a separate cut of the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, described in reference 12, no difference: 94 of 100 at either cap). Retrying capped attempts rarely helps: at the same cap most of them fail again, and at a higher one you also pay for the wasted attempt. Set `max_tokens` to 64,000 for agentic work, or to 128,000, the maximum, when a single cut-off attempt is costly; at 128,000 Fable 5.1 solved 60.0% for the same cost per solved task. [Stream responses](https://platform.claude.com/docs/en/build-with-claude/streaming) that large, treat [`stop_reason: max_tokens`](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#max-tokens) as a failure, and save money with effort and task budgets, which the model can see.
322* **Session budgets on Claude Managed Agents** are the hard stop. A [session budget](https://platform.claude.com/docs/en/managed-agents/budgets) is a dollar cap on one session at list rates for tokens, searches, and session time. At the cap, the session pauses with `stop_reason: budget_reached`; raising the budget resumes it. It is platform-enforced, works on any model with a list price, including models where task budgets are not yet available, and combines with the advisory task budget. Deployments apply the same field to every run.
300323 
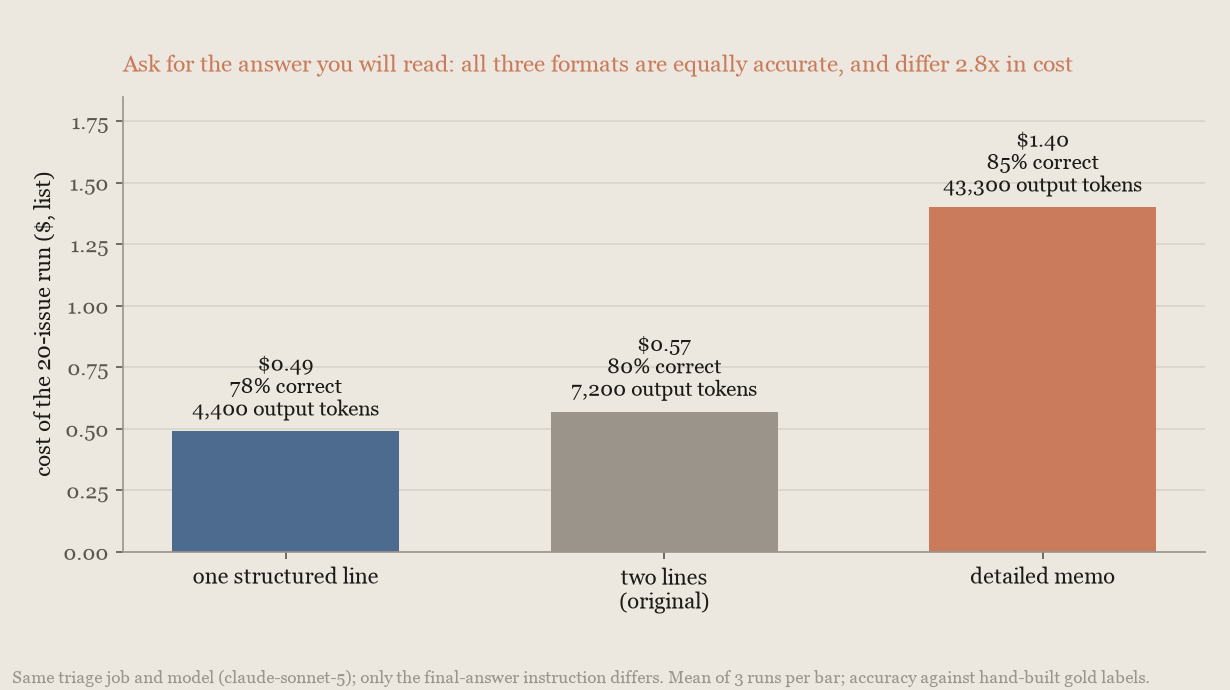
301324Ask for shorter answers. Output tokens cost five times input tokens on Claude Sonnet 5, and in an agent loop every token the model writes comes back as input on every later turn, so you pay for a long answer again and again. Anthropic ran the triage job under three final-answer instructions, three runs each, with the same model and tools. The original asked for two lines:
302325 
from line 350
327350 
328351![Bar chart: one-line format $0.49 per run, original two-line format $0.57, memo $1.40, all 78% to 85% correct](https://platform.claude.com/docs/images/cost-intel-output-format.png)
329352 
330The one-line answer used 39% fewer output tokens and cost $0.49 for the run against $0.57, with the same accuracy against the gold labels (78% compared with 80%, inside run-to-run noise). The memo used six times the output tokens of the original and cost $1.40, 2.8 times the one-line answer, for 85%, also inside the noise. The three formats are equally accurate; they differ in what you pay. Ask for the answer you will read, not the one that looks thorough.
353The one-line answer used 39% fewer output tokens than the two-line original and cost 14% less per run. The memo used six times the output tokens and cost 2.8 times the one-line answer. All three scored within run-to-run noise of each other against the gold labels, so the formats differ in what you pay far more than in what they get right. Ask for the answer you will read, not the one that looks thorough.
331354 
332The first of two `max_tokens` charts plots cost per attempt and per solved task at each cap:
355At the lower `max_tokens` cap both models spend less per attempt but solve proportionally fewer tasks, so cost per solved task barely moves:
333356 
334![Bar charts: at a 16k cap both models spend less per attempt but the same per solved task as at 64k, as they solve fewer tasks](https://platform.claude.com/docs/images/cost-intel-max-tokens-saving.png)
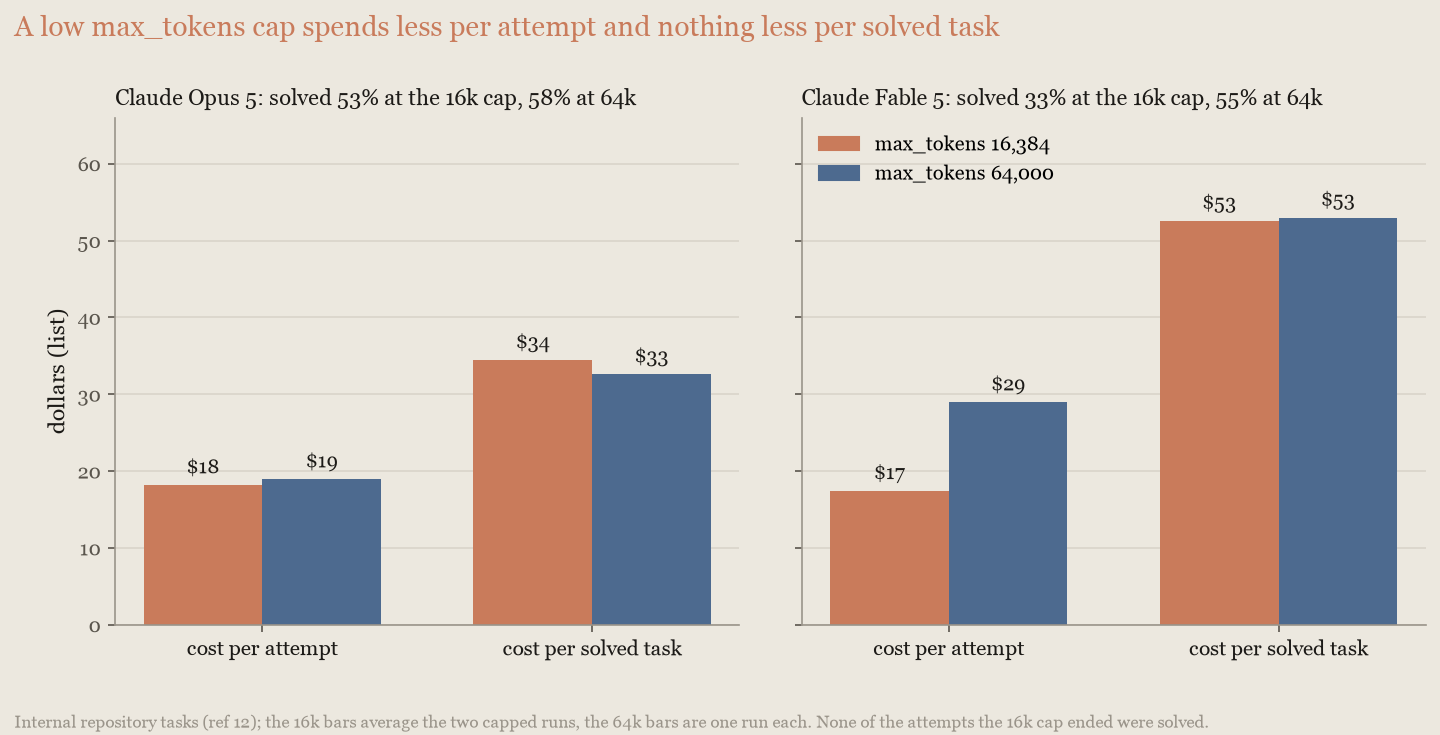
357![Bar charts: at a 16k cap both models spend less per attempt but about the same per solved task as at 64k, because they solve fewer tasks](https://platform.claude.com/docs/images/cost-intel-max-tokens-saving.png)
335358 
336The second plots per-turn output length against the caps:
359Almost every turn finishes far below either cap. The rare long turn is what the higher cap buys:
337360 
338![Dot plot of per-turn output for Opus 5 and Fable 5: medians a few hundred tokens, longest turns 33k and 59k, against the caps](https://platform.claude.com/docs/images/cost-intel-max-tokens-ladder.png)
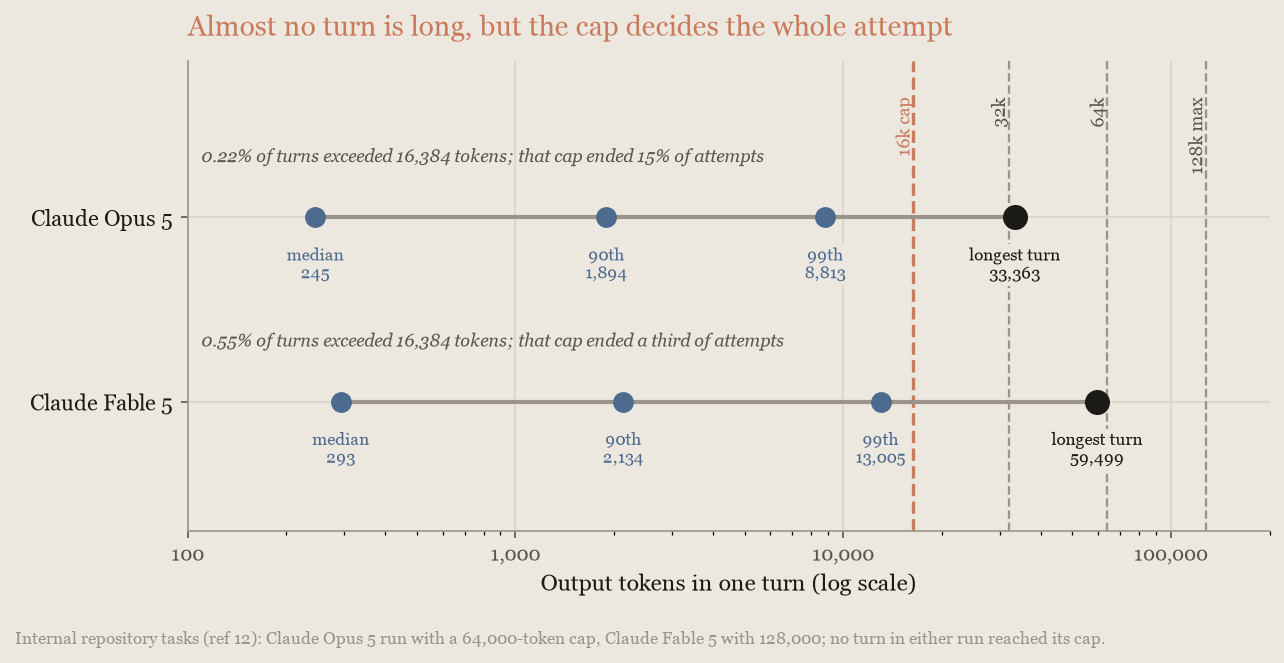
361![Dot plot of per-turn output for Opus 5 and Fable 5.1: medians a few hundred tokens, longest turns 33k and 128k, against the caps](https://platform.claude.com/docs/images/cost-intel-max-tokens-ladder.png)
339362 
340363## Combine models
341364 
from line 377
354377 
355378To use it, add the [advisor tool](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool) to your request. This beta feature runs the whole strategy server-side in one `/v1/messages` request: the executor emits a tool call, Anthropic runs the advisor inference, and the executor continues with the advice; you write no orchestration code. On Claude Managed Agents, [give the session an advisor](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration#give-the-session-an-advisor) by adding an `advisor` entry to the agent's `multiagent` roster; the session's primary thread consults it the same way. Claude Code supports it too; see [escalating hard decisions with the advisor tool](https://code.claude.com/docs/en/advisor).
356379 
357![Diagram of the advisor strategy: an executor model runs the main loop and calls a Claude Fable 5 advisor on demand](https://platform.claude.com/docs/images/model-routing-advisor-strategy.png)
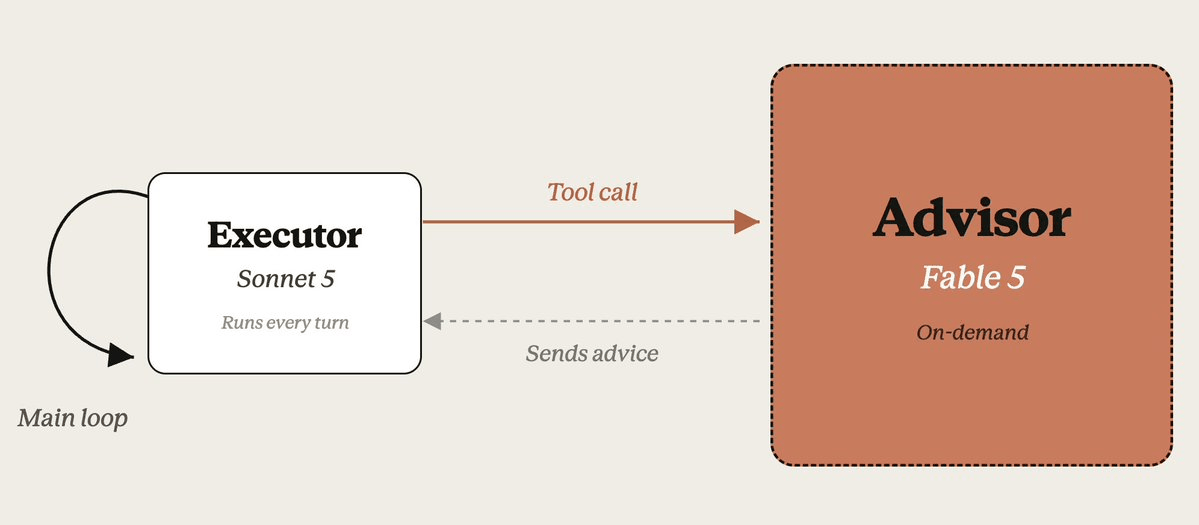
380![Diagram of the advisor strategy: an executor model runs the main loop and calls a Claude Fable 5.1 advisor on demand](https://platform.claude.com/docs/images/model-routing-advisor-strategy.png)
358381 
359382**What sets the payoff.** The advisor sees the task only through the executor's calls, so two things decide how much it helps.
360383 
361384The first is the gap between the models. The advisor can only hand over capability the executor lacks: on GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a Claude Haiku 4.5 executor gained a great deal from a Claude Opus 5 advisor, a Claude Sonnet 5 executor gained a few points, and a frontier executor almost nothing.
362385 
363The second, and the fragile one, is whether the executor actually asks (the consult rate). An executor at low effort can stop detecting that it is stuck: a pairing that consults on most tasks at the default effort can fall to consulting on almost none when effort is lowered, and then scores below the executor alone. The rate also varies by task: on DeepSWE[10](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a low-effort Sonnet 5 executor kept asking and gained 23 points; on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same executor stopped. When the executor does ask, it recovers most of the gap. Across the pairings in the following chart, the advisor closed 50% to 90% of the gap to the stronger model and you pay for the stronger model only on the consultations, which is what makes the cost cases possible:
386The second, and the fragile one, is whether the executor actually asks (the consult rate). An executor at low effort can stop detecting that it is stuck: a pairing that consults on most tasks at the default effort can fall to consulting on almost none when effort is lowered, and then scores below the executor alone. The rate also varies by task: on DeepSWE[10](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a low-effort Sonnet 5 executor kept asking and gained 23 points; on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same executor stopped. When the executor does ask, it recovers much of the gap. Across the pairings in the following chart whose executor kept asking, the advisor closed at least half the gap to the stronger model (the coding pairing beat the stronger model outright), and you pay for the stronger model only on the consultations, which is what makes the cost cases possible:
364387 
365![Bar chart of six advisor pairings: gap available versus gain realized, labeled with consult rates, which the gains track](https://platform.claude.com/docs/images/cost-intel-advisor-mechanism.png)
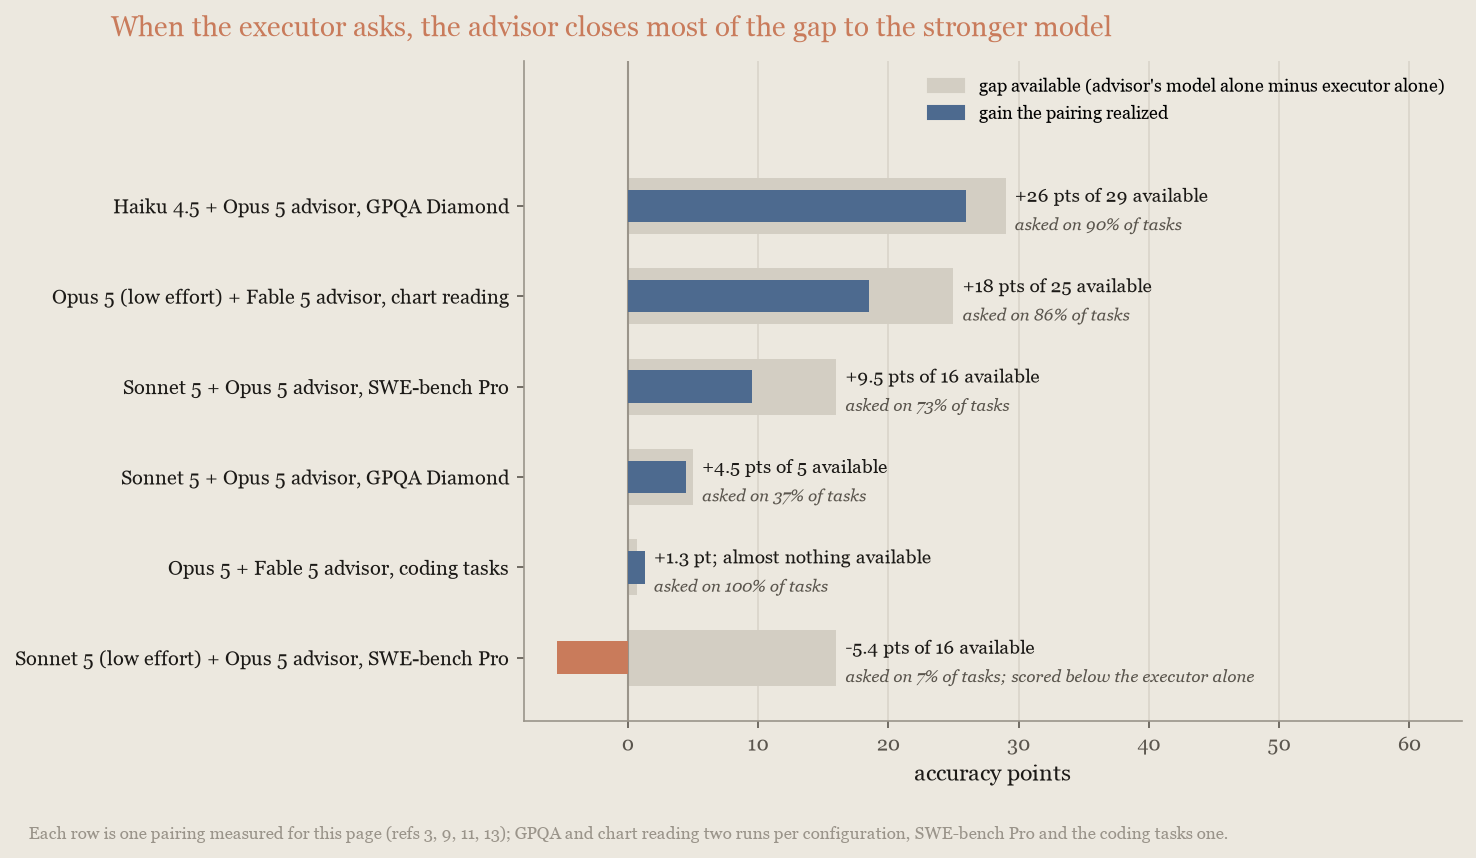
388![Bar chart of six advisor pairings, Claude Fable 5.1 as the advisor where it applies: gap available versus gain realized, labeled with consult rates, which the gains track](https://platform.claude.com/docs/images/cost-intel-advisor-mechanism.png)
366389 
367390The consult rate responds to prompting. With only the tool's built-in description, executors under-call, especially on coding work, so the [advisor tool documentation](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#prompting-for-coding-and-agent-tasks) gives a system prompt that asks for one call before substantive work and one before finishing, about two to three calls per task. The coding pairing measured next ran at that cadence, about two consultations on every task. That page also covers nudging an under-calling executor and capping calls client-side to bound cost. So watch the consult rate: prompt for it, measure it, and restore the executor's effort if it collapses.
368391 
369392**When it pays on cost.** An advisor saves money when a few short consultations, billed at the advisor's rate, replace running the advisor's model for the whole task. That works best when the advisor's model is priced well above the executor's, so the most cost-effective configuration is a frontier advisor over a mid-tier executor. A pairing can hold its own even at the top of the range, because advice also saves executor tokens: an executor told the right approach explores fewer dead ends, which can cover the consultations.
370393 
371On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5 executor with a Claude Fable 5 advisor was the most accurate configuration measured: 85.7% of attempts solved for $8.40 per attempt. It sits above the line through each model's own effort settings, but only a point or two over the best of them (Opus alone at the default setting, 84.4% for $8.50, and Fable alone at `medium`, 83.4% for $8.20), which a single run does not separate from noise. Fable alone at `medium` effort reaches about the same accuracy as the pairing (83.4% compared with 85.7%) for about the same money ($8.20 compared with $8.40 per attempt):
394On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5 executor with a Claude Fable 5.1 advisor was the most accurate configuration measured, at $7.69 per attempt. It sits above the line through each model's own effort settings: 3.5 points over Opus 5 alone at the default setting for slightly less money, a gap that five attempts per task do separate from noise, and about 2.5 points over the advisor's model alone for about half again the money:
372395 
373![Chart, coding benchmark: both models' effort curves, with the Opus 5 plus Fable 5 advisor pairing just above the top of both](https://platform.claude.com/docs/images/cost-intel-internal-coding-advisor.png)
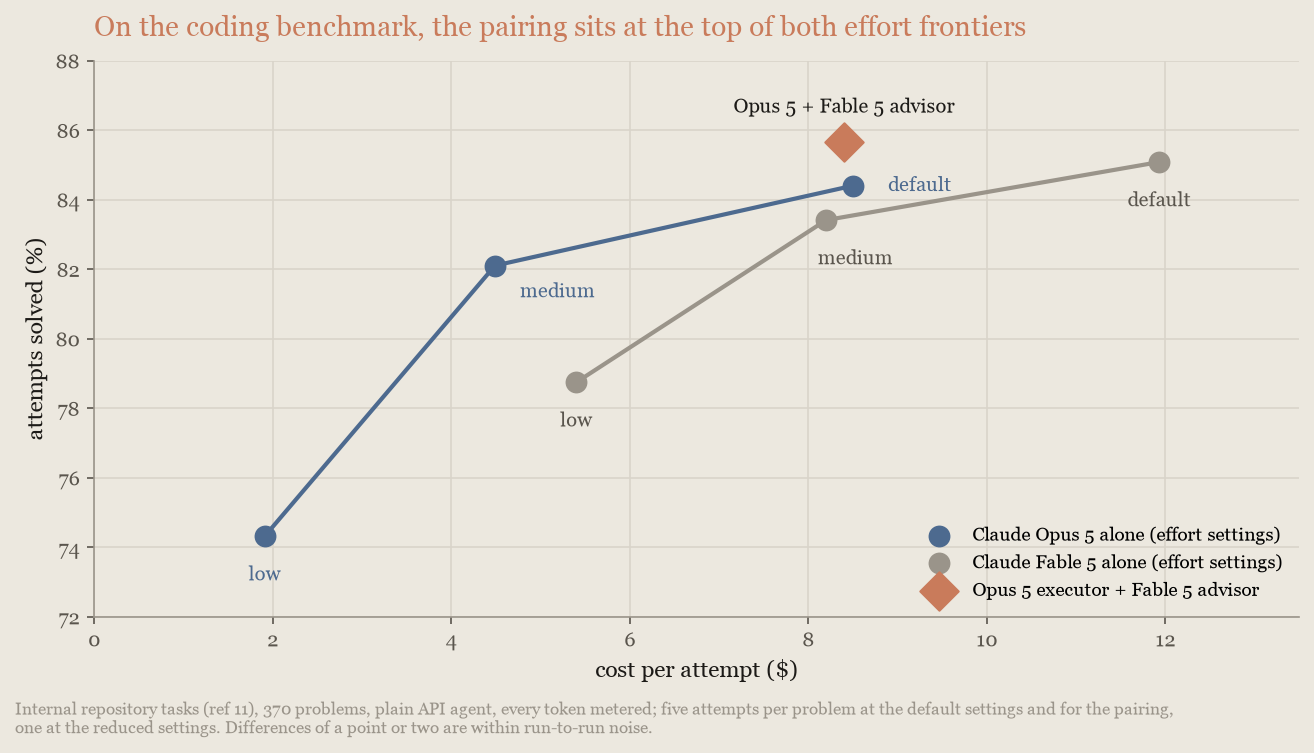
396![Chart, coding benchmark: both models' effort curves, with the Opus 5 plus Fable 5.1 advisor pairing 3.5 points over Opus 5 alone and about 2.5 over Fable 5.1 alone](https://platform.claude.com/docs/images/cost-intel-internal-coding-advisor.png)
374397 
375An earlier measurement through [Claude Code's advisor mode](https://code.claude.com/docs/en/advisor) produced the same ordering. Read this result as a shape to test on your workload, not a saving: at the top of the range the advisor buys a little accuracy at the frontier price, and the cost case belongs to pairings with a wider capability gap, such as the following chart-reading case. The latency cost is the consultations themselves: about two extra frontier-model calls per task on this benchmark, each on the task's critical path.
398An earlier measurement through [Claude Code's advisor mode](https://code.claude.com/docs/en/advisor) produced the same ordering. Read this result as a shape to test on your workload: the advisor buys a few points at about the executor's own price. A wider capability gap does not guarantee a better deal. The latency cost is the consultations themselves: about two extra frontier-model calls per task on this benchmark, each on the task's critical path.
376399 
377**When it pays instead of raising effort.** Where the capability gap is wider and a workload's accuracy responds to effort, a low-effort executor that consults an advisor can be a cheaper step up than raising the executor's own effort, because the advisor is paid for only on tasks that need it.
400**When the stronger model alone is the better step.** Where a workload's accuracy responds to effort, compare the pairing with the advisor's model alone at a reduced setting before building it: the advisor is paid for only on tasks that need it, but a consult that fires on most tasks costs more than running the stronger model itself. On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same pairing matched Claude Fable 5.1 alone at `medium` within run-to-run noise (65.0 against 67.5) at about 2.6 times the cost per task, because the advisor was consulted on nearly every task. Measure your own consult rate first: if the executor asks on most of its tasks, you are paying advisor rates across the whole workload, and running the advisor's model itself is the cheaper way to the same score.
378401 
379On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a public chart-reading benchmark run on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with its advisor, a Claude Opus 5 executor at `low` effort with a Claude Fable 5 advisor scored 67.5 for $0.60 per task. That is above the line through either model's own effort settings (Opus alone went from 49 to 75 between `low` and `medium` for $0.38 to $0.94), although the executor's own `medium` and default settings still hold the top scores, at 1.6 and 3.3 times the price:
380 
381![Line chart, Chartography: the low-effort Opus 5 executor with a Fable 5 advisor sits above both models' own effort curves](https://platform.claude.com/docs/images/cost-intel-chart-reading-advisor.png)
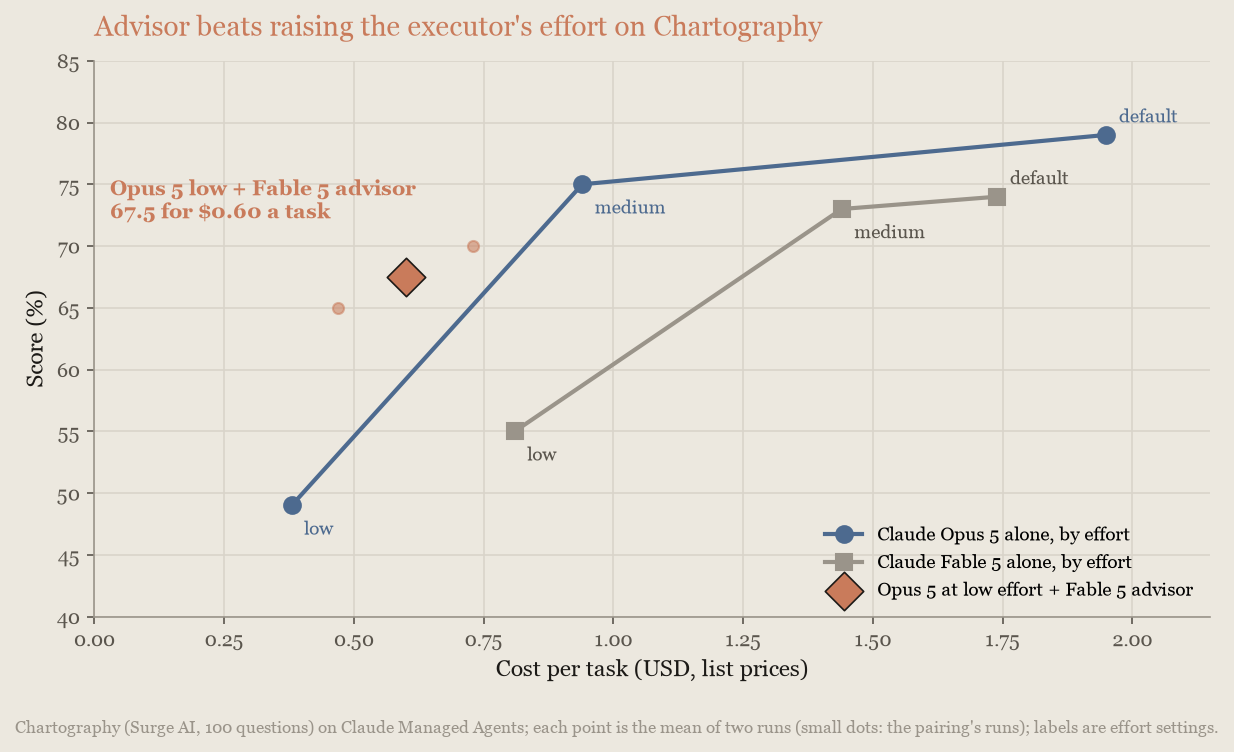
382 
383The low-effort executor consulted the advisor on 86% of tasks, the condition the SWE-bench Pro pairing failed to meet. Measure the consult rate in your agent loop before relying on this configuration.
384 
385402Whatever the pairing, first price the advisor's model alone at low effort; that is the baseline to beat. Recheck at every model release, because releases move both the capability gap and the price ratio.
386403 
387404**When it fits.** The advisor strategy suits workloads where turns are mostly mechanical but an excellent plan matters: coding agents, computer use, and multistep research pipelines. It fits poorly when every turn genuinely needs frontier capability, when there is nothing to plan (single-turn Q\&A), or when your executor is already close to the advisor's capability.
from line 407
390407 
391408In the orchestrator strategy, the frontier model holds the loop. It decomposes the task, dispatches subtasks to lower-cost worker models, and merges their results. The orchestrator's own transcript stays short because workers absorb the token-heavy exploration, so most tokens are billed at worker rates while the plan and synthesis still come from the frontier model.
392409 
393To build one, use [multiagent orchestration](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration) in Claude Managed Agents: configure a coordinator agent (the orchestrator) and a roster of worker agents, each with its own model. For a complete working example with a Claude Fable 5 coordinator and Claude Sonnet 5 workers, see the Claude Cookbook recipe [Coordinator pattern: big models for planning, small models for execution](https://github.com/anthropics/claude-cookbooks/blob/main/managed_agents/CMA_plan_big_execute_small.ipynb).
410To build one, use [multiagent orchestration](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration) in Claude Managed Agents: configure a coordinator agent (the orchestrator) and a roster of worker agents, each with its own model. For a complete working example with a frontier coordinator and Claude Sonnet 5 workers, see the Claude Cookbook recipe [Coordinator pattern: big models for planning, small models for execution](https://github.com/anthropics/claude-cookbooks/blob/main/managed_agents/CMA_plan_big_execute_small.ipynb).
394411 
395![Diagram of the orchestrator strategy: a Claude Fable 5 orchestrator fans subtasks out to three Claude Sonnet 5 workers](https://platform.claude.com/docs/images/model-routing-orchestrator-strategy.png)
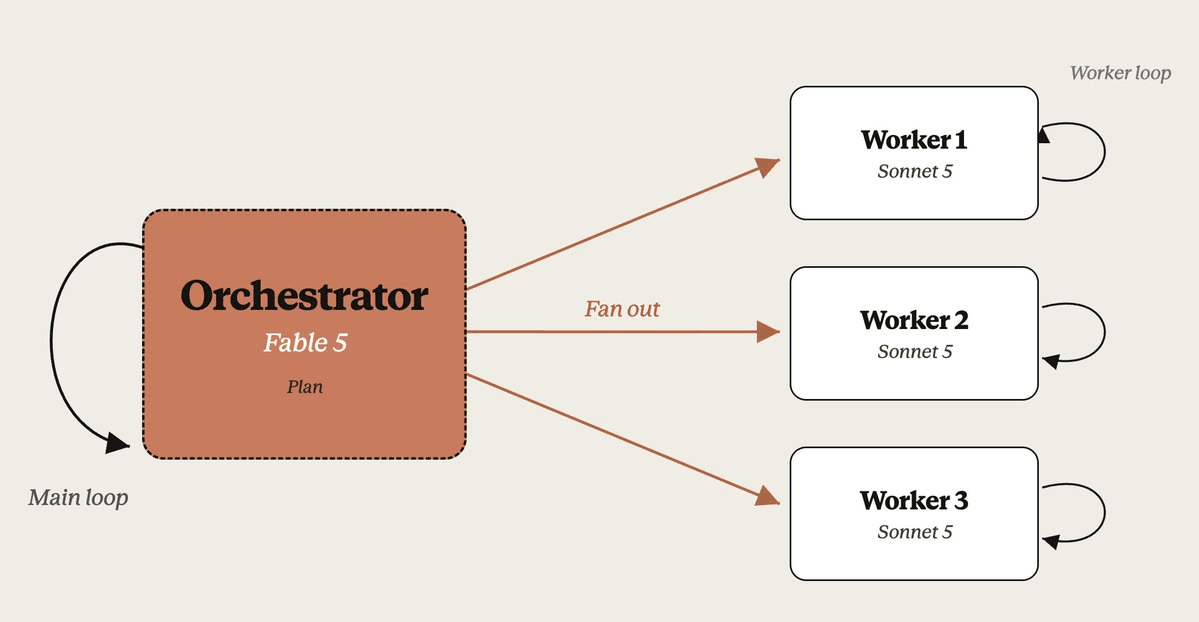
412![Diagram of the orchestrator strategy: a Claude Fable 5.1 orchestrator fans subtasks out to three Claude Sonnet 5 workers](https://platform.claude.com/docs/images/model-routing-orchestrator-strategy.png)
396413 
397This pattern saves wall-clock time when workers can run in parallel: on the corpus benchmark[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), an episode took a little over 2 hours with the coordinator running the platform's documented limit of 25 concurrent workers, compared with 11.4 hours solo. It saved money in only two measured situations. On work a single model could handle alone, the same model at lower effort was cheaper every time.
414This pattern saves wall-clock time when workers can run in parallel: on the corpus benchmark[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), an episode took about 2.3 hours with the coordinator running the platform's documented limit of 25 concurrent workers, compared with 15 to 20 hours solo. It saved money in only two measured situations. On work a single model could handle alone, the same model at lower effort was cheaper every time.
398415 
399416**Case 1: insurance against the cost tail on routine work.** A frontier model running alone occasionally spirals on a routine problem it would normally solve. Because you cannot tell in advance which those will be, a few such runs dominate the bill. A coordinator that hands routine work to a lower-cost worker caps that tail, because any spiraling now happens at worker rates.
400417 
401Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost a little under half as much as Fable alone on average and about a third as much at the 90th percentile ($12 compared with $33), and the solo model's single most expensive run, at $84, was also wrong:
418Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost about half as much as Claude Fable 5 alone on average and about a third as much at the 90th percentile ($12 compared with $33), and the solo model's single most expensive run, at $84, was also wrong:
402419 
403![Dot plot, BrowseComp routine slice: delegated runs cost about half of Fable alone on average, a third at the 90th percentile](https://platform.claude.com/docs/images/cost-intel-tail-insurance.png)
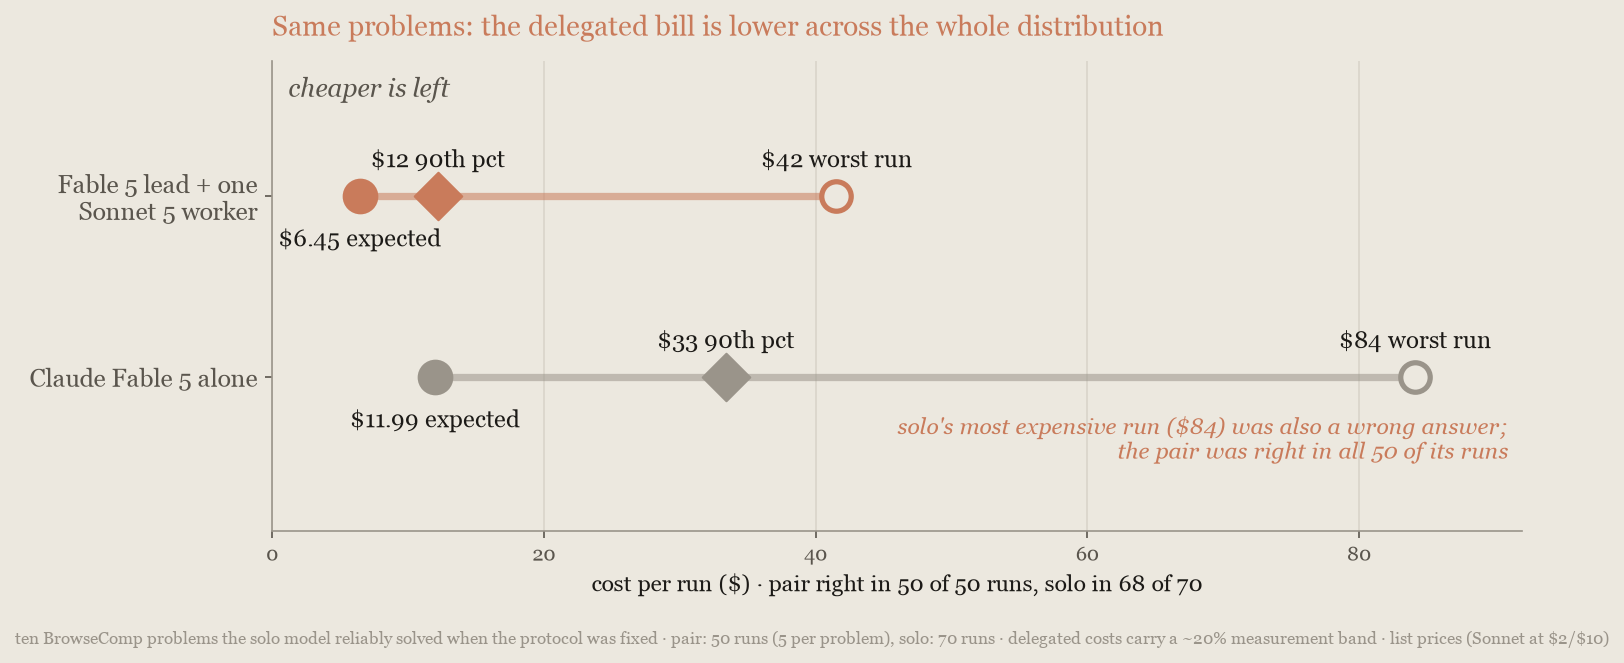
420![Dot plot, BrowseComp routine slice: delegated runs cost about half of Claude Fable 5 alone on average, a third at the 90th percentile](https://platform.claude.com/docs/images/cost-intel-tail-insurance.png)
404421 
405422Delegation paid on the routine, normally solvable share of the work, the opposite of the intuition that workers are for hard problems. On the full, harder BrowseComp set, the economics reversed. If your traffic has a long cost tail on routine tasks, this is the orchestrator case to measure first.
406423 
407424**Case 2: work larger than one context window.** A solo model must work through an input that large serially, one context window at a time, paying to re-read its own state on every pass. Workers each read their own partition, in parallel and at worker rates. Reading-heavy work that still fits in one context window is a model-choice problem, not a delegation problem: on reading cost alone, the orchestrator comes out ahead only when no single context can hold the work.
408425 
409Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5 solo cost $720 to $764 per episode at every effort setting, and only its accuracy moved. The coordinator configuration cost more than 60% less than any of those settings and scored 2 to 6 points below Fable at `medium` or the default, while beating a Claude Sonnet 5 solo baseline outright:
426Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5.1 solo cost $468 to $552 per episode across the three effort settings, and only its accuracy moved. The coordinator configuration, a Claude Fable 5.1 lead over 25 Claude Sonnet 5 workers, cost about half as much as those settings (47% to 55% less) and scored 10 to 12 points below them, in about 2.3 hours per episode against 15 to 20, while beating a Claude Sonnet 5 solo baseline outright:
410427 
411![Chart, corpus benchmark: the coordinator costs over 60% less than Fable solo at every effort setting, 2 to 6 points below its best](https://platform.claude.com/docs/images/cost-intel-corpus-pareto.png)
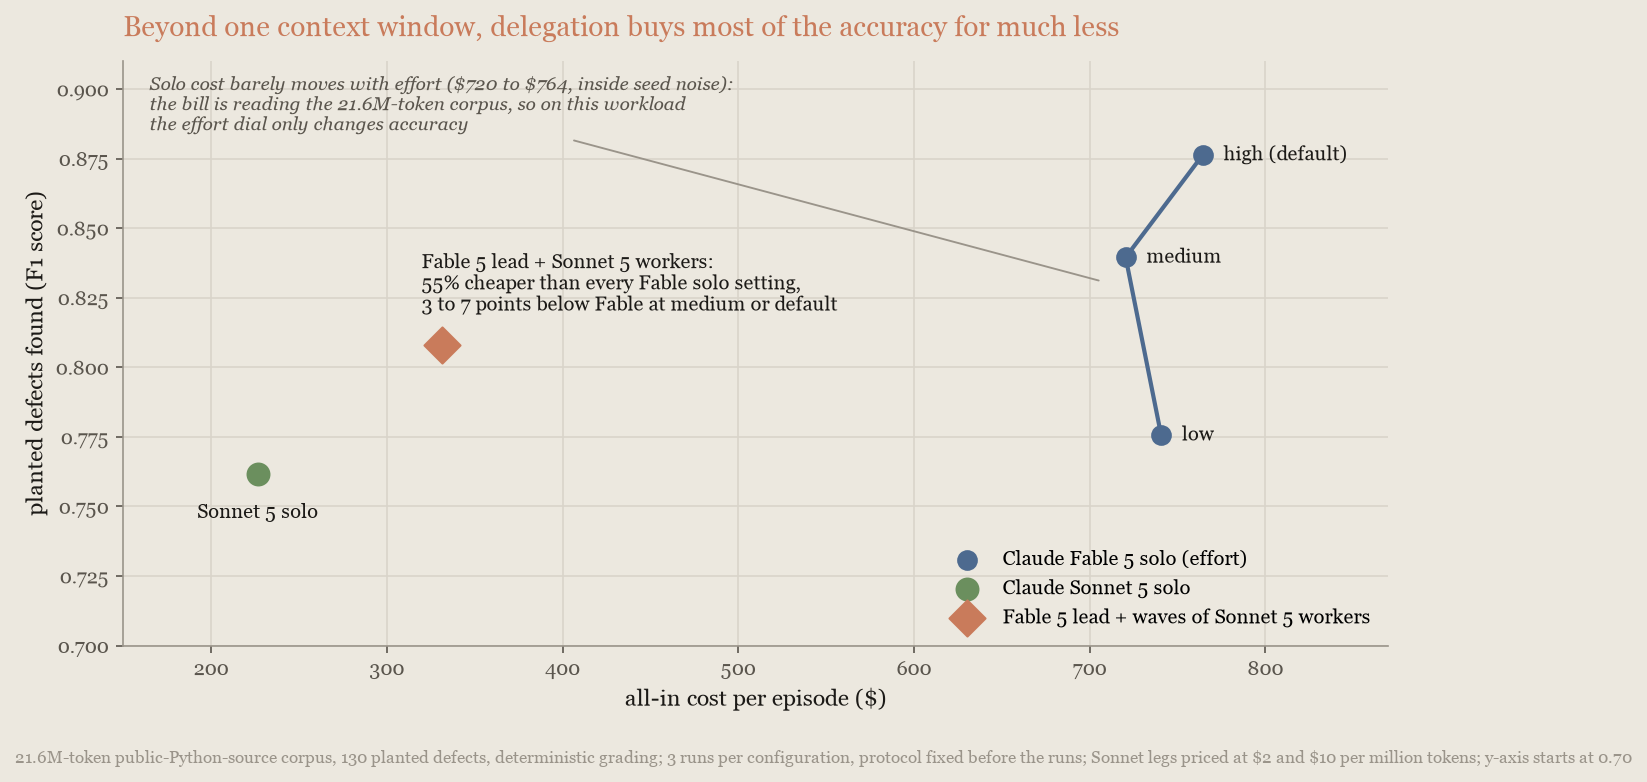
428![Chart, corpus benchmark: the coordinator costs about half as much as Fable 5.1 solo at any effort, about 12 points below its best](https://platform.claude.com/docs/images/cost-intel-corpus-pareto.png)
412429 
413The token accounting shows why. Both bills are mostly corpus reading served from the cache: the coordinator configuration read about 570 million cached tokens per episode, nearly three times the solo model's roughly 200 million, and still cost less than half as much, because its reads were billed at Claude Sonnet 5's cache-read rate rather than Claude Fable 5's. Fable 5 at default effort still holds peak accuracy, at 2.8 times the coordinator configuration's cost, so delegation here buys most of the accuracy, not all of it.
430The token accounting shows the scale of the reading: the coordinator configuration read about 560 million cached tokens per episode, about one and a half times the solo model's roughly 365 million, nearly all of them at Claude Sonnet 5's cache-read rate, and still cost about half as much overall. Fable 5.1 at `high` effort still holds peak accuracy, at about 2.2 times the coordinator configuration's cost, so delegation here buys most of the accuracy, not all of it.
414431 
415432**When delegation doesn't pay.** An orchestrator buys something only when there is bulk to hand off: many independent pieces, ideally too many for one context window. When the work is one dependent chain, or fits in a single context, the orchestrator pays for a plan, a handoff, and a merge that a single model gets for free. In every such case measured, the coordinator's model alone at lower effort came out ahead.
416433 
417BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) shows the boundary inside one benchmark. Delegation paid on the routine slice and lost on the full, harder set, where the frontier model alone reached the coordinator configuration's accuracy at 22% to 30% lower cost. Independent external work reports the same pattern[5](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). If the work is one chain, fits in one context without a long cost tail, or a single model at lower effort already meets your bar, don't build an orchestrator.
434The boundary is task difficulty, not the benchmark: on the full, harder BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) set, Claude Fable 5 alone reached the coordinator configuration's accuracy at 22% to 30% lower cost. Independent external work reports the same pattern[5](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). If the work is one chain, fits in one context without a long cost tail, or a single model at lower effort already meets your bar, don't build an orchestrator.
418435 
419436### Choose between the strategies
420437 
from line 448
431448 
432449## Measure on your own workload
433450 
434The numbers on this page reflect list prices at the time of measurement and drift as models and prices change. Your escalation rate, how cleanly tasks split, and transcript length move them too. The method stays the same:
451The numbers on this page reflect list prices at the time of measurement and will drift as models and prices change. Your escalation rate, how cleanly tasks split, and transcript length move them too. The method stays the same:
435452 
4361. Pull a few tasks from production logs, weighted like real traffic, and [write outcome checks](https://platform.claude.com/docs/en/test-and-evaluate/develop-tests) for each: tests pass, ticket closed, row count correct. Record cost per task beside the score: price the five priced token counts in each response's `usage` at their own rates, summed across the task's requests (the [Usage and Cost API](https://platform.claude.com/docs/en/manage-claude/usage-cost-api) reports the aggregate). The 1-hour cache write bills at 2x the input price, and the 5-minute write at 1.25x.
4531. Pull a few tasks from production logs, weighted like real traffic, and [write outcome checks](https://platform.claude.com/docs/en/test-and-evaluate/develop-tests) for each: tests pass, ticket closed, row count correct. Record cost per task beside the score: price the five priced token counts in each response's `usage` at their own rates (uncached input, 5-minute and 1-hour cache writes at 1.25x and 2x the input price, cache reads, and output), summed across the task's requests (the [Usage and Cost API](https://platform.claude.com/docs/en/manage-claude/usage-cost-api) reports the aggregate).
4374542. Baseline the model tiers across effort levels, not only the default, and plot score against spend. A multi-model configuration must beat the single model's whole curve.
4384553. If the curve shows a gap effort can't close, add the multi-model strategy that fits and re-run the suite.
4394564. Run the winner in shadow on a traffic slice before cutover, then keep the suite running.
from line 459
442459 
443460<CodeGroup>
444461 ```bash cURL
445 # Per-million-token prices from the pricing page; change these two for another model.
462 # Per-million-token prices from the pricing page; change these three for another model.
446463 INPUT_PER_MTOK=5.00 # Claude Opus 5
464 CACHE_READ_PER_MTOK=0.50 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
447465 OUTPUT_PER_MTOK=25.00
448466 
449467 response=$(curl --fail-with-body -sS https://api.anthropic.com/v1/messages \
from line 474
456474 "messages": [{"role": "user", "content": "Hello, Claude"}]
457475 }')
458476 
459 cost=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
477 cost=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson read_price "$CACHE_READ_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
460478 .usage
461479 | (.input_tokens * $in_price
462480 + (.cache_creation.ephemeral_1h_input_tokens // 0) * $in_price * 2.00 # 1-hour cache write
463481 + (.cache_creation.ephemeral_5m_input_tokens // 0) * $in_price * 1.25 # 5-minute cache write
464 + (.cache_read_input_tokens // 0) * $in_price * 0.10 # cache read
482 + (.cache_read_input_tokens // 0) * $read_price # cache read
465483 + .output_tokens * $out_price) / 1e6
466484 ' <<<"$response")
467485 printf 'Request cost: $%.6f\n' "$cost"
from line 486
468486 ```
469487 
470488 ```bash CLI
471 # Per-million-token prices from the pricing page; change these two for another model.
489 # Per-million-token prices from the pricing page; change these three for another model.
472490 INPUT_PER_MTOK=5.00 # Claude Opus 5
491 CACHE_READ_PER_MTOK=0.50 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
473492 OUTPUT_PER_MTOK=25.00
474493 
475494 USAGE=$(ant messages create \
from line 497
478497 --message '{role: user, content: "Hello, Claude"}' \
479498 --transform usage)
480499 
481 COST=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
500 COST=$(jq -r --argjson in_price "$INPUT_PER_MTOK" --argjson read_price "$CACHE_READ_PER_MTOK" --argjson out_price "$OUTPUT_PER_MTOK" '
482501 (.input_tokens * $in_price
483502 + (.cache_creation.ephemeral_1h_input_tokens // 0) * $in_price * 2.00 # 1-hour cache write
484503 + (.cache_creation.ephemeral_5m_input_tokens // 0) * $in_price * 1.25 # 5-minute cache write
485 + (.cache_read_input_tokens // 0) * $in_price * 0.10 # cache read
504 + (.cache_read_input_tokens // 0) * $read_price # cache read
486505 + .output_tokens * $out_price) / 1e6
487506 ' <<<"$USAGE")
488507 printf 'Request cost: $%.6f\n' "$COST"
from line 508
489508 ```
490509 
491510 ```python Python
492 # Per-million-token prices from the pricing page; change these two for another model.
511 # Per-million-token prices from the pricing page; change these three for another model.
493512 INPUT_PER_MTOK = 5.00 # Claude Opus 5
513 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
514 CACHE_READ_PER_MTOK = 0.50
494515 OUTPUT_PER_MTOK = 25.00
495516 
496517 client = anthropic.Anthropic()
from line 526
505526 writes_5m = cache_writes.ephemeral_5m_input_tokens if cache_writes else 0
506527 cost = (
507528 usage.input_tokens * INPUT_PER_MTOK
508 # 1-hour cache writes bill at 2x the input price, 5-minute at 1.25x; reads at 0.1x.
529 # 1-hour cache writes bill at 2x the input price, 5-minute at 1.25x; reads at the cache-read price.
509530 + writes_1h * INPUT_PER_MTOK * 2.0
510531 + writes_5m * INPUT_PER_MTOK * 1.25
511 + (usage.cache_read_input_tokens or 0) * INPUT_PER_MTOK * 0.10
532 + (usage.cache_read_input_tokens or 0) * CACHE_READ_PER_MTOK
512533 + usage.output_tokens * OUTPUT_PER_MTOK
513534 ) / 1_000_000
514535 print(f"Request cost: ${cost:.6f}")
from line 536
515536 ```
516537 
517538 ```typescript TypeScript
518 // Per-million-token prices from the pricing page; change these two for another model.
539 // Per-million-token prices from the pricing page; change these three for another model.
519540 const INPUT_PER_MTOK = 5.0; // Claude Opus 5
541 const CACHE_READ_PER_MTOK = 0.5; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
520542 const OUTPUT_PER_MTOK = 25.0;
521543 
522544 const client = new Anthropic();
from line 552
530552 (usage.input_tokens * INPUT_PER_MTOK +
531553 (usage.cache_creation?.ephemeral_1h_input_tokens ?? 0) * INPUT_PER_MTOK * 2 + // 1-hour cache write
532554 (usage.cache_creation?.ephemeral_5m_input_tokens ?? 0) * INPUT_PER_MTOK * 1.25 + // 5-minute cache write
533 (usage.cache_read_input_tokens ?? 0) * INPUT_PER_MTOK * 0.1 + // cache read
555 (usage.cache_read_input_tokens ?? 0) * CACHE_READ_PER_MTOK + // cache read
534556 usage.output_tokens * OUTPUT_PER_MTOK) /
535557 1_000_000;
536558 console.log(`Request cost: $${cost.toFixed(6)}`);
from line 559
537559 ```
538560 
539561 ```csharp C#
540 // Per-million-token prices from the pricing page; change these two for another model.
562 // Per-million-token prices from the pricing page; change these three for another model.
541563 const double InputPerMtok = 5.00; // Claude Opus 5
564 const double CacheReadPerMtok = 0.50; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
542565 const double OutputPerMtok = 25.00;
543566 
544567 AnthropicClient client = new();
from line 579
556579 usage.InputTokens * InputPerMtok
557580 + (usage.CacheCreation?.Ephemeral1hInputTokens ?? 0) * InputPerMtok * 2.00 // 1-hour cache write
558581 + (usage.CacheCreation?.Ephemeral5mInputTokens ?? 0) * InputPerMtok * 1.25 // 5-minute cache write
559 + (usage.CacheReadInputTokens ?? 0) * InputPerMtok * 0.10 // cache read
582 + (usage.CacheReadInputTokens ?? 0) * CacheReadPerMtok // cache read
560583 + usage.OutputTokens * OutputPerMtok
561584 ) / 1_000_000;
562585 Console.WriteLine($"Request cost: ${cost:F6}");
from line 586
563586 ```
564587 
565588 ```go Go
566 // Per-million-token prices from the pricing page; change these two for another model.
589 // Per-million-token prices from the pricing page; change these three for another model.
567590 const (
568 inputPerMTok = 5.00 // Claude Opus 5
569 outputPerMTok = 25.00
591 inputPerMTok = 5.00 // Claude Opus 5
592 cacheReadPerMTok = 0.50 // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
593 outputPerMTok = 25.00
570594 )
571595 
572596 // ...
from line 611
587611 cost := (float64(usage.InputTokens)*inputPerMTok +
588612 float64(usage.CacheCreation.Ephemeral1hInputTokens)*inputPerMTok*2.00 + // 1-hour cache write
589613 float64(usage.CacheCreation.Ephemeral5mInputTokens)*inputPerMTok*1.25 + // 5-minute cache write
590 float64(usage.CacheReadInputTokens)*inputPerMTok*0.10 + // cache read
614 float64(usage.CacheReadInputTokens)*cacheReadPerMTok + // cache read
591615 float64(usage.OutputTokens)*outputPerMTok) / 1_000_000
592616 fmt.Printf("Request cost: $%.6f\n", cost)
593617 ```
594618 
595619 ```java Java
596 // Per-million-token prices from the pricing page; change these two for another model.
620 // Per-million-token prices from the pricing page; change these three for another model.
597621 static final double INPUT_PER_MTOK = 5.00; // Claude Opus 5
622 static final double CACHE_READ_PER_MTOK = 0.50; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
598623 static final double OUTPUT_PER_MTOK = 25.00;
599624 
600625 void main() {
from line 637
612637 double cost = (usage.inputTokens() * INPUT_PER_MTOK
613638 + writes1h * INPUT_PER_MTOK * 2.00 // 1-hour cache write
614639 + writes5m * INPUT_PER_MTOK * 1.25 // 5-minute cache write
615 + usage.cacheReadInputTokens().orElse(0L) * INPUT_PER_MTOK * 0.10 // cache read
640 + usage.cacheReadInputTokens().orElse(0L) * CACHE_READ_PER_MTOK // cache read
616641 + usage.outputTokens() * OUTPUT_PER_MTOK) / 1_000_000;
617642 IO.println("Request cost: $%.6f".formatted(cost));
618643 }
from line 644
619644 ```
620645 
621646 ```php PHP
622 // Per-million-token prices from the pricing page; change these two for another model.
647 // Per-million-token prices from the pricing page; change these three for another model.
623648 const INPUT_PER_MTOK = 5.00; // Claude Opus 5
649 const CACHE_READ_PER_MTOK = 0.50; // 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
624650 const OUTPUT_PER_MTOK = 25.00;
625651 
626652 $client = new Client();
from line 660
634660 $usage->inputTokens * INPUT_PER_MTOK
635661 + ($usage->cacheCreation?->ephemeral1hInputTokens ?? 0) * INPUT_PER_MTOK * 2.00 // 1-hour cache write
636662 + ($usage->cacheCreation?->ephemeral5mInputTokens ?? 0) * INPUT_PER_MTOK * 1.25 // 5-minute cache write
637 + ($usage->cacheReadInputTokens ?? 0) * INPUT_PER_MTOK * 0.10 // cache read
663 + ($usage->cacheReadInputTokens ?? 0) * CACHE_READ_PER_MTOK // cache read
638664 + $usage->outputTokens * OUTPUT_PER_MTOK
639665 ) / 1_000_000;
640666 printf("Request cost: \$%.6f\n", $cost);
from line 667
641667 ```
642668 
643669 ```ruby Ruby
644 # Per-million-token prices from the pricing page; change these two for another model.
670 # Per-million-token prices from the pricing page; change these three for another model.
645671 INPUT_PER_MTOK = 5.00 # Claude Opus 5
672 CACHE_READ_PER_MTOK = 0.50 # 0.1x the input price; 0.025x on Claude Fable 5.1 and Claude Mythos 5.1
646673 OUTPUT_PER_MTOK = 25.00
647674 
648675 client = Anthropic::Client.new
from line 683
656683 usage.input_tokens * INPUT_PER_MTOK +
657684 usage.cache_creation&.ephemeral_1h_input_tokens.to_i * INPUT_PER_MTOK * 2.00 + # 1-hour cache write
658685 usage.cache_creation&.ephemeral_5m_input_tokens.to_i * INPUT_PER_MTOK * 1.25 + # 5-minute cache write
659 usage.cache_read_input_tokens.to_i * INPUT_PER_MTOK * 0.10 + # cache read
686 usage.cache_read_input_tokens.to_i * CACHE_READ_PER_MTOK + # cache read
660687 usage.output_tokens * OUTPUT_PER_MTOK
661688 ) / 1_000_000
662689 puts format("Request cost: $%.6f", cost)
from line 694
667694 
668695The following table lists the levers in the order to try them:
669696 
670| Lever | Saving in these runs | Quality cost | Latency | Where |
671| ------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------ | ------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
672| Prompt caching | Cost cut by a factor of 2.5 to 3.7 on agent loops; 83% on the triage run | None | Faster | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) |
673| 1-hour cache duration | Cheaper than the 5-minute default once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour; with no pauses the default cost 15% less on Claude Sonnet 5 and 11% less on Claude Opus 5 | None | Stays warm after a pause | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
674| Input trimming | A further 5 percentage points on the triage run | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
675| Prune stale tool results at task boundaries | 39% on the long triage run (compaction 32%); nothing on short loops | None measured | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
676| Tool search | 45% with 500 tool definitions attached; 20% with a GitHub MCP server | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
677| Data files through code execution | 92% on a 25-question data task | A gain, 25 of 25 instead of 6 of 25 | Faster | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
678| Batch API | 50% | None | Results within 24 hours | [Batch work that can wait](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#batch-work-that-can-wait) |
679| Prompt audit against the current model | 14% on both migrations measured | None; a gain on one | Faster (fewer tool rounds) | [Audit prompts against the current model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#audit-prompts-against-the-current-model) |
680| Upgrade the model | Opus 4.7 to Opus 5: about 12% less per solved task, 11 more points; Sonnet 4.6 to Sonnet 5: 14% less, 5 more points | A gain | Neutral | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
681| Lower effort | Knowledge work: `medium` 15% to 30%, `low` a third to a half; long coding: `medium` about half, `low` about three quarters | 1 to 3 points on knowledge work, 2 to 8 on long coding | Faster | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
682| Re-run failures | About half, at the same pass rate | None | Two runs on the tasks that fail | [Re-run failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
683| Task budget | 18% to 47% | 3 to 4 points | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
684| Ask for shorter answers | 39% of output tokens, 14% of cost on the triage run | None | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
685| Raising `max_tokens` | None per solved task, but more tasks solved | Gains of 2 to 18 points | Neutral | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
686| Advisor | Depends on the capability gap and the consult rate; the chart-reading pairing scored above both models' effort curves, the coding pairing only marginally | Small gains | About two extra calls per task | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
687| Orchestrator | More than 60% below the frontier model beyond one context window; about half on routine tails | 2 to 6 points below the frontier model | Much faster on large inputs | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
697| Lever | Saving in these runs | Quality cost | Latency | Where |
698| ------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------- | ------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
699| Prompt caching | Cost cut by a factor of 2.7 to 5.3 on agent loops; 83% on the triage run | None | Faster | [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context) |
700| 1-hour cache duration | Cheaper than the 5-minute default once about 1 turn in 20 follows a pause between 5 minutes and an hour and few gaps run over an hour, except on Claude Fable 5.1, where keeping the 5-minute cache warm is cheaper while pauses run minutes and the 1-hour duration wins when pauses run toward an hour; with no pauses the default cost 15% less on Claude Sonnet 5 and 11% less on Claude Opus 5 | None | Stays warm after a pause | [Pick the cache duration](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#pick-the-cache-duration) |
701| Input trimming | A further 5 percentage points on the triage run | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
702| Prune stale tool results at task boundaries | 39% on the long triage run (compaction 32%); nothing on short loops | None measured | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
703| Tool search | 45% with 500 tool definitions attached; 20% with a GitHub MCP server | None | Neutral | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
704| Data files through code execution | 92% on a 25-question data task | A gain, 25 of 25 instead of 6 of 25 | Faster | [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) |
705| Batch API | 50% | None | Results within 24 hours | [Batch work that can wait](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#batch-work-that-can-wait) |
706| Prompt audit against the current model | 14% on both migrations measured | None; a gain on one | Faster (fewer tool rounds) | [Audit prompts against the current model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#audit-prompts-against-the-current-model) |
707| Upgrade the model | Opus 4.8 to Opus 5: 12 more points at 21% more per solved task (Opus 5 at `low` beats Opus 4.8 for about 30% of the cost); Sonnet 4.6 to Sonnet 5: 15% less per solved task, 5 more points; Fable 5 to Fable 5.1: 43% less per solved task at about the same score | A gain | Neutral | [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) |
708| Lower effort | Knowledge work: `medium` 13% to 31%, `low` a third to a half; long coding: `medium` about half, `low` about three quarters | 1 to 3 points on knowledge work, 2 to 8 on long coding | Faster | [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort) |
709| Re-run failures | About half, at the same pass rate | None | Two runs on the tasks that fail | [Re-run failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
710| Task budget | 44% to 58% | 3 to 6 points | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
711| Ask for shorter answers | 39% of output tokens, 14% of cost on the triage run | None | Faster | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
712| Raising `max_tokens` | None per solved task, but more tasks solved | Gains of up to 22 points on the internal set; none on the public pair | Neutral | [Set budgets and output caps](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
713| Advisor | Depends on the capability gap and the consult rate; the coding pairing scored 3.5 points over Opus 5 alone and about 2.5 over Fable 5.1 alone, the chart-reading pairing matched the advisor's model alone at `medium` for about 2.6 times the price | Small gains | About two extra calls per task | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
714| Orchestrator | About half against the frontier model, both beyond one context window and on routine tails (the latter measured on Claude Fable 5) | 10 to 12 points below the frontier model | Much faster on large inputs | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
688715 
689716## Benchmarks referenced
690717 
691718Except where a reference says otherwise, measurements are Anthropic-internal runs of these benchmarks. Unless noted, costs are USD at the list prices in effect when each benchmark ran; Claude Sonnet 5 figures use $2 and $10 per million input and output tokens. Charts labeled "notional USD" price each request's token counts at those rates rather than reporting invoices.
692719 
6931. **WideSearch:** Wong et al., "WideSearch: Benchmarking Agentic Broad Info-Seeking," arXiv:2508.07999, 2025. Broad web-research tasks graded on a many-row table's completeness and accuracy; 200 problems, 3 runs per configuration, run August 1 to 2, 2026. The caching chart re-prices the effort chart's default-effort runs from their per-request billing records; per-problem costs differ slightly because the two charts use different cost accounting. The cost-concentration chart is a separate 20-problem run, 3 runs per problem, run August 3 to 4, 2026, costed from per-request billing records.
7201. **WideSearch:** Wong et al., "WideSearch: Benchmarking Agentic Broad Info-Seeking," arXiv:2508.07999, 2025. Broad web-research tasks graded on a many-row table's completeness and accuracy; 200 problems, 3 runs per configuration, run August 1 to 2, 2026. The cost-concentration chart is a separate 20-problem run, 3 runs per problem, run August 3 to 4, 2026, costed from per-request billing records.
6947212. **GDPval:** OpenAI, "GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks," 2025. Knowledge-work deliverables graded against task rubrics; a 210-task run of the released gold set, one attempt per task, run August 2, 2026. A Claude model grades, so absolute scores may differ from published results.
6953. **SWE-bench Pro:** Scale AI, "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", 2025. A 482-problem subset selected for compatibility with Anthropic's evaluation harness; scores are not comparable to the public leaderboard. Claude Opus 5 at the default effort averages two runs; reduced-effort settings are single runs; all ran August 4, 2026, as did the task-budget arms. Escalation figures come task by task from those runs: `low` first, then the default on its failures, solved 92.5% to 93.6% across run pairings for about $0.70; `medium` first, 93.8% to 94.2% for about $0.95; the default re-run on its own failures, 94.0% for $1.58; everything at the default, 90.9% to 92.5% for $1.39. The Claude Sonnet 5 executor pairings on the advisor chart come from the same measurement series on this subset: the Sonnet-plus-Opus pairing was run twice (August 7 and August 8, 2026, a run and an exact replication), the low-effort pairing once (August 8, 2026), and Claude Sonnet 5 alone twice (77.4%, the baseline for both Pro rows); the task-budget figures are one run per budget on the same subset. The Claude Fable 5 figure in [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) is a single run from July 2, 2026, also the task-budget chart's unbudgeted baseline; every budgeted run completed all 482 problems without harness errors. The upgrade ladder is one run per model at its shipped defaults (two each for Opus 5 and Sonnet 5), run the same week in one harness and organization.
7223. **SWE-bench Pro:** Scale AI, "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", 2025. A 482-problem subset selected for compatibility with Anthropic's evaluation harness; scores are not comparable to the public leaderboard. Claude Opus 5 at the default effort averages two runs; reduced-effort settings are single runs; all ran August 4, 2026. Escalation figures come task by task from those runs: `low` first, then the default on its failures, solved 92.5% to 93.6% across run pairings for about $0.45; `medium` first, 93.8% to 94.2% for about $0.61; the default re-run on its own failures, 94.0% for $1.06; everything at the default, 90.9% to 92.5% for $0.93. Costs on this subset are priced as a customer's organization is metered: each request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, checked against a customer ledger; the evaluation organization's own metering, which bills cache in 8,192-token pages, gave figures 1.4 to 1.8 times higher. The Claude Sonnet 5 executor pairings on the advisor chart come from the same measurement series on this subset: the Sonnet-plus-Opus pairing was run twice (August 7 and August 8, 2026, a run and an exact replication), the low-effort pairing once (August 8, 2026), and Claude Sonnet 5 alone twice (77.4%, the baseline for both Pro rows). The Claude Fable 5 point in Upgrade the model is the mean of three runs at the default effort, run August 26, 2026, priced the same way. The Claude Fable 5.1 task-budget figures are one run per budget (two at 35,000 tokens) on the same subset at the default effort, run August 26, 2026, with an unbudgeted run the same day (92.1%, $1.10 per task) as the baseline; an earlier set at `low` effort, run August 21, 2026, scored 88.6% unbudgeted at $0.48 per task. The [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) comparison pairs that single run with the two pooled Claude Sonnet 5 runs from the same subset; at Fable 5.1's default effort the pair reads the other way, 41% more per solved task than Sonnet 5. The upgrade ladder is one run per model at its shipped defaults (two each for Opus 5 and Sonnet 5, and the Fable 5 point as described above), the Opus and Sonnet runs the same week in one harness and organization.
6967234. **BrowseComp:** Wei et al., "BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents," OpenAI, 2025. Effort figures use a 500-problem cut, one to three runs per setting, run August 3, 2026, with the default point pooling two runs from July 26 to 27, 2026. The cost-insurance chart uses 10 reliably solved problems from a 26-problem slice, 50 delegated runs (August 1 to 2, 2026) and 70 solo runs (50 from August 2 to 3, 2026; 20 archived from July 12 to 13 and August 1, 2026), $6.45 compared with $11.99 per run in expectation; delegated figures carry a measurement band of about 20%.
6977245. **Agent-architecture scaling:** Kim et al., "Towards a Science of Scaling Agent Systems," arXiv:2512.08296, 2025. Independent external study, cited only for the direction of the finding on when delegation does not pay, not for any figure.
6987256. **DeepWideSearch:** "DeepWideSearch: Benchmarking Depth and Width in Agentic Information Seeking," arXiv:2510.20168, 2025. The 220 questions span 15 domains, each combining many-row collection with multi-hop retrieval; measured on the benchmark's standing row set, 3 runs per configuration, run August 2, 2026 (the single-worker team point ran July 26 to 27, 2026).
6997. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs (August 2 to 3, 2026), scored on tasks no configuration refused. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Anthropic did not run Claude Opus 5 on this benchmark, so it is absent from the [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) chart. The Sonnet 5 cost differs slightly between the caching chart (inference cost, with and without caching) and that chart (all-in cost, caching on); both come from the same runs.
7008. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is an August 13, 2026, run in which the Claude Fable 5 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers; its three episodes scored F1 0.842, 0.805, and 0.810 for $263, $299, and $261. The solo configurations ran August 3 to 4, 2026, on the same corpus build. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
7267. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs per setting, on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with the platform's own web search and fetch tools (August 26 to 27, 2026); scored on the 33 tasks no configuration refused, with attempts the production safety classifiers cut short removed; costs are what a customer is billed, the platform's requests plus web-search fees. Scores are each model's mean on the 33-task basis with its own pre-empted tasks removed; on the 21 tasks clean in every arm, Claude Fable 5.1 holds a 2-to-3-point lead over Claude Fable 5 at every effort level and both models are flat across effort. The caching chart re-prices the same requests with every input token at the uncached rate. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Claude Opus 5 at its default effort ran on the same surface and subset, three runs, on August 28, 2026: 68.8% on the raw 50 tasks, 70.8% on the 33-task basis, and 71.1% on the 21-task set, at $6.71 per task ($23.72 without caching); none of its attempts was cut short by the safety classifiers, under a safeguards deployment newer than the one the other models ran under.
7278. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is a run in which the Claude Fable 5.1 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers, run August 30, 2026; its three episodes scored F1 0.764, 0.825, and 0.791 after the extras audit (raw 0.751, 0.821, and 0.781) for $225, $234, and $283. The Claude Sonnet 5 solo configuration ran August 3 to 4, 2026; the Claude Fable 5.1 solo configurations ran August 24 to 25, 2026, under the platform's launch serving settings, three seeds per effort setting, on the same corpus build. The sandbox image carried installed copies of part of the corpus, and Claude Fable 5.1's final assembly step compared against them in 7 of 9 episodes; re-grading without those additions moved the affected seeds by up to 3 points. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
7017289. **GPQA Diamond:** Rein et al., "GPQA: A Graduate-Level Google-Proof Q\&A Benchmark," 2023. The 198-question Diamond subset, two runs per configuration, run August 7, 2026, model-graded against reference answers, advisor tokens metered per request. A platform safety check refused two biology questions on the Sonnet and Opus executors; excluding them changes no comparison by more than one point.
70272910. **DeepSWE:** Datacurve, "DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks," arXiv:2607.07946, 2026. The set has 113 original tasks across five languages with program-based verifiers. Pairings are two runs each, run August 7, 2026, with advisor tokens metered per request, and used a client-side advisor loop rather than the advisor tool, with identical accounting. Single-model effort sweeps are single runs priced from token counts, a cache-aware approximation. Costs per task are run totals divided by 113.
70311. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures (Opus 5 alone, Fable 5 alone, and the pairing) were measured August 9 to 10, 2026, at the default effort with a 128,000-token output cap, one run per configuration: five attempts per task at the default settings and for the pairing, one at `low` and `medium`; the pairing averaged about two advisor consultations per attempt; costs are per attempt. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
70412. **Internal repository-task benchmark (cap measurement):** A separate Anthropic-internal set of about 130 repository tasks, run August 8 to 10, 2026, with a plain API agent loop, one attempt per task. The 16,384-token figures average two runs per model; the 64,000-token figures are single runs (124 tasks scored for Opus 5; 108 for Claude Fable 5, the environment having skipped the rest before the model ran). About half the Fable attempts the 16,384 cap had ended solved at 64,000; a further Fable run at 128,000 scored 56.1%, within noise of the 64,000 run. The SWE-bench Pro cap figures are one Claude Fable 5 run per cap (August 10, 2026) at the default effort on a 100-problem subset stratified from reference 3's 482-problem set, not comparable to its scores. The chart's per-turn distributions come from the Opus run at 64,000 and the Fable run at 128,000, so neither is cut off by its own cap.
70513. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 8 to 10, 2026, with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. Two runs per configuration, pooled; run-to-run spreads were 4 to 10 points. Costs exclude sandbox time, which added under 1%. The consult-rate comparison comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
73011. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures were measured with a 128,000-token output cap, one run per configuration: Opus 5 alone at the default effort August 9 to 10, 2026, Claude Fable 5.1 alone at five explicitly set effort values August 20, 2026, and the pairing August 24 to 25, 2026. Attempts per task: five for the pairing and the Opus-alone control, one for the single-model points; the pairing averaged about two advisor consultations per attempt; costs are per attempt. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
73112. **Internal repository-task benchmark (cap measurement):** A separate Anthropic-internal set of about 130 repository tasks, run August 8 to 10, 2026 (Claude Opus 5) and August 20, 2026 (Claude Fable 5.1), with a plain API agent loop, one attempt per task. The Claude Fable 5.1 runs are 135 tasks per cap at the default effort set explicitly: the 16,384-token figure averages two runs (36.3% on both); the 64,000 and 128,000 figures are single runs (58.5% and 60.0%). Six problems drew a safety refusal in every run and count as failures. The Opus 5 16,384-token figure averages two runs and its 64,000 figure is a single run (124 tasks scored). The SWE-bench Pro cap figures are one Claude Fable 5.1 run per cap at the default effort, run August 26, 2026, on a 100-problem subset stratified from reference 3's 482-problem set, not comparable to its scores; the two caps scored the same at the default. The chart's per-turn distributions come from the Opus run at 64,000 and the Claude Fable 5.1 run at 128,000; no Opus turn reached its cap, and one Fable 5.1 turn reached 128,000 (0.46% of its turns exceeded 16,384).
73213. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 8 to 10, 2026, with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. Two runs per configuration, pooled; run-to-run spreads were 4 to 10 points. Costs exclude sandbox time, which added under 1%. The Claude Fable 5.1 solo runs are from August 24, 2026, under the platform's launch serving settings, two runs per setting; six attempts hit the 15-minute session cap and score 0, and two charts per run were answered by Claude Opus 5 after a safety refusal. The Claude Opus 5 low-effort executor with a Claude Fable 5.1 advisor ran twice on August 30, 2026, under the same settings (63.0 and 67.0, mean 65.0, at $0.72 a chart; the advisor was consulted on 88% of tasks in each run, and 4 of its 219 replies came from Claude Opus 5 instead, each after a production safety filter stopped the advisor's own reply). The consult-rate comparison for the earlier pairings comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
70673314. **Support-desk prompt-audit evaluation:** An Anthropic-constructed set of 44 support tickets with deterministic grading, run in early August 2026 and reported on August 8, 2026, under six system prompts, each adding to the same clean prompt one pattern common in prompts written for Claude Opus 4.8 and Claude Sonnet 4.6. Each chart point is one of three cases (older model, newer model on the same prompt, newer model after the audit) averaged over the six prompts and 44 tickets. The Opus 5 accuracy gain has a 95% confidence interval of 3 to 8 points; the Sonnet accuracy differences are within noise.
70773415. **Data-file question set:** An Anthropic-constructed set of 25 aggregate questions over a 1,862-row slice of a public liquor-sales CSV, with ground truth computed by pandas and exact-match grading, run on Claude Sonnet 5 and Claude Opus 5 with thinking disabled (the in-context arm cannot complete at the default), a 4,000-token output cap, and no prompt caching, three runs per configuration, run August 19, 2026. The file arm uploads the CSV through the Files API and uses the `code_execution_20260120` tool.
70816. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 23, 2026, on Claude Sonnet 5 and Claude Opus 5 on the Messages API with the same harness, the Claude Opus 5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute pauses on a 5-issue subset on both models; 45-minute pauses on a 5-issue subset on Claude Sonnet 5 only). Three runs per cell, cost computed from each response's `usage` fields on a customer-billed organization at list prices, accuracy against the same gold labels. The crossover is about 3.3% of turns on both models: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 and 36 Claude Opus 5 twenty-issue sessions in the analysis (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). The 5% cell tied on Claude Sonnet 5 because that draw's pauses fell on small prefixes. The page's 1-in-20 rule sits above the measured crossover. Anthropic measured keep-alive requests that refresh the 5-minute cache as a comparator only. They matched the 1-hour setting at best and cost more with a pause before every turn, so do not use them.
73516. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 23, 2026, on Claude Sonnet 5 and Claude Opus 5 on the Messages API with the same harness, the Claude Opus 5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute pauses on a 5-issue subset on both models; 45-minute pauses on a 5-issue subset on Claude Sonnet 5 only). Three runs per cell, cost computed from each response's `usage` fields on a customer-billed organization at list prices, accuracy against the same gold labels. The crossover is about 3.3% of turns on both models: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 and 36 Claude Opus 5 twenty-issue sessions in the analysis (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). The 5% cell tied on Claude Sonnet 5 because that draw's pauses fell on small prefixes. The page's 1-in-20 rule sits above the measured crossover. Anthropic measured keep-alive requests that refresh the 5-minute cache as a comparator only. They matched the 1-hour setting at best and cost more with a pause before every turn, so do not use them on these two models; on Claude Fable 5.1 the arithmetic reverses (reference 19).
70973617. **Cache-read share in production:** Aggregated first-party Claude API usage for the 14 days ending August 23, 2026, direct API product only, Anthropic-internal organizations excluded, no organization identified. An organization-day counts as an agent loop when its requests carry tool definitions and tool results, its prompts hold 9 or more prior tool calls on average, caching was used, and it made at least 10 such requests (the API has no conversation identifier, so this stands in for conversation length): 303,003 organization-days across 106,487 organizations, median cache-read share 84.2% of all input tokens, upper quartile 91.7%. Use-case labels (the organization's declared use case, or otherwise its classified one) cover 74% of those organization-days and 99% of their tokens; coding organizations supply 87% of agentic input tokens and read a median 88.5% (90.9% at 25 or more prior tool calls), upper quartile 93.4%, with about 72% of coding organization-days at 80% or more; support, research, and data agents read 84% to 85%. The top decile of organization-days reads 95.9% or more for coding and 94.2% to 94.8% for support, research, data, and other agents. The request-level split at 25 or more prior tool calls comes from a six-hour sample: coding 92% read, 7% write, under 1% uncached. Unlabeled organizations, mostly small, read a median 11%. Organization-days with no tool definitions read a median 34.6%. An independent query over the same window that reconstructs conversations of 10 or more requests, rather than scoring organization-days, puts the median at 90.2%; the difference is scope, not data.
71073718. **Compaction timing measurement:** The triage agent's long variant from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 24, 2026, on Claude Sonnet 5 with the 5-minute cache, cost from the usage fields at list prices, five sessions per arm: a no-change arm at the default effort throughout ($0.81 per session), and two arms that start at low effort and make the same two cache-breaking changes, a switch to the default effort and one added tool, either mid-session at requests 12 and 17 ($0.95) or together on the first request after the first compaction ($0.75). A fourth arm of six sessions, run August 25, 2026, made the same two changes on the request that triggered the first compaction ($0.92 per session): that request's summarization pass wrote the 81,000-token context to the cache instead of reading it, so that pass cost $0.21 against $0.04 for the same pass in the boundary arm. Sessions first compacted at request 21 to 25 (16 of the 21 sessions at request 22), once the prompt passed the 80,000-token compaction trigger, and two no-change sessions compacted a second time near the end. The boundary arm's lower total than the no-change arm reflects its low-effort requests before the change and those second compactions rather than caching: the two arms' re-write costs differ by under a cent. The mid-session arm paid $0.23 per session in cache re-writes; the difference between the mid-session and boundary arms was $0.20 with a 95% confidence interval of $0.11 to $0.29. One mid-session session ran cheap ($0.82) after its model mis-called the search tool following compaction and got empty results; it is included, and without it the arm averages $0.98. Accuracy averaged 14.2 of 20 labels in each August 24 arm and 14.7 in the August 25 arm; cache reads were 91% of prompt tokens with no changes, 85% mid-session, 91% at the boundary, and 86% with the changes on the triggering request.
73819. **Cache duration measurement on Claude Fable 5.1:** The same 20-issue triage job and harness as reference 16, run August 23 and August 26, 2026, on the Claude Fable 5.1 launch snapshot at its launch prices ($10 input, $12.50 5-minute write, $20 1-hour write, $0.25 cache read, $50 output per million tokens), three settings per schedule: the 5-minute cache, the 1-hour cache, and the 5-minute cache kept warm by a `max_tokens: 0` request on the unchanged prefix every 4 minutes of idle time (the August 23 runs pinged with `max_tokens: 1`; every August 26 ping refreshed the cache and billed no output). Schedules: no pauses, 10% of turns, and every turn at 6 minutes on all 20 issues, and 45-minute pauses on the 5-issue subset; three runs per cell, cost computed from each response's `usage` fields at list prices, accuracy against the same gold labels (12 to 17 exact labels of 20). Per-session means on August 26 for the 5-minute, 1-hour, and keep-alive settings: no pauses $2.42, $3.09, $2.29; 10% paused $4.50, $2.96, $2.36; every turn $22.89, $3.01, $2.62; the August 23 cells agree within 6%. The 45-minute figures ($1.68, $0.59, and $0.71 per 5-issue session) are from a clean re-run on August 26 after a cache-billing incident spoiled that day's first cells; the August 23 runs gave $1.67, $0.58, and $0.70. The crossover between the 5-minute and 1-hour settings is 3.1% of turns, the same measure as reference 16.
73920. **Terminal-Bench 3:** the public terminal-agent benchmark's 74 tasks, run on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with two custom tools, a shell and a file editor that the evaluation harness runs in each task's own container, in place of the platform's built-in tools, and otherwise at the platform's default settings for external accounts, two runs per model at `high` effort, August 27 to 28, 2026. Scores are raw pass rates over the 148 attempts per model; single runs swing by 5 to 11 points. Costs are what a customer would be billed at list prices, re-priced request by request from the runs' usage records with the 5-minute cache lifetime. Claude Opus 4.7 ended 11 of its 148 attempts at its output cap.
711740 
712741## Next steps
713742 
from line 770
741770 </Card>
742771 
743772 <Card title="Webinar: Building on the Claude Platform" icon="play" href="https://www.anthropic.com/webinars/building-on-the-claude-platform-claude-fable-5-and-model-orchestration-patterns">
744 Watch a walkthrough of Claude Fable 5 and the advisor and orchestrator patterns.
773 Watch a walkthrough of the advisor and orchestrator patterns.
745774 </Card>
746775</CardGroup>
747776 

about-claude/pricing Changed · +30 / -24 lines

from line 12
1212 
1313The following table shows pricing for all Claude models:
1414 
15| Model | Base Input Tokens | 5m Cache Writes | 1h Cache Writes | Cache Hits & Refreshes | Output Tokens |
16| ------------------------------------------------------------------------------------------------------------------------------------- | ----------------- | --------------- | --------------- | ---------------------- | ------------- |
17| Claude Fable 5 | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
18| Claude Mythos 5 ([limited availability](https://anthropic.com/glasswing)) | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
19| Claude Opus 5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
20| Claude Opus 4.8 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
21| Claude Opus 4.7 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
22| Claude Opus 4.6 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
23| Claude Opus 4.5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
24| Claude Opus 4.1 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
25| Claude Opus 4 ([retired, except on Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
26| Claude Sonnet 5 | $2 / MTok | $2.50 / MTok | $4 / MTok | $0.20 / MTok | $10 / MTok |
27| Claude Sonnet 4.6 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
28| Claude Sonnet 4.5 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
29| Claude Sonnet 4 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
30| Claude Haiku 4.5 | $1 / MTok | $1.25 / MTok | $2 / MTok | $0.10 / MTok | $5 / MTok |
31| Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $0.80 / MTok | $1 / MTok | $1.60 / MTok | $0.08 / MTok | $4 / MTok |
15| Model | Base input tokens | 5m cache writes | 1h cache writes | Cache hits and refreshes | Output tokens |
16| ------------------------------------------------------------------------------------------------------------------------------------- | ----------------- | --------------- | --------------- | ------------------------ | ------------- |
17| Claude Fable 5.1 | $10 / MTok | $12.50 / MTok | $20 / MTok | $0.25 / MTok1 | $50 / MTok |
18| Claude Mythos 5.1 ([limited availability](https://anthropic.com/glasswing)) | $10 / MTok | $12.50 / MTok | $20 / MTok | $0.25 / MTok1 | $50 / MTok |
19| Claude Fable 5 | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
20| Claude Mythos 5 ([limited availability](https://anthropic.com/glasswing)) | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
21| Claude Opus 5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
22| Claude Opus 4.8 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
23| Claude Opus 4.7 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
24| Claude Opus 4.6 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
25| Claude Opus 4.5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
26| Claude Opus 4.1 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
27| Claude Opus 4 ([retired, except on Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
28| Claude Sonnet 5 | $2 / MTok | $2.50 / MTok | $4 / MTok | $0.20 / MTok | $10 / MTok |
29| Claude Sonnet 4.6 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
30| Claude Sonnet 4.5 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
31| Claude Sonnet 4 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
32| Claude Haiku 4.5 | $1 / MTok | $1.25 / MTok | $2 / MTok | $0.10 / MTok | $5 / MTok |
33| Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $0.80 / MTok | $1 / MTok | $1.60 / MTok | $0.08 / MTok | $4 / MTok |
3234 
35*1 Cache hits and refreshes on Claude Fable 5.1 and Claude Mythos 5.1 are priced at 0.025x the base input price. All other models use the standard 0.1x multiplier.*
36 
3337<Note id="claude-sonnet-5-introductory-pricing">
3438 The $2/$10 per million input/output token pricing for Claude Sonnet 5, announced at launch as introductory pricing through August 31, 2026, is now the standard price. The previously scheduled increase to $3/$15 per million input/output tokens on September 1, 2026 will not occur.
3539</Note>
from line 142
138142 
139143Prompt caching uses the following pricing multipliers relative to base input token rates:
140144 
141| Cache operation | Multiplier | Duration |
142| -------------------- | ---------------------- | ------------------------------------ |
143| 5-minute cache write | 1.25x base input price | Cache valid for 5 minutes |
144| 1-hour cache write | 2x base input price | Cache valid for 1 hour |
145| Cache read (hit) | 0.1x base input price | Same duration as the preceding write |
145| Cache operation | Multiplier | Duration |
146| -------------------- | ------------------------------------------------------------------------ | ------------------------------------ |
147| 5-minute cache write | 1.25x base input price | Cache valid for 5 minutes |
148| 1-hour cache write | 2x base input price | Cache valid for 1 hour |
149| Cache read (hit) | 0.1x base input price (0.025x on Claude Fable 5.1 and Claude Mythos 5.1) | Same duration as the preceding write |
146150 
147Cache write tokens are charged when content is first stored. Cache read tokens are charged when a subsequent request retrieves the cached content. A cache hit costs 10% of the standard input price, which means caching pays off after one cache read for the 5-minute duration (1.25x write), or after two cache reads for the 1-hour duration (2x write).
151Cache write tokens are charged when content is first stored. Cache read tokens are charged when a subsequent request retrieves the cached content. A cache hit costs 10% of the standard input price, which means caching pays off after one cache read for the 5-minute duration (1.25x write), or after two cache reads for the 1-hour duration (2x write). On Claude Fable 5.1 and Claude Mythos 5.1, a cache hit costs 2.5% of the standard input price ($0.25 USD per million tokens).
148152 
149153These multipliers stack with other pricing modifiers, including the Batch API discount and data residency.
150154 
from line 187
183187 
184188| Model | Batch input | Batch output |
185189| ------------------------------------------------------------------------------------------------------------------------------------- | ------------ | ------------- |
190| Claude Fable 5.1 | $5 / MTok | $25 / MTok |
191| Claude Mythos 5.1 ([limited availability](https://anthropic.com/glasswing)) | $5 / MTok | $25 / MTok |
186192| Claude Fable 5 | $5 / MTok | $25 / MTok |
187193| Claude Mythos 5 ([limited availability](https://anthropic.com/glasswing)) | $5 / MTok | $25 / MTok |
188194| Claude Opus 5 | $2.50 / MTok | $12.50 / MTok |

agents-and-tools/agent-skills/claude-api-skill Changed · +3 / -3 lines

from line 26
2626* **Streaming patterns:** Implementation details for building chat UIs and handling incremental display
2727* **Batch processing:** Offline batch processing at 50% cost
2828* **Prompt caching:** Prefix-stability design, breakpoint placement, and silent-invalidator audit
29* **Model migration:** Step-by-step guidance for migrating to newer Claude models (including the breaking changes and behavior shifts on [Claude Opus 5](https://platform.claude.com/docs/en/models/opus-5/migration-guide#migrating-from-claude-opus-4-8-to-claude-opus-5))
29* **Model migration:** Step-by-step guidance for migrating to newer Claude models (including the breaking changes and behavior shifts on [Claude Opus 5](https://platform.claude.com/docs/en/models/opus-5/migration-guide#migrating-from-claude-opus-4-8-to-claude-opus-5) and [Claude Fable 5.1](https://platform.claude.com/docs/en/models/fable-5-1/migration-guide))
3030* **Current model information:** Model IDs, context window sizes, and pricing
3131* **Common pitfalls:** Detailed guidance on avoiding frequent mistakes when integrating with the API
3232 
from line 124
124124* **Effort calibration**, recommending an `output_config.effort` starting point for the target model (for example, the default `high` on Claude Opus 5, and `xhigh` for coding and agentic use cases on Claude Opus 4.8 and Claude Opus 4.7)
125125* **Prompt-behavior tuning**, flagging length-control, tool-triggering, subagent, and instruction-following prompts that may behave differently on the target model
126126* **Silent default handling**, opting back into thinking summarization (`thinking.display: "summarized"`) when reasoning is surfaced to users on Claude Opus 4.8 and Claude Opus 4.7
127* **Refusal fallback configuration**, adding `stop_reason: "refusal"` handling before reading response content and setting up a [fallback retry path](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback) when the target is Claude Fable 5 or Claude Opus 5 (the server-side `fallbacks` parameter, typically in its `"default"` mode, the SDK refusal-fallback middleware, or a fallback-credit retry), and updating fallback code written against earlier preview shapes
127* **Refusal fallback configuration**, adding `stop_reason: "refusal"` handling before reading response content and setting up a [fallback retry path](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback) when the target is Claude Fable 5.1, Claude Fable 5, or Claude Opus 5 (the server-side `fallbacks` parameter, typically in its `"default"` mode, the SDK refusal-fallback middleware, or a fallback-credit retry), and updating fallback code written against earlier preview shapes
128128 
129129As it edits, the skill explains each change and its motivation inline. On completion, it produces a checklist of items that require manual verification (typically integration tests, length-control prompt tuning, and cost/rate-limit re-baselining).
130130 
131For the full list of model-specific changes the skill applies, see [Migrating to Claude Opus 5 from Claude Opus 4.8](https://platform.claude.com/docs/en/models/opus-5/migration-guide#migrating-from-claude-opus-4-8-to-claude-opus-5).
131For the full list of model-specific changes the skill applies, see [Migrating to Claude Opus 5 from Claude Opus 4.8](https://platform.claude.com/docs/en/models/opus-5/migration-guide#migrating-from-claude-opus-4-8-to-claude-opus-5) and [Migrating to Claude Fable 5.1](https://platform.claude.com/docs/en/models/fable-5-1/migration-guide).
132132 
133133## Setting up a Managed Agent
134134 

agents-and-tools/tool-use/advisor-tool Changed · +15 / -13 lines

from line 341
341341| `advisor_redacted_result` | `encrypted_content`, `stop_reason` | The advisor model returns encrypted output. |
342342 
343343<Note>
344 Currently, Claude Opus 5, Claude Fable 5, and Claude Mythos 5 advisors return the encrypted `advisor_redacted_result`. Every other advisor model in the [compatibility table](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#model-compatibility) returns the plaintext `advisor_result`. To read the advice text in your own responses, use an advisor that returns plaintext, such as `claude-opus-4-8`.
344 Claude Fable 5.1, Claude Mythos 5.1, Claude Opus 5, Claude Fable 5, and Claude Mythos 5 advisors return the encrypted `advisor_redacted_result`. Every other advisor model in the [compatibility table](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#model-compatibility) returns the plaintext `advisor_result`. To read the advice text in your own responses, use an advisor that returns plaintext, such as `claude-opus-4-8`, where your executor's row in the [compatibility table](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#model-compatibility) lists one. Claude Fable 5.1, Claude Mythos 5.1, Claude Opus 5, Claude Fable 5, and Claude Mythos 5 executors pair only with advisors that return the encrypted form, so on those executors the advice text isn't readable in the response.
345345</Note>
346346 
347347Here is the same request sent twice, identical except for the advisor `model` in the tool definition, showing both variants.
from line 1258
12581258 
12591259The plain-text nudge is highly salient on Haiku and Sonnet executors: 74 percent (Sonnet) to 98 percent (Haiku) of nudged attempts in Anthropic's testing called the advisor immediately at turn 2. If that lands before your executor has read the problem or gathered context, the resulting advisor call is low-context and can displace a better-timed later call. Measure your executor's baseline first-call turn before adding the nudge. If the executor already calls the advisor reliably and its first call typically lands at turn N, set `NUDGE_TURN` greater than N. In Anthropic's testing, a turn-2 nudge on workloads where the baseline first call was turn 7 or later correlated with a 3 to 4 percentage-point task-performance drop. On a browse workload where the baseline call rate was 86 percent, the same nudge raised engagement with no task-performance cost.
12601260 
1261To force a consult on a specific request instead of nudging, set `tool_choice` to `{"type": "tool", "name": "advisor"}`, subject to the constraints in [Forcing tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/define-tools#forcing-tool-use). Forcing tool use cannot be combined with manual extended thinking (`thinking: {type: "enabled"}`): the API returns a `400 invalid_request_error` if you enable both. Adaptive thinking supports forced tool use.
1261To force a consult on a specific request instead of nudging, set `tool_choice` to `{"type": "tool", "name": "advisor"}`, subject to the constraints in [Forcing tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/define-tools#forcing-tool-use). Forcing tool use cannot be combined with manual extended thinking (`thinking: {type: "enabled"}`): the API returns a `400 invalid_request_error` if you enable both. Adaptive thinking supports forced tool use. Claude Fable 5.1 and Claude Mythos 5.1 executors reject `tool_choice` types `tool` and `any`, so use the prompt nudge on those models instead.
12621262 
12631263## Streaming
12641264 
from line 1830
18301830 
18311831The executor model (the top-level `model` field) and the advisor model (the `model` field inside the tool definition) must form a valid pair. The advisor must be Claude Sonnet 4.6 or a more capable model, and it must be at least as capable as the executor. Models of equal capability (for example, Claude Opus 4.7 and Claude Opus 4.8) can advise each other.
18321832 
1833| Executor models | Advisor models |
1834| ------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
1835| Claude Haiku 4.5 (claude-haiku-4-5) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Opus 4.6 (claude-opus-4-6) Claude Sonnet 5 (claude-sonnet-5) Claude Sonnet 4.6 (claude-sonnet-4-6) |
1836| Claude Sonnet 4.6 (claude-sonnet-4-6) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Opus 4.6 (claude-opus-4-6) Claude Sonnet 5 (claude-sonnet-5) Claude Sonnet 4.6 (claude-sonnet-4-6) |
1837| Claude Sonnet 5 (claude-sonnet-5) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Sonnet 5 (claude-sonnet-5) |
1838| Claude Opus 4.6 (claude-opus-4-6) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Opus 4.6 (claude-opus-4-6) Claude Sonnet 5 (claude-sonnet-5) |
1839| Claude Opus 4.7 (claude-opus-4-7) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) |
1840| Claude Opus 4.8 (claude-opus-4-8) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) |
1841| Claude Opus 5 (claude-opus-5) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) |
1842| Claude Fable 5 (claude-fable-5) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) |
1843| Claude Mythos 5 (claude-mythos-5) | Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) |
1833| Executor models | Advisor models |
1834| ------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
1835| Claude Haiku 4.5 (claude-haiku-4-5) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Opus 4.6 (claude-opus-4-6) Claude Sonnet 5 (claude-sonnet-5) Claude Sonnet 4.6 (claude-sonnet-4-6) |
1836| Claude Sonnet 4.6 (claude-sonnet-4-6) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Opus 4.6 (claude-opus-4-6) Claude Sonnet 5 (claude-sonnet-5) Claude Sonnet 4.6 (claude-sonnet-4-6) |
1837| Claude Sonnet 5 (claude-sonnet-5) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Sonnet 5 (claude-sonnet-5) |
1838| Claude Opus 4.6 (claude-opus-4-6) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) Claude Opus 4.6 (claude-opus-4-6) Claude Sonnet 5 (claude-sonnet-5) |
1839| Claude Opus 4.7 (claude-opus-4-7) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) |
1840| Claude Opus 4.8 (claude-opus-4-8) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) Claude Opus 4.8 (claude-opus-4-8) Claude Opus 4.7 (claude-opus-4-7) |
1841| Claude Opus 5 (claude-opus-5) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) |
1842| Claude Fable 5 (claude-fable-5) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) |
1843| Claude Mythos 5 (claude-mythos-5) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) Claude Mythos 5 (claude-mythos-5) Claude Fable 5 (claude-fable-5) Claude Opus 5 (claude-opus-5) |
1844| Claude Fable 5.1 (claude-fable-5-1) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) |
1845| Claude Mythos 5.1 (claude-mythos-5-1) | Claude Mythos 5.1 (claude-mythos-5-1) Claude Fable 5.1 (claude-fable-5-1) |
18441846 
18451847If you request an invalid pair, the API returns a `400 invalid_request_error` naming the unsupported combination.
18461848 

agents-and-tools/tool-use/code-execution-tool Changed · +9 / -1 lines

### Content Credentials on generated files

from line 6
66 
77## Compatibility
88- [ZDR](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention): not eligible
9- Supported models: `claude-fable-5`, `claude-mythos-5`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`, `claude-opus-4-6`, `claude-opus-4-5-20251101`, `claude-sonnet-5`, `claude-sonnet-4-6`, `claude-sonnet-4-5-20250929`, `claude-haiku-4-5-20251001`
9- Supported models: `claude-fable-5-1`, `claude-mythos-5-1`, `claude-fable-5`, `claude-mythos-5`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`, `claude-opus-4-6`, `claude-opus-4-5-20251101`, `claude-sonnet-5`, `claude-sonnet-4-6`, `claude-sonnet-4-5-20250929`, `claude-haiku-4-5-20251001`
1010- Platforms: Claude API, Claude Platform on AWS, Microsoft Foundry [1]; not available on Amazon Bedrock, Google Cloud
1111- Every supported model accepts all three [tool versions](https://platform.claude.com/docs/en/agents-and-tools/tool-use/code-execution-tool#tool-versions). On Claude Haiku 4.5, programmatic tool calling and REPL state persistence aren't available, so the newer versions behave like `code_execution_20250825` there.
1212- For [Claude Mythos Preview](https://anthropic.com/glasswing), code execution is supported on the Claude API and Microsoft Foundry.
from line 885
885885```
886886 
887887A file Claude wrote elsewhere is still in the container, so you can [reuse the container](https://platform.claude.com/docs/en/agents-and-tools/tool-use/code-execution-tool#container-reuse) and ask Claude to copy it into `$OUTPUT_DIR`.
888 
889### Content Credentials on generated files
890 
891On the Claude API, supported image and video files that Claude produces in the code execution sandbox carry [C2PA](https://c2pa.org/) Content Credentials when you download them through the [Files API](https://platform.claude.com/docs/en/build-with-claude/files). [Supported formats](https://opensource.contentauthenticity.org/docs/sdk-repos/c2pa-python/docs/supported-formats/) include PNG, JPEG, GIF, WebP, TIFF, HEIC, AVIF, SVG, MP4, and MOV. The credential is a cryptographically signed manifest embedded in the file's metadata. It identifies Anthropic as the issuer, carries a timestamp, and records the action description "Claude provided this file at the request of a user and may have created or modified the file contents."
892 
893Signing requires no changes to your requests or response handling, and the manifest records nothing about you, your organization, or your request. The file's visible content is unchanged. The manifest adds a few kilobytes, so the downloaded file's size and checksum differ from the file as it exists inside the container. Text files, PDFs, and office documents are not signed because they are not supported formats for signing. Files you upload are stored as-is, including any Content Credentials they already carry.
894 
895To verify a credential, inspect the file with any C2PA-compatible tool, such as the open-source [c2patool command-line utility](https://github.com/contentauth/c2pa-rs). Re-encoding, format conversion, screenshots, and tools that strip metadata remove the credential, so a missing credential doesn't mean a file wasn't produced with Claude. For more on why a credential can be missing, see [How Claude marks AI-generated content](https://support.claude.com/en/articles/16266773-how-claude-marks-ai-generated-content).
888896 
889897## Tool definition
890898 

agents-and-tools/tool-use/computer-use-tool Changed · +3 / -2 lines

from line 6
66 
77## Compatibility
88- [ZDR](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention): eligible (excludes [Covered Models](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention#model-specific-data-retention-requirements))
9- Supported models: `claude-fable-5`, `claude-mythos-5`, `claude-opus-5`, `claude-sonnet-5`, `claude-opus-4-8`
9- Supported models: `claude-fable-5-1`, `claude-mythos-5-1`, `claude-fable-5`, `claude-mythos-5`, `claude-opus-5`, `claude-sonnet-5`, `claude-opus-4-8`
1010- Platforms: Claude API, Claude Platform on AWS (beta), Amazon Bedrock (beta), Google Cloud, Microsoft Foundry (beta)
1111- Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 4.6, and Claude Opus 4.5 support computer use only through the earlier `computer_20251124` tool version, which requires a beta header; see [Earlier tool versions](https://platform.claude.com/docs/en/agents-and-tools/tool-use/computer-use-tool#earlier-tool-versions).
1212- Platforms other than the Claude API and Google Cloud currently offer only the [earlier beta tool versions](https://platform.claude.com/docs/en/agents-and-tools/tool-use/computer-use-tool#earlier-tool-versions).
from line 1805
18051805 
18061806* Place one `cache_control` breakpoint after the system prompt and tool definitions, and up to three more on the last `tool_result` block of each of the most recent turns, advancing them each turn. Within a [batch action](https://platform.claude.com/docs/en/agents-and-tools/tool-use/computer-use-tool#batch-actions), markers on several blocks act as a single breakpoint but each still counts toward the limit of four, so use one per turn.
18071807* Prune old screenshots in *batches*, not one each turn. Dropping a screenshot every turn changes the prefix every turn and invalidates the cache. A reasonable default is to keep the last three screenshots and prune every 25 turns, so the prefix stays byte-identical between prune events; if your screenshots exceed 2000 px on either side, choose an interval that keeps each request at 20 or fewer images.
1808* On Claude Fable 5.1, avoid pruning on the client: removing an earlier screenshot [invalidates every later thinking block](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation) in every request that still carries those turns. Resize screenshots to 2000 px or less per side instead, and use server-side [tool result clearing](https://platform.claude.com/docs/en/build-with-claude/context-editing#tool-result-clearing) to drop old ones from the context. If you must prune, keep [`prefix_mismatch_behavior: "drop_block"`](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-thinking-controls) set from then on; after each prune, Claude continues without the thinking produced since the pruned screenshot, on that request and every later one.
18081809 
18091810### Diagnose click issues
18101811 
from line 2154
21532154 
21542155| Tool version | Beta header | Use with | Parameters |
21552156| ------------------- | ------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------- |
2156| `computer_20251124` | `computer-use-2025-11-24` | Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Sonnet 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 4.6, and Claude Opus 4.5 | [API reference](https://platform.claude.com/docs/en/api/beta/messages/create) |
2157| `computer_20251124` | `computer-use-2025-11-24` | Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Sonnet 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 4.6, and Claude Opus 4.5 | [API reference](https://platform.claude.com/docs/en/api/beta/messages/create) |
21572158| `computer_20250124` | `computer-use-2025-01-24` | Claude Sonnet 4.5, Claude Haiku 4.5, Claude Opus 4.1 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)), Claude Sonnet 4 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)), and Claude Opus 4 ([retired, except on Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | [API reference](https://platform.claude.com/docs/en/api/beta/messages/create) |
21582159 
21592160***

agents-and-tools/tool-use/define-tools Changed · +11 / -16 lines

## Choosing a model

from line 9
99* Familiarity with the [tool use overview](https://platform.claude.com/docs/en/agents-and-tools/tool-use/overview)
1010* A Claude API key and a working SDK or cURL setup
1111 
12## Choosing a model
13 
14Use the latest Claude Opus model, Claude Opus 5, for complex tools and ambiguous queries; it handles multiple tools better and seeks clarification when needed.
15 
16Use Claude Haiku models for straightforward tools, but note they may infer missing parameters.
17 
1812<Tip>
1913 If using Claude with tool use and thinking, see [Thinking](https://platform.claude.com/docs/en/build-with-claude/thinking) for more information.
2014</Tip>
from line 552
558552 
559553### Forcing tool use
560554 
561In some cases, you may want Claude to use a specific tool to answer the user's question, even if Claude would otherwise answer directly without calling a tool. You can do this by specifying the tool in the `tool_choice` field of the request. The highlighted lines are the only difference from a standard tool use request:
555In some cases, you may want Claude to use a specific tool to answer the user's question, even if Claude would otherwise answer directly without calling a tool. You can do this by specifying the tool in the `tool_choice` field of the request.
562556 
557Not every model and setting supports forced tool use. Where it isn't supported, `tool_choice: {"type": "any"}` and `tool_choice: {"type": "tool", "name": "..."}` fail, while `tool_choice: {"type": "auto"}` (the default) and `tool_choice: {"type": "none"}` still work:
558 
559| Model or setting | Restriction | What to use instead |
560| ----------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
561| Manual [extended thinking](https://platform.claude.com/docs/en/build-with-claude/extended-thinking) (`thinking: {type: "enabled"}`) | `any` and `tool` are not supported and result in an error | `auto` or `none`. [Adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking), including on models where thinking is on by default such as Claude Opus 5, supports forced tool use |
562| Claude Fable 5.1 and [Claude Mythos 5.1](https://anthropic.com/glasswing) | `any` and `tool` return a [400 error](https://platform.claude.com/docs/en/api/errors#forced-tool-use-not-supported) | `auto` with [strict tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/strict-tool-use) to guarantee schema-valid tool inputs, or [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs) when you need a response in a fixed JSON shape. Prompting still influences which tool `auto` picks. `none` is also supported |
563 
564On models that support it, the highlighted lines are the only difference from a standard tool use request:
565 
563566<CodeGroup>
564567 ```bash cURL
565568 curl -sS https://api.anthropic.com/v1/messages \
from line 859
856859 
857860Note that when you have `tool_choice` as `any` or `tool`, the API prefills the assistant message to force a tool to be used. This means that the models will not emit a natural language response or explanation before `tool_use` content blocks, even if explicitly asked to do so.
858861 
859<Note>
860 When using manual [extended thinking](https://platform.claude.com/docs/en/build-with-claude/extended-thinking) (`thinking: {type: "enabled"}`) with tool use, `tool_choice: {"type": "any"}` and `tool_choice: {"type": "tool", "name": "..."}` are not supported and result in an error. Only `tool_choice: {"type": "auto"}` (the default) and `tool_choice: {"type": "none"}` are compatible with manual extended thinking. [Adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking), including on models where thinking is on by default such as Claude Opus 5, supports forced tool use.
861</Note>
862 
863<Note>
864 [Claude Mythos Preview](https://anthropic.com/glasswing) does not support forced tool use. Requests with `tool_choice: {"type": "any"}` or `tool_choice: {"type": "tool", "name": "..."}` return a 400 error on this model. Use `tool_choice: {"type": "auto"}` (the default) or `tool_choice: {"type": "none"}` and rely on prompting to influence tool selection.
865</Note>
866 
867862Testing has shown that this should not reduce performance. If you would like the model to provide natural language context or explanations while still requesting that the model use a specific tool, you can use `{"type": "auto"}` for `tool_choice` (the default) and add explicit instructions in a `user` message. For example: `What's the weather like in London? Use the get_weather tool in your response.`
868863 
869864<Tip>
870865 **Guaranteed tool calls with strict tools**
871866 
872 Combine `tool_choice: {"type": "any"}` with [strict tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/strict-tool-use) to guarantee both that one of your tools will be called AND that the tool inputs strictly follow your schema. Set `strict: true` on your tool definitions to enable schema validation.
867 On models that support forced tool use, combine `tool_choice: {"type": "any"}` with [strict tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/strict-tool-use) to guarantee both that one of your tools is called and that the tool inputs strictly follow your schema. Set `strict: true` on your tool definitions to enable schema validation.
873868</Tip>
874869 
875870### Model responses with tools

agents-and-tools/tool-use/parallel-tool-use Changed · +7 / -1 lines

from line 838
838838 </Accordion>
839839</AccordionGroup>
840840 
841<Note>
842 **Claude Fable 5.1 in long agent loops**
843 
844 Claude Fable 5.1 may issue fewer parallel tool calls than earlier models, most noticeably in long agent loops where the next reads are only implied (custom coding agents, bash and text editor harnesses, computer use). Standard function calling is unaffected. For the batching instruction to add and where to put it, see [Batch independent tool calls in agent loops](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#batch-independent-tool-calls-in-agent-loops).
845</Note>
846 
841847## Disable parallel tool use
842848 
843849Parallel tool use is on by default. To turn it off, set `disable_parallel_tool_use: true` inside the [`tool_choice`](https://platform.claude.com/docs/en/agents-and-tools/tool-use/define-tools#forcing-tool-use) object. It is not a top-level request parameter. The effect depends on the `tool_choice` type.
from line 1131
11251131 
11261132### Exactly one tool call
11271133 
1128When `tool_choice` type is `any` or `tool`, setting `disable_parallel_tool_use: true` means Claude calls exactly one tool. The following example uses `any`. The same field works with `tool`:
1134When `tool_choice` type is `any` or `tool`, setting `disable_parallel_tool_use: true` means Claude calls exactly one tool. Claude Fable 5.1 and Claude Mythos 5.1 don't support these `tool_choice` types (see [Forcing tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/define-tools#forcing-tool-use)). The following example uses `any`. The same field works with `tool`:
11291135 
11301136<CodeGroup>
11311137 ```bash cURL

api/errors Changed · +33 / -5 lines

### Forced tool use not supported ### Thinking block no longer matches the conversation

from line 451
451451`thinking` or `redacted_thinking` blocks in the latest assistant message cannot be modified. These blocks must remain as they were in the original response.
452452```
453453 
454With tool use, every `thinking` and `redacted_thinking` block from the assistant turn must be passed back exactly as received, including blocks whose `thinking` field is empty. Pass thinking blocks back unchanged, and if your application filters content blocks by type before resending, include both `thinking` and `redacted_thinking`. See [Troubleshooting thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#error-thinking-blocks-modified), [Preserving thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#preserving-thinking-blocks), and [Thinking output on Claude Fable 5 and Claude Mythos 5](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-output-on-claude-fable-5-and-claude-mythos-5).
454With tool use, every `thinking` and `redacted_thinking` block from the assistant turn must be passed back exactly as received, including blocks whose `thinking` field is empty. Pass thinking blocks back unchanged, and if your application filters content blocks by type before resending, include both `thinking` and `redacted_thinking`. See [Troubleshooting thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#error-thinking-blocks-modified), [Preserving thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#preserving-thinking-blocks), and [Preserved thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-thinking).
455455 
456456### Extended thinking not supported
457457 
from line 475
475475 
476476### Thinking cannot be disabled
477477 
478On Claude Fable 5, [Claude Mythos 5](https://anthropic.com/glasswing), and [Claude Mythos Preview](https://anthropic.com/glasswing), thinking is always on. Sending `thinking: {"type": "disabled"}` to any of these models returns a 400 `invalid_request_error`:
478On Claude Fable 5.1, [Claude Mythos 5.1](https://anthropic.com/glasswing), Claude Fable 5, [Claude Mythos 5](https://anthropic.com/glasswing), and [Claude Mythos Preview](https://anthropic.com/glasswing), thinking is always on. Sending `thinking: {"type": "disabled"}` to any of these models returns a 400 `invalid_request_error`:
479479 
480480```text wrap
481481"thinking.type.disabled" is not supported for this model. Thinking defaults to adaptive mode when not specified; use "thinking.type.enabled" with "budget_tokens" for extended thinking.
482482```
483483 
484On Claude Fable 5 and Claude Mythos 5, the error message's own suggestion of `"thinking.type.enabled"` is also rejected. Omit the `thinking` parameter and the request runs with adaptive thinking. To keep thinking content out of responses without turning thinking off, set `display: "omitted"` on the thinking configuration. See [Troubleshooting thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#error-thinking-type-disabled).
484On Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, and Claude Mythos 5, the error message's own suggestion of `"thinking.type.enabled"` is also rejected. Omit the `thinking` parameter and the request runs with adaptive thinking. To keep thinking content out of responses without turning thinking off, set `display: "omitted"` on the thinking configuration. See [Troubleshooting thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#error-thinking-type-disabled).
485485 
486### Forced tool use not supported
487 
488Claude Fable 5.1 and [Claude Mythos 5.1](https://anthropic.com/glasswing) don't support forced tool use. Sending `tool_choice: {"type": "any"}` or `tool_choice: {"type": "tool", "name": "..."}` to either model, including on the [token counting endpoint](https://platform.claude.com/docs/en/build-with-claude/token-counting), returns a 400 `invalid_request_error`:
489 
490```text wrap
491tool_choice: type "tool" and "any" are not supported for this model.
492```
493 
494`tool_choice: {"type": "auto"}` (the default) and `{"type": "none"}` are accepted. Use `auto` with [strict tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/strict-tool-use) to keep tool inputs schema-valid, or [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs) when you need the response itself in a fixed JSON shape. See [Forcing tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/define-tools#forcing-tool-use).
495 
496### Thinking block no longer matches the conversation
497 
498On Claude Fable 5.1, the API accepts a replayed thinking block only while the `system` prompt, `tools`, and messages that preceded it are unchanged. For new accounts created on or after August 31, 2026, and for any request that sets `thinking.block_binding.prefix_mismatch_behavior` to `"error"`, a replayed block whose earlier history changed is rejected with a 400 `invalid_request_error` (with `"drop_block"`, the API drops the block and the request succeeds). The message starts with the position of the first failing block:
499 
500```text wrap
501messages.{i}.content.{j}: Invalid `signature` in `thinking` block. The block is bound to a different conversation. Remove the block, or set `thinking.block_binding.prefix_mismatch_behavior` to "drop_block".
502```
503 
504Without the `thinking-binding-controls-2026-08-01` beta header the message also names that header. Keep the conversation history append-only, or send the beta header with `prefix_mismatch_behavior: "drop_block"` to drop the block and continue. A block from a model the target model can't read is dropped rather than rejected. See [Preserved thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation) and [Troubleshooting thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#error-thinking-block-signature).
505 
506Sending `thinking.block_binding` without the `thinking-binding-controls-2026-08-01` [beta header](https://platform.claude.com/docs/en/api/beta-headers) returns a 400 `invalid_request_error` whose message ends in:
507 
508```text wrap
509block_binding: Extra inputs are not permitted
510```
511 
512Add the header, or remove the field.
513 
486514### Outbound web identity federation disabled (Claude Platform on AWS)
487515 
488516If every request to [Claude Platform on AWS](https://platform.claude.com/docs/en/build-with-claude/claude-platform-on-aws) returns `"Outbound web identity federation is disabled for your account"`, run `aws iam enable-outbound-web-identity-federation` once per AWS account. See [Enable outbound web identity federation](https://platform.claude.com/docs/en/build-with-claude/claude-platform-on-aws#enable-outbound-web-identity-federation) for details.
from line 518
490518## Next steps
491519 
492520<CardGroup cols={3}>
493 <Card title="Trigger a routine through the API" icon="play" href="https://platform.claude.com/docs/en/api/claude-code/routines-fire">
494 Start a Claude Code routine session on demand by sending an authenticated POST request.
521 <Card title="Troubleshooting thinking" icon="wrench" href="https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting">
522 Symptom-first fixes for thinking configuration 400 errors, empty thinking blocks, and `max_tokens` stops.
495523 </Card>
496524 
497525 <Card title="Rate limits" icon="gauge" href="https://platform.claude.com/docs/en/api/rate-limits">

api/rate-limits Changed · +22 / -20 lines

from line 119
119119**Example:** With a 2,000,000 ITPM limit and an 80% cache hit rate, you could effectively process 10,000,000 total input tokens per minute (2M uncached + 8M cached), because cached tokens don't count toward your rate limit.
120120 
121121<Note>
122 Claude Haiku 3.5 (marked with in the following rate limit tables) also counts `cache_read_input_tokens` toward ITPM rate limits.
122 Claude Haiku 3.5 (marked with footnote 4 in the following rate limit tables) also counts `cache_read_input_tokens` toward ITPM rate limits.
123123 
124 For all models without the † marker, cached input tokens do not count toward rate limits and are billed at a reduced rate (10% of base input token price). This means you can achieve significantly higher effective throughput by using [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching).
124 For all other models, cached input tokens do not count toward rate limits and are billed at the [cache read rate](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#pricing), a fraction of the base input price. This means you can achieve significantly higher effective throughput by using [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching).
125125</Note>
126126 
127127To make the most of your rate limits, cache repeated content such as system instructions and prompts, large context documents, tool definitions, and conversation history; see [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) for guidance. With effective caching, you can substantially increase your actual throughput without raising your rate limits. Monitor your cache hit rate on the [Usage page](https://platform.claude.com/usage) to tune your caching strategy.
from line 138
138138 <Tab title="Start tier">
139139 | Model | Maximum requests per minute (RPM) | Maximum input tokens per minute (ITPM) | Maximum output tokens per minute (OTPM) |
140140 | ------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------- | -------------------------------------- | --------------------------------------- |
141 | Claude Fable 5 | 1,000 | 500,000 | 100,000 |
141 | Claude Fable 5.x1 | 1,000 | 500,000 | 100,000 |
142142 | Claude Opus 5 | 1,000 | 2,000,000 | 400,000 |
143 | Claude Opus 4.x\* | 1,000 | 2,000,000 | 400,000 |
143 | Claude Opus 4.x2 | 1,000 | 2,000,000 | 400,000 |
144144 | Claude Sonnet 5 | 1,000 | 2,000,000 | 400,000 |
145 | Claude Sonnet 4.x\*\* | 1,000 | 2,000,000 | 400,000 |
145 | Claude Sonnet 4.x3 | 1,000 | 2,000,000 | 400,000 |
146146 | Claude Haiku 4.5 | 1,000 | 2,000,000 | 400,000 |
147 | Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | 1,000 | 100,000† | 20,000 |
147 | Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | 1,000 | 100,0004 | 20,000 |
148148 </Tab>
149149 
150150 <Tab title="Build tier">
151151 | Model | Maximum requests per minute (RPM) | Maximum input tokens per minute (ITPM) | Maximum output tokens per minute (OTPM) |
152152 | ------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------- | -------------------------------------- | --------------------------------------- |
153 | Claude Fable 5 | 2,000 | 1,500,000 | 300,000 |
153 | Claude Fable 5.x1 | 2,000 | 1,500,000 | 300,000 |
154154 | Claude Opus 5 | 5,000 | 5,000,000 | 1,000,000 |
155 | Claude Opus 4.x\* | 5,000 | 5,000,000 | 1,000,000 |
155 | Claude Opus 4.x2 | 5,000 | 5,000,000 | 1,000,000 |
156156 | Claude Sonnet 5 | 5,000 | 5,000,000 | 1,000,000 |
157 | Claude Sonnet 4.x\*\* | 5,000 | 5,000,000 | 1,000,000 |
157 | Claude Sonnet 4.x3 | 5,000 | 5,000,000 | 1,000,000 |
158158 | Claude Haiku 4.5 | 5,000 | 5,000,000 | 1,000,000 |
159 | Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | 2,000 | 200,000† | 40,000 |
159 | Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | 2,000 | 200,0004 | 40,000 |
160160 </Tab>
161161 
162162 <Tab title="Scale tier">
163163 | Model | Maximum requests per minute (RPM) | Maximum input tokens per minute (ITPM) | Maximum output tokens per minute (OTPM) |
164164 | ------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------- | -------------------------------------- | --------------------------------------- |
165 | Claude Fable 5 | 4,000 | 4,000,000 | 800,000 |
165 | Claude Fable 5.x1 | 4,000 | 4,000,000 | 800,000 |
166166 | Claude Opus 5 | 10,000 | 10,000,000 | 2,000,000 |
167 | Claude Opus 4.x\* | 10,000 | 10,000,000 | 2,000,000 |
167 | Claude Opus 4.x2 | 10,000 | 10,000,000 | 2,000,000 |
168168 | Claude Sonnet 5 | 10,000 | 10,000,000 | 2,000,000 |
169 | Claude Sonnet 4.x\*\* | 10,000 | 10,000,000 | 2,000,000 |
169 | Claude Sonnet 4.x3 | 10,000 | 10,000,000 | 2,000,000 |
170170 | Claude Haiku 4.5 | 10,000 | 10,000,000 | 2,000,000 |
171 | Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | 4,000 | 400,000† | 80,000 |
171 | Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | 4,000 | 400,0004 | 80,000 |
172172 </Tab>
173173 
174174 <Tab title="Custom tier">
from line 176
176176 </Tab>
177177</Tabs>
178178 
179*\* Opus rate limit is a total limit that applies to combined traffic across Claude Opus 4.8, Opus 4.7, Opus 4.6, and Opus 4.5. Claude Opus 5 has a separate rate limit and is not part of this combined bucket.*
179*1 Fable rate limit is a total limit that applies to combined traffic across Claude Fable 5.1 and Claude Fable 5. Claude Mythos 5.1 and Claude Mythos 5 share a separate combined limit on the same terms.*
180180 
181*\*\* Sonnet 4.x rate limit is a total limit that applies to combined traffic across Sonnet 4.6 and Sonnet 4.5. Claude Sonnet 5 has a separate rate limit and is not part of this combined bucket.*
181*2 Opus rate limit is a total limit that applies to combined traffic across Claude Opus 4.8, Opus 4.7, Opus 4.6, and Opus 4.5. Claude Opus 5 has a separate rate limit and is not part of this combined bucket.*
182182 
183*† Limit counts `cache_read_input_tokens` toward ITPM usage.*
183*3 Sonnet 4.x rate limit is a total limit that applies to combined traffic across Sonnet 4.6 and Sonnet 4.5. Claude Sonnet 5 has a separate rate limit and is not part of this combined bucket.*
184 
185*4 Limit counts `cache_read_input_tokens` toward ITPM usage.*
184186 
185187### Message Batches API
186188 

build-with-claude/claude-in-amazon-bedrock Changed · +6 / -3 lines

from line 12
1212 
1313## Access
1414 
15Amazon Bedrock sets access criteria for each Claude model individually. Claude Fable 5, Claude Opus 4.8, Claude Sonnet 5, Claude Opus 4.7, and Claude Haiku 4.5 are open to all Amazon Bedrock customers; for any other model's current criteria, check [Amazon Bedrock model access](https://console.aws.amazon.com/bedrock/home#/modelaccess) in the AWS console. Claude Mythos Preview requires an invitation; see [Project Glasswing](https://anthropic.com/glasswing). For region availability, see [Regions](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock#regions).
15Amazon Bedrock sets access criteria for each Claude model individually. Claude Fable 5.1, Claude Fable 5, Claude Opus 4.8, Claude Sonnet 5, Claude Opus 4.7, and Claude Haiku 4.5 are open to all Amazon Bedrock customers. For any other model's current criteria, check [Amazon Bedrock model access](https://console.aws.amazon.com/bedrock/home#/modelaccess) in the AWS console. Claude Mythos Preview requires an invitation through [Project Glasswing](https://anthropic.com/glasswing). For region availability, see [Regions](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock#regions).
1616 
1717## Prerequisites
1818 
from line 328
328328 
329329| Model | Model ID | Access |
330330| --------------------- | ------------------------------- | --------------------------------------------------------------------------------------------------- |
331| Claude Fable 5.1 | anthropic.claude-fable-5-1 | Open |
331332| Claude Fable 5 | anthropic.claude-fable-5 | Open |
332333| Claude Opus 5 | anthropic.claude-opus-5 | See [Access](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock#access) |
333334| Claude Opus 4.8 | anthropic.claude-opus-4-8 | Open |
from line 337
336337| Claude Haiku 4.5 | anthropic.claude-haiku-4-5 | Open |
337338| Claude Mythos Preview | anthropic.claude-mythos-preview | Invitation only ([Project Glasswing](https://anthropic.com/glasswing)) |
338339 
340Use Claude Code 2.1.255 or later with Claude Fable 5.1 on Amazon Bedrock; run `claude update` to upgrade.
341 
339342<Tip>
340343 Upgrading to a newer Claude model? In Claude Code, run `/claude-api migrate` to apply model ID swaps and breaking parameter changes across your codebase. The skill detects which cloud platform your code targets and adjusts model ID formats and feature changes for that platform. See [Migrating to a newer Claude model](https://platform.claude.com/docs/en/agents-and-tools/agent-skills/claude-api-skill#migrating-to-a-newer-claude-model).
341344</Tip>
from line 373
370373* **Global:** dynamic routing across all available regions for maximum availability. No pricing premium.
371374* **Regional:** the endpoint resolves to the single AWS region you specify, for data-residency requirements. Regional endpoints carry a 10% pricing premium over global endpoints. To route across multiple regions within a geography, use an [inference profile](https://docs.aws.amazon.com/bedrock/latest/userguide/cross-region-inference.html) (US, EU, JP, or AU). Regions marked **In-region only** in the table support direct single-region routing without an inference profile.
372375 
373The global endpoint is available for Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Sonnet 5, and Claude Haiku 4.5. Claude Mythos Preview is regional only and is available in `us-east-1`.
376The global endpoint is available for Claude Fable 5.1, Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Sonnet 5, and Claude Haiku 4.5. For Claude Fable 5.1, regional endpoints are currently available in `us-east-1` only. Claude Mythos Preview is regional only and is available in `us-east-1`.
374377 
375378| AWS region | Location | Endpoint types |
376379| ---------------- | ------------------------- | -------------------------- |
from line 407
404407 
405408## Quotas
406409 
407Default quota is 2 million input tokens per minute (TPM). You can request up to 4 million input TPM without additional Anthropic approval. AWS enforces requests-per-minute (RPM) limits on the Bedrock side; contact AWS support for RPM adjustments.
410Default quota is 2 million input tokens per minute (TPM). You can request up to 5 million input TPM and 500,000 output TPM without additional Anthropic approval. AWS enforces requests-per-minute (RPM) limits on the Bedrock side; contact AWS support for RPM adjustments.
408411 
409412## Data retention
410413 

build-with-claude/claude-in-microsoft-foundry Changed · +3 / -2 lines

from line 4
44description: Access Claude models through Microsoft Foundry with Azure-native endpoints and authentication.
55---
66 
7This guide shows you how to set up and make API calls to Claude in Microsoft Foundry using one of Anthropic's client SDKs or direct HTTP requests. When you access Claude in Microsoft Foundry, you are billed for Claude usage in the Azure Marketplace. You can use the latest Claude models, including Claude Opus 5, Claude Opus 4.8, and Claude Sonnet 5, and features such as the [1M-token context window](https://platform.claude.com/docs/en/build-with-claude/context-windows), while managing costs through your Azure subscription.
7This guide shows you how to set up and make API calls to Claude in Microsoft Foundry using one of Anthropic's client SDKs or direct HTTP requests. When you access Claude in Microsoft Foundry, you are billed for Claude usage in the Azure Marketplace. You can use Claude models including Claude Fable 5.1, Claude Opus 5, Claude Opus 4.8, and Claude Sonnet 5, and features such as the [1M-token context window](https://platform.claude.com/docs/en/build-with-claude/context-windows), while managing costs through your Azure subscription.
88 
99Claude is available in Global Standard and US Data Zone Standard deployment types in Foundry resources, billed in Claude Consumption Units through the Azure Marketplace. Visit [Claude in Microsoft Foundry pricing](https://platform.claude.com/docs/en/about-claude/pricing#claude-in-microsoft-foundry-pricing) for details.
1010 
from line 632
632632 
633633### Context window
634634 
635Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6 have a [1M-token context window](https://platform.claude.com/docs/en/build-with-claude/context-windows) on Microsoft Foundry. Other Claude models, including Claude Sonnet 4.5, have a 200k-token context window.
635Claude Fable 5.1, Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6 have a [1M-token context window](https://platform.claude.com/docs/en/build-with-claude/context-windows) on Microsoft Foundry. Other Claude models, including Claude Sonnet 4.5, have a 200k-token context window.
636636 
637637### Claude features not supported for Claude in Microsoft Foundry
638638 
from line 671
671671 
672672| Model | Default deployment name | Hosted on Azure | Hosted on Anthropic |
673673| ----------------- | ----------------------- | --------------- | ------------------- |
674| Claude Fable 5.1 | claude-fable-5-1 | | ✓ |
674675| Claude Fable 5 | claude-fable-5 | | ✓ |
675676| Claude Opus 5 | claude-opus-5 | ✓ | ✓ |
676677| Claude Opus 4.8 | claude-opus-4-8 | ✓ | ✓ |

build-with-claude/claude-on-amazon-bedrock-legacy Changed · +3 / -3 lines

from line 125
125125#### API model IDs
126126 
127127<Note>
128 Claude Opus 5, Claude Sonnet 5, Claude Fable 5, Claude Opus 4.8, and Claude Opus 4.7 are reachable through `InvokeModel` on `bedrock-runtime`. These requests are served by the same infrastructure as the [Claude in Amazon Bedrock](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock) endpoint. For the native Messages API request shape and full feature parity, use that page. These models are omitted from the model table on this page because they do not have ARN-versioned model IDs.
128 Claude Fable 5.1, Claude Fable 5, Claude Opus 5, Claude Sonnet 5, Claude Opus 4.8, and Claude Opus 4.7 are reachable through `InvokeModel` on `bedrock-runtime`. These requests are served by the same infrastructure as the [Claude in Amazon Bedrock](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock) endpoint. For the native Messages API request shape and full feature parity, use that page. These models are omitted from the model table on this page because they do not have ARN-versioned model IDs.
129129</Note>
130130 
131131Lifecycle terms (Deprecated, Retired) are defined in [Model deprecations](https://platform.claude.com/docs/en/about-claude/model-deprecations). Lifecycle dates on partner-operated platforms are set by the partner and can differ from the Claude API schedule. For the current retirement date of any model on Amazon Bedrock, see [Amazon Bedrock's model lifecycle page](https://docs.aws.amazon.com/bedrock/latest/userguide/model-lifecycle.html).
from line 752
752752 
753753### Mid-conversation system messages on Bedrock
754754 
755[Mid-conversation system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages) are available through the InvokeModel API for Claude Fable 5 and Claude Opus 4.8. As described in the note under [API model IDs](https://platform.claude.com/docs/en/build-with-claude/claude-on-amazon-bedrock-legacy#api-model-ids), these requests are served by the same infrastructure as the [Claude in Amazon Bedrock](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock) endpoint. No beta header is required. This feature is not available on Claude Sonnet 5; use the top-level `system` field instead. It is not available for the ARN-versioned models in the model table on this page.
755[Mid-conversation system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages) are available through the InvokeModel API for Claude Fable 5.1, Claude Fable 5, Claude Opus 5, and Claude Opus 4.8. As described in the note under [API model IDs](https://platform.claude.com/docs/en/build-with-claude/claude-on-amazon-bedrock-legacy#api-model-ids), these requests are served by the same infrastructure as the [Claude in Amazon Bedrock](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock) endpoint. No beta header is required. This feature is not available on Claude Sonnet 5. Use the top-level `system` field instead. It is not available for the ARN-versioned models in the model table on this page.
756756 
757757**For Converse API users:** the Converse API accepts system instructions through its top-level [`system` parameter](https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_Converse.html). To add system instructions mid-conversation, use the InvokeModel API.
758758 
759759### Context window
760760 
761Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6 have a [1M-token context window](https://platform.claude.com/docs/en/build-with-claude/context-windows) on Amazon Bedrock. Other Claude models, including Sonnet 4.5 and Sonnet 4 (deprecated), have a 200k-token context window.
761Claude Fable 5.1, Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6 have a [1M-token context window](https://platform.claude.com/docs/en/build-with-claude/context-windows) on Amazon Bedrock. Other Claude models, including Sonnet 4.5 and Sonnet 4 (deprecated), have a 200k-token context window.
762762 
763763Bedrock limits request payloads to 20 MB. When sending large documents or many images, you may reach this limit before the token limit.
764764 

build-with-claude/compaction Changed · +7 / -1 lines

from line 8
88- Status: Beta
99- [Beta header](https://platform.claude.com/docs/en/api/beta-headers): `compact-2026-01-12`
1010- [ZDR](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention): eligible (excludes [Covered Models](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention#model-specific-data-retention-requirements))
11- Supported models: `claude-fable-5`, `claude-mythos-5`, `claude-mythos-preview`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`, `claude-opus-4-6`, `claude-sonnet-5`, `claude-sonnet-4-6`
11- Supported models: `claude-fable-5-1`, `claude-mythos-5-1`, `claude-fable-5`, `claude-mythos-5`, `claude-mythos-preview`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`, `claude-opus-4-6`, `claude-sonnet-5`, `claude-sonnet-4-6`
1212- Platforms: Claude API (beta), Claude Platform on AWS (beta), Amazon Bedrock (beta), Google Cloud (beta), Microsoft Foundry (beta)
1313 
1414<Tip>
from line 707
707707 ```
708708</CodeGroup>
709709 
710On Claude Fable 5.1 and Claude Mythos 5.1, a request with custom `instructions` summarizes from the visible conversation only: earlier thinking blocks are not part of the summarizer's input.
711 
710712### Pausing after compaction
711713 
712714Use `pause_after_compaction` to pause the API after generating the compaction summary. This allows you to add additional content blocks (such as preserving recent messages or specific instruction-oriented messages) before the API continues with the response.
from line 1692
16901692* Keep the original messages in your list and let the API handle removing the compacted content
16911693* Manually drop the compacted messages and only include the compaction block onwards
16921694 
1695On Claude Fable 5.1 and Claude Mythos 5.1, thinking blocks from before a `compaction` block aren't carried forward, so the summary is all the model has of that earlier work. If you write your own `instructions`, tell the model what the summary must retain; see [Tell the model what to preserve in compaction summaries](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#tell-the-model-what-to-preserve-in-compaction-summaries).
1696 
16931697### Streaming
16941698 
16951699The compaction block streams differently from text blocks. You receive a `content_block_start` event, followed by a single `content_block_delta` with the complete summary content (no intermediate streaming), and then a `content_block_stop` event.
from line 2834
28302834 puts chat(client, messages, "Now add rate limiting and error handling")
28312835 ```
28322836</CodeGroup>
2837 
2838On Claude Fable 5.1, remove the `thinking` and `redacted_thinking` blocks from any assistant turn you re-insert after the compaction block, or send `thinking.block_binding.prefix_mismatch_behavior: "drop_block"` with the `thinking-binding-controls-2026-08-01` [beta header](https://platform.claude.com/docs/en/api/beta-headers). Those blocks were produced when the full history was present, so they no longer pass the [conversation check](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation). Where the check is enforced, the continuation request is rejected with a 400 error. The preserved text and tool blocks can stay as they are. Letting the API summarize everything, without re-inserting earlier turns, avoids this.
28332839 
28342840Here's an example that uses `pause_after_compaction` to preserve the prior exchange and the current user message (three messages total) verbatim instead of summarizing them:
28352841 

build-with-claude/context-editing Changed · +11 / -8 lines

from line 46
4646<Tip>
4747 **Default behavior:** The default varies by model class.
4848 
49 | Model class | Keep all prior thinking | Keep only the last turn's thinking |
50 | ----------- | --------------------------- | ----------------------------------- |
51 | Opus | Claude Opus 4.5 and later | Claude Opus 4.1 and earlier |
52 | Sonnet | Claude Sonnet 4.6 and later | Claude Sonnet 4.5 and earlier |
53 | Haiku | (none) | All models through Claude Haiku 4.5 |
49 | Model class | Keep all prior thinking | Keep only the last turn's thinking |
50 | ---------------- | --------------------------- | ----------------------------------- |
51 | Opus | Claude Opus 4.5 and later | Claude Opus 4.1 and earlier |
52 | Sonnet | Claude Sonnet 4.6 and later | Claude Sonnet 4.5 and earlier |
53 | Haiku | (none) | All models through Claude Haiku 4.5 |
54 | Fable and Mythos | All models | (none) |
5455 
5556 Use this strategy to override the default. If your code runs across multiple model tiers, set `keep` explicitly rather than relying on the per-model default.
5657</Tip>
from line 62
6162 
6263Context editing is applied server-side before the prompt reaches Claude. Your client application maintains the full, unmodified conversation history. You do not need to sync your client state with the edited version. Continue managing your full conversation history locally as you normally would.
6364 
65On Claude Fable 5.1, server-side context management never invalidates thinking blocks. Client-side edits to earlier turns can invalidate the thinking blocks in every later assistant turn. For new accounts created on or after August 31, 2026, a request that replays an invalidated block is rejected unless you opt into dropping it. See [Preserved thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation).
66 
6467### Context editing and prompt caching
6568 
6669Context editing's interaction with [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) varies by strategy:
from line 921
918921 
919922The `clear_thinking_20251015` strategy supports the following configuration:
920923 
921| Configuration option | Default | Description |
922| -------------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
923| `keep` | Model-specific | Defines how many recent assistant turns with thinking blocks to preserve. Use `{type: "thinking_turns", value: N}` where N must be > 0 to keep the last N turns, or `"all"` to keep all thinking blocks. Opus 4.5+ and Sonnet 4.6+: all turns. Earlier Opus/Sonnet and all Haiku: last turn only. |
924| Configuration option | Default | Description |
925| -------------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
926| `keep` | Model-specific | Defines how many recent assistant turns with thinking blocks to preserve. Use `{type: "thinking_turns", value: N}` where N must be > 0 to keep the last N turns, or `"all"` to keep all thinking blocks. Opus 4.5+ and Sonnet 4.6+: all turns. Fable and Mythos models: all turns. Earlier Opus/Sonnet and all Haiku: last turn only. |
924927 
925928**Example configurations:**
926929 

build-with-claude/context-windows Changed · +4 / -6 lines

from line 33
3333 
3434## Context window sizes by model
3535 
36Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6 have a 1M-token context window on the Claude API, Amazon Bedrock, Google Cloud, and Microsoft Foundry. [Claude Mythos Preview](https://anthropic.com/glasswing) also has a 1M-token context window.
36Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, Claude Sonnet 4.6, and [Claude Mythos Preview](https://anthropic.com/glasswing) have a 1M-token context window. A single request to any of them can generate up to 128k output tokens (`max_tokens`). Other Claude models, including Claude Sonnet 4.5, have a 200k-token context window.
3737 
38Claude Fable 5 and Claude Mythos 5 (claude-fable-5 and claude-mythos-5) also have a 1M-token context window. A single request to any model with a 1M-token context window can generate up to 128k output tokens (`max_tokens`). Other Claude models, including Claude Sonnet 4.5, have a 200k-token context window.
39 
4038For every model with a 1M-token context window, 1M is the default: you don't need a beta header, and long-context requests are billed at [standard pricing](https://platform.claude.com/docs/en/about-claude/pricing#long-context-pricing).
4139 
4240A single request can include up to 600 images or PDF pages (100 for models with a 200k-token context window). If you send many images or large documents, you might reach [request size limits](https://platform.claude.com/docs/en/api/overview#request-size-limits) before the token limit.
from line 47
4947 
5048Thinking tokens are a subset of your `max_tokens` parameter, are billed as output tokens, and count toward rate limits. With [adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking), Claude determines its thinking allocation dynamically, so thinking token usage varies from request to request.
5149 
52Whether thinking blocks from previous assistant turns stay in the context window depends on the model. On Claude Opus 4.5 and later Opus models, Claude Sonnet 4.6 and later Sonnet models, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview, the API keeps previous thinking blocks by default, and they count toward the context window like any other input tokens. On earlier Opus and Sonnet models and all Haiku models, the API automatically strips previous thinking blocks from the conversation history when you pass them back, which preserves token capacity for conversation content. For the per-model defaults, see [thinking block preservation by model](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-block-preservation-by-model). To override the default in either direction, use [thinking block clearing](https://platform.claude.com/docs/en/build-with-claude/context-editing#thinking-block-clearing).
50Whether thinking blocks from previous assistant turns stay in the context window depends on the model. On Claude Opus 4.5 and later Opus models, Claude Sonnet 4.6 and later Sonnet models, Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview, the API keeps previous thinking blocks by default, and they count toward the context window like any other input tokens. On earlier Opus and Sonnet models and all Haiku models, the API automatically strips previous thinking blocks from the conversation history when you pass them back, which preserves token capacity for conversation content. For the per-model defaults, see [thinking block preservation by model](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-block-preservation-by-model). To override the default in either direction, use [thinking block clearing](https://platform.claude.com/docs/en/build-with-claude/context-editing#thinking-block-clearing).
5351 
5452The following diagram shows how tokens are managed when thinking is enabled on a model that strips previous thinking blocks:
5553 
from line 80
8280 </Step>
8381 
8482 <Step title="New user turn (turn 3)">
85 * **Input components:** All inputs and the output from the previous turn are carried forward. The thinking block from the completed tool use cycle no longer has to stay in context: on models that strip previous thinking blocks, the API drops it automatically when you pass it back, and on models that keep previous thinking blocks, you can strip it yourself at this stage. This is also where you add the next `user` turn.
83 * **Input components:** All inputs and the output from the previous turn are carried forward. The thinking block from the completed tool use cycle no longer has to stay in context: on models that strip previous thinking blocks, the API drops it automatically when you pass it back, and on models that keep previous thinking blocks, it stays unless you clear it with [thinking block clearing](https://platform.claude.com/docs/en/build-with-claude/context-editing#thinking-block-clearing). This is also where you add the next `user` turn.
8684 * **Output components:** Because there is a new `user` turn outside the tool use cycle, Claude generates a new thinking block and continues from there.
8785 * **Token calculation:** On models that strip previous thinking blocks, the previous thinking tokens no longer count toward the context window. All other previous blocks still count toward the context window, as does the thinking block in the current `assistant` turn.
8886 </Step>
from line 121
123121 
124122Image tokens are included in these budgets.
125123 
126Claude Opus 4.7 and later Opus models, Claude Fable 5, and Claude Mythos 5 don't receive these injected tags. On Claude Opus 4.7 and later Opus models, Claude Fable 5, and Claude Mythos 5, you can give the model an explicit budget with [task budgets](https://platform.claude.com/docs/en/build-with-claude/task-budgets), which are in beta.
124Claude Opus 4.7 and later Opus models, Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, and Claude Mythos 5 don't receive these injected tags. On these models, you can give the model an explicit budget with [task budgets](https://platform.claude.com/docs/en/build-with-claude/task-budgets), which are in beta.
127125 
128126<Tip>
129127 For agents that span multiple sessions, design your state artifacts so that context recovery is fast when a new session starts. The [memory tool's multisession pattern](https://platform.claude.com/docs/en/agents-and-tools/tool-use/memory-tool#multisession-software-development-pattern) walks through a concrete approach. See also [Effective harnesses for long-running agents](https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents).

build-with-claude/effort Changed · +399 / -115 lines

## Set the effort level ### Recommended effort levels for Claude Fable 5.1 ## Change effort mid-conversation ### Per-message effort (beta) ### Top-level effort on the next request ## Basic usage ## When to adjust the effort parameter ## Changing effort mid-conversation

The two sides of this change are more than 400 edits apart, too far apart to line up, so this is the differ's own diff of it and the words inside a line are not marked.

from line 6
66 
77## Compatibility
88- [ZDR](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention): eligible (excludes [Covered Models](https://platform.claude.com/docs/en/manage-claude/api-and-data-retention#model-specific-data-retention-requirements))
9- Supported models: `claude-fable-5`, `claude-mythos-5`, `claude-mythos-preview`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`, `claude-opus-4-6`, `claude-sonnet-5`, `claude-sonnet-4-6`, `claude-opus-4-5-20251101`
9- Supported models: `claude-fable-5-1`, `claude-mythos-5-1`, `claude-fable-5`, `claude-mythos-5`, `claude-mythos-preview`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`, `claude-opus-4-6`, `claude-opus-4-5-20251101`, `claude-sonnet-5`, `claude-sonnet-4-6`
1010- Platforms: Claude API, Claude Platform on AWS, Amazon Bedrock, Google Cloud, Microsoft Foundry
1111 
12The effort parameter lets you control how many tokens Claude spends when responding to requests. You can trade off between response thoroughness and token efficiency with a single model. The effort parameter is available on all supported models with no beta header required.
12The effort parameter lets you control how many tokens Claude spends when responding to requests. You can trade off between response thoroughness and token efficiency with a single model. The top-level effort parameter is available on all supported models with no beta header required. [Per-message effort](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) is in beta.
1313 
1414<Tip>
1515 To learn how effort interacts with thinking and which control to reach for, see [Thinking and effort](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-effort). Where adaptive thinking is available, effort is the recommended way to control thinking depth.
1616</Tip>
1717 
18## How effort works
19 
20By default, Claude uses high effort, spending as many tokens as needed for excellent results. You can raise the effort level to `max` for the absolute highest capability, or lower it to be more conservative with token usage, optimizing for speed and cost while accepting some reduction in capability.
21 
22<Tip>
23 Setting `effort` to `"high"` produces exactly the same behavior as omitting the `effort` parameter entirely.
24</Tip>
25 
26The effort parameter affects **all tokens** in the response, including:
27 
28* Text responses and explanations
29* Tool calls and function arguments
30* Thinking (when active)
31 
32This approach has two major advantages:
33 
341. It doesn't require thinking to be enabled.
352. It can affect all token spend including tool calls. For example, lower effort would mean Claude makes fewer tool calls. This gives a much greater degree of control over efficiency.
36 
37### Effort levels
38 
39| Level | Description | Typical use case |
40| -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------ |
41| `max` | Absolute maximum capability with no constraints on token spending. Available on Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Mythos Preview, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6. | Tasks requiring the deepest possible reasoning and most thorough analysis |
42| `xhigh` | Extended capability for long-horizon work. Available on Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, and Claude Sonnet 5. | Long-running agentic and coding tasks (over 30 minutes) with token budgets in the millions |
43| `high` | High capability. Equivalent to not setting the parameter. | Complex reasoning, difficult coding problems, agentic tasks |
44| `medium` | Balanced approach with moderate token savings. | Agentic tasks that require a balance of speed, cost, and performance |
45| `low` | Most efficient. Significant token savings with some capability reduction. | Simpler tasks that need the best speed and lowest costs, such as subagents |
46 
47`xhigh` is a newer level; some models that support `max` don't support `xhigh`.
48 
49<Note>
50 Effort is a behavioral signal, not a strict token budget. At lower effort levels, Claude will still think on sufficiently difficult problems, but it will think less than it would at higher effort levels for the same problem.
51</Note>
52 
53### Recommended effort levels for Claude Sonnet 5
54 
55Claude Sonnet 5 defaults to `high` effort on the Claude API and Claude Code.
56 
57* **High effort (default):** Suitable for complex reasoning, coding, and agentic tasks where quality matters more than speed or cost.
58* **Xhigh effort:** For the hardest coding and agentic tasks. See [Prompting Claude Sonnet 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-sonnet-5#calibrating-effort-and-thinking-depth).
59* **Medium effort:** Cost-saving step-down from the default. Comparable to Claude Sonnet 4.6 at high effort.
60* **Low effort:** For high-volume or latency-sensitive workloads. Suitable for chat and non-coding use cases where faster turnaround is prioritized.
61* **Max effort:** For tasks requiring the absolute highest capability with no constraints on token spending.
62 
63### Recommended effort levels for Claude Sonnet 4.6
64 
65Sonnet 4.6 defaults to `high` effort. Explicitly set effort when using Sonnet 4.6 to avoid unexpected latency:
66 
67* **Medium effort** (recommended default): Best balance of speed, cost, and performance for most applications. Suitable for agentic coding, tool-heavy workflows, and code generation.
68* **Low effort:** For high-volume or latency-sensitive workloads. Suitable for chat and non-coding use cases where faster turnaround is prioritized.
69* **High effort:** For complex reasoning and tasks where quality matters more than speed or cost.
70* **Max effort:** For tasks requiring the absolute highest capability with no constraints on token spending.
71 
72### Recommended effort levels for Claude Opus 4.7
73 
74**Start with `xhigh` for coding and agentic use cases**, and use `high` as the minimum for most intelligence-sensitive workloads. Step down to `medium` for cost-sensitive workloads, or up to `max` only when your evals show measurable headroom at `xhigh`.
75 
76The API default is `high`. To use `xhigh`, set `effort` explicitly; the value you pass overrides the default.
77 
78| Effort | Guidance for Claude Opus 4.7 |
79| -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
80| `low` | Efficient, but best for short, scoped tasks. Pair `low` with explicit checklists if your task has multiple sections. |
81| `medium` | The drop-in for the average workflow where you want good results while reducing costs. |
82| `high` | Advanced use cases that still need a balance of intelligence and token consumption. This is often the best balance of quality and token efficiency. |
83| `xhigh` | The recommended starting point for coding and agentic work, and for exploratory tasks such as repeated tool calling, detailed web search, and knowledge-base search. Expect meaningfully higher token usage than `high`. |
84| `max` | Reserve for genuinely frontier problems. On most workloads `max` adds significant cost for relatively small quality gains, and on some structured-output or less intelligence-sensitive tasks it can lead to overthinking. |
85 
86Claude Opus 4.7 also respects effort levels more strictly than Claude Opus 4.6, especially at `low` and `medium`. At lower effort levels, the model scopes its work to what was asked rather than doing more than requested. If you observe shallow reasoning on complex problems with Claude Opus 4.7, raise effort rather than prompting around it. If you must keep effort low for latency, add targeted guidance like "This task involves multistep reasoning. Think carefully before responding."
87 
88When running Claude Opus 4.7 at `xhigh` or `max` effort, set a large `max_tokens` so the model has room to think and act across subagents and tool calls. Starting at 64k tokens and tuning from there is a reasonable default.
89 
90### Recommended effort levels for Claude Opus 4.8
91 
92The guidance for Claude Opus 4.7 also applies to Claude Opus 4.8. **Start with `xhigh` for coding and agentic use cases**, use `high` for most other intelligence-sensitive workloads, and step down to `medium` or `low` only when you've measured that the lower level holds quality on your evals.
93 
94The API default is `high`. Set `effort` explicitly to use a different level; the value you pass overrides the default.
95 
96When running Claude Opus 4.8 at `xhigh` or `max` effort, set a large `max_tokens` so the model has room to think and act across subagents and tool calls. Starting at 64k tokens and tuning from there is a reasonable default.
97 
98### Recommended effort levels for Claude Opus 5
99 
100Claude Opus 5 supports all five effort levels. **Start with `high`, the default**, and adjust based on your evals: step up to `xhigh` for demanding coding and agentic work, or to `max` when a task justifies unconstrained token spending, and use `low` and `medium` liberally as your primary control for token cost and response time wherever your evals show quality holds. If you carried effort settings over from an earlier model, run a fresh effort sweep on your evals rather than reusing them.
101 
102Effort controls thinking volume, not visible response length: on Claude Opus 5, changing effort does not reliably shorten responses, so [prompt for length](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#response-length-and-verbosity) instead.
103 
104The API default is `high`. Set `effort` explicitly to use a different level; the value you pass overrides the default.
105 
106On Claude Opus 5, thinking cannot be disabled at `xhigh` or `max` effort: requests that set `thinking: {"type": "disabled"}` at those levels return a 400 error. See [Effort with thinking](https://platform.claude.com/docs/en/build-with-claude/effort#effort-with-thinking).
107 
108When running Claude Opus 5 at `xhigh` or `max` effort, set a large `max_tokens` so the model has room to think and act across subagents and tool calls. Starting at 64k tokens and tuning from there is a reasonable default.
109 
110### Recommended effort levels for Claude Fable 5
111 
112Effort is the primary control for trading off intelligence, latency, and cost on Claude Fable 5. **Start with `high`, the default, for most tasks**, use `xhigh` for the most capability-sensitive workloads, and step down to `medium` or `low` for routine work. Lower effort settings on Claude Fable 5 still perform well and often exceed `xhigh` performance on prior models. At `high` and `xhigh`, set a large `max_tokens`: it is a hard limit on total output, thinking plus response text. See [Cost control](https://platform.claude.com/docs/en/build-with-claude/thinking-steering-and-cost#cost-control).
113 
114Reduce effort if a task completes but takes longer than necessary, or if you want a faster, more interactive working style. The same recommendations apply to Claude Mythos 5. For fuller guidance, see [Prompting Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5).
115 
116## Basic usage
18## Set the effort level
19 
20Set `output_config.effort` on the request. The following example runs one request at `medium` effort and prints the response text.
11721 
11822<CodeGroup>
11923 ```bash cURL
from line 198
294198 ```
295199</CodeGroup>
296200 
297## When to adjust the effort parameter
298 
299* Use **max effort** when you need the absolute highest capability with no constraints: the most thorough reasoning and deepest analysis. Available on Claude 4.6 and later models and Claude Mythos Preview.
300* Use **xhigh effort** for advanced coding and complex agentic work requiring extended exploration, such as repeated tool calling and detailed search. Available on Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, and Claude Sonnet 5.
301* Use **high effort** (the default) for complex reasoning, nuanced analysis, difficult coding problems, or any task where quality matters more than speed or cost.
302* Use **medium effort** as a balanced option when you want solid performance without the full token expenditure of high effort.
303* Use **low effort** when you're optimizing for speed (because Claude answers with fewer tokens) or cost. For example, simple classification tasks, quick lookups, or high-volume use cases where marginal quality improvements don't justify additional latency or spend.
201## How effort works
202 
203By default, Claude uses high effort, spending as many tokens as needed for excellent results. You can raise the effort level to `max` for the absolute highest capability, or lower it to be more conservative with token usage, optimizing for speed and cost while accepting some reduction in capability.
204 
205<Tip>
206 Setting `effort` to `"high"` produces exactly the same behavior as omitting the `effort` parameter entirely.
207</Tip>
208 
209The effort parameter affects **all tokens** in the response, including:
210 
211* Text responses and explanations
212* Tool calls and function arguments
213* Thinking (when active)
214 
215Because effort applies to every output token, it works whether or not thinking is enabled. Lower effort also means fewer and terser tool calls.
216 
217### Effort levels
218 
219| Level | Description | Typical use case |
220| -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------ |
221| `max` | Absolute maximum capability with no constraints on token spending. Available on Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Mythos Preview, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, and Claude Sonnet 4.6. | Tasks requiring the deepest possible reasoning and most thorough analysis |
222| `xhigh` | Extended capability for long-horizon work. Available on Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, and Claude Sonnet 5. | Long-running agentic and coding tasks (over 30 minutes) with token budgets in the millions |
223| `high` | High capability. Equivalent to not setting the parameter. | Complex reasoning, difficult coding problems, agentic tasks |
224| `medium` | Balanced approach with moderate token savings. | Agentic tasks that require a balance of speed, cost, and performance |
225| `low` | Most efficient. Significant token savings with some capability reduction. | Simpler tasks that need the best speed and lowest costs, such as subagents |
226 
227Not every model that supports `max` supports `xhigh`.
228 
229<Note>
230 Effort is a behavioral signal, not a strict token budget. At lower effort levels, Claude still thinks on sufficiently difficult problems, but thinks less than it would at higher effort levels for the same problem.
231</Note>
232 
233The per-model recommendations that follow override this table where they differ.
234 
235### Recommended effort levels for Claude Fable 5.1
236 
237Claude Fable 5.1 supports all five effort levels. **Start with `high`, the default.** Step up to `xhigh` or `max` for the most capability-sensitive agentic and coding work, and step down to `medium` or `low` for routine or latency-sensitive work once your evals show quality holds. At `high` and above, set a large `max_tokens`. It's a hard limit on total output (thinking plus response text). The same recommendations apply to Claude Mythos 5.1. See [Prompting Claude Fable 5.1](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#consider-all-effort-levels).
238 
239Claude Fable 5.1 also supports [changing effort mid-conversation](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) with a per-message `output_config`, which preserves the prompt cache.
240 
241### Recommended effort levels for Claude Fable 5
242 
243Effort is the primary control for trading off intelligence, latency, and cost on Claude Fable 5. **Start with `high`, the default, for most tasks**, use `xhigh` for the most capability-sensitive workloads, and step down to `medium` or `low` for routine work. Lower effort settings on Claude Fable 5 still perform well and often exceed `xhigh` performance on prior models. At `high` and `xhigh`, set a large `max_tokens`. It's a hard limit on total output (thinking plus response text). See [Cost control](https://platform.claude.com/docs/en/build-with-claude/thinking-steering-and-cost#cost-control).
244 
245Reduce effort if a task completes but takes longer than necessary, or if you want a faster, more interactive working style. The same recommendations apply to Claude Mythos 5. For fuller guidance, see [Prompting Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5).
246 
247### Recommended effort levels for Claude Opus 5
248 
249Claude Opus 5 supports all five effort levels. **Start with `high`, the default**, and adjust based on your evals: step up to `xhigh` for demanding coding and agentic work, or to `max` when a task justifies unconstrained token spending, and use `low` and `medium` liberally as your primary control for token cost and response time wherever your evals show quality holds. If you carried effort settings over from an earlier model, run a fresh effort sweep on your evals rather than reusing them.
250 
251Effort controls thinking volume, not visible response length: on Claude Opus 5, changing effort does not reliably shorten responses, so [prompt for length](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#response-length-and-verbosity) instead.
252 
253The API default is `high`. Set `effort` explicitly to use a different level. The value you pass overrides the default.
254 
255On Claude Opus 5, thinking cannot be disabled at `xhigh` or `max` effort: requests that set `thinking: {"type": "disabled"}` at those levels return a 400 error. See [Effort with thinking](https://platform.claude.com/docs/en/build-with-claude/effort#effort-with-thinking).
256 
257When running Claude Opus 5 at `xhigh` or `max` effort, set a large `max_tokens` so the model has room to think and act across subagents and tool calls. Starting at 64k tokens and tuning from there is a reasonable default.
258 
259Claude Opus 5 also supports [changing effort mid-conversation](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) with a per-message `output_config`, which preserves the prompt cache.
260 
261### Recommended effort levels for Claude Opus 4.8
262 
263The guidance for Claude Opus 4.7 also applies to Claude Opus 4.8. **Start with `xhigh` for coding and agentic use cases**, use `high` for most other intelligence-sensitive workloads, and step down to `medium` or `low` only when you've measured that the lower level holds quality on your evals.
264 
265The API default is `high`. Set `effort` explicitly to use a different level. The value you pass overrides the default.
266 
267When running Claude Opus 4.8 at `xhigh` or `max` effort, set a large `max_tokens` so the model has room to think and act across subagents and tool calls. Starting at 64k tokens and tuning from there is a reasonable default.
268 
269### Recommended effort levels for Claude Opus 4.7
270 
271**Start with `xhigh` for coding and agentic use cases**, and use `high` as the minimum for most intelligence-sensitive workloads. Step down to `medium` for cost-sensitive workloads, or up to `max` only when your evals show measurable headroom at `xhigh`.
272 
273The API default is `high`. To use `xhigh`, set `effort` explicitly. The value you pass overrides the default.
274 
275| Effort | Guidance for Claude Opus 4.7 |
276| -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
277| `low` | Efficient, but best for short, scoped tasks. Pair `low` with explicit checklists if your task has multiple sections. |
278| `medium` | The drop-in for the average workflow where you want good results while reducing costs. |
279| `high` | Advanced use cases that still need a balance of intelligence and token consumption. This is often the best balance of quality and token efficiency. |
280| `xhigh` | The recommended starting point for coding and agentic work, and for exploratory tasks such as repeated tool calling, detailed web search, and knowledge-base search. Expect meaningfully higher token usage than `high`. |
281| `max` | Reserve for frontier problems. On most workloads `max` adds significant cost for relatively small quality gains, and on some structured-output or less intelligence-sensitive tasks it can lead to overthinking. |
282 
283Claude Opus 4.7 also respects effort levels more strictly than Claude Opus 4.6, especially at `low` and `medium`. At lower effort levels, the model scopes its work to what was asked rather than doing more than requested. If you observe shallow reasoning on complex problems with Claude Opus 4.7, raise effort rather than prompting around it. If you must keep effort low for latency, add targeted guidance like "This task involves multistep reasoning. Think carefully before responding."
284 
285When running Claude Opus 4.7 at `xhigh` or `max` effort, set a large `max_tokens` so the model has room to think and act across subagents and tool calls. Starting at 64k tokens and tuning from there is a reasonable default.
286 
287### Recommended effort levels for Claude Sonnet 5
288 
289Claude Sonnet 5 defaults to `high` effort on the Claude API and Claude Code.
290 
291* **High effort (default):** Suitable for complex reasoning, coding, and agentic tasks where quality matters more than speed or cost.
292* **Xhigh effort:** For the hardest coding and agentic tasks. See [Prompting Claude Sonnet 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-sonnet-5#calibrating-effort-and-thinking-depth).
293* **Medium effort:** Cost-saving step-down from the default. Comparable to Claude Sonnet 4.6 at high effort.
294* **Low effort:** For high-volume or latency-sensitive workloads. Suitable for chat and non-coding use cases where faster turnaround is prioritized.
295* **Max effort:** For tasks requiring the absolute highest capability with no constraints on token spending.
296 
297### Recommended effort levels for Claude Sonnet 4.6
298 
299Sonnet 4.6 defaults to `high` effort. Explicitly set effort when using Sonnet 4.6 to avoid unexpected latency:
300 
301* **Medium effort** (recommended default): Best balance of speed, cost, and performance for most applications. Suitable for agentic coding, tool-heavy workflows, and code generation.
302* **Low effort:** For high-volume or latency-sensitive workloads. Suitable for chat and non-coding use cases where faster turnaround is prioritized.
303* **High effort:** For complex reasoning and tasks where quality matters more than speed or cost.
304* **Max effort:** For tasks requiring the absolute highest capability with no constraints on token spending.
304305 
305306## Effort with tool use
306307 
from line 323
322323 
323324The `thinking` parameter controls whether Claude thinks in [thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking) before answering; the `effort` parameter controls how much work Claude puts into the whole response, which in adaptive mode includes how often and how deeply it thinks. Don't pass `adaptive` as an `effort` value: `adaptive` is a thinking mode, not an effort level.
324325 
325At higher effort levels, Claude thinks on most requests and at greater length; at lower levels, it can skip thinking entirely for simpler problems. See [Thinking and effort](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-effort) for full guidance on how the two controls work together.
326At higher effort levels, Claude thinks on most requests and at greater length. At lower levels, it can skip thinking entirely for simpler problems. See [Thinking and effort](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-effort) for full guidance on how the two controls work together.
326327 
327328On Claude Opus 4.5, the only extended-thinking-only model that supports effort, it works alongside [`budget_tokens`](https://platform.claude.com/docs/en/build-with-claude/extended-thinking): set the effort level for your task, then set the thinking token budget based on how much reasoning depth the task needs.
328329 
329For per-model thinking availability, see the [per-model configuration table](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#supported-models). Effort works with or without thinking; see [How effort works](https://platform.claude.com/docs/en/build-with-claude/effort#how-effort-works).
330 
331## Changing effort mid-conversation
332 
333`output_config.effort` is a request-level setting: each request carries its own value, so to run a later part of a conversation at a different effort level, set the new value on the next request. The effort level applies to the whole request. Because effort shapes the rendered prompt, changing it between requests does not preserve cached prefixes from earlier turns; if you rely on [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) across a long session, pick an effort level at the start and keep it constant.
330For per-model thinking availability, see the [per-model configuration table](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#supported-models). Effort works with or without thinking. See [How effort works](https://platform.claude.com/docs/en/build-with-claude/effort#how-effort-works).
331 
332## Change effort mid-conversation
333 
334You can run later turns of a conversation at a different effort level in two ways. On Claude Fable 5.1, Claude Mythos 5.1, and Claude Opus 5, use a per-message effort change, which keeps the prompt cache. On other models, set a new top-level value on the next request, which starts the cache over.
335 
336### Per-message effort (beta)
337 
338Per-message effort is in beta and requires the [beta header](https://platform.claude.com/docs/en/api/beta-headers) `mid-conversation-output-config-2026-07-01`. Models without per-message effort, including Claude Fable 5, return a 400 error: `output_config.effort requires a model that supports per-turn effort; this model does not`.
339 
340Add a `role: "system"` message with empty `content` and the new level in `output_config.effort`. The new level takes effect from the next `user` turn and holds until a later message changes it. Everything before that message is unchanged, so the cached prefix still matches.
341 
342The following example starts at `high`, then drops to `low` for a routine follow-up:
343 
344<CodeGroup>
345 ```bash cURL
346 # Effort-only system message: the new level takes effect from the next user turn.
347 curl https://api.anthropic.com/v1/messages \
348 -H "x-api-key: $ANTHROPIC_API_KEY" \
349 -H "anthropic-version: 2023-06-01" \
350 -H "anthropic-beta: mid-conversation-output-config-2026-07-01" \
351 -H "content-type: application/json" \
352 -d '{
353 "model": "claude-fable-5-1",
354 "max_tokens": 4096,
355 "output_config": {"effort": "high"},
356 "messages": [
357 {"role": "user", "content": "Plan a migration from SQLite to PostgreSQL in three short steps."},
358 {"role": "assistant", "content": "1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts."},
359 {"role": "system", "content": [], "output_config": {"effort": "low"}},
360 {"role": "user", "content": "Summarize the plan in one sentence."}
361 ]
362 }'
363 ```
364 
365 ```bash CLI
366 ant beta:messages create --beta mid-conversation-output-config-2026-07-01 \
367 --transform 'content.#(type=="text").text' --raw-output <<'YAML'
368 model: claude-fable-5-1
369 max_tokens: 4096
370 output_config:
371 effort: high
372 messages:
373 - role: user
374 content: Plan a migration from SQLite to PostgreSQL in three short steps.
375 - role: assistant
376 content: "1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts."
377 # Effort-only system message: the new level takes effect from the next user turn.
378 - role: system
379 content: []
380 output_config:
381 effort: low
382 - role: user
383 content: Summarize the plan in one sentence.
384 YAML
385 ```
386 
387 ```python Python
388 client = anthropic.Anthropic()
389 
390 response = client.beta.messages.create(
391 model="claude-fable-5-1",
392 max_tokens=4096,
393 output_config={"effort": "high"},
394 messages=[
395 {
396 "role": "user",
397 "content": "Plan a migration from SQLite to PostgreSQL in three short steps.",
398 },
399 {
400 "role": "assistant",
401 "content": "1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts.",
402 },
403 # Effort-only system message: the new level takes effect from the next user turn.
404 {"role": "system", "content": [], "output_config": {"effort": "low"}},
405 {"role": "user", "content": "Summarize the plan in one sentence."},
406 ],
407 betas=["mid-conversation-output-config-2026-07-01"],
408 )
409 
410 for block in response.content:
411 if block.type == "text":
412 print(block.text)
413 ```
414 
415 ```typescript TypeScript
416 const client = new Anthropic();
417 
418 const response = await client.beta.messages.create({
419 model: "claude-fable-5-1",
420 max_tokens: 4096,
421 output_config: { effort: "high" },
422 messages: [
423 {
424 role: "user",
425 content: "Plan a migration from SQLite to PostgreSQL in three short steps."
426 },
427 {
428 role: "assistant",
429 content:
430 "1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts."
431 },
432 // Effort-only system message: the new level takes effect from the next user turn.
433 { role: "system", content: [], output_config: { effort: "low" } },
434 { role: "user", content: "Summarize the plan in one sentence." }
435 ],
436 betas: ["mid-conversation-output-config-2026-07-01"]
437 });
438 
439 for (const block of response.content) {
440 if (block.type === "text") {
441 console.log(block.text);
442 }
443 }
444 ```
445 
446 ```csharp C#
447 using Anthropic.Models.Beta;
448 using Anthropic.Models.Beta.Messages;
449 
450 AnthropicClient client = new();
451 
452 var response = await client.Beta.Messages.Create(new MessageCreateParams
453 {
454 Model = "claude-fable-5-1",
455 MaxTokens = 4096,
456 OutputConfig = new() { Effort = Effort.High },
457 Messages =
458 [
459 new() { Role = Role.User, Content = "Plan a migration from SQLite to PostgreSQL in three short steps." },
460 new() { Role = Role.Assistant, Content = "1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts." },
461 // Effort-only system message: the new level takes effect from the next user turn.
462 new()
463 {
464 Role = Role.System,
465 Content = new([]),
466 OutputConfig = new() { Effort = BetaSystemMessageOutputConfigEffort.Low },
467 },
468 new() { Role = Role.User, Content = "Summarize the plan in one sentence." },
469 ],
470 Betas = [AnthropicBeta.MidConversationOutputConfig2026_07_01],
471 });
472 
473 foreach (var block in response.Content)
474 {
475 if (block.TryPickText(out var textBlock))
476 {
477 Console.WriteLine(textBlock.Text);
478 }
479 }
480 ```
481 
482 ```go Go
483 client := anthropic.NewClient()
484 
485 response, err := client.Beta.Messages.New(context.Background(), anthropic.BetaMessageNewParams{
486 Model: "claude-fable-5-1",
487 MaxTokens: 4096,
488 OutputConfig: anthropic.BetaOutputConfigParam{
489 Effort: anthropic.BetaOutputConfigEffortHigh,
490 },
491 Messages: []anthropic.BetaMessageParam{
492 anthropic.NewBetaUserMessage(anthropic.NewBetaTextBlock("Plan a migration from SQLite to PostgreSQL in three short steps.")),
493 {
494 Role: anthropic.BetaMessageParamRoleAssistant,
495 Content: []anthropic.BetaContentBlockParamUnion{anthropic.NewBetaTextBlock("1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts.")},
496 },
497 // Effort-only system message: the new level takes effect from the next user turn.
498 anthropic.NewBetaSystemMessage(anthropic.BetaSystemMessageOutputConfigParam{
499 Effort: anthropic.BetaSystemMessageOutputConfigEffortLow,
500 }),
501 anthropic.NewBetaUserMessage(anthropic.NewBetaTextBlock("Summarize the plan in one sentence.")),
502 },
503 Betas: []anthropic.AnthropicBeta{anthropic.AnthropicBetaMidConversationOutputConfig2026_07_01},
504 })
505 if err != nil {
506 log.Fatal(err)
507 }
508 
509 for _, block := range response.Content {
510 if textBlock, ok := block.AsAny().(anthropic.BetaTextBlock); ok {
511 fmt.Println(textBlock.Text)
512 }
513 }
514 ```
515 
516 ```java Java
517 import com.anthropic.models.beta.AnthropicBeta;
518 import com.anthropic.models.beta.messages.BetaMessage;
519 import com.anthropic.models.beta.messages.BetaMessageParam;
520 import com.anthropic.models.beta.messages.BetaOutputConfig;
521 import com.anthropic.models.beta.messages.BetaSystemMessageOutputConfig;
522 import com.anthropic.models.beta.messages.MessageCreateParams;
523 
524 void main() {
525 AnthropicClient client = AnthropicOkHttpClient.fromEnv();
526 
527 MessageCreateParams params = MessageCreateParams.builder()
528 .model("claude-fable-5-1")
529 .maxTokens(4096L)
530 .addBeta(AnthropicBeta.MID_CONVERSATION_OUTPUT_CONFIG_2026_07_01)
531 .outputConfig(BetaOutputConfig.builder()
532 .effort(BetaOutputConfig.Effort.HIGH)
533 .build())
534 .addUserMessage("Plan a migration from SQLite to PostgreSQL in three short steps.")
535 .addAssistantMessage("1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts.")
536 // Effort-only system message: the new level takes effect from the next user turn.
537 .addMessage(BetaMessageParam.builder()
538 .role(BetaMessageParam.Role.SYSTEM)
539 .contentOfBetaContentBlockParams(List.of())
540 .outputConfig(BetaSystemMessageOutputConfig.builder()
541 .effort(BetaSystemMessageOutputConfig.Effort.LOW)
542 .build())
543 .build())
544 .addUserMessage("Summarize the plan in one sentence.")
545 .build();
546 
547 BetaMessage response = client.beta().messages().create(params);
548 response.content().stream()
549 .flatMap(block -> block.text().stream())
550 .forEach(textBlock -> IO.println(textBlock.text()));
551 }
552 ```
553 
554 ```php PHP
555 use Anthropic\Beta\AnthropicBeta;
556 use Anthropic\Beta\Messages\BetaMessageParam;
557 use Anthropic\Beta\Messages\BetaOutputConfig;
558 use Anthropic\Beta\Messages\BetaSystemMessageOutputConfig;
559 use Anthropic\Client;
560 
561 $client = new Client();
562 
563 $response = $client->beta->messages->create(
564 model: 'claude-fable-5-1',
565 maxTokens: 4096,
566 outputConfig: BetaOutputConfig::with(effort: 'high'),
567 messages: [
568 BetaMessageParam::with(role: 'user', content: 'Plan a migration from SQLite to PostgreSQL in three short steps.'),
569 BetaMessageParam::with(role: 'assistant', content: '1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts.'),
570 // Effort-only system message: the new level takes effect from the next user turn.
571 BetaMessageParam::with(
572 role: 'system',
573 content: [],
574 outputConfig: BetaSystemMessageOutputConfig::with(effort: 'low'),
575 ),
576 BetaMessageParam::with(role: 'user', content: 'Summarize the plan in one sentence.'),
577 ],
578 betas: [AnthropicBeta::MID_CONVERSATION_OUTPUT_CONFIG_2026_07_01],
579 );
580 
581 foreach ($response->content as $block) {
582 if ($block->type === 'text') {
583 echo $block->text, PHP_EOL;
584 }
585 }
586 ```
587 
588 ```ruby Ruby
589 client = Anthropic::Client.new
590 
591 response = client.beta.messages.create(
592 model: "claude-fable-5-1",
593 max_tokens: 4096,
594 output_config: {effort: :high},
595 messages: [
596 {role: "user", content: "Plan a migration from SQLite to PostgreSQL in three short steps."},
597 {role: "assistant", content: "1. Export the SQLite data. 2. Create the PostgreSQL schema. 3. Import the data and verify row counts."},
598 # Effort-only system message: the new level takes effect from the next user turn.
599 {role: "system", content: [], output_config: {effort: :low}},
600 {role: "user", content: "Summarize the plan in one sentence."}
601 ],
602 betas: [Anthropic::AnthropicBeta::MID_CONVERSATION_OUTPUT_CONFIG_2026_07_01]
603 )
604 
605 response.content.each do |block|
606 puts block.text if block.type == :text
607 end
608 ```
609</CodeGroup>
610 
611An effort-only system message carries no text, so the [placement rules for mid-conversation system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#limitations) don't apply. It can appear anywhere in `messages`, including as the first entry or between an `assistant` turn and the next `user` turn. Values are the level names (`low`, `medium`, `high`, `xhigh`, and `max`).
612 
613On Claude Fable 5.1, prefer this form over changing the top-level value between requests. A top-level change restarts the cache and also steers the model less reliably: its earlier replies were written at the previous level, and it tends to stay consistent with them.
614 
615### Top-level effort on the next request
616 
617The top-level `output_config.effort` applies to the whole request. To run a later part of a conversation at a different level, set the new value on the next request. Because top-level effort shapes the rendered prompt, changing it between requests doesn't preserve cached prefixes from earlier turns. If you rely on [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) across a long session and your model doesn't support per-message effort, pick an effort level at the start and keep it constant.
334618 
335619## Best practices
336620 
from line 622
3386222. **Use low for speed-sensitive or simple tasks:** When latency matters or tasks are straightforward, low effort can significantly reduce response times and costs.
3396233. **Test your use case:** The impact of effort levels varies by task type. Evaluate performance on your specific use cases before deploying.
3406244. **Consider dynamic effort:** Adjust effort based on task complexity. Simple queries may warrant low effort while agentic coding and complex reasoning benefit from high effort. See the next item before varying it within one conversation.
3415. **Hold effort constant within cached conversations:** Changing the effort value between requests invalidates [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching), so vary effort across workloads rather than within a conversation that relies on cache hits. See [Thinking and prompt caching](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-prompt-caching).
6255. **Hold top-level effort constant within cached conversations:** Changing the top-level effort value between requests invalidates [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching), so vary it across workloads rather than within a conversation that relies on cache hits. On models that support it, use a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) instead, which preserves the cache. See [Thinking and prompt caching](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-prompt-caching).
342626 
343627## Next steps
344628 
345629 

build-with-claude/fallback-credit Changed · +7 / -7 lines

from line 1
11---
22title: Fallback credit
33url: https://platform.claude.com/docs/en/build-with-claude/fallback-credit
4description: Avoid paying the prompt-cache cost twice when you retry a refused Claude Fable 5 request on another model.
4description: Avoid paying the prompt-cache cost twice when you retry a refused request on another model.
55---
66 
7Prompt caches are per-model. When Claude Fable 5 declines a request and you retry on another model, the conversation prefix that was already cached for Claude Fable 5 must be written into the new model's cache from scratch. Cache writes cost more than cache reads. Fallback credit removes that extra cost. The refusal carries a credit token, you echo the token on the retry, and the retry is billed as though the conversation had been on the new model all along.
7Prompt caches are per-model. When a model declines a request and you retry on another model, the conversation prefix already cached for the first model must be written into the new model's cache from scratch. Cache writes cost more than cache reads. Fallback credit removes that extra cost. The refusal carries a credit token, you echo the token on the retry, and the retry is billed as though the conversation had been on the new model all along.
88 
99You need this page only when you build the retry yourself: over raw HTTP or with custom retry logic. [Server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback) and the [SDK middleware](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#client-side-fallback) apply fallback credit automatically. If you use either, skip this page.
1010 
from line 27
2727 </Step>
2828 
2929 <Step title="Build the retry">
30 Start from the refused request body. Set `model` to the fallback model and add the token as the top-level `fallback_credit_token` parameter. Pick the body shape from the table below.
30 Start from the refused request body. Set `model` to the fallback model and add the token as the top-level `fallback_credit_token` parameter. Pick the body shape from the following table.
3131 </Step>
3232 
3333 <Step title="Send the retry with the same header">
from line 564
564564 
565565Fallback credit is in beta on the Claude API, Amazon Bedrock, Claude Platform on AWS, Google Cloud, and Microsoft Foundry. Refusals in [Message Batches](https://platform.claude.com/docs/en/build-with-claude/batch-processing) don't mint credit tokens, and redemption applies only to direct Messages API requests: a token passed on a batch request is accepted but ignored.
566566 
567The retry model must be one of the refused model's permitted fallback targets. Claude Fable 5's permitted targets are Claude Opus 4.8 (`claude-opus-4-8`) and Claude Opus 5 (`claude-opus-5`).
567The retry model must be one of the refused model's permitted fallback targets. For Claude Fable 5.1 and Claude Fable 5, those are Claude Opus 4.8 (`claude-opus-4-8`) and Claude Opus 5 (`claude-opus-5`).
568568 
569569<Accordion title="Looking up permitted fallback targets programmatically">
570570 On the Claude API and Claude Platform on AWS, the target list is published as `allowed_fallback_models` on each model's entry in the [Models API](https://platform.claude.com/docs/en/api/models/list) when the `server-side-fallback-2026-07-01` beta header is set. The list is not yet visible under the `fallback-credit-*` header alone. It is not exposed on Amazon Bedrock, Google Cloud, or Microsoft Foundry.
from line 598
598598 
599599## Reference
600600 
601The sections below cover edge cases and the complete redemption rules. Most integrations do not need them.
601The following sections cover edge cases and the complete redemption rules. Most integrations do not need them.
602602 
603603<Accordion title="Fields that must match the refused request">
604604 Redemption compares the retry against the refused request. Every field that shapes the prompt must match exactly. Fields that do not shape the prompt may change on the retry.
from line 622
622622 * **`fallback-credit-*`:** keep this header on both requests. The retry needs it to redeem the token.
623623 
624624 <Note>
625 On models that include the 1M token context window by default, such as Claude Fable 5, Claude Opus 5, and Claude Opus 4.8, the `context-1m-2025-08-07` beta header has no effect. The most robust way to keep the two requests identical is to omit that header on both, rather than sending it on one request and not the other.
625 On models that include the 1M token context window by default, such as Claude Fable 5.1, Claude Fable 5, Claude Opus 5, and Claude Opus 4.8, the `context-1m-2025-08-07` beta header has no effect. To keep the two requests identical, omit that header on both rather than sending it on one and not the other.
626626 </Note>
627627</Accordion>
628628 
629629<Accordion title="When fallback_has_prefill_claim is absent">
630 The field is `null` only when the token is also `null`, so a value you observe while holding a token is never `null`. It can still surface as absent (`None` in the typed SDKs) on Amazon Bedrock, Google Cloud, and Microsoft Foundry while their support for the field rolls out. In that case, treat the retry shape as unknown rather than as `false`. Try the appended-assistant-message shape first, and rely on the rejection handling in [When a retry is rejected](https://platform.claude.com/docs/en/build-with-claude/fallback-credit#when-a-retry-is-rejected), which falls back to the unchanged body.
630 The field is `null` only when the token is also `null`, so a value you observe while holding a token is never `null`. It can still be absent (`None` in the typed SDKs) on Amazon Bedrock, Google Cloud, and Microsoft Foundry while their support for the field rolls out. In that case, treat the retry shape as unknown rather than as `false`. Try the appended-assistant-message shape first, and rely on the rejection handling in [When a retry is rejected](https://platform.claude.com/docs/en/build-with-claude/fallback-credit#when-a-retry-is-rejected), which falls back to the unchanged body.
631631</Accordion>
632632 
633633<Accordion title="Echoing the refused response's content">

build-with-claude/mid-conversation-system-messages Changed · +357 / -11 lines

### Turn-scoped system messages

from line 12
1212 
1313Mid-conversation system messages close that gap. You append a `{"role": "system"}` message at the point in the conversation where the new instruction becomes relevant, instead of editing the top-level `system` field. The cached prefix stays the same, so the next request still reads it from cache, and the new instruction is still applied as a system instruction rather than as ordinary user text.
1414 
15This page covers two features: mid-conversation system messages, and [mid-conversation tool changes](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#mid-conversation-tool-changes), a beta introduced with Claude Opus 5 that applies the same approach to the `tools` array.
16 
1715<Note>
1816 Mid-conversation system messages are available on the Claude API, [Claude in Amazon Bedrock](https://platform.claude.com/docs/en/build-with-claude/claude-in-amazon-bedrock), and [Google Cloud](https://platform.claude.com/docs/en/build-with-claude/claude-on-vertex-ai).
1917 
20 This feature is available on Claude Fable 5, [Claude Mythos 5](https://anthropic.com/glasswing), Claude Opus 4.8, and Claude Opus 5. No beta header is required for mid-conversation system messages. This feature is not available on Claude Sonnet 5; use the top-level `system` field instead.
18 This feature is available on Claude Fable 5.1, [Claude Mythos 5.1](https://anthropic.com/glasswing), Claude Fable 5, [Claude Mythos 5](https://anthropic.com/glasswing), Claude Opus 4.8, and Claude Opus 5. No beta header is required for mid-conversation system messages. This feature is not available on Claude Sonnet 5. Use the top-level `system` field there instead.
2119 
22 Mid-conversation tool changes are in beta and require the `mid-conversation-tool-changes-2026-07-01` beta header. They are available on Claude Fable 5, Claude Mythos 5, Claude Opus 4.8, and Claude Opus 5, on the Claude API, Amazon Bedrock, and Google Cloud. They are not available on Claude Sonnet 5.
20 [Mid-conversation tool changes](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#mid-conversation-tool-changes) are in beta and require the `mid-conversation-tool-changes-2026-07-01` beta header. They are available on the same models, on the Claude API, Amazon Bedrock, and Google Cloud.
21 
22 [Turn-scoped system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#turn-scoped-system-messages) (`clear_at`) are in beta and require the `mid-conversation-system-clear-at-2026-08-21` beta header, on the same models and platforms as mid-conversation system messages.
2323</Note>
2424 
2525## Mid-conversation tool changes
2626 
27The `tools` array sits even earlier in the hashed request prefix than the top-level `system` field, so editing it invalidates the [prompt cache](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) for the entire conversation. Mid-conversation tool changes, a beta introduced with Claude Opus 5, are the tools counterpart to mid-conversation system messages. Instead of fixing the tool list for the lifetime of the conversation, you change which tools are offered to the model between turns: declare the full tool set in `tools` up front, then use `tool_addition` and `tool_removal` blocks to offer a tool to the model, or withdraw it, from a specific point in the conversation onward. The `tools` array itself never changes, so the cached prefix stays intact.
27The `tools` array sits even earlier in the hashed request prefix than the top-level `system` field, so editing it invalidates the [prompt cache](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) for the entire conversation. Mid-conversation tool changes are the tools counterpart to mid-conversation system messages. Instead of fixing the tool list for the lifetime of the conversation, you change which tools are offered to the model between turns: declare the full tool set in `tools` up front, then use `tool_addition` and `tool_removal` blocks to offer a tool to the model, or withdraw it, from a specific point in the conversation onward. The `tools` array itself never changes, so the cached prefix stays intact.
2828 
2929`tool_addition` and `tool_removal` are content blocks in the `content` array of a `role: "system"` message, and they can be mixed with `text` blocks in the same message. The message follows the same placement rules as any mid-conversation system message (see [Limitations](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#limitations)), and the change applies from that point in the conversation onward. Each block's `tool` field references a tool rather than defining one: `{"type": "tool_reference", "name": "..."}` names a tool declared in the request's `tools` array, and [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector) tools can be referenced individually with `mcp_tool_reference` (`server_name` and `name`) or as a whole toolset with `mcp_toolset_reference` (`server_name`). Referencing a name that is not declared in `tools` returns a 400 error.
3030 
from line 446
446446 ```
447447</CodeGroup>
448448 
449Mid-conversation tool changes are in beta. To use them, include the beta header `mid-conversation-tool-changes-2026-07-01` in your requests. They are available on Claude Fable 5, Claude Mythos 5, Claude Opus 4.8, and Claude Opus 5, on the Claude API, Amazon Bedrock, and Google Cloud.
449Mid-conversation tool changes are in beta. To use them, include the beta header `mid-conversation-tool-changes-2026-07-01` in your requests.
450450 
451451## When to use a mid-conversation system message
452452 
from line 460
460460 
461461* **Mid-session policy or persona changes.** A long agentic session needs a new constraint ("from now on, write all SQL as parameterized queries") after dozens of cached turns. Adding it to the top-level `system` field would re-process the entire history.
462462* **Per-turn context that must be authoritative.** You want to inject a freshness note, a session deadline, or a tool-availability change with system-level weight, and it changes too often to live in the cached prefix.
463* **Per-turn reminders that shouldn't pile up.** A harness nudges the model after each batch of tool results ("request independent reads together", "the user hasn't heard from you in a while") and wants the model to see only the newest copy. A [turn-scoped system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#turn-scoped-system-messages) renders for one turn and then costs nothing, without deleting anything from the history.
463464* **State changes your application observes.** Your application notices something Claude should treat as an operator-level fact: files changed on disk, the user toggled an auto-approve setting, available tools changed, or the remaining token budget dropped below a threshold.
464* **User input that should not interrupt an agentic loop.** A user types a follow-up while Claude is still executing tools for the previous request. Relaying it as a system message after the next tool result lets Claude fold the new input into the work it is already doing, instead of treating it as a fresh request to switch to. See [Placement after tool results](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#placement-after-tool-results) below.
465* **User input that should not interrupt an agentic loop.** A user types a follow-up while Claude is still executing tools for the previous request. Relaying it as a system message after the next tool result lets Claude fold the new input into the work it is already doing, instead of treating it as a fresh request to switch to. See [Placement after tool results](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#placement-after-tool-results).
465466* **Mode switches that grant standing permissions.** A session-level mode can use a mid-conversation system message to grant standing consent to an expensive capability, such as automatically launching multiagent workflows, with a short refresher every several turns and an exit notice when the mode is turned off. For a worked example, see [Build an orchestration mode](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-effort-example).
466467 
467468In all of these cases you could put the instruction in a regular `user` message, and Claude does follow instructions that arrive in user turns. The difference is priority: a `user` message is treated as coming from the end user, while a `system` message is treated as coming from you, the application operator. When the two conflict, system instructions take precedence, so use the `system` role for operator-level facts and constraints that should hold even if the end user asks for something different. A mid-conversation system message keeps that operator-level priority without paying the cache-miss cost of editing the top-level `system` field.
from line 473
472473 
473474You can still set the top-level `system` field for instructions that should apply to the entire conversation. Reserve mid-conversation system messages for instructions that only become relevant later, or that you want to add without invalidating the cached prefix.
474475 
476A `role: "system"` message can also carry `output_config.effort` to change the [effort](https://platform.claude.com/docs/en/build-with-claude/effort) level from the next `user` turn on. This is in beta on Claude Fable 5.1, Claude Mythos 5.1, and Claude Opus 5 on the Claude API and requires the `mid-conversation-output-config-2026-07-01` beta header. See [Per-message effort](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta).
477 
475478<CodeGroup>
476479 ```bash cURL
477480 curl https://api.anthropic.com/v1/messages \
from line 814
811814 
812815This pattern is for relaying input from the conversation's own end user. Do not use it to pass tool output, retrieved documents, or other third-party content; keep that content in `tool_result` blocks (see [Limitations](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#limitations)).
813816 
817### Turn-scoped system messages
818 
819To scope a `role: "system"` message to the current turn, set its `clear_at` field. It takes one of two values:
820 
821* `"never"` (the default): the message renders at its position on every request that includes it. Omitting the field is identical.
822* `"next_user_message"`: the message is **turn-scoped**. Its text renders only while no `role: "user"` message comes after it in `messages`. A user message that carries only `tool_result` blocks counts as a user message here. Once a later user message exists, the message is **cleared**: it stays in the array but renders nothing and costs no input tokens, on that request and every later one.
823 
824Turn-scoped system messages are in beta. Include the [beta header](https://platform.claude.com/docs/en/api/beta-headers) `mid-conversation-system-clear-at-2026-08-21`. Without it, `clear_at` is rejected as an unknown field.
825 
826```json
827{
828 "role": "system",
829 "clear_at": "next_user_message",
830 "content": "First privately list what you need next; then request every item that doesn't depend on another's result in this one response."
831}
832```
833 
834The main use is a per-turn reminder in a tool loop. Append the reminder after the `tool_result` message each time you want the model to see it, and leave every earlier copy where it is. The model sees only the copies that come after the last user message, so the reminder never piles up. Nothing earlier in `messages` changes, so the [prompt cache](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) keeps matching. On Claude Fable 5.1 this also keeps later [thinking blocks valid](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation): deleting an earlier reminder would change the conversation before those blocks and fail the conversation check, while a cleared message stays in the array and leaves that conversation unchanged.
835 
836The following request is a later step of an agent loop. `messages[3]` rendered on the earlier request, when it was the last message in the array. Once `messages[5]` (a later user message) exists, `messages[3]` is cleared: the cleared message stays in the array, so the conversation before the thinking block in `messages[4]` is unchanged, but the model no longer sees its text. `messages[6]` and `messages[7]` both render, in order.
837 
838```json
839{
840 "model": "claude-fable-5-1",
841 "max_tokens": 16000,
842 "messages": [
843 { "role": "user", "content": "Fix the failing test." },
844 {
845 "role": "assistant",
846 "content": [
847 { "type": "thinking", "thinking": "", "signature": "..." },
848 {
849 "type": "tool_use",
850 "id": "toolu_01",
851 "name": "read_file",
852 "input": { "path": "test_auth.py" }
853 }
854 ]
855 },
856 {
857 "role": "user",
858 "content": [{ "type": "tool_result", "tool_use_id": "toolu_01", "content": "..." }]
859 },
860 {
861 "role": "system",
862 "clear_at": "next_user_message",
863 "content": "Request independent reads in one turn."
864 },
865 {
866 "role": "assistant",
867 "content": [
868 { "type": "thinking", "thinking": "", "signature": "..." },
869 {
870 "type": "tool_use",
871 "id": "toolu_02",
872 "name": "read_file",
873 "input": { "path": "auth.py" }
874 },
875 {
876 "type": "tool_use",
877 "id": "toolu_03",
878 "name": "read_file",
879 "input": { "path": "tokens.py" }
880 }
881 ]
882 },
883 {
884 "role": "user",
885 "content": [
886 { "type": "tool_result", "tool_use_id": "toolu_02", "content": "..." },
887 {
888 "type": "tool_result",
889 "tool_use_id": "toolu_03",
890 "content": "...",
891 "cache_control": { "type": "ephemeral" }
892 }
893 ]
894 },
895 {
896 "role": "system",
897 "clear_at": "next_user_message",
898 "content": "Request independent reads in one turn."
899 },
900 {
901 "role": "system",
902 "clear_at": "next_user_message",
903 "content": "The shell exited with status 137."
904 }
905 ]
906}
907```
908 
909Rules for turn-scoped messages:
910 
911* **Re-send cleared messages verbatim.** A cleared message is still part of the conversation history. Rebuilding it from current state (a fresh token count, a timestamp), dropping it as redundant, or changing its `clear_at` value is an edit to an earlier message. The prompt cache misses from that point, and on Claude Fable 5.1 every thinking block produced after it fails the [conversation check](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation).
912* **Text only.** `content` is one or more `text` blocks (or a string). `tool_addition` and `tool_removal` blocks return a 400 error on a turn-scoped message, and so does `output_config`. Use a separate `role: "system"` message without `clear_at` for those.
913* **No `cache_control` on its blocks.** A cleared message is never part of a cache key, so a breakpoint on it could never match. Put the breakpoint on the last block of the preceding user turn instead, as the example does. The top-level [automatic caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#automatic-caching) field skips turn-scoped messages when it picks a breakpoint. On the request that clears a message, the reusable cached prefix ends at the user turn before it, so only the one assistant turn between that message and the new user message is reprocessed.
914* **Placement rules still apply**, cleared or not. A turn-scoped message must follow a `user` turn (or an `assistant` turn ending in a server tool result) and precede an `assistant` turn or end the array, like any mid-conversation system message. One that ends the array always renders. One followed directly by another `user` message is a 400 error, not a cleared message: put all of a tool round's results in one user message and the reminders after it.
915* **Assistant turns don't clear it.** A prefilled or [paused](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#pause-turn) assistant turn after the message, or a server-side tool loop, adds no user message, so the message still renders on that continuation. To keep a reminder in view through a client-side tool loop, append it again after each `tool_result` message.
916* **Token counting follows what renders.** A cleared message adds nothing to `usage.input_tokens` or to a [token count](https://platform.claude.com/docs/en/build-with-claude/token-counting).
917* **Imported history.** In a transcript you construct in one step (few-shot examples, a migrated conversation), a turn-scoped message that already has an assistant turn and a user message after it is cleared from the first request and never renders. That is the right state for a per-turn reminder you are carrying over. Leave `clear_at` unset only on a message the model should see on every request.
918 
919The validation errors are:
920 
921```text wrap
922messages.3.clear_at: Extra inputs are not permitted
923messages.3.clear_at: clear_at is only permitted on role 'system' messages
924messages.3.clear_at: Input should be 'next_user_message' or 'never'
925messages.3: a turn-scoped system message supports text blocks only (clear_at: 'next_user_message')
926messages.3: output_config is not permitted on a turn-scoped system message (clear_at: 'next_user_message')
927messages.3.content.0: cache_control is not permitted on a turn-scoped system message (clear_at: 'next_user_message')
928```
929 
930The first is the error returned without the beta header. On Amazon Bedrock and Google Cloud, pass the beta value as described in [Beta headers](https://platform.claude.com/docs/en/api/beta-headers).
931 
932Through the SDKs, set `clear_at` on the `role: "system"` entry in `messages` and send the beta header. The following example appends a turn-scoped reminder after the user turn; on the next request, once a later user message exists, the reminder stays in the array but no longer renders:
933 
934<CodeGroup>
935 ```bash cURL
936 curl https://api.anthropic.com/v1/messages \
937 -H "x-api-key: $ANTHROPIC_API_KEY" \
938 -H "anthropic-version: 2023-06-01" \
939 -H "anthropic-beta: mid-conversation-system-clear-at-2026-08-21" \
940 -H "content-type: application/json" \
941 -d '{
942 "model": "claude-fable-5-1",
943 "max_tokens": 4096,
944 "messages": [
945 {"role": "user", "content": "Draft a short status update on the database migration for the team channel."},
946 {"role": "system", "clear_at": "next_user_message", "content": "The reader is on call: keep this reply under 50 words."}
947 ]
948 }'
949 ```
950 
951 ```bash CLI
952 ant beta:messages create --beta mid-conversation-system-clear-at-2026-08-21 \
953 --transform 'content.#(type=="text").text' --raw-output <<'YAML'
954 model: claude-fable-5-1
955 max_tokens: 4096
956 messages:
957 - role: user
958 content: Draft a short status update on the database migration for the team channel.
959 # Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
960 - role: system
961 clear_at: next_user_message
962 content: "The reader is on call: keep this reply under 50 words."
963 YAML
964 ```
965 
966 ```python Python
967 client = anthropic.Anthropic()
968 
969 response = client.beta.messages.create(
970 model="claude-fable-5-1",
971 max_tokens=4096,
972 messages=[
973 {
974 "role": "user",
975 "content": "Draft a short status update on the database migration for the team channel.",
976 },
977 # Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
978 {
979 "role": "system",
980 "clear_at": "next_user_message",
981 "content": "The reader is on call: keep this reply under 50 words.",
982 },
983 ],
984 betas=["mid-conversation-system-clear-at-2026-08-21"],
985 )
986 
987 for block in response.content:
988 if block.type == "text":
989 print(block.text)
990 ```
991 
992 ```typescript TypeScript
993 const client = new Anthropic();
994 
995 const response = await client.beta.messages.create({
996 model: "claude-fable-5-1",
997 max_tokens: 4096,
998 messages: [
999 {
1000 role: "user",
1001 content: "Draft a short status update on the database migration for the team channel."
1002 },
1003 // Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
1004 {
1005 role: "system",
1006 clear_at: "next_user_message",
1007 content: "The reader is on call: keep this reply under 50 words."
1008 }
1009 ],
1010 betas: ["mid-conversation-system-clear-at-2026-08-21"]
1011 });
1012 
1013 for (const block of response.content) {
1014 if (block.type === "text") {
1015 console.log(block.text);
1016 }
1017 }
1018 ```
1019 
1020 ```csharp C#
1021 using Anthropic.Models.Beta;
1022 using Anthropic.Models.Beta.Messages;
1023 
1024 AnthropicClient client = new();
1025 
1026 var response = await client.Beta.Messages.Create(new MessageCreateParams
1027 {
1028 Model = "claude-fable-5-1",
1029 MaxTokens = 4096,
1030 Messages =
1031 [
1032 new() { Role = Role.User, Content = "Draft a short status update on the database migration for the team channel." },
1033 // Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
1034 new()
1035 {
1036 Role = Role.System,
1037 ClearAt = ClearAt.NextUserMessage,
1038 Content = "The reader is on call: keep this reply under 50 words.",
1039 },
1040 ],
1041 Betas = [AnthropicBeta.MidConversationSystemClearAt2026_08_21],
1042 });
1043 
1044 foreach (var block in response.Content)
1045 {
1046 if (block.TryPickText(out var textBlock))
1047 {
1048 Console.WriteLine(textBlock.Text);
1049 }
1050 }
1051 ```
1052 
1053 ```go Go
1054 client := anthropic.NewClient()
1055 
1056 response, err := client.Beta.Messages.New(context.Background(), anthropic.BetaMessageNewParams{
1057 Model: "claude-fable-5-1",
1058 MaxTokens: 4096,
1059 Messages: []anthropic.BetaMessageParam{
1060 anthropic.NewBetaUserMessage(anthropic.NewBetaTextBlock("Draft a short status update on the database migration for the team channel.")),
1061 // Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
1062 {
1063 Role: anthropic.BetaMessageParamRoleSystem,
1064 ClearAt: anthropic.BetaMessageParamClearAtNextUserMessage,
1065 Content: []anthropic.BetaContentBlockParamUnion{anthropic.NewBetaTextBlock("The reader is on call: keep this reply under 50 words.")},
1066 },
1067 },
1068 Betas: []anthropic.AnthropicBeta{anthropic.AnthropicBetaMidConversationSystemClearAt2026_08_21},
1069 })
1070 if err != nil {
1071 log.Fatal(err)
1072 }
1073 
1074 for _, block := range response.Content {
1075 if textBlock, ok := block.AsAny().(anthropic.BetaTextBlock); ok {
1076 fmt.Println(textBlock.Text)
1077 }
1078 }
1079 ```
1080 
1081 ```java Java
1082 import com.anthropic.models.beta.AnthropicBeta;
1083 import com.anthropic.models.beta.messages.BetaMessage;
1084 import com.anthropic.models.beta.messages.BetaMessageParam;
1085 import com.anthropic.models.beta.messages.MessageCreateParams;
1086 
1087 void main() {
1088 AnthropicClient client = AnthropicOkHttpClient.fromEnv();
1089 
1090 MessageCreateParams params = MessageCreateParams.builder()
1091 .model("claude-fable-5-1")
1092 .maxTokens(4096L)
1093 .addBeta(AnthropicBeta.MID_CONVERSATION_SYSTEM_CLEAR_AT_2026_08_21)
1094 .addUserMessage("Draft a short status update on the database migration for the team channel.")
1095 // Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
1096 .addMessage(BetaMessageParam.builder()
1097 .role(BetaMessageParam.Role.SYSTEM)
1098 .clearAt(BetaMessageParam.ClearAt.NEXT_USER_MESSAGE)
1099 .content("The reader is on call: keep this reply under 50 words.")
1100 .build())
1101 .build();
1102 
1103 BetaMessage response = client.beta().messages().create(params);
1104 response.content().stream()
1105 .flatMap(block -> block.text().stream())
1106 .forEach(textBlock -> IO.println(textBlock.text()));
1107 }
1108 ```
1109 
1110 ```php PHP
1111 use Anthropic\Beta\AnthropicBeta;
1112 use Anthropic\Beta\Messages\BetaMessageParam;
1113 use Anthropic\Client;
1114 
1115 $client = new Client();
1116 
1117 $response = $client->beta->messages->create(
1118 model: 'claude-fable-5-1',
1119 maxTokens: 4096,
1120 messages: [
1121 BetaMessageParam::with(role: 'user', content: 'Draft a short status update on the database migration for the team channel.'),
1122 // Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
1123 BetaMessageParam::with(
1124 role: 'system',
1125 clearAt: 'next_user_message',
1126 content: 'The reader is on call: keep this reply under 50 words.',
1127 ),
1128 ],
1129 betas: [AnthropicBeta::MID_CONVERSATION_SYSTEM_CLEAR_AT_2026_08_21],
1130 );
1131 
1132 foreach ($response->content as $block) {
1133 if ($block->type === 'text') {
1134 echo $block->text, PHP_EOL;
1135 }
1136 }
1137 ```
1138 
1139 ```ruby Ruby
1140 client = Anthropic::Client.new
1141 
1142 response = client.beta.messages.create(
1143 model: "claude-fable-5-1",
1144 max_tokens: 4096,
1145 messages: [
1146 {role: "user", content: "Draft a short status update on the database migration for the team channel."},
1147 # Turn-scoped reminder: renders for this turn, then clears once a later user message exists.
1148 {role: "system", clear_at: :next_user_message, content: "The reader is on call: keep this reply under 50 words."}
1149 ],
1150 betas: [Anthropic::AnthropicBeta::MID_CONVERSATION_SYSTEM_CLEAR_AT_2026_08_21]
1151 )
1152 
1153 response.content.each do |block|
1154 puts block.text if block.type == :text
1155 end
1156 ```
1157</CodeGroup>
1158 
8141159## Combining with prompt caching
8151160 
8161161Mid-conversation system messages and [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) are designed to be used together:
from line 1165
8201165* **Append the system message after the breakpoint.** Because it comes after the cached prefix, it does not change the prefix hash and the cache still hits.
8211166* **A mid-conversation system message is itself cacheable.** Once it is in the conversation, it becomes part of the stable history. On the next turn you can move your cache breakpoint past it (or rely on [automatic caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#automatic-caching) to do so) and the system message is read from cache like any other turn.
8221167 
823Avoid editing or removing a mid-conversation system message that has already been sent. Like any other change to earlier messages, that invalidates the cache from that point forward. If the instruction needs to evolve, append a new system message rather than rewriting the old one. Consecutive system messages are accepted and treated as a single system section, which follows the same placement rule as a whole.
1168Avoid editing or removing a mid-conversation system message that has already been sent. Like any other change to earlier messages, that invalidates the cache from that point forward. On Claude Fable 5.1 it also invalidates the [thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation) in every later assistant turn. For guidance that should apply to one turn only, use a [turn-scoped system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#turn-scoped-system-messages) and leave it in place. If the instruction needs to evolve, append a new system message rather than rewriting the old one. Consecutive system messages are accepted and treated as a single system section, which follows the same placement rule as a whole.
8241169 
8251170## Limitations
8261171 
827* **Not for the first message.** A `system` message cannot be the first entry in `messages`. Use the top-level `system` field for instructions that apply from the very start.
828* **Placement is constrained.** A `system` message must immediately follow a `user` turn (including a `user` turn that carries `tool_result` blocks) or an `assistant` turn ending in a server tool result, and must precede an `assistant` turn or end the array. It cannot sit between a `tool_use` block and its `tool_result`. Placing it elsewhere returns a 400 error.
1172* **Not for the first message.** A `system` message that carries content cannot be the first entry in `messages`. Use the top-level `system` field for instructions that apply from the very start.
1173* **Placement is constrained.** A `system` message that carries content (`text`, `tool_addition`, or `tool_removal` blocks) must immediately follow a `user` turn (including a `user` turn that carries `tool_result` blocks) or an `assistant` turn ending in a server tool result, and must precede an `assistant` turn or end the array. It cannot sit between a `tool_use` block and its `tool_result`. Placing it elsewhere returns a 400 error. A message with empty `content` that only sets [`output_config.effort`](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) renders nothing at its position and is accepted anywhere in `messages`, including first or between an `assistant` turn and a `user` turn. Consecutive `system` messages are judged together, so adding a text-carrying message next to an effort-only one makes the whole group follow the content rule.
1174* **Turn-scoped messages are text-only and re-sent verbatim.** A `clear_at: "next_user_message"` message carries no `tool_addition`, `tool_removal`, `output_config`, or `cache_control`, and once cleared it must stay in `messages` byte-for-byte on later requests. See [Turn-scoped system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#turn-scoped-system-messages).
8291175* **Not a place for untrusted content.** Claude treats system content as operator instructions and follows it. Do not place text from outside the conversation, such as raw tool output, retrieved documents, or web content, directly in a system message; doing so gives that text operator-level authority. Keep that data in `tool_result` blocks and continue to follow [Mitigate jailbreaks and prompt injections](https://platform.claude.com/docs/en/test-and-evaluate/strengthen-guardrails/mitigate-jailbreaks).
8301176 
8311177## Related

build-with-claude/prompt-caching Changed · +40 / -35 lines

from line 231
231231 
232232Prompt caching introduces a new pricing structure. The following table shows the price per million tokens for each supported model:
233233 
234| Model | Base Input Tokens | 5m Cache Writes | 1h Cache Writes | Cache Hits & Refreshes | Output Tokens |
235| ------------------------------------------------------------------------------------------------------------------------------------- | ----------------- | --------------- | --------------- | ---------------------- | ------------- |
236| Claude Fable 5 | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
237| Claude Mythos 5 ([limited availability](https://anthropic.com/glasswing)) | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
238| Claude Opus 5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
239| Claude Opus 4.8 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
240| Claude Opus 4.7 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
241| Claude Opus 4.6 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
242| Claude Opus 4.5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
243| Claude Opus 4.1 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
244| Claude Opus 4 ([retired, except on Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
245| Claude Sonnet 5 | $2 / MTok | $2.50 / MTok | $4 / MTok | $0.20 / MTok | $10 / MTok |
246| Claude Sonnet 4.6 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
247| Claude Sonnet 4.5 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
248| Claude Sonnet 4 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
249| Claude Haiku 4.5 | $1 / MTok | $1.25 / MTok | $2 / MTok | $0.10 / MTok | $5 / MTok |
250| Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $0.80 / MTok | $1 / MTok | $1.60 / MTok | $0.08 / MTok | $4 / MTok |
234| Model | Base input tokens | 5m cache writes | 1h cache writes | Cache hits and refreshes | Output tokens |
235| ------------------------------------------------------------------------------------------------------------------------------------- | ----------------- | --------------- | --------------- | ------------------------ | ------------- |
236| Claude Fable 5.1 | $10 / MTok | $12.50 / MTok | $20 / MTok | $0.25 / MTok1 | $50 / MTok |
237| Claude Mythos 5.1 ([limited availability](https://anthropic.com/glasswing)) | $10 / MTok | $12.50 / MTok | $20 / MTok | $0.25 / MTok1 | $50 / MTok |
238| Claude Fable 5 | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
239| Claude Mythos 5 ([limited availability](https://anthropic.com/glasswing)) | $10 / MTok | $12.50 / MTok | $20 / MTok | $1 / MTok | $50 / MTok |
240| Claude Opus 5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
241| Claude Opus 4.8 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
242| Claude Opus 4.7 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
243| Claude Opus 4.6 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
244| Claude Opus 4.5 | $5 / MTok | $6.25 / MTok | $10 / MTok | $0.50 / MTok | $25 / MTok |
245| Claude Opus 4.1 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
246| Claude Opus 4 ([retired, except on Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $15 / MTok | $18.75 / MTok | $30 / MTok | $1.50 / MTok | $75 / MTok |
247| Claude Sonnet 5 | $2 / MTok | $2.50 / MTok | $4 / MTok | $0.20 / MTok | $10 / MTok |
248| Claude Sonnet 4.6 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
249| Claude Sonnet 4.5 | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
250| Claude Sonnet 4 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $3 / MTok | $3.75 / MTok | $6 / MTok | $0.30 / MTok | $15 / MTok |
251| Claude Haiku 4.5 | $1 / MTok | $1.25 / MTok | $2 / MTok | $0.10 / MTok | $5 / MTok |
252| Claude Haiku 3.5 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)) | $0.80 / MTok | $1 / MTok | $1.60 / MTok | $0.08 / MTok | $4 / MTok |
251253 
254*1 Cache hits and refreshes on Claude Fable 5.1 and Claude Mythos 5.1 are priced at 0.025x the base input price. All other models use the standard 0.1x multiplier.*
255 
252256<Note>
253257 The previous table reflects the following pricing multipliers for prompt caching:
254258 
255259 * 5-minute cache write tokens are 1.25 times the base input tokens price
256260 * 1-hour cache write tokens are 2 times the base input tokens price
257 * Cache read tokens are 0.1 times the base input tokens price
261 * Cache read tokens are 0.1 times the base input tokens price (see the table footnote for per-model exceptions)
258262 
259263 These multipliers stack with other pricing modifiers such as the Batch API discount and data residency. See [pricing](https://platform.claude.com/docs/en/about-claude/pricing) for full details.
260264</Note>
from line 546
542546 
5435472. **Cache reads look backward for entries that prior requests wrote.** On each request the system computes the prefix hash at your breakpoint and checks for a matching cache entry. If none exists, it walks backward one block at a time, checking whether the prefix hash at each earlier position matches something already in the cache. It is looking for prior writes, not for stable content.
544548 
5453. **The lookback window is 20 blocks.** The system checks at most 20 positions per breakpoint, counting the breakpoint itself as the first. If the system finds no matching entry in that window, checking stops (or resumes from the next explicit breakpoint, if any).
5493. **The lookback window is 20 blocks.** The system checks at most 20 positions per breakpoint, counting the breakpoint itself as the first. If the system finds no matching entry in that window, checking stops (or resumes from the next explicit breakpoint, if any). On the Claude API, a run of consecutive `tool_use` blocks counts as one position, and so does a run of consecutive `tool_result` blocks, so a turn with many parallel tool calls doesn't push the previous request's entry out of the window on its own.
546550 
547551**Example: Lookback in a growing conversation**
548552 
from line 584
580584**Cache breakpoints themselves don't add any cost.** You are only charged for:
581585 
582586* **Cache writes:** When new content is written to the cache (25% more than base input tokens for 5-minute TTL)
583* **Cache reads:** When cached content is used (10% of base input token price)
587* **Cache reads:** When cached content is used (10% of base input token price, or 2.5% on Claude Fable 5.1 and Claude Mythos 5.1)
584588* **Regular input tokens:** For any uncached content
585589 
586590Adding more `cache_control` breakpoints doesn't increase your costs - you still pay the same amount based on what content is actually cached and read. The breakpoints give you control over what sections can be cached independently.
from line 597
593597 
594598On the Claude API, [Claude Platform on AWS](https://platform.claude.com/docs/en/build-with-claude/claude-platform-on-aws), [Google Cloud](https://platform.claude.com/docs/en/build-with-claude/claude-on-vertex-ai), and [Microsoft Foundry](https://platform.claude.com/docs/en/build-with-claude/claude-in-microsoft-foundry), the minimum cacheable prompt length is:
595599 
596* 512 tokens for Claude Opus 5, Claude Fable 5, and [Claude Mythos 5](https://anthropic.com/glasswing)
600* 512 tokens for Claude Fable 5.1, Claude Mythos 5.1, Claude Opus 5, Claude Fable 5, and [Claude Mythos 5](https://anthropic.com/glasswing)
597601* 2,048 tokens for [Claude Mythos Preview](https://anthropic.com/glasswing) and Claude Opus 4.7
598602* 4,096 tokens for Claude Opus 4.6 and Claude Opus 4.5
599603* 1,024 tokens for Claude Opus 4.8, Claude Sonnet 5, Claude Sonnet 4.6, Claude Sonnet 4.5, Claude Opus 4.1 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)), Claude Opus 4 ([retired, except on Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations)), and Claude Sonnet 4 ([retired, except on Bedrock and Google Cloud](https://platform.claude.com/docs/en/about-claude/model-deprecations))
from line 650
646650 
647651The following table shows which parts of the cache are invalidated by different types of changes. ✘ indicates that the cache is invalidated, while ✓ indicates that the cache remains valid.
648652 
649| What changes | Tools cache | System cache | Messages cache | Impact |
650| --------------------------------------------------------- | -------------- | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
651| **Tool definitions** | ✘ | ✘ | ✘ | Modifying tool definitions (names, descriptions, parameters) invalidates the entire cache |
652| **Web search toggle** | ✓ | ✘ | ✘ | Enabling/disabling web search modifies the system prompt |
653| **Citations toggle** | ✓ | ✘ | ✘ | Enabling/disabling citations modifies the system prompt |
654| **Speed setting** | ✓ | ✘ | ✘ | Switching between [`speed: "fast"` and standard speed](https://platform.claude.com/docs/en/build-with-claude/fast-mode) invalidates system and message caches |
655| **Tool choice** | ✓ | ✓ | ✘ | Changes to `tool_choice` parameter only affect message blocks |
656| **Images** | ✓ | ✓ | ✘ | Adding/removing images anywhere in the prompt affects message blocks |
657| **Thinking parameters** | Model-specific | Model-specific | ✘ | The thinking configuration (mode, and `budget_tokens` in extended mode) is rendered into the prompt, so changing it always invalidates message blocks; tool and system caches are also invalidated on models that render the configuration ahead of them. See [Thinking and prompt caching](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-prompt-caching). |
658| **Effort setting** | Model-specific | Model-specific | ✘ | Changing the [`output_config.effort`](https://platform.claude.com/docs/en/build-with-claude/effort) value always invalidates message blocks, with the same model-specific effect on tool and system caches as thinking parameters. Setting effort explicitly to the model's default is equivalent to omitting it and does not invalidate. |
659| **Non-tool results passed to extended thinking requests** | ✓ | ✓ | Model-specific | On Opus 4.5+ and Sonnet 4.6+, thinking blocks are preserved by default, so the cache remains valid (✓). On earlier Opus/Sonnet models and all Haiku models, all previously-cached thinking blocks are stripped from context, and any messages that follow those thinking blocks are removed from the cache (✘). For more details, see [Caching with thinking blocks](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#caching-with-thinking-blocks). |
653| What changes | Tools cache | System cache | Messages cache | Impact |
654| --------------------------------------------------------- | -------------- | -------------- | -------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
655| **Tool definitions** | ✘ | ✘ | ✘ | Modifying tool definitions (names, descriptions, parameters) invalidates the entire cache |
656| **Web search toggle** | ✓ | ✘ | ✘ | Enabling/disabling web search modifies the system prompt |
657| **Citations toggle** | ✓ | ✘ | ✘ | Enabling/disabling citations modifies the system prompt |
658| **Speed setting** | ✓ | ✘ | ✘ | Switching between [`speed: "fast"` and standard speed](https://platform.claude.com/docs/en/build-with-claude/fast-mode) invalidates system and message caches |
659| **Tool choice** | ✓ | ✓ | ✘ | Changes to `tool_choice` parameter only affect message blocks |
660| **Images** | ✓ | ✓ | ✘ | Adding/removing images anywhere in the prompt affects message blocks |
661| **Thinking parameters** | Model-specific | Model-specific | ✘ | The thinking configuration (mode, and `budget_tokens` in extended mode) is rendered into the prompt, so changing it always invalidates message blocks; tool and system caches are also invalidated on models that render the configuration ahead of them. See [Thinking and prompt caching](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-prompt-caching). |
662| **Effort setting** | Model-specific | Model-specific | ✘ | Changing the [`output_config.effort`](https://platform.claude.com/docs/en/build-with-claude/effort) value always invalidates message blocks, with the same model-specific effect on tool and system caches as thinking parameters. Setting effort explicitly to the model's default is equivalent to omitting it and does not invalidate. On models that support [per-message effort](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta), an effort change carried in a `role: "system"` message inside `messages` leaves the cached prefix intact. |
663| **Non-tool results passed to extended thinking requests** | ✓ | ✓ | Model-specific | On Opus 4.5+ and Sonnet 4.6+, thinking blocks are preserved by default, so the cache remains valid (✓). On earlier Opus/Sonnet models and all Haiku models, all previously-cached thinking blocks are stripped from context, and any messages that follow those thinking blocks are removed from the cache (✘). For more details, see [Caching with thinking blocks](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#caching-with-thinking-blocks). |
664| **Dropped thinking blocks** | ✓ | ✓ | ✘ | When the API drops a Claude Fable 5.1 or Claude Mythos 5.1 thinking block that isn't [preserved](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-thinking) on that request (for example, one you replay to an earlier model), the cached prefix changes from that block's position onward on that request. Blocks the receiving model can read, passed back unchanged, keep the cache intact. |
660665 
661666<Note>
662 On Claude Fable 5, [Claude Mythos 5](https://anthropic.com/glasswing), Claude Opus 4.8, and Claude Opus 5, you can add a new system instruction partway through a conversation without invalidating the system or message caches. Append a `{"role": "system"}` message to `messages` instead of editing the top-level `system` field, so the cached prefix stays unchanged. This feature is not available on Claude Sonnet 5; use the top-level `system` field instead. See [Mid-conversation system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages).
667 On Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, [Claude Mythos 5](https://anthropic.com/glasswing), Claude Opus 4.8, and Claude Opus 5, you can add a new system instruction partway through a conversation without invalidating the system or message caches. Append a `{"role": "system"}` message to `messages` instead of editing the top-level `system` field, so the cached prefix stays unchanged. This feature is not available on Claude Sonnet 5. Use the top-level `system` field instead. See [Mid-conversation system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages).
663668</Note>
664669 
665670### Tracking cache performance
from line 3199
31943199 No, cache breakpoints themselves are free. You only pay for:
31953200 
31963201 * Writing content to cache (25% more than base input tokens for 5-minute TTL)
3197 * Reading from cache (10% of base input token price)
3202 * Reading from cache (a fraction of the base input token price, see [Pricing](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#pricing))
31983203 * Regular input tokens for uncached content
31993204 
32003205 The number of breakpoints doesn't affect pricing - only the amount of content cached and read matters.
from line 3267
32623267 </Accordion>
32633268 
32643269 <Accordion title="How does prompt caching affect pricing?">
3265 Prompt caching introduces a new pricing structure where 5-minute cache writes cost 25% more than base input tokens, 1-hour cache writes cost 2x base input tokens, and cache hits cost only 10% of the base input token price.
3270 Prompt caching introduces a new pricing structure where 5-minute cache writes cost 25% more than base input tokens, 1-hour cache writes cost 2x base input tokens, and cache hits cost a fraction of the base input token price (see [Pricing](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#pricing) for the per-model multiplier).
32663271 </Accordion>
32673272 
32683273 <Accordion title="Can I manually clear the cache?">

build-with-claude/prompt-engineering/claude-prompting-best-practices Changed · +33 / -27 lines

## Model-specific guidance ## Claude Fable 5 ## Claude Sonnet 5 ## Prompting Claude Opus 5 ## Prompting Claude Opus 4.8

from line 4
44description: Comprehensive guide to prompt engineering techniques for Claude's latest models, covering clarity, examples, XML structuring, thinking, and agentic systems.
55---
66 
7This is the reference for prompt engineering with Claude's latest models, including Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, Claude Sonnet 4.6, and Claude Haiku 4.5. The page is organized in three parts:
7This is the reference for prompt engineering with current Claude models, including Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, Claude Sonnet 5, Claude Sonnet 4.6, and Claude Haiku 4.5. The page is organized in three parts:
88 
9* **Model-specific guidance** first: where [Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5), [Claude Sonnet 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-sonnet-5), [Claude Opus 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5), and [Claude Opus 4.8](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-4-8) behave differently and what to change.
9* **[Model-specific guidance](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/claude-prompting-best-practices#model-specific-guidance)** first: where a single model behaves differently and what to change in your prompt.
1010* **Techniques for all current models** after that: general principles, output and formatting, tool use, thinking, and agentic systems.
1111* **Migration considerations** last, for prompts moving from earlier generations.
1212 
1313<Tip>
14 For an overview of model capabilities, see the [models overview](https://platform.claude.com/docs/en/models/overview). For Claude Fable 5 capabilities and API changes, see [Introducing Claude Fable 5 and Claude Mythos 5](https://platform.claude.com/docs/en/models/fable-5/introducing-claude-fable-5-and-claude-mythos-5). For details on what's new in Claude Sonnet 5, see [What's new in Claude Sonnet 5](https://platform.claude.com/docs/en/models/sonnet-5/whats-new-sonnet-5). For details on what's new in Claude Opus 5, see [What's new in Claude Opus 5](https://platform.claude.com/docs/en/models/opus-5/whats-new-opus-5). For migration guidance, see the [Migration guide](https://platform.claude.com/docs/en/about-claude/models/migration-guide).
14 For an overview of model capabilities, see the [models overview](https://platform.claude.com/docs/en/models/overview). For Claude Fable 5.1 capabilities and API changes, see [What's new in Claude Fable 5.1](https://platform.claude.com/docs/en/models/fable-5-1/whats-new-fable-5-1). For Claude Fable 5 capabilities and API changes, see [Introducing Claude Fable 5 and Claude Mythos 5](https://platform.claude.com/docs/en/models/fable-5/introducing-claude-fable-5-and-claude-mythos-5). For details on what's new in Claude Sonnet 5, see [What's new in Claude Sonnet 5](https://platform.claude.com/docs/en/models/sonnet-5/whats-new-sonnet-5). For details on what's new in Claude Opus 5, see [What's new in Claude Opus 5](https://platform.claude.com/docs/en/models/opus-5/whats-new-opus-5). For migration guidance, see the [Migration guide](https://platform.claude.com/docs/en/about-claude/models/migration-guide).
1515</Tip>
1616 
17## Claude Fable 5
17## Model-specific guidance
1818 
19Prompting guidance for Claude Fable 5 and Claude Mythos 5 has its own page: [Prompting Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5). It covers the behavioral differences from Claude Opus 4.8 and the prompt and scaffolding changes worth making, including effort levels, instruction following, long-run progress claims, memory systems, and the `reasoning_extraction` refusal category.
19Each of these models has its own prompting page. Read the one for your model first, then the techniques that follow.
2020 
21## Claude Sonnet 5
21| Model | Guide | What's different |
22| -------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
23| Claude Fable 5.1 and Claude Mythos 5.1 | [Prompting Claude Fable 5.1](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1) | Differences from Claude Fable 5: effort levels, finishing long tasks, user-facing progress updates, passing thinking blocks back unchanged, tool-call batching in agent loops, search triggering at low effort, formatting, and writing density. |
24| Claude Fable 5 and Claude Mythos 5 | [Prompting Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5) | Differences from Claude Opus 4.8: effort levels, instruction following, long-run progress claims, memory systems, and the `reasoning_extraction` refusal category. |
25| Claude Sonnet 5 | [Prompting Claude Sonnet 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-sonnet-5) | Differences from Claude Sonnet 4.6: response length, effort and thinking-depth calibration, tool use triggering, literal instruction following, and design and frontend defaults. |
26| Claude Opus 5 | [Prompting Claude Opus 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5) | Differences from prior Opus models: response length and verbosity, user-facing progress updates, written deliverable length, task scope and over-verification, subagent control, and self-correction. |
27| Claude Opus 4.8 | [Prompting Claude Opus 4.8](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-4-8) | Response length, effort and thinking-depth calibration, tool use triggering, literal instruction following, subagent control, and design and frontend defaults. |
2228 
23Prompting guidance for Claude Sonnet 5 has its own page: [Prompting Claude Sonnet 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-sonnet-5). It covers the behavioral differences from Claude Sonnet 4.6 and the prompt changes worth making, including response length, effort and thinking-depth calibration, tool use triggering, literal instruction following, and design and frontend defaults.
24 
25## Prompting Claude Opus 5
26 
27Prompting guidance for Claude Opus 5 has its own page: [Prompting Claude Opus 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5). It covers the behavioral differences from prior Opus models and the prompt changes worth making, including response length and verbosity, user-facing progress updates, written deliverable length, task scope and over-verification, subagent control, and self-correction.
28 
29## Prompting Claude Opus 4.8
30 
31Prompting guidance for Claude Opus 4.8 has its own page: [Prompting Claude Opus 4.8](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-4-8). It covers response length, effort and thinking-depth calibration, tool use triggering, literal instruction following, subagent control, and design and frontend defaults.
32 
3329## General principles
3430 
35The techniques in this section and the sections that follow apply to all current Claude models, including Claude Fable 5 and Claude Mythos 5.
31The techniques in this section and the sections that follow apply to current Claude models, including Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, and Claude Mythos 5. Where a technique names a specific model, treat it as measured on that model and re-check it against your own evals before applying it to another.
3632 
3733### Be clear and direct
3834 
from line 41
4541* Be specific about the desired output format and constraints.
4642* Provide instructions as sequential steps using numbered lists or bullet points when the order or completeness of steps matters.
4743 
48<Accordion title="Example: Creating an analytics dashboard">
44<Accordion title="Example: Creating an analytics dashboard" defaultOpen>
4945 **Less effective:**
5046 
5147 ```text wrap
from line 59
6359 
6460Providing context or motivation behind your instructions, such as explaining to Claude why such behavior is important, can help Claude better understand your goals and deliver more targeted responses.
6561 
66<Accordion title="Example: Formatting preferences">
62<Accordion title="Example: Formatting preferences" defaultOpen>
6763 **Less effective:**
6864 
6965 ```text wrap
from line 331
335331After completing a task that involves tool use, provide a quick summary of the work you've done.
336332```
337333 
338Claude Opus 5 is an exception on verbosity: its default user-facing responses run longer than prior models', and raising or lowering [effort](https://platform.claude.com/docs/en/build-with-claude/effort) does not reliably change visible response length. Prompt explicitly for conciseness instead. See [Prompting Claude Opus 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#response-length-and-verbosity) for a sample instruction.
334Claude Opus 5 is an exception on verbosity: its default user-facing responses run longer than prior models', and raising or lowering [effort](https://platform.claude.com/docs/en/build-with-claude/effort) does not reliably change visible response length. Prompt explicitly for conciseness instead. See [Prompting Claude Opus 5](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#response-length-and-verbosity) for a sample instruction. Claude Fable 5.1 has the opposite tendency during agentic work: it writes fewer user-facing updates between tool calls. Ask for progress text explicitly, and remove any instruction telling it to keep that text brief. See [Ask for user-facing progress updates](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#ask-for-user-facing-progress-updates).
339335 
340336### Control the format of responses
341337 
from line 376
380376</avoid_excessive_markdown_and_bullet_points>
381377````
382378 
379Claude Fable 5.1 already formats less than earlier models, so on that model a block like this can suppress structure the content needs. Remove it, or replace it with the shorter rule in [Formatting in chat](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#formatting-in-chat).
380 
383381### LaTeX output
384382 
385383Claude's latest models default to LaTeX for mathematical expressions, equations, and technical explanations. If you prefer plain text, add the following instructions to your prompt:
from line 443
445443 
446444For Claude to take action, be more explicit:
447445 
448<Accordion title="Example: Explicit instructions">
446<Accordion title="Example: Explicit instructions" defaultOpen>
449447 **Less effective (Claude will only suggest):**
450448 
451449 ```text wrap
from line 515
517515Execute operations sequentially with brief pauses between each step to ensure stability.
518516```
519517 
518On Claude Fable 5.1 in long agent loops, send the parallel-calls instruction as a turn-scoped system message after each round of tool results. See [Batch independent tool calls in agent loops](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#batch-independent-tool-calls-in-agent-loops).
519 
520520## Thinking and reasoning
521521 
522522### Overthinking and excessive thoroughness
from line 542
542542 
543543Claude's latest models offer thinking capabilities that can be especially helpful for tasks involving reflection after tool use or complex multistep reasoning. You can guide its initial or interleaved thinking for better results.
544544 
545Claude 4.6 and later models and Claude Mythos Preview use [adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking) (`thinking: {type: "adaptive"}`), where Claude dynamically decides when and how much to think. On Claude Fable 5 and Claude Mythos 5, thinking is always on and adaptive thinking is the only mode. Claude calibrates its thinking based on two factors: the `effort` parameter and query complexity. Higher effort elicits more thinking, and more complex queries do the same. On easier queries that don't require thinking, the model responds directly. In internal evaluations, adaptive thinking reliably drives better performance than extended thinking. Consider moving to adaptive thinking to get the most intelligent responses.
545Claude 4.6 and later models and Claude Mythos Preview use [adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking) (`thinking: {type: "adaptive"}`), where Claude dynamically decides when and how much to think. On Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, and Claude Mythos 5, thinking is always on and adaptive thinking is the only mode. Claude calibrates its thinking based on two factors: the `effort` parameter and query complexity. Higher effort elicits more thinking, and more complex queries do the same. On easier queries that don't require thinking, the model responds directly. In internal evaluations, adaptive thinking reliably drives better performance than extended thinking. Consider moving to adaptive thinking.
546546 
547547Use adaptive thinking for workloads that require agentic behavior such as multistep tool use, complex coding tasks, and long-horizon agent loops. Older models use manual [extended thinking](https://platform.claude.com/docs/en/build-with-claude/extended-thinking) with `budget_tokens`; see the [per-model configuration table](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#supported-models) for which configuration each model accepts.
548548 
from line 771
771771 ```
772772</CodeGroup>
773773 
774If you are not using extended thinking, no changes are required. On Claude Opus 4.6 through Claude Opus 4.8 and Claude Sonnet 4.6, thinking is off when you omit the `thinking` parameter. On Claude Opus 5 and Claude Sonnet 5, thinking is on by default when you omit the `thinking` parameter; on Claude Opus 5, you can disable it only at effort `high` or lower. On Claude Fable 5 and Claude Mythos 5, thinking is always on, regardless of whether you set the `thinking` parameter.
774If you are not using extended thinking, no changes are required. On Claude Opus 4.6 through Claude Opus 4.8 and Claude Sonnet 4.6, thinking is off when you omit the `thinking` parameter. On Claude Opus 5 and Claude Sonnet 5, thinking is on by default when you omit the `thinking` parameter. On Claude Opus 5, you can disable it only at effort `high` or lower. On Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, and Claude Mythos 5, thinking is always on, regardless of whether you set the `thinking` parameter.
775775 
776776* **Prefer general instructions over prescriptive steps.** A prompt like "think thoroughly" often produces better reasoning than a hand-written step-by-step plan. Claude's reasoning frequently exceeds what a human would prescribe.
777777* **Multishot examples work with thinking.** Use `<thinking>` tags inside your few-shot examples to show Claude the reasoning pattern. It will generalize that style to its own extended thinking blocks.
778778* **Manual chain-of-thought (CoT) prompting as a fallback.** When thinking is off, you can still encourage step-by-step reasoning by asking Claude to think through the problem. Use structured tags like `<thinking>` and `<answer>` to cleanly separate reasoning from the final output. On Claude Opus 5, prefer keeping thinking enabled at a lower effort level instead: with thinking disabled, the model can occasionally emit internal XML tags into its visible output, so see [Running with thinking disabled](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#running-with-thinking-disabled) before applying this pattern there.
779* **Ask Claude to self-check.** Append something like "Before you finish, verify your answer against \[test criteria]." This catches errors reliably, especially for coding and math. Claude Opus 5 is the exception: it verifies its own work well without explicit instruction, and verification instructions carried over from prompts tuned for earlier models can cause over-verification, adding tokens and latency. When migrating to Claude Opus 5, remove these instructions rather than rewriting them; see [Task scope and over-verification](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#task-scope-and-over-verification).
779* **Ask Claude to self-check.** Append something like "Before you finish, verify your answer against \[test criteria]." This catches errors reliably, especially for coding and math. Claude Opus 5 is the exception: it verifies its own work well without explicit instruction, and verification instructions carried over from prompts tuned for earlier models can cause over-verification, adding tokens and latency. When migrating to Claude Opus 5, remove these instructions rather than rewriting them. See [Task scope and over-verification](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#task-scope-and-over-verification).
780780 
781781<Note>
782782 When extended thinking is disabled, Claude Opus 4.5 is particularly sensitive to the word "think" and its variants. Consider using alternatives like "consider," "evaluate," or "reason through" in those cases.
from line 1080
10801080 
108110816. **Tune anti-laziness prompting:** If your prompts previously encouraged the model to be more thorough or use tools more aggressively, dial back that guidance. Claude 4.6 models are more proactive and may overtrigger on instructions that were needed for previous models.
10821082 
10837. **Pass thinking blocks back unchanged and keep history append-only:** Append each assistant turn exactly as the API returned it, thinking blocks included. On Claude Fable 5.1, [modifying the conversation before a thinking block](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation) results in an error, or in the block being dropped if you opt into that: editing earlier messages, rebuilding `system` or `tools`, or summarizing older turns in place between requests invalidates every later thinking block, so move those changes to mid-conversation system messages and server-side context management. See [Keep the conversation history append-only](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#keep-the-conversation-history-append-only).
1084 
10831085For detailed migration steps, see the [Migration guide](https://platform.claude.com/docs/en/about-claude/models/migration-guide).
10841086 
10851087### Migrating to Claude Sonnet 5 from Claude Sonnet 4.5 or earlier
from line 1091
10891091## Next steps
10901092 
10911093<CardGroup cols={2}>
1094 <Card title="Prompting Claude Fable 5.1" icon="terminal" href="https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1">
1095 Behavioral differences and prompting patterns for Claude Fable 5.1, covering effort, task completion, progress updates, thinking blocks, tool-call batching, and writing style.
1096 </Card>
1097 
10921098 <Card title="Prompting Claude Fable 5" icon="terminal" href="https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5">
10931099 Behavioral differences and prompting patterns for Claude Fable 5 and Claude Mythos 5, covering effort, instruction following, long runs, memory, and scaffolding changes.
10941100 </Card>

build-with-claude/refusals-and-fallback Changed · +65 / -67 lines

### Billing and rate limits ### Sticky routing ## Writing the retry yourself

from line 1
11---
22title: Refusals and fallback
33url: https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback
4description: How Claude Fable 5 and Claude Opus 5 return classifier refusals and how to retry refused requests on a fallback model.
4description: How Claude Fable and Claude Opus models return classifier refusals and how to retry refused requests on a fallback model.
55---
66 
7Claude Fable 5 and Claude Opus 5 include safety classifiers that can decline a request. When that happens, you receive a normal response, not an error, with `stop_reason: "refusal"`. You can usually still get an answer by sending the same request to another Claude model. This page shows you how to recognize a refusal and how to set up that retry.
7Claude Fable 5.1, Claude Fable 5, and Claude Opus 5 include safety classifiers that can decline a request. When that happens, you receive a normal response, not an error, with `stop_reason: "refusal"`. Its `stop_details.category` names the policy area (see [What a refusal looks like](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#refusal-response)). You can usually still get an answer by sending the same request to another Claude model. This page shows you how to recognize a refusal and how to set up that retry.
88 
9Read this page when you build on Claude Fable 5 or Claude Opus 5 and want declined requests to fall through to another model automatically. It also applies when you have just seen `"refusal"` in a response and want to know what to do next.
9Read this page when you build on any of these models and want declined requests to fall through to another model automatically. It also applies when you have seen `"refusal"` in a response and want to know what to do next.
1010 
1111Related pages:
1212 
1313* [Stop reasons and fallback](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons): the full list of `stop_reason` values.
14* [Fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit): how refused requests are billed, and how to avoid paying twice for prompt caching on a retry.
14* [Fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit): how to avoid paying the prompt-cache cost twice when you build the retry yourself.
1515* [SDK middleware](https://platform.claude.com/docs/en/cli-sdks-libraries/middleware): the SDK helper that wraps all of this.
1616* [Fallback and billing cookbook](https://platform.claude.com/cookbook/fable-5-fallback-billing-guide): a worked end-to-end example.
1717 
from line 177
177177 
178178* **`category`:** names the policy area that triggered the classifier.
179179* **`explanation`:** a human-readable description. The text is not stable, so display it rather than parse it.
180* Both fields are `null` when the refusal does not map to a named category. That `null` is a normal, permanent value, not a placeholder.
180* **`recommended_model`:** present only on requests that set `fallbacks` ([server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback), beta). It names a model to retry directly when the API skipped the fallback attempt (for example, the fallback model was rate limited), and is `null` otherwise. It's a hint, not a guarantee.
181* `category` and `explanation` are both `null` when the refusal does not map to a named category. That `null` is a normal, permanent value, not a placeholder.
181182* `stop_details` itself is `null` for every stop reason other than `refusal`.
182183 
183184| `category` | What it means |
from line 187
186187| `"bio"` | The request could enable biological harm, such as dangerous lab methods. Beneficial life sciences work can also trigger this category. |
187188| `"frontier_llm"` | The request could assist the development of competing AI models, which is restricted under [Anthropic's commercial terms](https://www.anthropic.com/legal/commercial-terms). Benign machine learning work can also trigger this category. |
188189| `"reasoning_extraction"` | The request asks the model to reproduce its internal reasoning in the response text. To get reasoning in a structured form instead, use [adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking). |
189| `"general_harms"` | The request could be related to an area that was determined as harmful. Benign work might sometimes trigger this category. |
190| `"general_harms"` | The request falls under a usage-policy area outside the four named categories. Benign work can also trigger this category. |
190191 
191192A refusal can arrive before any output, or mid-stream after partial output. In either case, treat any partial output as incomplete and discard it.
192193 
from line 199
198199 
199200There are three ways to retry a refused request on another model. The right one depends on where you are running and how much control you need.
200201 
201| Your situation | Use | Why |
202| ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------ | ----------------------------------------------------------- |
203| Claude API, simplest setup | [Server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback) | One request, one response. The API handles the retry. |
204| Any platform, using an Anthropic SDK | [The SDK middleware](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#client-side-fallback) | Configure once on the client. Retries happen automatically. |
205| Raw HTTP or custom retry logic | Manual retry with [fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit) | Full control. Fallback credit keeps the cost down. |
202| Your situation | Use | Why |
203| ------------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------- |
204| Claude API, simplest setup | [Server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback) | One request, one response. The API handles the retry. |
205| Any platform, using an Anthropic SDK | [The SDK middleware](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#client-side-fallback) | Configure once on the client. Retries happen automatically. |
206| Raw HTTP or custom retry logic | [A manual retry](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#manual-retry) with [fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit) | Full control. Fallback credit keeps the cost down. |
206207 
207208Server-side fallback and the SDK middleware apply fallback credit for you. You only need the [Fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit) page when you build the retry yourself.
208209 
209210## Server-side fallback
210211 
211Server-side fallback retries a refused request inside a single API call. In the default mode, when the primary model declines and the refusal category has a recommended fallback, the API runs the same request on the model Anthropic recommends for that category. You can instead name up to three fallback models of your own (below). Either way, you get back one response that names the model that answered, so your user gets an answer in one round trip.
212Server-side fallback retries a refused request inside a single API call. In the default mode, when the primary model declines and the refusal category has a recommended fallback, the API runs the same request on the model Anthropic recommends for that category. You can instead [name up to three fallback models of your own](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#naming-your-own-fallback-models). Either way, you get back one response that names the model that answered, so your user gets an answer in one round trip.
212213 
213214<Note>
214215 Server-side fallback is in beta on the Claude API. The `fallbacks` parameter is not supported on the [Message Batches API](https://platform.claude.com/docs/en/build-with-claude/batch-processing) (a batch item that includes it comes back as an errored result) and is not available on Amazon Bedrock, Google Cloud, or Microsoft Foundry. On those platforms, use [client-side fallback with the SDK middleware](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#client-side-fallback) instead.
from line 481
480481Only a safety classifier decline triggers the fallback. A rate limit, overload, or server error on the requested model is returned to you as-is.
481482 
482483<Note>
483 The beta header must carry exactly the date `2026-07-01`, which supports both `"default"` and the explicit-list form below, or `2026-06-01`, which accepts only the explicit-list form. Under any other `server-side-fallback-*` value, the `fallbacks` parameter is rejected with a 400 error. If you built against an earlier preview of this feature, update the beta header and the request and response shapes together to the ones on this page.
484 The beta header must carry exactly the date `2026-07-01`, which supports both `"default"` and the explicit-list form, or `2026-06-01`, which accepts only the explicit-list form. Under any other `server-side-fallback-*` value, the `fallbacks` parameter is rejected with a 400 error. If you built against an earlier preview of this feature, update the beta header and the request and response shapes together to the ones on this page.
484485</Note>
485486 
486487### Naming your own fallback models
from line 490
489490 
490491Named fallback models count toward the [oversized-image check](https://platform.claude.com/docs/en/build-with-claude/vision-coordinates#oversized-image-error): a request whose image block sets `"oversized_image": "error"` is checked up front against the requested model and every named fallback, is rejected if any of them would resize that image, and the rejection's reported rescale target fits them all.
491492 
493The highlighted lines are the only difference from the default-routing request.
494 
492495<CodeGroup>
493496 ```bash cURL
494497 curl --fail-with-body -sS https://api.anthropic.com/v1/messages \
from line 633
630633* Each entry names a `model` and can override `max_tokens`, `thinking`, `output_config`, and `speed` for that attempt only.
631634* The request must be valid as a direct request to every model named. If a fallback model does not support a feature the request uses, the API rejects the request up front.
632635* As with the default mode, only a safety classifier decline triggers the fallback. A rate limit, overload, or server error on the requested model is returned to you as-is.
636* If a fallback model is rate limited or overloaded, the fallback attempt is not made and the preceding refusal is returned instead. The refusal's `stop_details.recommended_model` then names a model to retry directly. Size the fallback model's rate limits for the refusal volume you expect, or fallbacks degrade to refusals under load.
633637 
634The explicit-list form also works under the `server-side-fallback-2026-06-01` beta header; the `"default"` mode does not.
635 
636638The response has the same shape in both modes: the model that served the turn appears in the top-level `model` field, a `fallback` content block marks the handoff, and `usage.iterations` records each attempt.
637639 
638640### What the response contains
from line 695
693695 
694696The `usage.iterations` array records every attempt. A model that declined appears as an ordinary `message` entry, and the model that served the turn appears as a `fallback_message` entry. If every model in the chain declines, the response is the last model's refusal, with a `message` entry for each earlier hop and a `fallback_message` entry for the last.
695697 
698[Sticky routing](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#sticky-routing) can send a later turn straight to the fallback model. Such a turn carries no `fallback` content block, because no model declined that turn. Identify it by the `fallback_message` entry in `usage.iterations`, the absence of a `message` entry for the requested model, and the response's `model` field.
699 
696700### Continuing the conversation
697701 
698On the next turn, send the assistant content back as you received it. After a mid-output fallback, `content` can include block types the declining model produced before the handoff; the following table covers which to keep and which to drop when you echo the turn.
702On the next turn, send the assistant content back as you received it. After a mid-output fallback, `content` can include block types the declining model produced before the handoff. The following table covers which to keep and which to drop when you echo the turn.
699703 
700704| Block type | On the next turn |
701705| -------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
from line 726
722726**When the decline happens mid-output:**
723727 
724728* The open content block closes, and the `fallback` block (an ordinary `content_block_start` and `content_block_stop` pair with no deltas) marks the boundary.
725* The fallback model continues from the partial output. Only the partial output's `text` blocks are passed to the fallback model as context; other block types remain in `content`.
729* The fallback model continues from the partial output. Only the partial output's `text` blocks are passed to the fallback model as context. Other block types remain in `content`.
726730* `message_start` already named the requested model, so read the serving model from the `fallback` block's `to.model` and from the `fallback_message` entry in the final `message_delta`'s `usage.iterations`.
727731 
728732### Non-streaming responses
from line 737
733737 **Declines during tool use:** completed tool work does not block fallback. When a decline fires after server tools (for example, web search or code execution) have finished executing within a request, the fallback attempt proceeds: the completed tool results carry over, and the fallback model can keep invoking server tools. The one case that does not retry is a streaming decline that fires while a tool-use block of any type (a client tool, a server tool, or an MCP tool call) is still open on the stream: that refusal is returned directly, and if the `fallback-credit-2026-07-01` header is set it still carries a credit token redeemable by continuing the partial response. Non-streaming requests are unaffected; the API clears the partial work and retries before responding.
734738</Note>
735739 
736<Accordion title="Sticky routing">
737 After a conversation falls back, the API records which model served it. Later requests for that conversation that include `fallbacks` go directly to that fallback model, without running the requested model. This avoids paying for an attempt that would predictably be declined again on every turn.
740### Billing and rate limits
738741 
739 A few properties of the routing decision:
742An attempt that declined before producing any output is not billed: its tokens are reported on its `usage.iterations` entry but not charged. Every attempt that produced output, including one that declined partway through its response, is billed separately at the rates of the model that ran it. The `usage.iterations` array is the per-attempt record of what you're billed. The top-level `usage` counts describe only the attempt that produced the returned message. Tokens from different models are never summed into one field.
740743 
741 * It is retained for approximately 1 hour and is scoped to your organization.
742 * It is stored as a content hash of the conversation prefix plus the model that served it. The message content itself is not stored.
743 * It is best-effort, so your code must handle the requested model being tried again at any time.
744Every attempt that runs, including one that declined, counts against its own model's rate limits.
744745 
745 A sticky-served turn carries no `fallback` content block, because no model declined that turn. Identify it by the `fallback_message` entry in `usage.iterations`, the absence of a `message` entry for the requested model, and the response's `model` field.
746### Sticky routing
746747 
747 Sticky routing applies to both streaming and non-streaming requests. On a streaming request, the routing decision is made before the stream opens, so the `message_start` event's `model` field already carries the fallback model's ID.
748</Accordion>
748After a conversation falls back, the API records which model served it. Later requests for that conversation that include `fallbacks` go directly to that fallback model, without running the requested model. This avoids paying for an attempt that would predictably be declined again on every turn.
749749 
750<Accordion title="How server-side fallback is billed">
751 You pay for the model that actually serves the request. An attempt that declined before producing output is not billed: its tokens are reported on its `usage.iterations` entry but not charged. Declined attempts still count against rate limits (see below).
750A few properties of the routing decision:
752751 
753 Each attempt is billed separately, at the rates of the model that ran it. The `usage.iterations` array is the per-attempt record of what you are billed. The top-level `usage` counts describe only the attempt that produced the returned message; tokens from different models are never summed into one field.
752* It is retained for approximately 1 hour and is scoped to your organization.
753* It is stored as a content hash of the conversation prefix plus the model that served it. The message content itself is not stored.
754* It is best-effort, so your code must handle the requested model being tried again at any time.
754755 
755 Each attempt that runs counts against its own model's rate limits. If the fallback model is rate limited or overloaded, the fallback attempt is not made and the preceding refusal is returned instead. Size the fallback model's rate limits for the refusal volume you expect, or fallbacks degrade to refusals under load.
756Sticky routing applies to both streaming and non-streaming requests. On a streaming request, the routing decision is made before the stream opens, so the `message_start` event's `model` field already carries the fallback model's ID.
756757 
757 When a fallback attempt is skipped this way, `stop_details.recommended_model` names a model to retry directly. The recommendation is a hint, not a guarantee, and it is `null` when no recommendation is available.
758</Accordion>
759 
760758## Client-side fallback with the SDK middleware
761759 
762760Every Anthropic SDK includes a refusal-fallback middleware. You configure it once on the client with your list of fallback models. Calls through `client.beta.messages` then retry refused requests automatically, on any platform. The middleware also sends the `fallback-credit-2026-07-01` beta header on every request it handles, so retries are repriced without per-request setup.
from line 1109
11111109 
11121110* Retries walk your fallback list in order. A fallback model that itself refuses passes the request to the next entry.
11131111* When every model in the list has declined, the middleware returns the final refusal (the last model's refusal response) rather than raising an error.
1114* [Thinking blocks from Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-output-on-claude-fable-5-and-claude-mythos-5) pass through unchanged: each retry re-sends your original request body, and the only blocks the middleware removes from conversation history on later requests are the `fallback` boundary blocks it added itself.
1112* Thinking blocks from Claude Fable 5.1 or Claude Fable 5 pass through unchanged. Each retry re-sends your original request body, and the only blocks the middleware removes from conversation history on later requests are the `fallback` boundary blocks it added itself. The fallback model can't read Claude Fable 5.1 blocks, which are [preserved only for that model or a newer one](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-for-model), so the API drops them.
11151113* Responses served through the middleware include a `fallback` content block at each model boundary, the same as server-side fallback responses. The middleware manages those blocks for you on later requests.
11161114* The model that accepted is recorded in `BetaFallbackState`, so follow-up requests that share the state stay pinned to it rather than re-asking a model that refused.
11171115 
from line 1117
11191117 The middleware and the server-side `fallbacks` parameter do the same job. Configure one or the other, never both on the same request. To send a server-side `fallbacks` request from an application that installs the middleware, use a separate client instance without it.
11201118</Note>
11211119 
1122<Accordion title="Writing the retry yourself">
1123 Over raw HTTP or with custom retry logic, implement the pattern the middleware wraps:
1120## Writing the retry yourself
11241121 
1125 <Steps>
1126 <Step title="Detect the refusal">
1127 Check the response for `stop_reason: "refusal"`.
1128 </Step>
1122Over raw HTTP or with custom retry logic, implement the pattern the middleware wraps:
11291123 
1130 <Step title="Re-send on a fallback model">
1131 Send the same request with `model` set to a fallback model, such as Claude Opus 4.8. A request that Claude Fable 5's classifiers decline can normally be served by another model. How you handle the conversation history depends on whether you redeem a [fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit):
1124<Steps>
1125 <Step title="Detect the refusal">
1126 Check the response for `stop_reason: "refusal"`.
1127 </Step>
11321128 
1133 * **Not redeeming a credit:** you can first strip the [thinking blocks from Claude Fable 5](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-output-on-claude-fable-5-and-claude-mythos-5) out of the conversation history. Other models ignore them, and stripping keeps cross-model requests minimal.
1134 * **Redeeming a credit:** send the body unchanged, because redemption requires an exact match.
1135 </Step>
1129 <Step title="Re-send on a fallback model">
1130 Send the same request with `model` set to a fallback model, such as Claude Opus 4.8. Another model can normally serve a request that Claude Fable 5.1 or Claude Fable 5 declines. How you handle the conversation history depends on whether you redeem a [fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit):
11361131 
1137 <Step title="Stay on the fallback model">
1138 For multi-turn conversations, keep using the fallback model for subsequent turns rather than switching back.
1139 </Step>
1140 </Steps>
1132 * **Not redeeming a credit:** you can leave the earlier `thinking` and `redacted_thinking` blocks in place or strip them to save input tokens. The fallback model cannot use them either way: it ignores Claude Fable 5 blocks, and Claude Fable 5.1 blocks are [preserved only for that model or a newer one](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-for-model), so the API drops them.
1133 * **Redeeming a credit:** send the body unchanged, because redemption requires an exact match. The server handles the earlier model's thinking blocks on a redemption, so do not strip them (see [Fields that must match the refused request](https://platform.claude.com/docs/en/build-with-claude/fallback-credit#reference)).
1134 </Step>
11411135 
1142 A manual retry writes the fallback model's prompt cache from scratch, which costs more than reading an existing cache. [Fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit) refunds that cost; redeem it on every retry you build yourself.
1143</Accordion>
1136 <Step title="Stay on the fallback model">
1137 For multi-turn conversations, keep using the fallback model for subsequent turns rather than switching back.
1138 </Step>
1139</Steps>
11441140 
1141A manual retry writes the fallback model's prompt cache from scratch, which costs more than reading an existing cache. [Fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit) refunds that cost; redeem it on every retry you build yourself.
1142 
11451143## Refusals in Message Batches
11461144 
11471145A refused request in a [Message Batch](https://platform.claude.com/docs/en/build-with-claude/batch-processing) comes back as `result.type: "succeeded"` with `stop_reason: "refusal"`. Batch results carry the same `stop_details` object as synchronous responses, so you can detect refusals through either `stop_reason` or `stop_details.type`. One difference: batch refusals don't mint fallback credits, so `stop_details` on a batch result never includes a `fallback_credit_token`.
from line 1147
11491147Server-side fallback is not available for batches (a batch request that includes `fallbacks` produces a per-item errored result). To retry refused batch items:
11501148 
115111491. Collect the refused items from the results.
11522. Strip Claude Fable 5's thinking blocks from any multi-turn histories.
11502. Strip the Claude Fable 5.1 or Claude Fable 5 thinking blocks from any multi-turn histories.
115311513. Resubmit them on a fallback model as a new batch or as direct requests.
11541152 
11551153## Common pitfalls
from line 1175
11771175 How SDK middleware works, including the refusal-fallback helper.
11781176 </Card>
11791177 
1180 <Card title="Migration guide" icon="arrow-right" href="https://platform.claude.com/docs/en/models/fable-5/migration-guide">
1181 Move an existing application to Claude Fable 5.
1178 <Card title="Migration guide" icon="arrow-right" href="https://platform.claude.com/docs/en/models/fable-5-1/migration-guide">
1179 Move an existing application to Claude Fable 5.1.
11821180 </Card>
11831181</CardGroup>
11841182 

build-with-claude/task-budgets Changed · +5 / -3 lines

from line 7
77## Compatibility
88- Status: Beta
99- [Beta header](https://platform.claude.com/docs/en/api/beta-headers): `task-budgets-2026-03-13`
10- Supported models: `claude-fable-5`, `claude-mythos-5`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`
10- Supported models: `claude-fable-5-1`, `claude-mythos-5-1`, `claude-fable-5`, `claude-mythos-5`, `claude-opus-5`, `claude-opus-4-8`, `claude-opus-4-7`
1111 
1212Task budgets let you tell Claude how many tokens it has for a full agentic loop, including thinking, tool calls, tool results, and output. The model sees a running countdown and uses it to prioritize work and finish gracefully as the budget is consumed.
1313 
from line 587
587587 
588588Run this across a representative set of tasks and record the distribution. Start with the p99 of your per-task token spend to understand how providing the model with a task budget might modify the model's behavior, then test up or down as needed.
589589 
590The minimum accepted `task_budget.total` is model-specific; on every model that currently supports task budgets (see [Feature support](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support)) it is **20,000 tokens**, and values below the minimum return a 400 error.
590The minimum accepted `task_budget.total` is model-specific. On every model that supports task budgets (see [Feature support](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support)) it is **20,000 tokens**, and smaller values return a 400 error.
591591 
592592## Interaction with other parameters
593593 
594594* **`max_tokens`:** Orthogonal to task budgets. `max_tokens` is a hard per-request cap on generated tokens, while `task_budget` is an advisory cap across the full agentic loop (potentially spanning many requests). At `xhigh` or `max` effort, set `max_tokens` to at least 64k to give Claude room to think and act on each request.
595595* **[Effort](https://platform.claude.com/docs/en/build-with-claude/effort):** Effort controls how deeply Claude reasons per step. Task budgets control how much total work Claude does across an agentic loop. The two are complementary: effort tunes depth, task budgets tune breadth.
596* **[Adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking):** Task budgets include thinking tokens in the count, so adaptive thinking naturally scales down as the budget depletes.
596* **[Adaptive thinking](https://platform.claude.com/docs/en/build-with-claude/thinking):** Task budgets include thinking tokens in the count, so adaptive thinking scales down as the budget depletes.
597597* **[Prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching):** The budget-countdown marker is injected server-side per turn, so it does not match across requests. If your client decrements `task_budget.remaining` on each follow-up request, the changed value invalidates any cache prefix that contains it. To preserve caching, set the budget once on the initial request and let the model self-regulate against the server-side countdown rather than mutating the budget client-side.
598598 
599599## Feature support
from line 600
600600 
601601| Model | Support |
602602| ----------------- | ------------------------------------------- |
603| Claude Fable 5.1 | Beta (set `task-budgets-2026-03-13` header) |
604| Claude Mythos 5.1 | Beta (set `task-budgets-2026-03-13` header) |
603605| Claude Opus 5 | Beta (set `task-budgets-2026-03-13` header) |
604606| Claude Fable 5 | Beta (set `task-budgets-2026-03-13` header) |
605607| Claude Mythos 5 | Beta (set `task-budgets-2026-03-13` header) |

build-with-claude/thinking Changed · +504 / -37 lines

### Progress updates between tool calls ## Preserved thinking ### Only for the model that produced it, or a newer one ### Only in the conversation that produced it ### Controls for blocks that aren't preserved (beta) ### Sampling parameters ### Response prefill and forced tool use ### Output limits ### Long requests ## Thinking output on Claude Fable 5 and Claude Mythos 5

The two sides of this change are more than 400 edits apart, too far apart to line up, so this is the differ's own diff of it and the words inside a line are not marked.

from line 38
3838}
3939```
4040 
41You don't always see this text, and what you see is never the raw chain of thought: the text in a thinking block is a [summary of Claude's reasoning](https://platform.claude.com/docs/en/build-with-claude/thinking#summarized-thinking). The `display` field on the thinking configuration controls whether that summary is returned at all: `"summarized"` returns it, while `"omitted"`, the default on the newest models, returns thinking blocks with an empty `thinking` field. Either way the block is billed the same and passed back the same in multi-turn conversations. See [Controlling thinking display](https://platform.claude.com/docs/en/build-with-claude/thinking#controlling-thinking-display) for per-model defaults and details.
41You don't always see this text, and what you see is never the raw chain of thought: the text in a thinking block is a [summary of Claude's reasoning](https://platform.claude.com/docs/en/build-with-claude/thinking#summarized-thinking). The `display` field on the thinking configuration controls whether that summary is returned at all: `"summarized"` returns it, while `"omitted"`, the default on many models, returns thinking blocks with an empty `thinking` field. Either way the block is billed the same and passed back the same in multi-turn conversations. See [Controlling thinking display](https://platform.claude.com/docs/en/build-with-claude/thinking#controlling-thinking-display) for per-model defaults and details.
4242 
4343If Claude uses tools, thinking can also appear between tool calls. See [Thinking with tool use](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-with-tool-use). For the full response format, see the [Messages API reference](https://platform.claude.com/docs/en/api/messages/create).
4444 
4545## Configuring thinking
4646 
47On current models, thinking is on by default or one parameter away. Which configuration each model accepts, and what it defaults to, is listed in the [per-model configuration table](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#supported-models) on the Troubleshooting page.
48 
49On Claude Opus 5, Claude Sonnet 5, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview, thinking is already on: no configuration needed. The first thing most developers need on these models is to see the thinking text, because `display` defaults to `"omitted"` there. Opt in with `thinking: {"type": "adaptive", "display": "summarized"}`, which is exactly the following request with the [model string](https://platform.claude.com/docs/en/models/overview) swapped.
47On most models, thinking is on by default or one parameter away. Which configuration each model accepts, and what it defaults to, is listed in the [per-model configuration table](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#supported-models) on the Troubleshooting page.
48 
49On Claude Opus 5, Claude Sonnet 5, Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview, thinking is already on and needs no configuration. `display` defaults to `"omitted"` on these models, so the thinking text is hidden until you opt in. Opt in with `thinking: {"type": "adaptive", "display": "summarized"}`, which is exactly the following request with the [model string](https://platform.claude.com/docs/en/models/overview) swapped.
5050 
5151On Claude Opus 4.8, Claude Opus 4.7, Claude Opus 4.6, and Claude Sonnet 4.6, thinking is off until you set `thinking: {type: "adaptive"}`, which lets Claude decide when and how deeply to think based on the request. The following examples do that, set `display: "summarized"` so the thinking text is visible, and use a roomy `max_tokens`:
5252 
from line 430
430430 
431431Claude Opus 5 also has thinking on by default and accepts `thinking: {type: "disabled"}` at [effort](https://platform.claude.com/docs/en/build-with-claude/effort) `high` or below. At `xhigh` or `max` effort, thinking cannot be turned off: requests that combine `thinking: {type: "disabled"}` with those effort levels return a 400 error. This restriction applies to Claude Opus 5 and later models and is enforced on each request. With thinking disabled, Claude Opus 5 can occasionally emit tool calls as plain text or include internal XML tags in its visible output. See [Running with thinking disabled](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5#running-with-thinking-disabled) for prompting mitigations.
432432 
433Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview reject `thinking: {type: "disabled"}`: thinking cannot be turned off on these models.
433Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview reject `thinking: {type: "disabled"}`. Thinking can't be turned off on these models.
434434 
435435If your model supports only extended thinking (see the [per-model configuration table](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting#supported-models)), configure it with `type: "enabled"` and a `budget_tokens` value instead. The [Extended thinking](https://platform.claude.com/docs/en/build-with-claude/extended-thinking) page covers that configuration. And if any thinking configuration comes back with a 400 error, [Troubleshooting thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting) matches each error message to its fix.
436436 
from line 438
438438 
439439### Controlling thinking display
440440 
441The `display` field on the thinking configuration controls how thinking content is returned in API responses. `display` works in both modes: set it alongside `type: "adaptive"` or `type: "enabled"`. It accepts two values:
441The `display` field on the thinking configuration controls how thinking content is returned in API responses. `display` works in both modes: set it alongside `type: "adaptive"` or `type: "enabled"`. It accepts these values:
442442 
443443* `"summarized"`: thinking blocks contain [summarized thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#summarized-thinking) text, a readable summary of Claude's reasoning. This is the default on Claude Opus 4.6, Claude Sonnet 4.6, and earlier models.
444* `"omitted"`: thinking blocks are returned with an empty `thinking` field. The `signature` field still carries the encrypted full thinking for multi-turn continuity (see [Thinking encryption](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-encryption)). This is the default on Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Sonnet 5, Claude Opus 4.8, Claude Opus 4.7, and [Claude Mythos Preview](https://anthropic.com/glasswing).
444* `"omitted"`: thinking blocks are returned with an empty `thinking` field. The `signature` field still carries the encrypted full thinking for multi-turn continuity (see [Thinking encryption](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-encryption)). This is the default on Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Opus 5, Claude Sonnet 5, Claude Opus 4.8, Claude Opus 4.7, and [Claude Mythos Preview](https://anthropic.com/glasswing).
445* `"updates"` (beta): reasoning blocks are returned with an empty `thinking` field, as with `"omitted"`, and the short [progress updates](https://platform.claude.com/docs/en/build-with-claude/thinking#progress-updates) some models write between tool calls come back as readable text. Requires the beta header `thinking-display-updates-2026-08-18`.
445446 
446447Set `display: "omitted"` when your application doesn't surface thinking content to users. The primary benefit is faster time-to-first-text-token when streaming: the server skips streaming thinking tokens entirely and delivers only the signature, so the final text response begins streaming sooner.
447448 
from line 470
469470* If you pass thinking blocks back in multi-turn conversations, pass them unchanged. The server decrypts the `signature` to reconstruct the original thinking for prompt construction (see [Preserving thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#preserving-thinking-blocks)). Any text you place in the `thinking` field of a round-tripped omitted block is ignored.
470471* `display` is invalid with `thinking.type: "disabled"` (there is nothing to display).
471472* When using `thinking.type: "adaptive"` and the model skips thinking for a simple request, no thinking block is produced regardless of `display`.
472* When streaming with `display: "omitted"`, no `thinking_delta` events are emitted. See [Streaming thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#streaming-thinking) for the event sequence.
473* When streaming with `display: "omitted"`, no `thinking_delta` events are emitted. With `display: "updates"`, only [progress-update blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#progress-updates) stream `thinking_delta` events. See [Streaming thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#streaming-thinking) for the event sequence.
473474 
474475<Note>
475 The `signature` field is identical whether `display` is `"summarized"` or `"omitted"`. Switching `display` values between turns in a conversation is supported.
476 The `signature` field is identical whichever `display` value you set. Switching `display` values between turns in a conversation is supported.
476477</Note>
477478 
478479In the Ruby SDK, plain hashes take `display:` as the examples show. The typed `ThinkingConfigAdaptive` class names the parameter `display_` (trailing underscore, to avoid shadowing Ruby's `Kernel#display`). Either way, the wire field is still `display`.
from line 494
493494 In rare cases where you need access to full thinking output, [contact Anthropic sales](mailto:[email protected]).
494495</Note>
495496 
497To see the model's reasoning, read the `thinking` blocks rather than prompting for reasoning in the response text. On Claude Fable 5.1 and Claude Fable 5, a request that attempts to elicit the model's internal reasoning as part of the response text can be refused with `stop_details.category: "reasoning_extraction"`. See [Refusal categories](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#refusal-response) for the field reference and handling guidance.
498 
496499### Streaming thinking
497500 
498501Thinking works with [streaming](https://platform.claude.com/docs/en/build-with-claude/streaming). Thinking blocks stream as `thinking_delta` events inside `content_block_delta` events, followed by a single `signature_delta` event just before the block's `content_block_stop`. Text blocks stream afterward as usual.
499502 
500![Diagram of the streaming event sequence with thinking: the thinking block opens, thinking deltas stream only when display is summarized, a single signature delta closes the block, then text deltas stream](https://platform.claude.com/docs/images/how-thinking-streams.svg)
503![Diagram of the streaming event sequence with thinking: the thinking block opens, thinking deltas stream only when the display setting returns text (summarized, or updates for progress-update blocks), a single signature delta closes the block, then text deltas stream](https://platform.claude.com/docs/images/how-thinking-streams.svg)
501504 
502505The following examples stream a response with adaptive thinking, printing thinking and text deltas as they arrive:
503506 
from line 796
793796data: {"type":"content_block_start","index":1,"content_block":{"type":"text","text":""}}
794797```
795798 
799With `display: "updates"` (beta), reasoning blocks stream as they do under `"omitted"`. Each [progress-update block](https://platform.claude.com/docs/en/build-with-claude/thinking#progress-updates) streams its text as `thinking_delta` events before the `tool_use` block it introduces. A pause of several seconds before the progress-update block opens is normal:
800 
801```sse Output
802event: content_block_start
803data: {"type":"content_block_start","index":1,"content_block":{"type":"thinking","thinking":"","signature":""}}
804 
805event: content_block_delta
806data: {"type":"content_block_delta","index":1,"delta":{"type":"thinking_delta","thinking":"Confirmed the retry path never refreshes the expired token. Editing auth.py to add the refresh call."}}
807 
808event: content_block_delta
809data: {"type":"content_block_delta","index":1,"delta":{"type":"signature_delta","signature":"Es8CCkYICxIM..."}}
810 
811event: content_block_stop
812data: {"type":"content_block_stop","index":1}
813 
814event: content_block_start
815data: {"type":"content_block_start","index":2,"content_block":{"type":"tool_use","id":"toolu_01D7FLrfh4GYq7yT1ULFeyMV","name":"edit_file","input":{}}}
816```
817 
818Under `"updates"`, treat a block as a progress update as soon as one of its `thinking_delta` events carries non-empty text.
819 
796820<Note>
797821 When using streaming with thinking enabled, you might notice that text sometimes arrives in larger chunks alternating with smaller, token-by-token delivery. This is expected behavior, especially for thinking content.
798822 
from line 842
818842 
819843Thinking works alongside [tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/overview), letting Claude reason through tool selection and process tool results. Two constraints apply:
820844 
8211. **Tool choice limitation (manual mode):** tool use with manual extended thinking (`thinking: {type: "enabled"}`) only supports `tool_choice: {"type": "auto"}` (the default) or `tool_choice: {"type": "none"}`. Using `tool_choice: {"type": "any"}` or `tool_choice: {"type": "tool", "name": "..."}` results in an error because these options force tool use, which is incompatible with manual extended thinking. Adaptive thinking, including on models where thinking is on by default, supports forced tool use.
8451. **Tool choice limitation (manual mode):** tool use with manual extended thinking (`thinking: {type: "enabled"}`) only supports `tool_choice: {"type": "auto"}` (the default) or `tool_choice: {"type": "none"}`. Using `tool_choice: {"type": "any"}` or `tool_choice: {"type": "tool", "name": "..."}` results in an error because these options force tool use, which is incompatible with manual extended thinking. Adaptive thinking, including on models where thinking is on by default, supports forced tool use, except on Claude Fable 5.1 and Claude Mythos 5.1 (see [Response prefill and forced tool use](https://platform.claude.com/docs/en/build-with-claude/thinking#limits-and-feature-compatibility)).
8228462. **Preserving thinking blocks:** when you return tool results, you must pass the thinking blocks from the assistant message back to the API, complete and unmodified. See [Preserving thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#preserving-thinking-blocks).
823847 
824848**A tool-use loop is one assistant turn.** From the model's perspective, an assistant turn doesn't complete until Claude finishes its full response, which may include multiple tool calls and results. This whole sequence is a single assistant turn:
from line 906
882906 Consecutive tool calls do not require interleaved thinking. Claude can chain tool calls with or without interleaved thinking. Interleaving changes where thinking blocks appear between tool calls, not whether tool calls can chain.
883907</Note>
884908 
885With adaptive thinking, interleaved thinking is automatic on every model that supports adaptive thinking. No beta header is needed. On Claude Fable 5, Claude Mythos 5, Claude Mythos Preview, Claude Opus 5, Claude Opus 4.8, and Claude Opus 4.7, reasoning between tool calls always appears in thinking blocks. Claude Haiku 4.5 does not support interleaved thinking. On models using manual extended thinking, interleaving requires a beta header and changes how the thinking budget is counted. [Interleaved thinking in manual mode](https://platform.claude.com/docs/en/build-with-claude/extended-thinking#interleaved-thinking) covers the per-model rules and platform-specific header behavior.
909With adaptive thinking, interleaved thinking is automatic on every model that supports adaptive thinking. No beta header is needed. On Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Mythos Preview, Claude Opus 5, Claude Opus 4.8, and Claude Opus 4.7, reasoning between tool calls always appears in thinking blocks. Claude Haiku 4.5 does not support interleaved thinking. On models using manual extended thinking, interleaving requires a beta header and changes how the thinking budget is counted. [Interleaved thinking in manual mode](https://platform.claude.com/docs/en/build-with-claude/extended-thinking#interleaved-thinking) covers the per-model rules and platform-specific header behavior.
886910 
887911With interleaved thinking, the thinking allocation can span the entire assistant turn rather than a single response. Interleaved thinking is only supported for [tools used through the Messages API](https://platform.claude.com/docs/en/agents-and-tools/tool-use/overview).
888912 
889913For a worked comparison showing what interleaved thinking changes in a two-tool workflow, see [How interleaved thinking changes the flow](https://platform.claude.com/docs/en/build-with-claude/thinking-tool-workflows#how-interleaved-thinking-changes-the-flow).
890914 
915### Progress updates between tool calls
916 
917On Claude Fable 5.1, Claude Mythos 5.1, and Claude Fable 5, the model can write a progress update between tool calls. A progress update is a sentence or two on what the model just found and what it's about to do next, written for the person watching the agent rather than as reasoning. Each one comes back as its own `thinking` block with its own `signature`, separate from any reasoning block at the same point. It sits immediately before the `tool_use` or `server_tool_use` block it introduces. At most one progress update precedes each tool call, and the model can skip any of them. Progress updates aren't [interleaved thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#interleaved-thinking): they appear whether or not reasoning blocks appear between tool calls, and a response can contain both.
918 
919What a progress-update block contains depends on [`display`](https://platform.claude.com/docs/en/build-with-claude/thinking#controlling-thinking-display):
920 
921| `display` | Reasoning blocks | Progress-update blocks |
922| ----------------------------------------- | ---------------------- | -------------------------------------------------------- |
923| `"omitted"` (the default on these models) | Empty `thinking` field | Empty `thinking` field |
924| `"updates"` (beta) | Empty `thinking` field | Summary text |
925| `"summarized"` | Summary text | Summary text, not distinguishable from a reasoning block |
926 
927Use `display: "updates"` for an agent interface that keeps reasoning hidden and shows the user a status line at each step. Under it, any `thinking` block with non-empty text is a progress update, so render those and nothing else. It's in beta and requires the beta header `thinking-display-updates-2026-08-18` (on Amazon Bedrock, Google Cloud, and Microsoft Foundry, pass the beta value as described in [Beta headers](https://platform.claude.com/docs/en/api/beta-headers)). Without it, the value is rejected with the same 400 `invalid_request_error` as an unknown `display` value.
928 
929```json
930{
931 "model": "claude-fable-5-1",
932 "max_tokens": 16000,
933 "thinking": { "type": "adaptive", "display": "updates" },
934 "tools": [
935 {
936 "name": "edit_file",
937 "description": "Replace the contents of a file in the repository.",
938 "input_schema": {
939 "type": "object",
940 "properties": {
941 "path": { "type": "string" },
942 "content": { "type": "string" }
943 },
944 "required": ["path", "content"]
945 }
946 }
947 ],
948 "messages": [
949 {
950 "role": "user",
951 "content": "The login test fails after an hour of uptime. Find out why and fix it."
952 }
953 ]
954}
955```
956 
957Under `"updates"`, the start of the response that follows a `tool_result` looks like this. The first block is reasoning and stays empty, as it would under `"omitted"`. The second carries text, so it's a progress update. Under `"summarized"` both blocks carry text, and under `"omitted"` both are empty.
958 
959```json Output
960{
961 "content": [
962 {
963 "type": "thinking",
964 "thinking": "",
965 "signature": "EqMBCkYICxIM..."
966 },
967 {
968 "type": "thinking",
969 "thinking": "Confirmed the retry path never refreshes the expired token. Editing auth.py to add the refresh call.",
970 "signature": "Es8CCkYICxIM..."
971 },
972 {
973 "type": "tool_use",
974 "id": "toolu_01D7FLrfh4GYq7yT1ULFeyMV",
975 "name": "edit_file",
976 "input": { "path": "auth.py", "content": "..." }
977 }
978 ]
979}
980```
981 
982Keep the following in mind when working with progress updates:
983 
984* Pass progress-update blocks back unchanged with the rest of the assistant turn, like any other `thinking` block.
985* The text you receive is a summary of the progress update, normally a sentence or two. Don't rely on its length. The progress update counts toward `usage.output_tokens` at its full length, not the summary's.
986* A progress-update block can come back with an empty `thinking` field under any `display` value. Render nothing for an empty block. Under `"updates"` it looks the same as an empty reasoning block and needs no separate handling.
987* When a response stops on `max_tokens`, `model_context_window_exceeded`, or `stop_sequence` soon after a tool call or tool result, its last block can be a progress-update block standing in for the work the model hadn't finished. Under `"updates"` and `"summarized"` its text is exactly `This part of the response was interrupted before it finished.` and you can show it like any other update. Under `"omitted"` it's empty. To continue, pass the assistant turn back unchanged and append a new `user` message (with a `tool_result` for each `tool_use` block in that turn).
988* When [streaming](https://platform.claude.com/docs/en/build-with-claude/thinking#streaming-thinking), expect a pause of several seconds before a progress-update block opens. See the `"updates"` trace in [Streaming thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#streaming-thinking).
989* These models write fewer progress updates at higher [effort](https://platform.claude.com/docs/en/build-with-claude/effort) and in long tool chains. If your interface depends on them, see [Ask for user-facing progress updates](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5-1#ask-for-user-facing-progress-updates).
990 
891991### Thinking block preservation by model
892992 
893993Whether thinking blocks from previous assistant turns stay in context by default depends on the model:
894994 
895* **Keep all prior turns:** Claude Opus 4.5 and later Opus models, Claude Sonnet 4.6 and later Sonnet models, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview.
995* **Keep all prior turns:** Claude Opus 4.5 and later Opus models, Claude Sonnet 4.6 and later Sonnet models, Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, and Claude Mythos Preview.
896996* **Keep the last turn only:** earlier Opus and Sonnet models, and all Haiku models through Claude Haiku 4.5. When you pass older thinking blocks back, the API strips them automatically. You don't need to remove them yourself.
897997 
898998Preservation brings two benefits:
from line 1002
9021002 
9031003The tradeoff is context usage: long conversations consume more context space on keep-all models, because retained thinking blocks count as input like any other conversation history (see [Thinking and the context window](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-and-the-context-window)). The behavior is automatic in both regimes. No code changes or beta headers are required, and you should keep passing complete, unmodified thinking blocks back as described in [Preserving thinking blocks](https://platform.claude.com/docs/en/build-with-claude/thinking#preserving-thinking-blocks). To override the default in either direction, use [thinking block clearing](https://platform.claude.com/docs/en/build-with-claude/context-editing#thinking-block-clearing).
9041004 
905**Switching models mid-conversation.** When you switch between any two models, for example after a [classifier refusal fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback), strip `thinking` and `redacted_thinking` blocks from prior assistant turns. Thinking blocks are tied to the model that produced them. Other models silently ignore them rather than rejecting the request, but ignored blocks still add input tokens.
1005**Switching models mid-conversation.** Keep passing thinking blocks back unchanged when you switch models, for example after a [classifier refusal fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback). A thinking block is readable only by the model that produced it or a newer one, and the API ignores or drops the blocks the target model can't read. On Claude Fable 5.1 and Claude Mythos 5.1 the direction matters: they read every earlier model's thinking blocks and no earlier model reads theirs, so switching up to them keeps the conversation's reasoning and switching down drops it (see [Preserved thinking](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-for-model) for the exact list and for how dropped blocks are billed and reported). Strip prior `thinking` and `redacted_thinking` blocks yourself only to save input tokens on models that ignore rather than drop them, and never when redeeming a [fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit), which requires the body unchanged.
1006 
1007## Preserved thinking
1008 
1009Claude preserves a thinking block, keeping it usable on later turns, only under the conditions it was created in. Starting with Claude Fable 5.1 and Claude Mythos 5.1, a `thinking` or `redacted_thinking` block is preserved only:
1010 
1011* **For the model that produced it, or a newer one.** An earlier model can't use the block, and the API drops it from that request. See [Only for the model that produced it, or a newer one](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-for-model).
1012* **In the conversation that produced it (Claude Fable 5.1 only).** If the `system` prompt, the `tools`, or any earlier message changes, the block is no longer valid, and the API rejects the request or drops the block. See [Only in the conversation that produced it](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation).
1013 
1014The block's `signature` records both conditions on both models. The API checks it whenever the block comes back in a later request, including a request to a different model; Claude Mythos 5.1 checks only the model condition.
1015 
1016**Pass blocks back unchanged.** Send every assistant turn exactly as you received it, thinking blocks included, and let the API decide which blocks the model can use.
1017 
1018### Only for the model that produced it, or a newer one
1019 
1020This condition is one-way: Claude Fable 5.1 and Claude Mythos 5.1 read earlier models' thinking blocks, and no earlier model reads theirs.
1021 
1022* **A conversation that moves onto Claude Fable 5.1 or Claude Mythos 5.1 keeps its reasoning.** The earlier model's thinking blocks stay readable, so the model thinks as usual from the first turn after the switch.
1023* **A conversation that moves from them to any earlier model loses it.** The earlier model can't read their blocks, the API drops them for that request, and the earlier model reasons again from the visible messages. If the conversation later returns to Claude Fable 5.1 with the same history, its own blocks are readable again.
1024 
1025In full, Claude Fable 5.1 and Claude Mythos 5.1 read thinking blocks produced by each other, by Claude Opus 5, Claude Fable 5, and Claude Mythos 5, and by Claude Opus 4.8 and earlier Opus models, Claude Sonnet models, and Claude Haiku 4.5. No model other than these two can read a block produced by Claude Fable 5.1 or Claude Mythos 5.1.
1026 
1027**A block the receiving model can't read is dropped.** The API removes it before the prompt reaches the model. It doesn't count toward `input_tokens` and isn't billed. When you fall back from Claude Fable 5.1 to an older model mid-conversation, for example after a [classifier refusal fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback), the older model reasons again from the visible conversation. With the [controls beta header](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-thinking-controls) the drop is reported in `input_transformations` as `model_binding_mismatch`. Without it the drop is silent. A [server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback) drops unreadable blocks the same way.
1028 
1029### Only in the conversation that produced it
1030 
1031A thinking block from Claude Fable 5.1 is preserved only while the conversation prefix it was produced from stays unchanged. Its `signature` covers the `system` prompt, the `tools`, and the messages that preceded the block. Claude Mythos 5.1 records the same `signature` but doesn't run this check.
1032 
1033This check is enforced for new accounts created on or after August 31, 2026. For accounts created earlier, the API records the condition in the signature but doesn't act on a mismatch unless the request sets [`thinking.block_binding.prefix_mismatch_behavior`](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-thinking-controls), which opts into enforcement. Anthropic plans to enforce this condition for every organization on future models. If your account was created earlier, make your application compatible now: the same append-only patterns keep the [prompt cache](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) warm, and you can test against the check by sending `prefix_mismatch_behavior: "error"`. If you ship a tool or framework that people run with their own API key, test that way: your users on new accounts are enforced before you are. [Preserved thinking](https://platform.claude.com/docs/en/build-with-claude/preserved-thinking) has the integration checklist: how to tell whether your code edits history, and the API feature that replaces each kind of edit.
1034 
1035Where the check is enforced, a request that replays a block against a changed prefix is rejected with a 400 `invalid_request_error`:
1036 
1037```text wrap
1038messages.5.content.0: Invalid `signature` in `thinking` block. The block is bound to a different conversation. Remove the block, or set `thinking.block_binding.prefix_mismatch_behavior` to "drop_block". That setting requires the `thinking-binding-controls-2026-08-01` value in the `anthropic-beta` header.
1039```
1040 
1041The last sentence appears only when the request didn't send the beta header. The message can end with one more sentence naming the first message that changed. Retrying the same request body fails the same way. To continue without the invalidated reasoning instead, send the `thinking-binding-controls-2026-08-01` beta header and set `prefix_mismatch_behavior` to `"drop_block"`. The API then drops the failing block and every thinking block after it in the conversation, and reports each one in `input_transformations` as `prefix_binding_mismatch`. The [token counting](https://platform.claude.com/docs/en/build-with-claude/token-counting) endpoint runs the same check and returns the same 400.
1042 
1043What invalidates later thinking blocks:
1044 
1045* Editing, reordering, or removing an earlier message, including removing a per-turn reminder you injected into an earlier user turn.
1046* Changing the content of the top-level `system` prompt, or adding, removing, or editing a tool in the `tools` array, between requests.
1047* Client-side compaction or truncation that keeps recent assistant turns verbatim, thinking included, while rewriting the turns before them.
1048* An image or document URL in an earlier turn that serves different bytes on a later request. The check covers the bytes, not the URL string, so a rotating signed URL for the same file is fine. For content you reference across turns, upload it once with the [Files API](https://platform.claude.com/docs/en/build-with-claude/files) and send the `file_id`, or send base64.
1049 
1050What doesn't:
1051 
1052* Removing a leading run of thinking blocks, oldest first: the first thinking block in the conversation (or the first one after the most recent compaction block), then the next, and so on. Removing a thinking block from anywhere else invalidates every thinking block after it, in that turn and in every later turn.
1053* Changing `output_config.effort`, `max_tokens`, or other sampling settings between requests.
1054* `cache_control` markers, wherever you place or move them.
1055* Server-side [compaction](https://platform.claude.com/docs/en/build-with-claude/compaction) and [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing): they don't count as edits, because the check compares the conversation as you sent it, not the server's edited copy. After a compaction, the checked prefix starts from the compaction block.
1056 
1057Patterns that keep thinking blocks valid:
1058 
1059* **Append only.** Add new messages at the end of `messages` and leave earlier turns byte-for-byte unchanged.
1060* **Use [mid-conversation system messages](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages)** and mid-conversation tool changes to add instructions or change tool availability partway through, instead of editing the top-level `system` field or `tools` array. For a reminder that should apply to one turn only, send it as a [turn-scoped system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#turn-scoped-system-messages) and leave it in the history rather than deleting it later. This also preserves the prompt cache.
1061* **Use server-side context management** rather than trimming history yourself.
1062* **If a request is rejected for a prefix mismatch and you can't repair the history,** resend it with the beta header and `prefix_mismatch_behavior: "drop_block"`, or strip every `thinking` and `redacted_thinking` block from the history and retry once.
1063 
1064When earlier thinking is dropped, the model answers that turn without those blocks. A client that repeatedly invalidates its own history restarts the prompt cache each time, which raises cost.
1065 
1066**Client-side compaction.** This check doesn't rule out compacting on the client. The rule is narrower: don't keep a thinking block behind a prefix you've rewritten. Server-side [compaction](https://platform.claude.com/docs/en/build-with-claude/compaction) is the simplest way to satisfy it. If you compact on the client, use one of these shapes:
1067 
1068* **Simple compaction (recommended):** summarize the conversation into one message and start the next request with that summary plus the new user turn, replaying no earlier turns and no earlier thinking blocks. No earlier thinking remains, so nothing fails, and the model thinks afresh on the compacted conversation. Claude models are trained on long-horizon tasks with this scheme, and it performs comparably to more elaborate ones for most workloads. It resets the prompt cache, as any compaction does.
1069* **Keep-tail compaction:** summarize older turns and keep the most recent turns verbatim. The kept turns' thinking blocks were produced against the full history and fail behind the summary. Strip `thinking` and `redacted_thinking` from every turn you carry across (their text and tool calls can stay), or set `prefix_mismatch_behavior: "drop_block"` and let the API discard them.
1070* **Background compaction:** build the summary off the critical path and swap it in while the conversation continues. Every turn produced in the meantime has thinking that predates the swap. Send `"drop_block"` on every request that still carries thinking blocks produced before the swap (or strip those blocks yourself; `input_transformations` on the first response after the swap lists exactly which ones), or compact synchronously.
1071 
1072Snipping individual turns out of the middle of the transcript invalidates every thinking block after them, and no client-side shape avoids that. Use a mid-conversation system message for the instruction change you were making, or server-side [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing) for selective removal.
1073 
1074### Controls for blocks that aren't preserved (beta)
1075 
1076Send the [beta header](https://platform.claude.com/docs/en/api/beta-headers) `thinking-binding-controls-2026-08-01` to get two things: an `input_transformations` array on every response that lists any thinking blocks the API dropped, and a `block_binding` object on the thinking configuration with one field.
1077 
1078| Field | Type | Default | Description |
1079| -------------------------- | --------------------------- | --------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
1080| `prefix_mismatch_behavior` | `"error"` or `"drop_block"` | `"error"` | What the API does with a thinking block that fails the [conversation check](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-in-conversation). `"error"` rejects the request with a 400 error. `"drop_block"` removes the block and every later thinking block in the conversation, reports each in `input_transformations`, and continues. Neither value changes the model check, which always drops. |
1081 
1082`block_binding` is accepted alongside `thinking.type: "adaptive"` and `thinking.type: "enabled"`. Sending it without the beta header returns a 400 error. Models that don't run the conversation check accept the object and report only model-check drops, so one request body works across models. On Amazon Bedrock and Google Cloud, pass beta names as described in [Beta headers](https://platform.claude.com/docs/en/api/beta-headers).
1083 
1084The following request opts into dropping rather than rejecting. On a first turn there is nothing to replay, so `input_transformations` comes back empty:
1085 
1086<CodeGroup>
1087 ```bash cURL
1088 curl https://api.anthropic.com/v1/messages \
1089 -H "x-api-key: $ANTHROPIC_API_KEY" \
1090 -H "anthropic-version: 2023-06-01" \
1091 -H "anthropic-beta: thinking-binding-controls-2026-08-01" \
1092 -H "content-type: application/json" \
1093 -d '{
1094 "model": "claude-fable-5-1",
1095 "max_tokens": 16000,
1096 "thinking": {
1097 "type": "adaptive",
1098 "block_binding": {
1099 "prefix_mismatch_behavior": "drop_block"
1100 }
1101 },
1102 "messages": [
1103 {
1104 "role": "user",
1105 "content": "What is the greatest common divisor of 1071 and 462?"
1106 }
1107 ]
1108 }'
1109 ```
1110 
1111 ```bash CLI
1112 ant beta:messages create --beta thinking-binding-controls-2026-08-01 \
1113 --transform '{content.#(type=="text")#.text,input_transformations}' \
1114 --format yaml <<'YAML'
1115 model: claude-fable-5-1
1116 max_tokens: 16000
1117 thinking:
1118 type: adaptive
1119 block_binding:
1120 prefix_mismatch_behavior: drop_block
1121 messages:
1122 - role: user
1123 content: What is the greatest common divisor of 1071 and 462?
1124 YAML
1125 ```
1126 
1127 ```python Python
1128 client = anthropic.Anthropic()
1129 
1130 response = client.beta.messages.create(
1131 model="claude-fable-5-1",
1132 max_tokens=16000,
1133 thinking={
1134 "type": "adaptive",
1135 "block_binding": {"prefix_mismatch_behavior": "drop_block"},
1136 },
1137 messages=[
1138 {
1139 "role": "user",
1140 "content": "What is the greatest common divisor of 1071 and 462?",
1141 }
1142 ],
1143 betas=["thinking-binding-controls-2026-08-01"],
1144 )
1145 
1146 for block in response.content:
1147 if block.type == "text":
1148 print(block.text)
1149 
1150 print(f"Input transformations: {len(response.input_transformations or [])}")
1151 ```
1152 
1153 ```typescript TypeScript
1154 const client = new Anthropic();
1155 
1156 const response = await client.beta.messages.create({
1157 model: "claude-fable-5-1",
1158 max_tokens: 16000,
1159 thinking: {
1160 type: "adaptive",
1161 block_binding: { prefix_mismatch_behavior: "drop_block" }
1162 },
1163 messages: [
1164 { role: "user", content: "What is the greatest common divisor of 1071 and 462?" }
1165 ],
1166 betas: ["thinking-binding-controls-2026-08-01"]
1167 });
1168 
1169 for (const block of response.content) {
1170 if (block.type === "text") {
1171 console.log(block.text);
1172 }
1173 }
1174 console.log(`Input transformations: ${response.input_transformations?.length ?? 0}`);
1175 ```
1176 
1177 ```csharp C#
1178 
1179 AnthropicClient client = new();
1180 
1181 var response = await client.Beta.Messages.Create(
1182 new()
1183 {
1184 Model = "claude-fable-5-1",
1185 MaxTokens = 16000,
1186 Thinking = new BetaThinkingConfigAdaptive
1187 {
1188 BlockBinding = new()
1189 {
1190 PrefixMismatchBehavior = BetaThinkingPrefixMismatchBehavior.DropBlock,
1191 },
1192 },
1193 Messages =
1194 [
1195 new()
1196 {
1197 Role = Role.User,
1198 Content = "What is the greatest common divisor of 1071 and 462?",
1199 },
1200 ],
1201 Betas = [AnthropicBeta.ThinkingBindingControls2026_08_01],
1202 }
1203 );
1204 
1205 foreach (var block in response.Content)
1206 {
1207 if (block.TryPickText(out var textBlock))
1208 {
1209 Console.WriteLine(textBlock.Text);
1210 }
1211 }
1212 
1213 Console.WriteLine($"Input transformations: {response.InputTransformations?.Count ?? 0}");
1214 ```
1215 
1216 ```go Go
1217 client := anthropic.NewClient()
1218 
1219 response, err := client.Beta.Messages.New(context.TODO(), anthropic.BetaMessageNewParams{
1220 Model: "claude-fable-5-1",
1221 MaxTokens: 16000,
1222 Thinking: anthropic.BetaThinkingConfigParamUnion{
1223 OfAdaptive: &anthropic.BetaThinkingConfigAdaptiveParam{
1224 BlockBinding: anthropic.BetaThinkingBlockBindingParam{
1225 PrefixMismatchBehavior: anthropic.BetaThinkingPrefixMismatchBehaviorDropBlock,
1226 },
1227 },
1228 },
1229 Messages: []anthropic.BetaMessageParam{
1230 anthropic.NewBetaUserMessage(anthropic.NewBetaTextBlock("What is the greatest common divisor of 1071 and 462?")),
1231 },
1232 Betas: []anthropic.AnthropicBeta{anthropic.AnthropicBetaThinkingBindingControls2026_08_01},
1233 })
1234 if err != nil {
1235 log.Fatal(err)
1236 }
1237 
1238 for _, block := range response.Content {
1239 if textBlock, ok := block.AsAny().(anthropic.BetaTextBlock); ok {
1240 fmt.Println(textBlock.Text)
1241 }
1242 }
1243 fmt.Printf("Input transformations: %d\n", len(response.InputTransformations))
1244 ```
1245 
1246 ```java Java
1247 import com.anthropic.models.beta.AnthropicBeta;
1248 import com.anthropic.models.beta.messages.BetaMessage;
1249 import com.anthropic.models.beta.messages.BetaThinkingBlockBinding;
1250 import com.anthropic.models.beta.messages.BetaThinkingConfigAdaptive;
1251 import com.anthropic.models.beta.messages.BetaThinkingPrefixMismatchBehavior;
1252 import com.anthropic.models.beta.messages.MessageCreateParams;
1253 
1254 void main() {
1255 AnthropicClient client = AnthropicOkHttpClient.fromEnv();
1256 
1257 MessageCreateParams params = MessageCreateParams.builder()
1258 .model("claude-fable-5-1")
1259 .maxTokens(16000L)
1260 .addBeta(AnthropicBeta.THINKING_BINDING_CONTROLS_2026_08_01)
1261 .thinking(BetaThinkingConfigAdaptive.builder()
1262 .blockBinding(BetaThinkingBlockBinding.builder()
1263 .prefixMismatchBehavior(BetaThinkingPrefixMismatchBehavior.DROP_BLOCK)
1264 .build())
1265 .build())
1266 .addUserMessage("What is the greatest common divisor of 1071 and 462?")
1267 .build();
1268 
1269 BetaMessage response = client.beta().messages().create(params);
1270 
1271 response.content().stream()
1272 .flatMap(block -> block.text().stream())
1273 .forEach(textBlock -> IO.println(textBlock.text()));
1274 IO.println("Input transformations: "
1275 + response.inputTransformations().map(List::size).orElse(0));
1276 }
1277 ```
1278 
1279 ```php PHP
1280 use Anthropic\Beta\AnthropicBeta;
1281 use Anthropic\Beta\Messages\BetaThinkingBlockBinding;
1282 use Anthropic\Beta\Messages\BetaThinkingConfigAdaptive;
1283 use Anthropic\Beta\Messages\BetaThinkingPrefixMismatchBehavior;
1284 use Anthropic\Client;
1285 
1286 $client = new Client();
1287 
1288 $response = $client->beta->messages->create(
1289 model: 'claude-fable-5-1',
1290 maxTokens: 16000,
1291 thinking: BetaThinkingConfigAdaptive::with(
1292 blockBinding: BetaThinkingBlockBinding::with(
1293 prefixMismatchBehavior: BetaThinkingPrefixMismatchBehavior::DROP_BLOCK,
1294 ),
1295 ),
1296 messages: [
1297 ['role' => 'user', 'content' => 'What is the greatest common divisor of 1071 and 462?'],
1298 ],
1299 betas: [AnthropicBeta::THINKING_BINDING_CONTROLS_2026_08_01],
1300 );
1301 
1302 foreach ($response->content as $block) {
1303 if ($block->type === 'text') {
1304 echo $block->text, PHP_EOL;
1305 }
1306 }
1307 
1308 echo 'Input transformations: ', count($response->inputTransformations ?? []), PHP_EOL;
1309 ```
1310 
1311 ```ruby Ruby
1312 client = Anthropic::Client.new
1313 
1314 response = client.beta.messages.create(
1315 model: "claude-fable-5-1",
1316 max_tokens: 16_000,
1317 thinking: {
1318 type: "adaptive",
1319 block_binding: {prefix_mismatch_behavior: "drop_block"}
1320 },
1321 messages: [
1322 {role: "user", content: "What is the greatest common divisor of 1071 and 462?"}
1323 ],
1324 betas: [Anthropic::AnthropicBeta::THINKING_BINDING_CONTROLS_2026_08_01]
1325 )
1326 
1327 response.content.each do |block|
1328 puts block.text if block.type == :text
1329 end
1330 
1331 puts "Input transformations: #{response.input_transformations&.length || 0}"
1332 ```
1333</CodeGroup>
1334 
1335```text Output wrap
1336The greatest common divisor of 1071 and 462 is 21.
1337Input transformations: 0
1338```
1339 
1340**Dropped blocks are reported in `input_transformations`.** Under the beta header, every response from a thinking-capable model carries this top-level array. It's empty when nothing was dropped and never `null`. Each entry names the position of a dropped block and the check it failed:
1341 
1342```json
1343{
1344 "input_transformations": [
1345 {
1346 "type": "thinking_dropped",
1347 "path": "messages.1.content.0",
1348 "reason": "model_binding_mismatch"
1349 }
1350 ]
1351}
1352```
1353 
1354The `reason` field is `model_binding_mismatch` or `prefix_binding_mismatch`. Ignore entries whose `type` or `reason` you don't recognize, because later checks add values. When [streaming](https://platform.claude.com/docs/en/build-with-claude/streaming), `input_transformations` arrives on the `message` object in the `message_start` event. After a mid-stream server-side fallback, the final `message_delta` event carries the array again with the serving model's entries. Without the beta header the field is absent.
1355 
1356A tampered or undecryptable signature is a different failure: it always returns a 400 (``Invalid `signature` in `thinking` block``, with no reason clause) and `prefix_mismatch_behavior` doesn't apply to it. In a [message batch](https://platform.claude.com/docs/en/build-with-claude/batch-processing), an item whose block fails the conversation check under `"error"` resolves as `errored`.
9061357 
9071358## Thinking and prompt caching
9081359 
9091360[Prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) interacts with thinking in a few specific ways. The following rules apply in both thinking modes.
9101361 
911**Configuration changes invalidate caching.** The thinking configuration and the resolved [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) level are rendered into the prompt itself, so changing any of them starts a new cache prefix. Switching between `adaptive`, `enabled`, and `disabled`, changing `budget_tokens`, and changing the effort value all invalidate cache breakpoints: message-level breakpoints always miss, and tool and system-prompt breakpoints can miss too, depending on where the model renders the configuration. Treat any thinking or effort change as starting the cache over. Consecutive requests that keep the same configuration preserve the cache, and setting a parameter explicitly to its default value is equivalent to omitting it. A worked demonstration with usage output is on the [Steering thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-steering-and-cost#prompt-caching) page.
1362**Configuration changes invalidate caching.** The thinking configuration and the resolved [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) level are rendered into the prompt itself, so changing any of them starts a new cache prefix. Switching between `adaptive`, `enabled`, and `disabled`, changing `budget_tokens`, and changing the effort value all invalidate cache breakpoints: message-level breakpoints always miss, and tool and system-prompt breakpoints can miss too, depending on where the model renders the configuration. Treat any thinking or top-level effort change as starting the cache over. On models that support [per-message effort](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta), an effort change carried in a `role: "system"` message inside `messages` leaves the cached prefix intact. Consecutive requests that keep the same configuration preserve the cache, and setting a parameter explicitly to its default value is equivalent to omitting it. A thinking block the API drops under either [preserved-thinking condition](https://platform.claude.com/docs/en/build-with-claude/thinking#preserved-thinking) changes the cached prefix from that block's position onward. Blocks passed back unchanged keep the cache intact. A worked demonstration with usage output is on the [Steering thinking](https://platform.claude.com/docs/en/build-with-claude/thinking-steering-and-cost#prompt-caching) page.
9121363 
9131364**Thinking blocks are cached with tool results.** During a tool-use loop, caching occurs when you make a follow-up request that includes tool results. At that point the previous conversation history, including its thinking blocks, can be cached, and those cached thinking blocks count as input tokens in your usage metrics when read from the cache. This occurs automatically, even without explicit `cache_control` markers, and behaves the same for regular and interleaved thinking. The tradeoff: thinking blocks you never see again in responses still contribute to input token usage when read from cache.
9141365 
from line 1449
9981449 `redacted_thinking` blocks are a distinct content block type returned when thinking is safety-redacted. This is separate from the [`display: "omitted"`](https://platform.claude.com/docs/en/build-with-claude/thinking#controlling-thinking-display) option, which returns regular `thinking` blocks with an empty `thinking` field.
9991450</Note>
10001451 
1001## Thinking output on Claude Fable 5 and Claude Mythos 5
1002 
1003On Claude Fable 5 and Claude Mythos 5, the raw chain of thought is never returned. The blocks you receive are regular `thinking` blocks, not `redacted_thinking`, and the [`display` setting](https://platform.claude.com/docs/en/build-with-claude/thinking#controlling-thinking-display) works the same as on other models ([summarized](https://platform.claude.com/docs/en/build-with-claude/thinking#summarized-thinking) text, or an empty `thinking` field when omitted, the default here). For the response shape of thinking blocks, see the [Messages API reference](https://platform.claude.com/docs/en/api/messages/create).
1004 
1005When continuing a conversation on the same model, pass each thinking block back to the API exactly as received, including blocks whose `thinking` field is empty. Don't edit or reconstruct them. Reading the summary text for display is fine: the API rejects blocks whose returned content has been modified, not blocks you have read. Text placed in an empty omitted `thinking` field is [ignored rather than rejected](https://platform.claude.com/docs/en/build-with-claude/thinking#controlling-thinking-display).
1006 
1007To learn how thinking blocks are handled when you switch models mid-conversation, see [Thinking block preservation by model](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-block-preservation-by-model).
1008 
1009Two exceptions, covered in [Fallback credit](https://platform.claude.com/docs/en/build-with-claude/fallback-credit):
1010 
1011* Fallback-credit retries must echo the refused request body unchanged.
1012* `fallback` blocks from a mid-output fallback stay where they appeared.
1013 
1014To get visibility into the model's reasoning, read the `thinking` blocks described on this page rather than prompting for reasoning in the response text. On Claude Fable 5, a request that attempts to elicit the model's internal reasoning as part of the response text can be refused with `stop_details.category: "reasoning_extraction"`. See [Refusal categories](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#refusal-response) for the field reference and handling guidance.
1015 
10161452## Limits and feature compatibility
10171453 
1018**Sampling parameters.** On Claude Fable 5, Claude Mythos 5, Claude Mythos Preview, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, and Claude Sonnet 5, non-default `temperature`, `top_p`, or `top_k` values return a 400 error on every request, regardless of whether thinking is used. On older models, the restriction applies only while thinking is on: `temperature` and `top_k` are incompatible with thinking, and `top_p` is allowed at values between 0.95 and 1.
1019 
1020**Response prefill and forced tool use.** You can't pre-fill the assistant response while thinking is on. Forced tool use (`tool_choice: {"type": "any"}` or `{"type": "tool", ...}`) is incompatible with manual extended thinking but works with adaptive thinking. See [Thinking with tool use](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-with-tool-use).
1021 
1022**Output limits.** Claude Fable 5, Claude Mythos 5, Claude Mythos Preview, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Sonnet 5, Claude Opus 4.6, and Claude Sonnet 4.6 support up to 128k output tokens per request. Claude Haiku 4.5, Claude Sonnet 4.5, and Claude Opus 4.5 support up to 64k. On the [Message Batches API](https://platform.claude.com/docs/en/build-with-claude/batch-processing#extended-output-beta), the `output-300k-2026-03-24` [beta header](https://platform.claude.com/docs/en/api/beta-headers) raises the limit to 300k for Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, Claude Sonnet 5, Claude Opus 4.6, and Claude Sonnet 4.6. See each model's page under [Models](https://platform.claude.com/docs/en/models/overview) for its limits.
1023 
1024**Long requests.** The SDKs require streaming when `max_tokens` is greater than 21,333, to avoid HTTP timeouts on long-running requests. This is a client-side validation, not an API restriction. If you don't need to process events incrementally, use `.stream()` with `.get_final_message()` (Python) or `.finalMessage()` (TypeScript) to get the complete `Message` object without handling individual events. See [Streaming Messages](https://platform.claude.com/docs/en/build-with-claude/streaming#get-the-final-message-without-handling-events). Expect longer response times when thinking is active, because generating thinking blocks adds processing time. For workloads that push thinking above roughly 32k tokens per request, use [batch processing](https://platform.claude.com/docs/en/build-with-claude/batch-processing) to avoid networking issues: such requests can run long enough to hit system timeouts and open connection limits.
1454### Sampling parameters
1455 
1456On Claude Fable 5.1, Claude Mythos 5.1, Claude Fable 5, Claude Mythos 5, Claude Mythos Preview, Claude Opus 5, Claude Opus 4.8, Claude Opus 4.7, and Claude Sonnet 5, non-default `temperature`, `top_p`, or `top_k` values return a 400 error on every request, regardless of whether thinking is used. On older models, the restriction applies only while thinking is on: `temperature` and `top_k` are incompatible with thinking, and `top_p` is allowed at values between 0.95 and 1.
1457 
1458### Response prefill and forced tool use
1459 
1460You can't prefill the assistant response while thinking is on. Forced tool use (`tool_choice: {"type": "any"}` or `{"type": "tool", ...}`) is incompatible with manual extended thinking but works with adaptive thinking. The exceptions are Claude Fable 5.1 and Claude Mythos 5.1, which reject forced tool use on every request with a 400 error. On those models, use `tool_choice: {"type": "auto"}` with [strict tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/strict-tool-use) or [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs) instead. See [Thinking with tool use](https://platform.claude.com/docs/en/build-with-claude/thinking#thinking-with-tool-use).
1461 
1462### Output limits
1463 
1464Each model accepts `max_tokens` up to the ceiling listed here. On the [Message Batches API](https://platform.claude.com/docs/en/build-with-claude/batch-processing#extended-output-beta), the `output-300k-2026-03-24` [beta header](https://platform.claude.com/docs/en/api/beta-headers) raises that ceiling for the models with a batches ceiling listed.
1465 
1466| Model | Max output tokens | Batches beta ceiling |
1467| --------------------- | ----------------- | -------------------- |
1468| Claude Fable 5.1 | 128k | — |
1469| Claude Mythos 5.1 | 128k | — |
1470| Claude Fable 5 | 128k | — |
1471| Claude Mythos 5 | 128k | — |
1472| Claude Mythos Preview | 128k | Not available |
1473| Claude Opus 5 | 128k | 300k |
1474| Claude Opus 4.8 | 128k | 300k |
1475| Claude Opus 4.7 | 128k | 300k |
1476| Claude Sonnet 5 | 128k | 300k |
1477| Claude Opus 4.6 | 128k | 300k |
1478| Claude Sonnet 4.6 | 128k | 300k |
1479| Claude Haiku 4.5 | 64k | Not available |
1480| Claude Sonnet 4.5 | 64k | Not available |
1481| Claude Opus 4.5 | 64k | Not available |
1482 
1483See the [models overview](https://platform.claude.com/docs/en/models/overview) for limits on legacy models.
1484 
1485### Long requests
1486 
1487The SDKs require streaming when `max_tokens` is greater than 21,333, to avoid HTTP timeouts on long-running requests. This is a client-side validation, not an API restriction. If you don't need to process events incrementally, use `.stream()` with `.get_final_message()` (Python) or `.finalMessage()` (TypeScript) to get the complete `Message` object without handling individual events. See [Streaming Messages](https://platform.claude.com/docs/en/build-with-claude/streaming#get-the-final-message-without-handling-events). Expect longer response times when thinking is active, because generating thinking blocks adds processing time. For workloads that push thinking above roughly 32k tokens per request, use [batch processing](https://platform.claude.com/docs/en/build-with-claude/batch-processing) to avoid networking issues: such requests can run long enough to hit system timeouts and open connection limits.
10251488 
10261489## Next steps
10271490 
from line 1497
10341497 Walk through a complete two-turn tool-use round trip that preserves thinking blocks correctly, and see how interleaved thinking changes the flow.
10351498 </Card>
10361499 
1500 <Card title="Preserved thinking" icon="stack" href="https://platform.claude.com/docs/en/build-with-claude/preserved-thinking">
1501 Find out whether your Messages API integration edits conversation history, and replace each edit with the API feature that keeps earlier thinking blocks valid.
1502 </Card>
1503 
10371504 <Card title="Troubleshooting thinking" icon="hammer" href="https://platform.claude.com/docs/en/build-with-claude/thinking-troubleshooting">
10381505 Diagnose and fix the most common thinking failures: configuration 400 errors, empty or missing thinking blocks, max\_tokens stops, and cache misses.
10391506 </Card>
10401507












