
optimizing-for-cost-and-intelligence changedabout-claude/models/optimizing-for-cost-and-intelligence
Nearest release: v2.1.293, published an hour before this site recorded the change. Shown because the two are within 24 hours of each other. Nothing here says the release caused the edit.
Recorded here
Lines+94added
Lines−40removed
From line
8
where the diff opens
First seen
14 Aug 2026
this site's first read of the page
Recorded edits18to this page, all time
The whole hunk
from line 8, old and new numbered
/
from line 8
88
99Cost and intelligence are usually pictured as a frontier where one buys the other. The first group of levers on this page moves a workload toward that frontier by cutting cost without touching quality; only the second group moves along it:
1010
11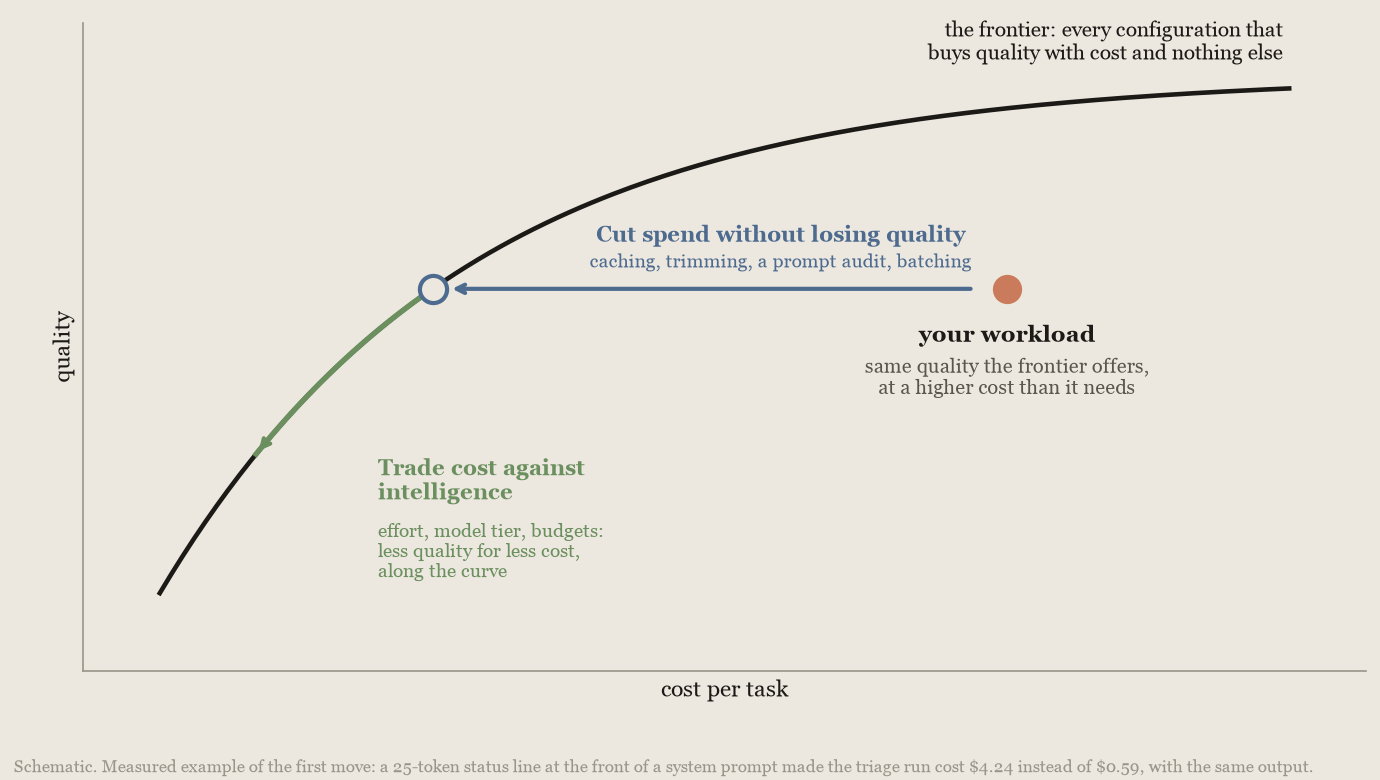
11<Frame>
12 
13</Frame>
1214
1315The levers come in two kinds:
1416
from line 54
5254
5355Across Anthropic's measured runs, cache reads are routinely the largest single component of task cost, making caching worth more than most model-choice decisions. Anthropic priced the DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) runs with and without caching:
5456
55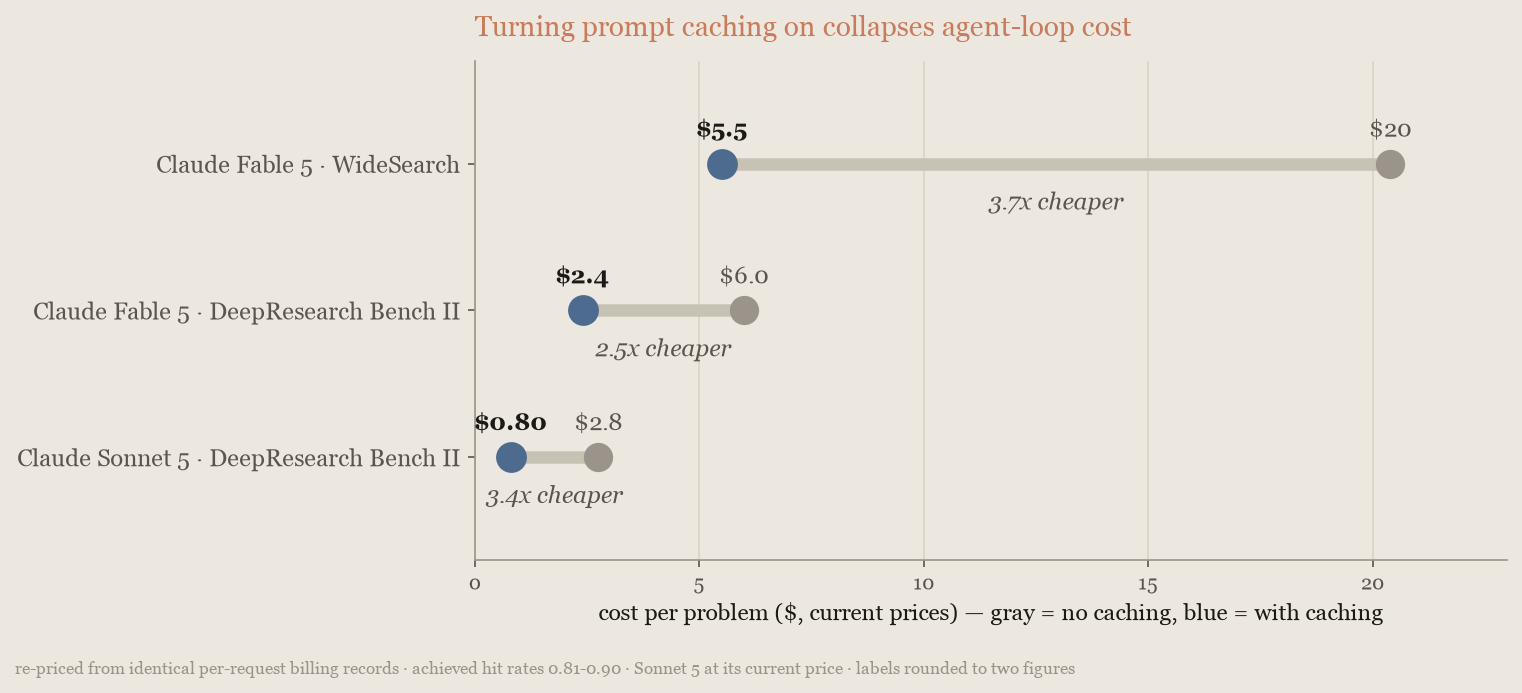
57<Frame>
58 
59</Frame>
5660
5761The cache's default lifetime is 5 minutes and an agent loop's turns are seconds apart, so the discount applies to most tokens on every turn. The caching chart's runs read 79% to 90% of their input tokens from the cache. The saving varies with episode depth, because shorter loops re-read less, but caching stayed the largest single lever on every model and benchmark measured.
5862
from line 70
6670* Turns arrive seconds apart: stay on the 5-minute default. When nothing paused, it cost 15% less than the 1-hour setting on Claude Sonnet 5 and about 15% to 18% less on Claude Opus 5.5.
6771* Gaps over an hour are common: stay on the default. A gap over an hour expires both durations, and the 1-hour setting then re-writes the prefix at its higher write price, so it loses on each of those gaps. Of your pauses longer than 5 minutes, if about 60% or more also run past an hour, stay on the default; the 1-hour duration pays only when at least about 40% of long pauses end within the hour.
6872
69Anthropic measured the triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) with pauses inserted before some turns to simulate a person's delay[16](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). On Claude Sonnet 5 and Claude Opus 5.5, the 1-hour cache became the cheaper setting once about 1 turn in 30 followed a pause, so the 1-in-20 rule leaves a margin, and the gap widens quickly past the crossover because every paused turn on the 5-minute setting re-writes the whole prefix. Every current model uses the same cache-write multipliers, and every model but Claude Fable 5.1, Claude Mythos 5.1, and Claude Opus 5.5 the same read price, so the crossover is in the same range on the other models; Fable 5.1 is the case covered next. Accuracy stayed within run-to-run noise in every cell. The turn after a pause kept its warm-cache latency on the 1-hour setting (measured on Claude Sonnet 5 and Claude Opus 5, not on Claude Opus 5.5). The following chart plots cost per session against the share of paused turns on Claude Sonnet 5:
73Anthropic measured the triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens) with pauses inserted before some turns to simulate a person's delay[16](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). On Claude Sonnet 5 and Claude Opus 5.5, the 1-hour cache became the cheaper setting once about 1 turn in 30 followed a pause, so the 1-in-20 rule leaves a margin, and the gap widens quickly past the crossover because every paused turn on the 5-minute setting re-writes the whole prefix. Every current model uses the same cache-write multipliers, and every model but Claude Fable 5.1, Claude Mythos 5.1, Claude Opus 5.5, and Claude Sonnet 5.5 the same read price (Claude Sonnet 5.5 has the same multipliers as Claude Opus 5.5), so the crossover is in the same range on the other models; Fable 5.1 is the case covered next. Accuracy stayed within run-to-run noise in every cell. The turn after a pause kept its warm-cache latency on the 1-hour setting (measured on Claude Sonnet 5 and Claude Opus 5, not on Claude Opus 5.5). The following chart plots cost per session against the share of paused turns on Claude Sonnet 5:
7074
71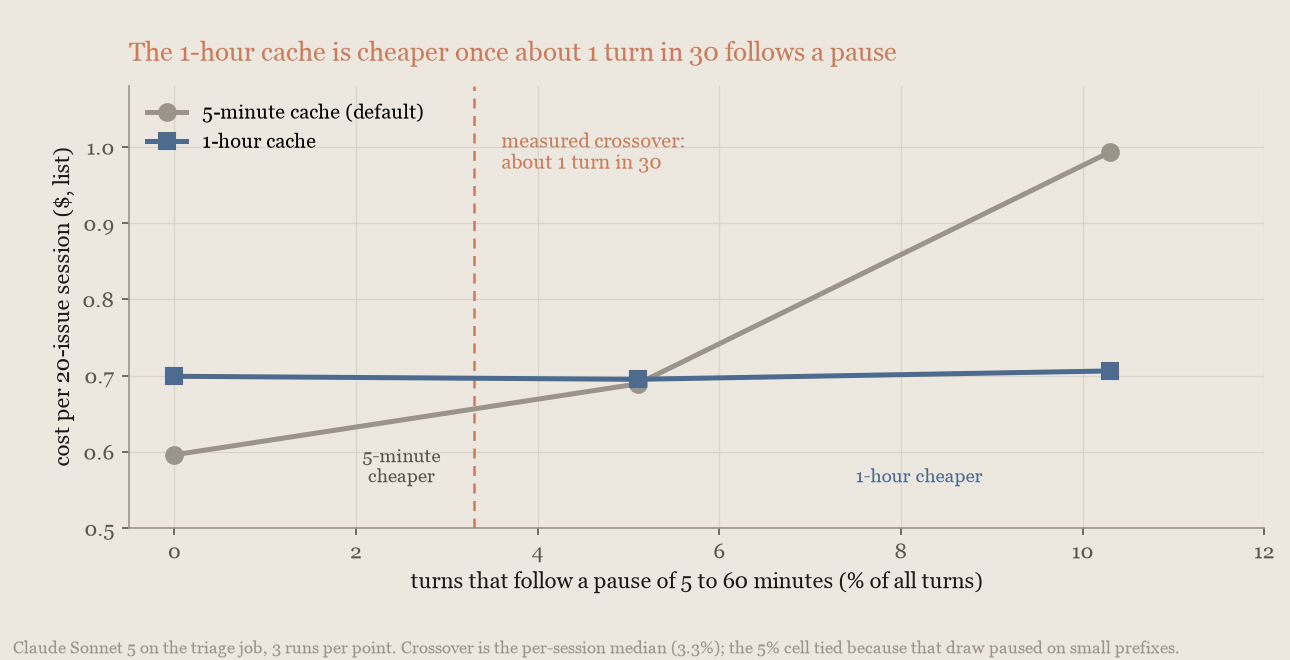
75<Frame>
76 
77</Frame>
7278
7379Anthropic also measured extra requests that keep the 5-minute cache warm. On Claude Sonnet 5 they cost about 8% less than the 1-hour duration when 1 turn in 20 followed a pause, but about the same at 2 in 20; on Claude Opus 5, the previous Opus model, they saved nothing measurable. With a pause of 6 minutes or more before every turn they cost more on both models. Because the Claude Sonnet 5 saving was gone by 2 turns in 20, use the 1-hour duration instead on Claude Sonnet 5 and Claude Opus 5.
7480
7581On Claude Fable 5.1 the cheapest setting is a different one. Its [cache read](https://platform.claude.com/docs/en/about-claude/pricing#prompt-caching) costs 0.025x the input price ($0.25 USD per million tokens) while its cache writes keep the standard multipliers, so a keep-alive request that re-reads the prefix is cheap and the 1-hour duration's write premium is the larger bill. Anthropic measured the triage job on Claude Fable 5.1 with the same three settings[19](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Keeping the 5-minute cache warm cost 13% to 20% less per session than the 1-hour cache whenever pauses ran for minutes; only with pauses near 45 minutes did the 1-hour cache win, by about $0.12 USD a session. On Claude Fable 5.1, keep the 5-minute cache warm while a person is away for minutes, and buy the 1-hour duration when pauses run toward an hour:
7682
77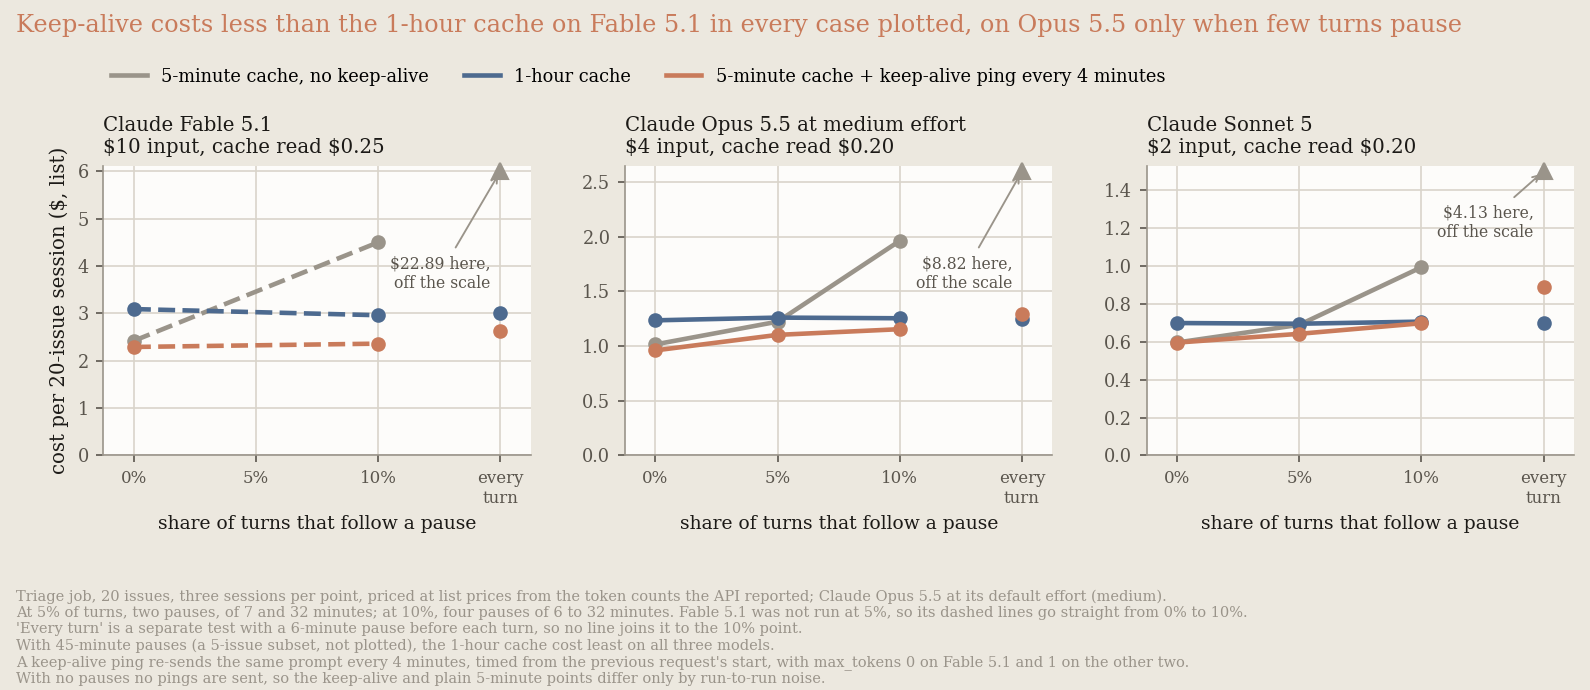
83<Frame>
84 
85</Frame>
7886
7987On Claude Opus 5.5, whose cache read costs 0.05x the input price, keep-alive requests cost 8% to 13% less than the 1-hour duration when 5% or 10% of turns followed a pause of 6 to 32 minutes (at the default effort, `medium`; 10% to 18% less at `high`), but more with a pause before every turn: about 4% to 6% more at 6-minute pauses, rising to over 50% more at 45-minute pauses. So on Claude Opus 5.5, keep the 5-minute cache warm when only a turn or two in 20 follow a pause of up to about half an hour, and otherwise follow the list at the start of this section. These measurements sent keep-alive requests with `max_tokens: 1`. For the `max_tokens: 0` request described next, Anthropic's pre-launch API tests on Claude Opus 5.5 show that it writes the cache and that the next request reads it; whether it refreshes an existing entry was not measured on Opus 5.5.
8088
from line 132
124132
125133Several things can break your cache during a task. Anything that changes per request, such as a timestamp or a queue position, placed ahead of the stable prefix turns every request into a full cache write: on the triage run in [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), a 25-token status line at the front of the system prompt cost $4.24 USD per run instead of $0.59 USD, more than running with caching off. Keep per-request text in the newest user turn.
126134
127The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On the most recent models, change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. Check that page for which models support it. On models that support it, a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) leaves the cached prefix intact too. The stakes are highest on Claude Fable 5.1 and Claude Mythos 5.1, where a break re-writes the prefix at 1.25x the input price instead of reading it at 0.025x. On a 100,000-token prefix, one broken turn there costs $1.25 USD instead of $0.03 USD, 50 times the read; on Claude Opus 5.5 it costs $0.50 USD instead of $0.02 USD, 25 times, and on the other current models 12.5 times.
135The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On the most recent models, change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. Check that page for which models support it. On models that support it, a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) leaves the cached prefix intact too. The stakes are highest on Claude Fable 5.1 and Claude Mythos 5.1, where a break re-writes the prefix at 1.25x the input price instead of reading it at 0.025x. On a 100,000-token prefix, one broken turn there costs $1.25 USD instead of $0.03 USD, 50 times the read; on Claude Opus 5.5 it costs $0.50 USD instead of $0.02 USD, and on Claude Sonnet 5.5 $0.25 USD instead of $0.01 USD, 25 times, and on the other current models 12.5 times.
128136
129137Anthropic measured this on the triage agent's long sessions[18](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). An effort change and an added tool made mid-session rewrote 39,000 and 60,000 cached tokens, and those sessions cost $0.95 USD per session. The same two changes on the first request after compaction cost $0.75 USD, and on the request that triggered the compaction $0.92 USD, because the compaction's summarization pass then re-processed the 81,000-token context at the cache-write price: that summarization pass cost $0.21 USD, against $0.04 USD when the same changes came one request later, with accuracy within run-to-run noise in every arm:
130138
131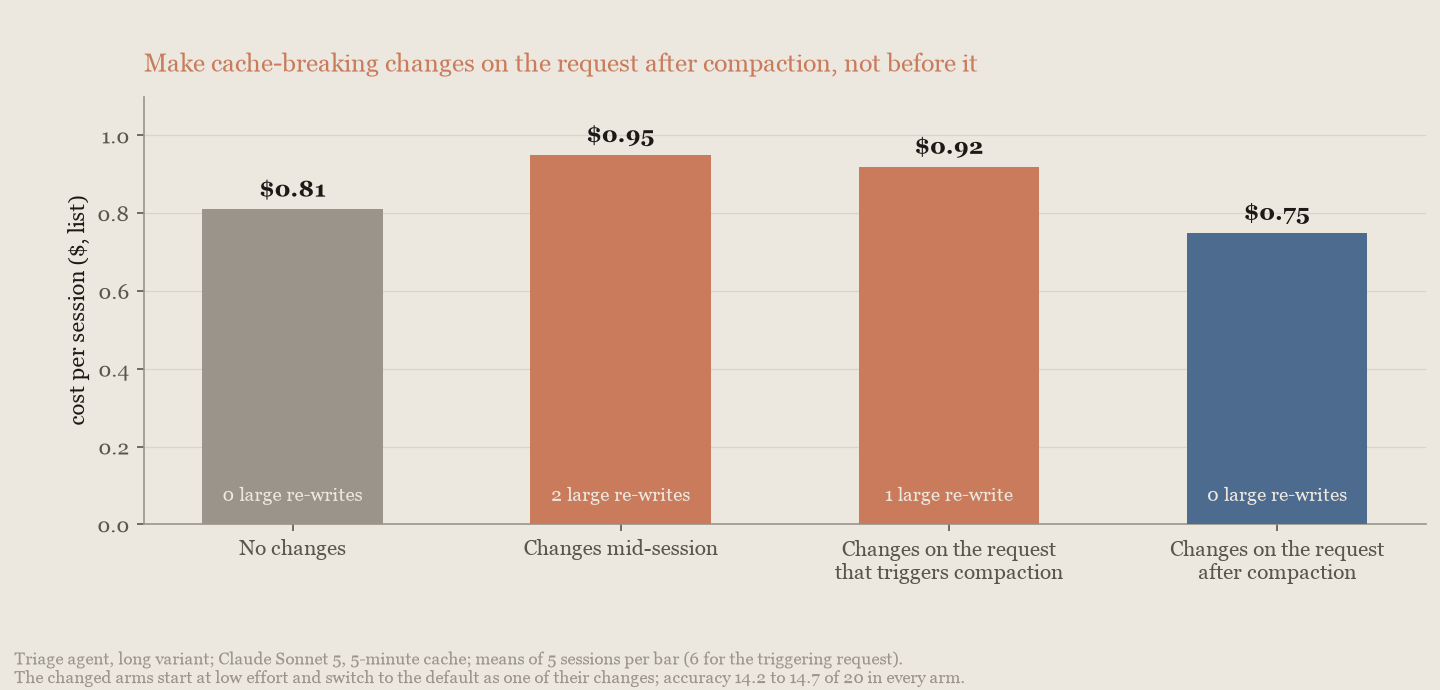
139<Frame>
140 
141</Frame>
132142
133143Changing a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) partway through invalidates any cached prefix that contains the budget value, so set it once, on the first request. Every [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching) pass invalidates the prefix from the point it clears and the next request pays to re-cache everything after it, so clear in a few large batches rather than many small ones. On Claude Fable 5.1 and Claude Mythos 5.1 each of these costs 50 times the read price per token, so they matter most there. Make every cache-invalidating change at natural breaks, then confirm cache reads have not dropped; if they have, [cache diagnostics](https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics) shows where the prefix diverged.
134144
from line 155
145155
146156Every tool definition attached to a request is input on every turn, and a few MCP servers add up to hundreds of them. Anthropic ran the triage agent with its own two tools plus a catalog of real tool definitions from public MCP servers, for a total of up to 502 tools, loading all of them or marking the extras `defer_loading` behind [tool search](https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool):
147157
148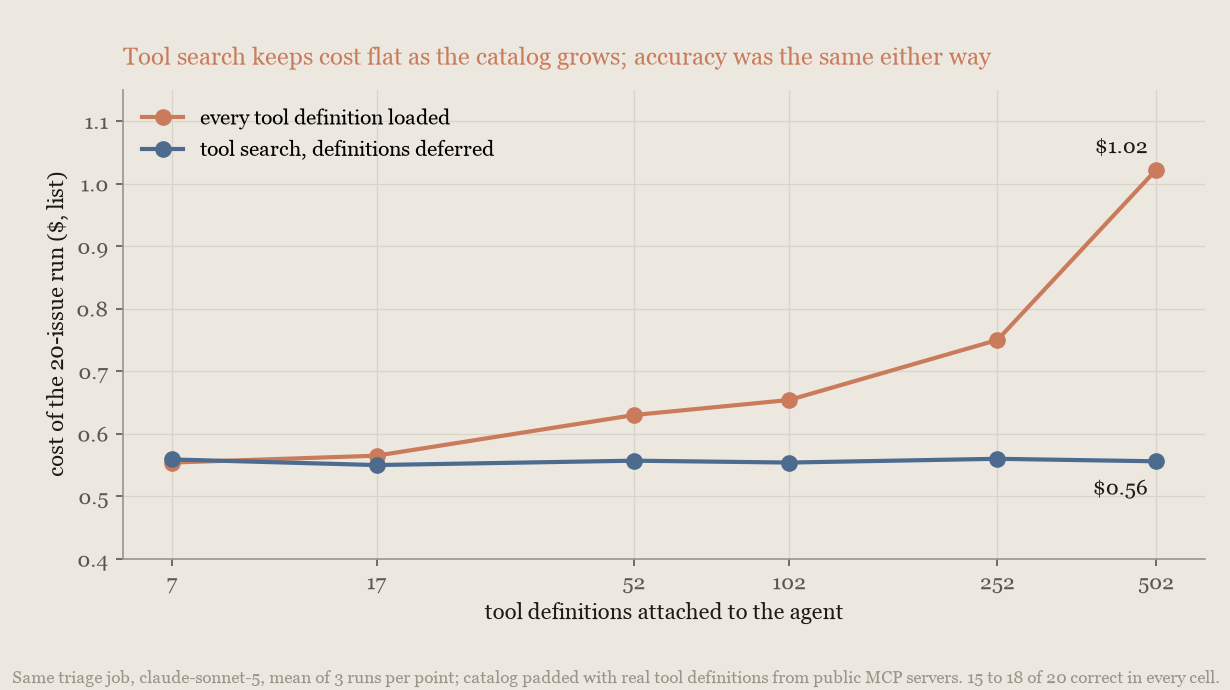
158<Frame>
159 
160</Frame>
149161
150162With every definition loaded, the run cost nearly doubled as the catalog grew, tracking the schema tokens on each request. With tool search it stayed flat at every catalog size, 45% less at 502 tools. Accuracy was 15 to 18 of 20 in every cell either way, and the model never called a wrong tool, so at this scale the catalog costs money, not correctness. The same holds for tools that come through the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector): with a public GitHub MCP server attached, deferring its toolset (`default_config: {defer_loading: true}`) cut the run 20% at the same accuracy.
151163
from line 165
153165
154166When the model has to compute over a table, upload it with the [Files API](https://platform.claude.com/docs/en/build-with-claude/files) and let the model query it with [code execution](https://platform.claude.com/docs/en/agents-and-tools/tool-use/code-execution-tool) instead of pasting it in. Anthropic asked 25 aggregate questions[15](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (sums, filtered counts, group-bys, and a date filter) over a 1,862-row public CSV, with the answers computed by pandas:
155167
156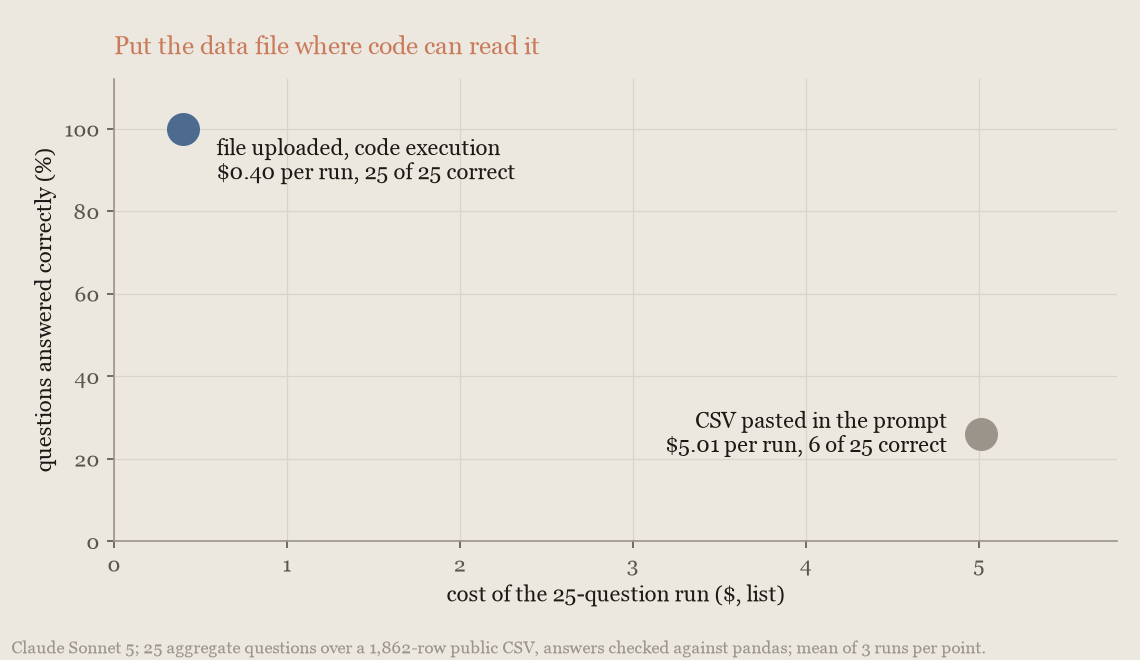
168<Frame>
169 
170</Frame>
157171
158172Pasted into the prompt, the table is about 91,000 input tokens on every request, and Claude Sonnet 5 answered 6 of 25 questions correctly. Uploaded, with code execution, it answered all 25, and the run cost about a twelfth as much. Claude Opus 5 showed the same pattern.
159173
from line 175
161175
162176The context levers only pay on a session long enough to need them:
163177
164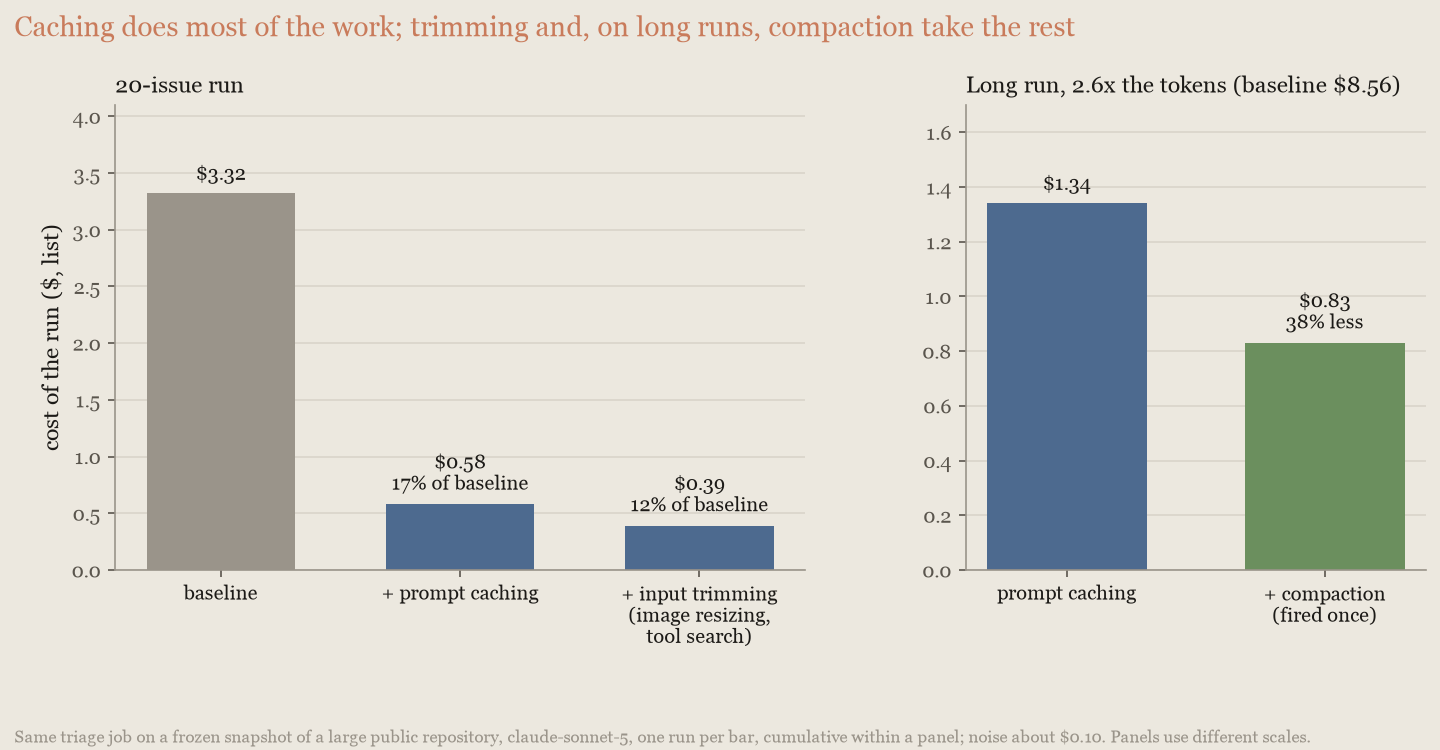
178<Frame>
179 
180</Frame>
165181
166182On the 20-issue run they saved nothing, and context editing cost 74% more. On the long run the prune saved 39% and compaction 32%, while context editing changed nothing. The prune is a few lines you write yourself: at each task boundary, replace large stale tool results with a one-line extract. It caches well because the edits sit at the tail of the conversation, where the next task adds new content anyway: 89% cache reads on the first request after a boundary and 81% on the requests between boundaries. Run-wide, the prune and context editing cache about equally well. The prune is cheaper because context editing rewrites content mid-task that the prune deletes (about two thirds of the gap) and because it keeps the context about half the size (the other third). If you use context editing, [clear in a few large batches](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching). The prune, adapted from the harness:
167183
from line 250
234250
235251The effect is measurable. On a support-desk evaluation[14](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), prompts written for Claude Opus 4.8 cost 36% more per ticket on Claude Opus 5 for no change in accuracy. Running the audit over the same prompts made Opus 5 both cheaper than the unaudited version (by 14%) and more accurate (97% of tickets, up from 92%, a gain outside the noise). On the Claude Sonnet 4.6 to Claude Sonnet 5 migration, the audit took 14% off at the same accuracy:
236252
237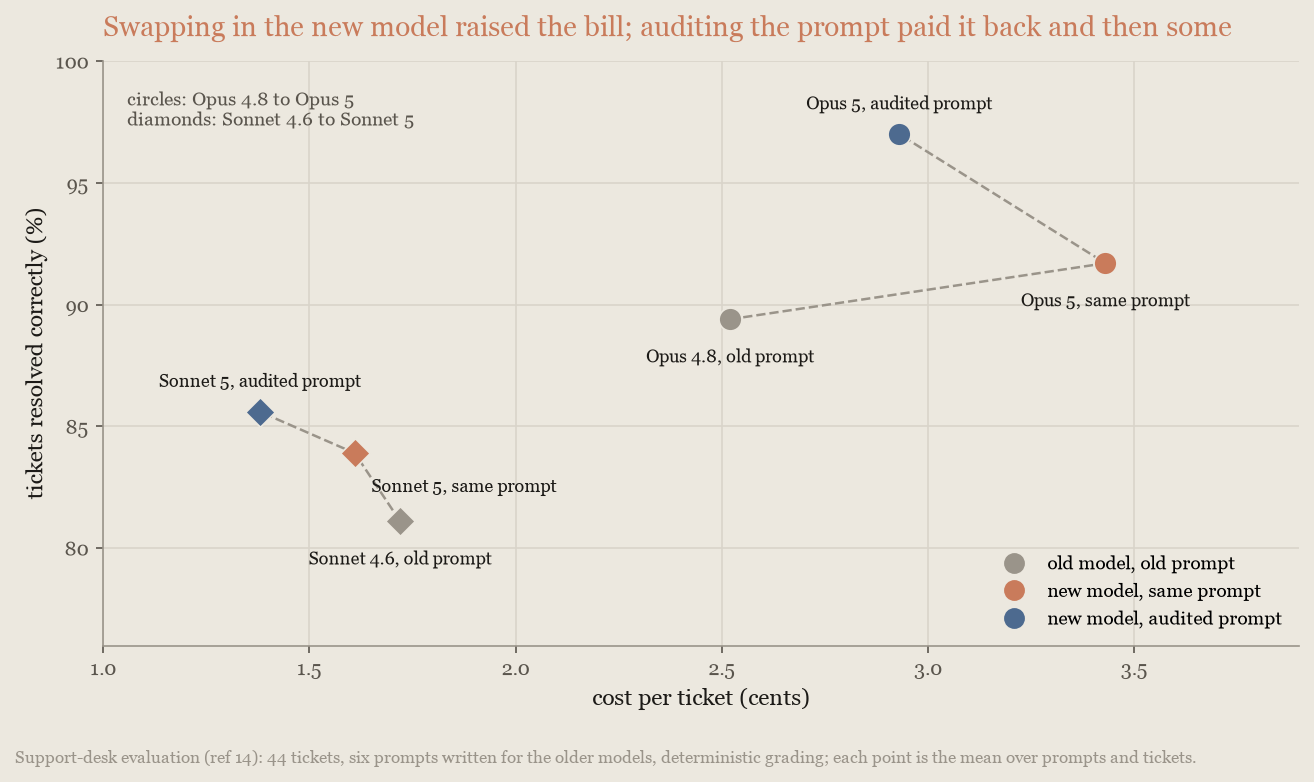
253<Frame>
254 
255</Frame>
238256
239257The two kinds of stale text have different costs. Instructions the new model follows too literally cost money: removing "verify twice" cut Opus 5's cost per ticket by a third, and removing "be maximally thorough" almost as much. Text that no longer fits the model costs accuracy instead: a retired thinking setting, contradictory rules, and a hand-rolled scratchpad that conflicts with the model's own thinking each restored 7 to 11 points on Opus 5 when removed:
240258
241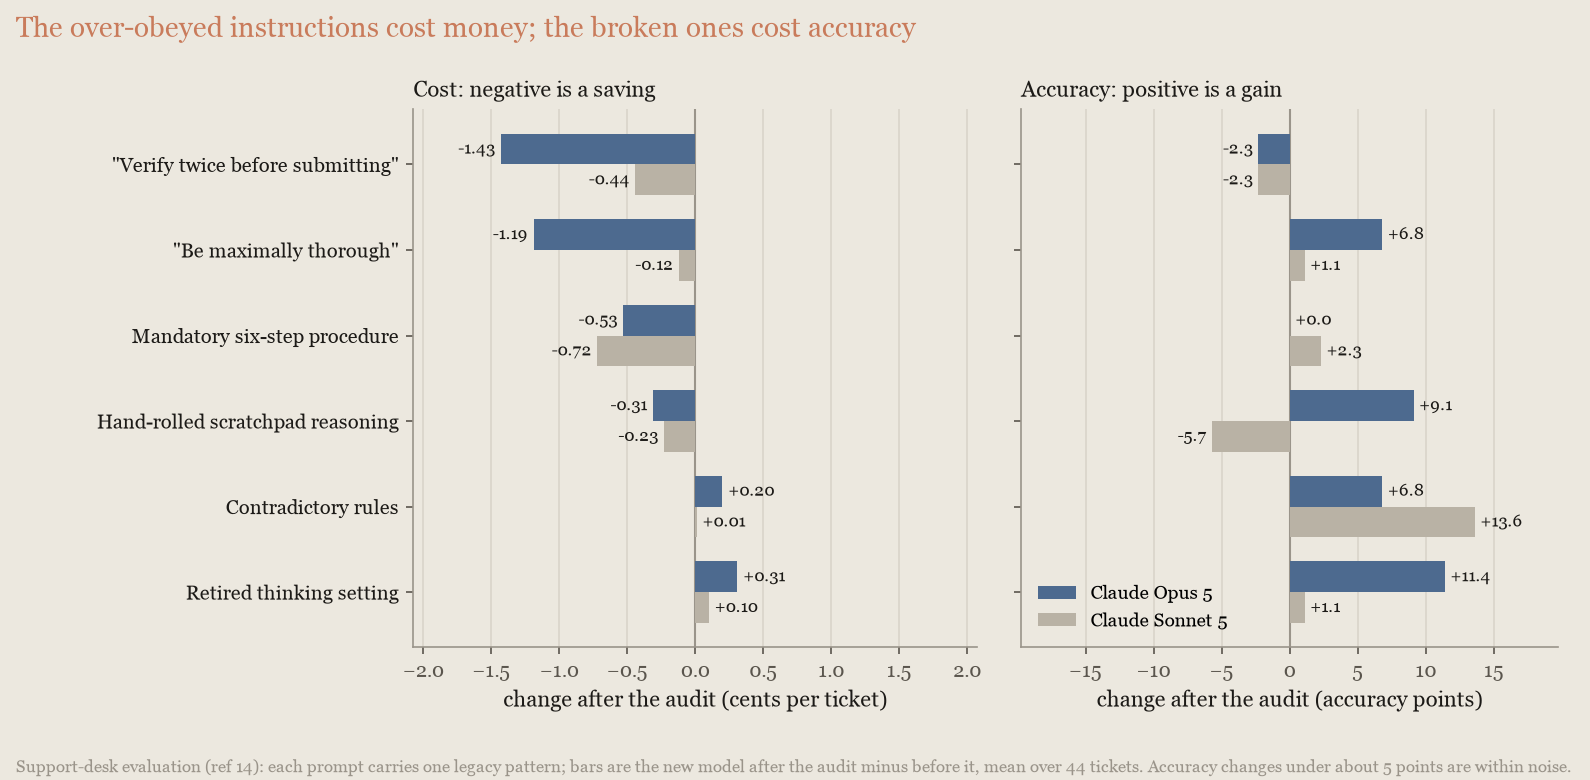
259<Frame>
260 
261</Frame>
242262
243263The same patterns tend to appear in tool descriptions and skills, which are worth auditing too.
244264
245265## Trade cost against intelligence
246266
247These levers set where a single model sits between cost and intelligence: model choice, effort, re-running failures at a higher setting, the budgets and caps it works within, and whether it can see how much time has passed. Start with an effort sweep on your current model ([Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort)). From lowest to highest cost and capability, the current models are Claude Haiku 4.5, Claude Sonnet 5.5, Claude Opus 5.5, and Claude Fable 5.1 (the frontier model); [Models overview](https://platform.claude.com/docs/en/models/overview) has the full lineup and prices.
267These levers set where a single model sits between cost and intelligence: model choice, effort, re-running failures at a higher setting, the budgets and caps it works within, and whether it can see how much time has passed. Start with an effort sweep on your current model ([Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort)). From lowest to highest cost and capability, the current models are Claude Haiku 5.5, Claude Sonnet 5.5, Claude Opus 5.5, and Claude Fable 5.1 (the frontier model); [Models overview](https://platform.claude.com/docs/en/models/overview) has the full lineup and prices.
248268
249269### Compare models on cost per task
250270
from line 272
252272
253273Anthropic measured this on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, priced as a customer is billed:
254274
255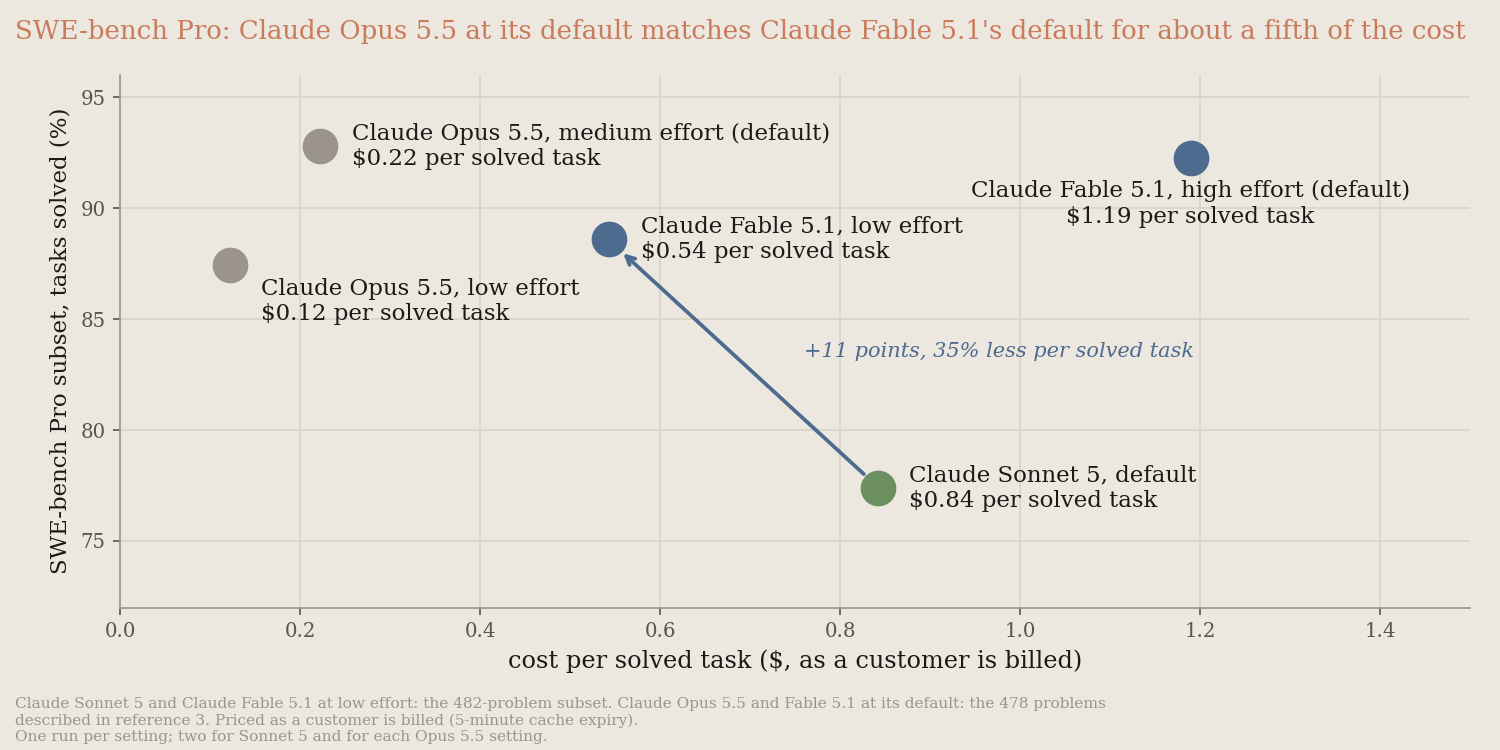
275<Frame>
276 
277</Frame>
256278
257279Claude Fable 5.1 at `low` effort solved 88.6% of tasks for $0.54 USD per solved task, against 77.4% for $0.84 USD from Claude Sonnet 5 at its default: 11 more points for 35% less per solved task, despite a per-token price five times higher. It does not always win, though. On the same subset, which Claude Opus 5.5 and Claude Fable 5.1 both largely saturate and whose scores are not comparable to the public leaderboard, Opus 5.5 at its default, `medium`, matched Fable 5.1 at its default (92.8% against 92.3%, inside run-to-run noise) for about a fifth of the cost per solved task ($0.22 USD against $1.19 USD). At `low`, Opus 5.5 solved 87.4% for $0.12 USD. These figures use the 478 problems described in reference 3. And on long research loops the frontier model does more work, not less: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Fable 5.1 at `low` scored 10 points above Sonnet 5 (66% against 56%) at about four times the cost per task ($4.66 USD against $1.20 USD), because it runs a longer research loop over a larger context. Claude Opus 5 at its default scored 71% on the same basis for $6.71 USD per task, above Fable 5.1 at its default (65% for $7.12 USD), so on research too Fable 5.1 earns its price only at `low`.
258280
259For most agent workloads, start with Claude Opus 5.5 at its default effort (`medium`), and use Claude Fable 5.1 for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5.5 at higher effort still fall short. On the SWE-bench Pro subset, Opus 5.5 at its default matched Fable 5.1 at its default for about a fifth of the cost per solved task, as noted earlier. On the coding benchmark in [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions), it scored 86.6% against 84.2% for Fable 5.1 at `medium` (a single Fable 5.1 run), for under a third of the cost per attempt ($0.84 USD against $2.68 USD). On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a chart-reading benchmark, Opus 5.5 at `low` scored 68.7 for about $0.03 USD a chart, against 62.5 for $0.15 USD from Fable 5.1 at `low` and 49 for $0.16 USD from Claude Opus 5 at `low`. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a fifth of Claude Opus 5.5's cost per question, with 63% accuracy compared with 92% for Opus 5.5, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
281For most agent workloads, start with Claude Opus 5.5 at its default effort (`medium`), and use Claude Fable 5.1 for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5.5 at higher effort still fall short. On the SWE-bench Pro subset, Opus 5.5 at its default matched Fable 5.1 at its default for about a fifth of the cost per solved task, as noted earlier. On the coding benchmark in [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions), it scored 86.6% against 84.2% for Fable 5.1 at `medium` (a single Fable 5.1 run), for under a third of the cost per attempt ($0.84 USD against $2.68 USD). On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a chart-reading benchmark, Opus 5.5 at `low` scored 68.7 for about $0.03 USD a chart, against 62.5 for $0.15 USD from Fable 5.1 at `low` and 49 for $0.16 USD from Claude Opus 5 at `low`. At the other end, Claude Haiku 5.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a twentieth of Claude Opus 5.5's cost per question, with 85% accuracy compared with 91% for Opus 5.5 run the same way. It suits high-volume and latency-sensitive work with checkable outputs.
260282
261283The ranking flips by workload, and no price list tells you which way. Price every candidate in cost per completed task on your own traffic, including Claude Opus 5.5 at its default effort and the frontier model at reduced effort.
262284
263285Price the tail of your workload, not the median: compare models on the hardest tenth of your tasks, not the typical one. On the typical task every model looks similar and the cheapest looks best, but the bill is decided by the tasks the cheaper model fails, because a failed task still bills its tokens, then the retry, then whatever the failure costs downstream. The tail is also where the money goes even when nothing fails. On a 20-problem WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) run, two problems carried 43% of the spend:
264286
265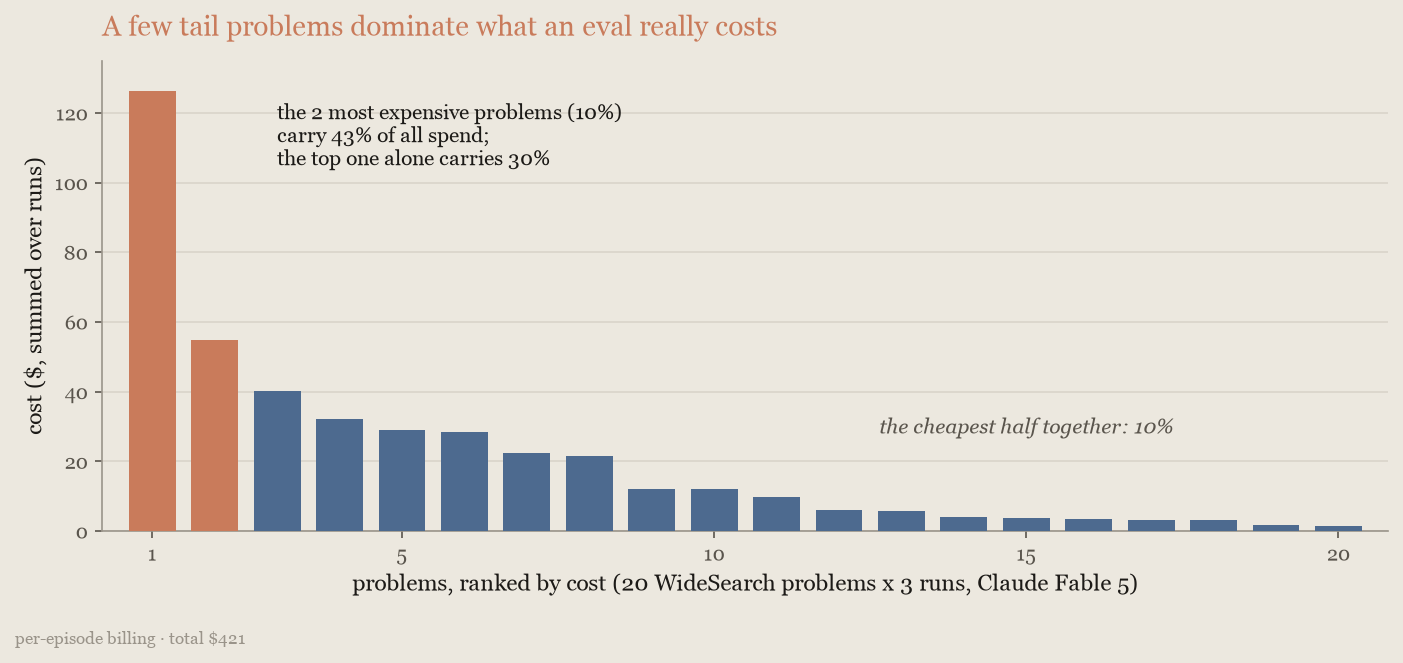
287<Frame>
288 
289</Frame>
266290
267291The [multi-model strategies](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#combine-models) exist to spend frontier intelligence on that tail without paying frontier rates for the rest.
268292
from line 294
270294
271295If you are a model or two behind, the cheapest lever is the model string. Anthropic ran recent Claude Opus, Claude Sonnet, and Claude Fable models through the same harness on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, each at its shipped defaults and priced at list rates, and ran the Opus line again on Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs):
272296
273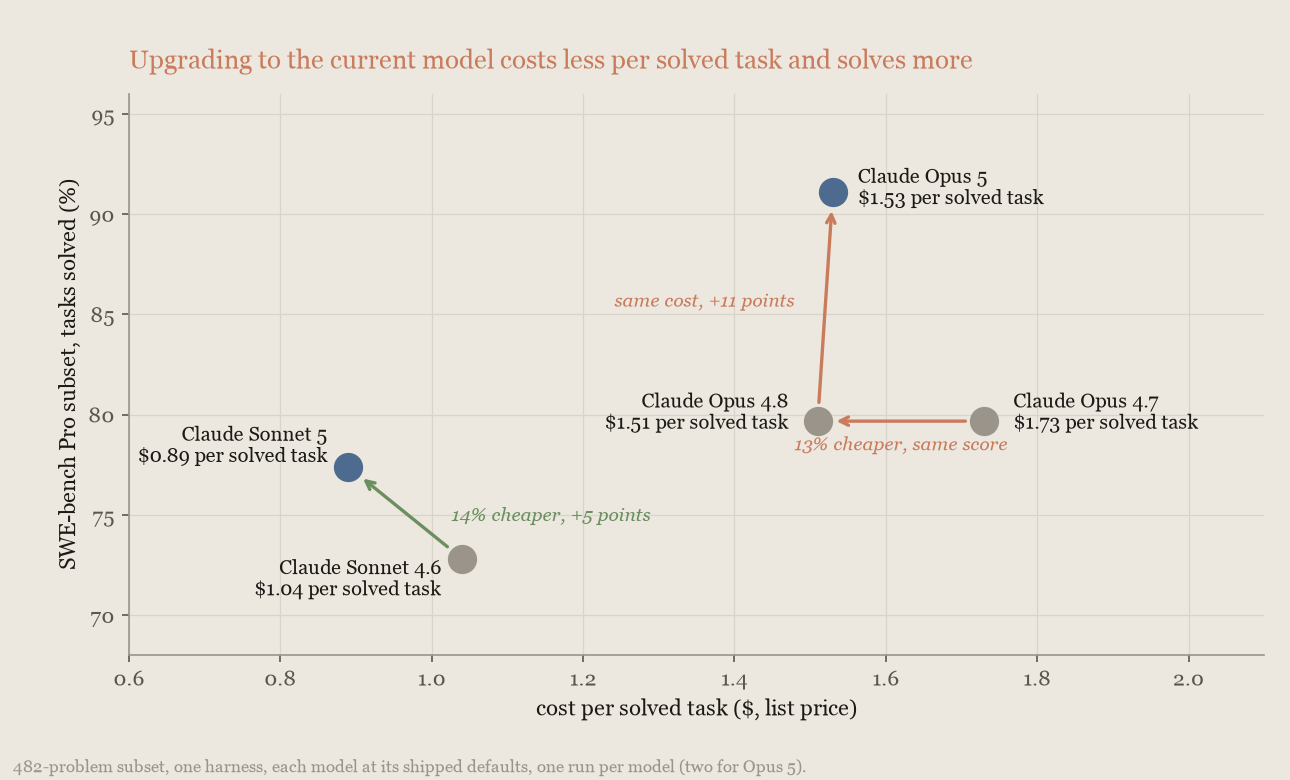
297<Frame>
298 
299</Frame>
274300
275301Anthropic prices Claude Opus 4.7, Opus 4.8, and Opus 5 identically per token, so any difference among them comes from how much work each model does per task: priced as a customer is billed, Claude Opus 4.8 solves the same share of tasks as Claude Opus 4.7 for 14% less per solved task, and Claude Opus 5 then solves 12 more points of tasks at 21% more per solved task. Claude Opus 5 at `low` effort beats Opus 4.8's default on this benchmark for about 30% of its cost per solved task, so the cheapest upgrade is the new model at a lower setting. Sonnet 5's saving comes from its lower per-token price, which more than offsets the extra tokens it uses per task compared with Sonnet 4.6: 15% less per solved task for 5 more points. The frontier tier gained the same way: Claude Fable 5.1 matches Claude Fable 5's score for 43% less per solved task, most of it the lower cache-read price. That direction is not guaranteed: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same upgrade costs 41% more per task at `high` (79% more at `low`) for its 2 to 3 extra points on the tasks clean in every arm (reference 7), because the new model does more work per task there. The input and output prices are the same and the cache read is 4x cheaper, so measure the upgrade on your own workload before assuming it saves.
276302
from line 306
280306
281307### Tune effort
282308
283Effort is the most direct way to tune a model to your task. The `effort` parameter governs how much thinking, tool calling, and self-verification the model does, and `high`, the default on most models, suits demanding tasks; Claude Opus 5.5 defaults to `medium`. Cost scales with all that activity; accuracy scales only with the part your task needs. Below the model's ceiling, the highest effort levels pay for depth the task never uses.
309Effort is the most direct way to tune a model to your task. The `effort` parameter governs how much thinking, tool calling, and self-verification the model does, and `high`, the default on most models, suits demanding tasks; Claude Opus 5.5 and Claude Haiku 5.5 default to `medium`. Cost scales with all that activity; accuracy scales only with the part your task needs. Below the model's ceiling, the highest effort levels pay for depth the task never uses.
284310
285311On the research and knowledge-work benchmarks (WideSearch[1](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), DeepWideSearch[6](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and GDPval[2](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), all with Claude Fable 5), the curve of accuracy against cost is nearly flat: `low` gave up 1 to 3 points for a third to a half off the cost per task, `medium` matched the default's accuracy at about 70% to 87% of its cost, and the default bought nothing measurable over `medium` on any of the four. On DeepWideSearch, `low` also matched an orchestrator with a Claude Sonnet 5 worker at 29% lower cost: lowering effort beat an architecture change.
286312
from line 314
288314
289315Long-horizon coding is where effort genuinely buys accuracy. On SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), measured against `high`, Claude Opus 5.5 scored about 2.5 points lower at its default, `medium`, for about 70% of the cost, and about 8 points lower at `low` for about a third of the cost; `xhigh` scored about 1.4 points higher for 2.5 times the cost of `high`: a real tradeoff, which [re-running failures at higher effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) turns back into a saving. This chart plots accuracy against cost for the research and knowledge-work benchmarks and for SWE-bench Pro:
290316
291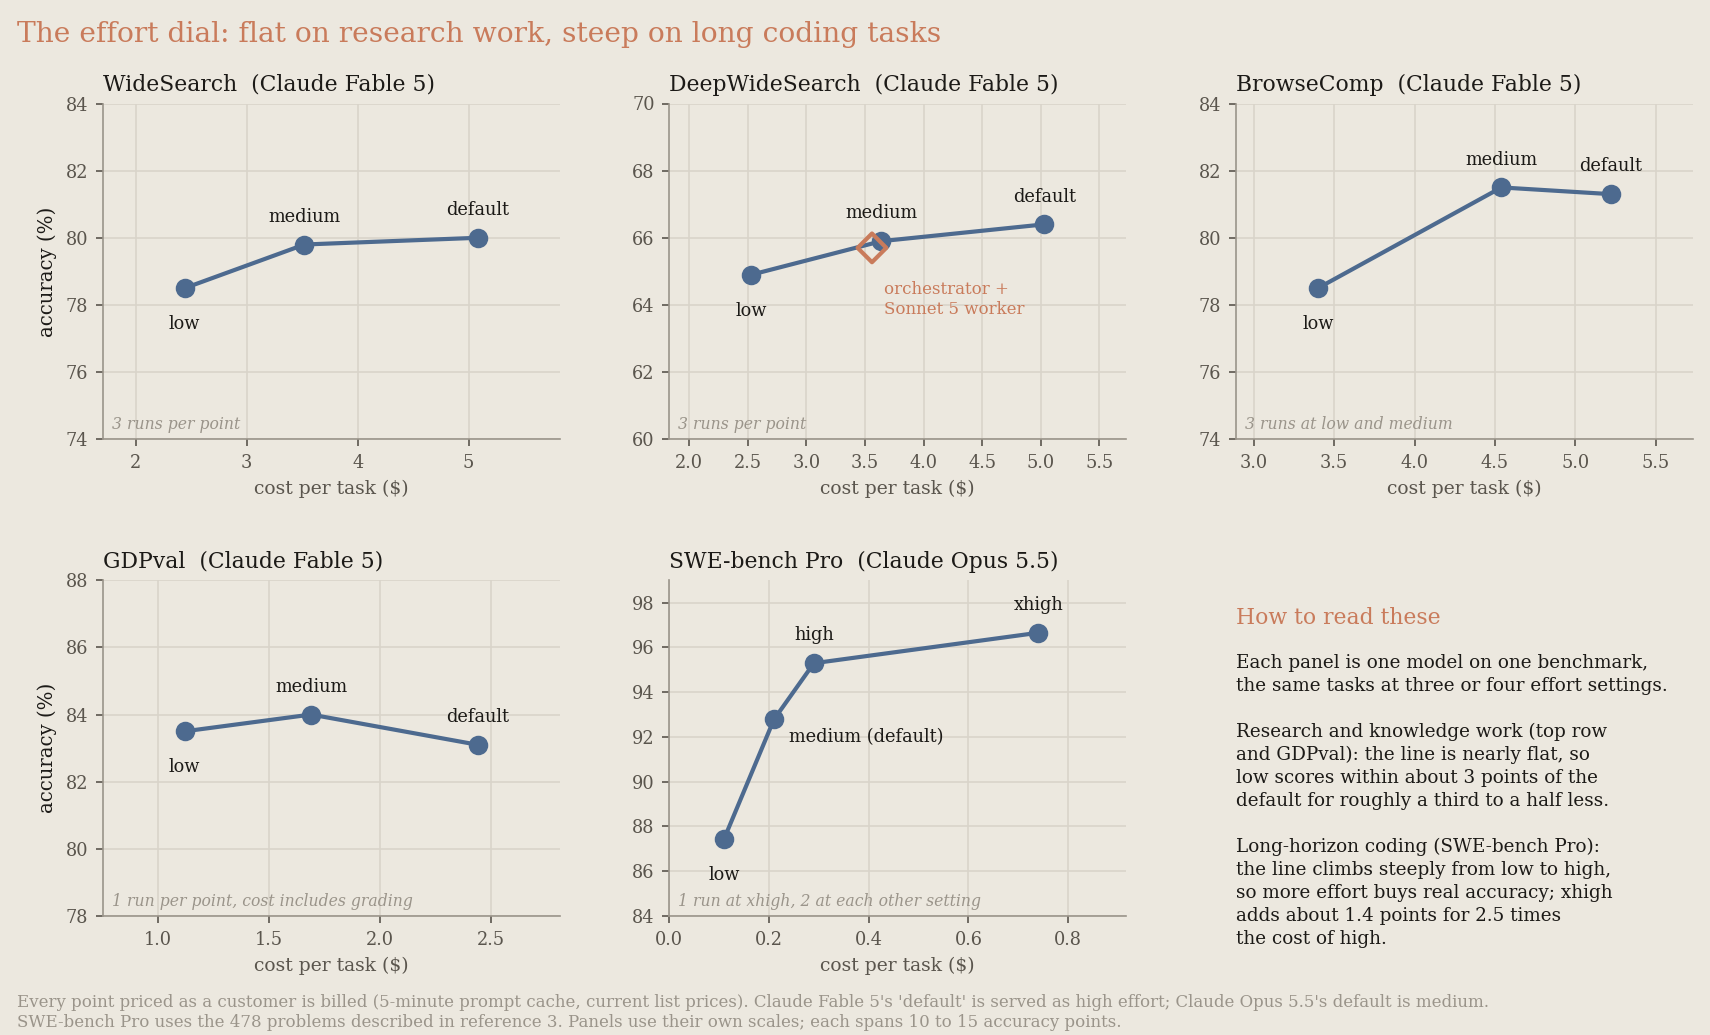
317<Frame>
318 
319</Frame>
292320
293321Two consequences follow. First, draw this curve for your own workload before you add a second model: in these internal measurements, a multi-model configuration that looked cheaper than the default single model cost more than that same model at lower effort. Second, this curve is the single-model baseline any multi-model strategy must beat, so [step 2 of measuring on your own workload](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#measure-on-your-own-workload) baselines across effort levels.
294322
295323Hard work does not automatically need high effort. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Fable 5.1 scored nearly the same at `low`, `medium`, and `high` while the cost per task rose from $4.66 USD to $7.12 USD, so raising the effort in this case does not increase the quality of the output noticeably; on the 21 tasks clean in every arm (reference 7), Claude Fable 5 was flat across effort too, though the chart's 33-task basis, which drops each model's own cut-short attempts, shows it climbing. Measure the curve on the model you ship, not the one you measured last:
296324
297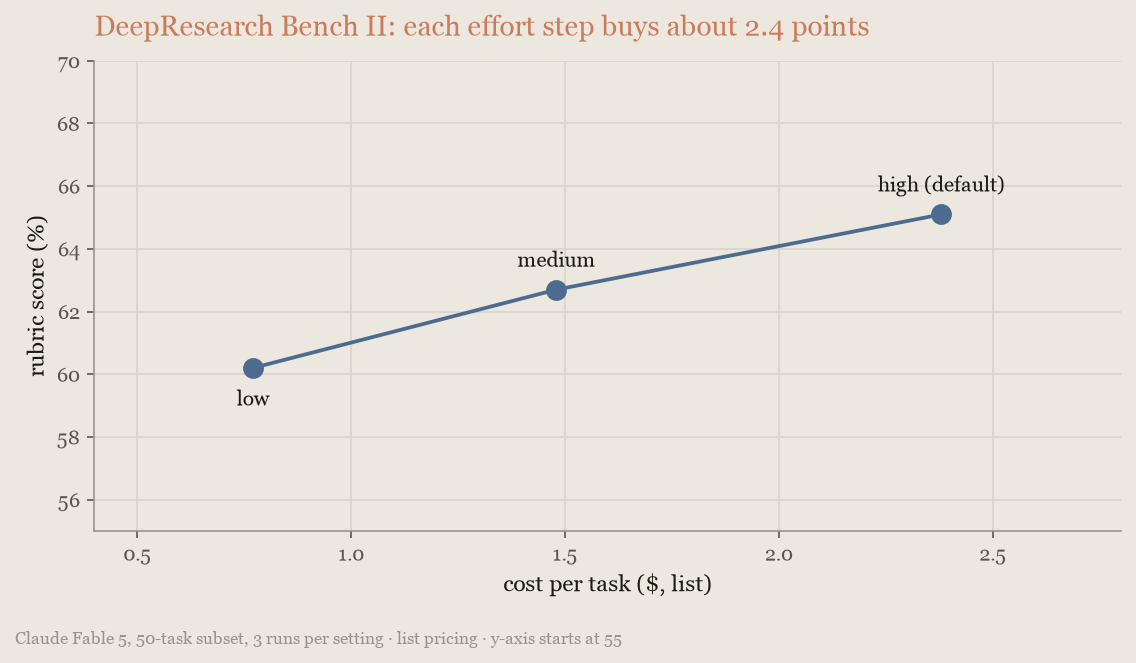
325<Frame>
326 
327</Frame>
298328
299329The task description alone does not reveal which kind of workload you have, so sweep two or three effort levels on a sample of your own traffic and read the answer off the curve. Test each level in a separate session: changing top-level effort mid-session invalidates the cache (see [Cache repeated context](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context)) and distorts the comparison. For parameter details, see [Effort](https://platform.claude.com/docs/en/build-with-claude/effort).
300330
from line 334
304334
305335Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5.5 at `low`, 13% of tasks failed; with those re-run at `high`, about 97% passed for about $0.17 USD each, against 95.3% for $0.29 USD running everything at `high`: a slightly higher pass rate for a little over half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 97% for about $0.24 USD. Most of the small lift is the second attempt (re-running the failures of one `high` run at `high` scores about the same, for more money), so use this policy for the saving, not the lift:
306336
307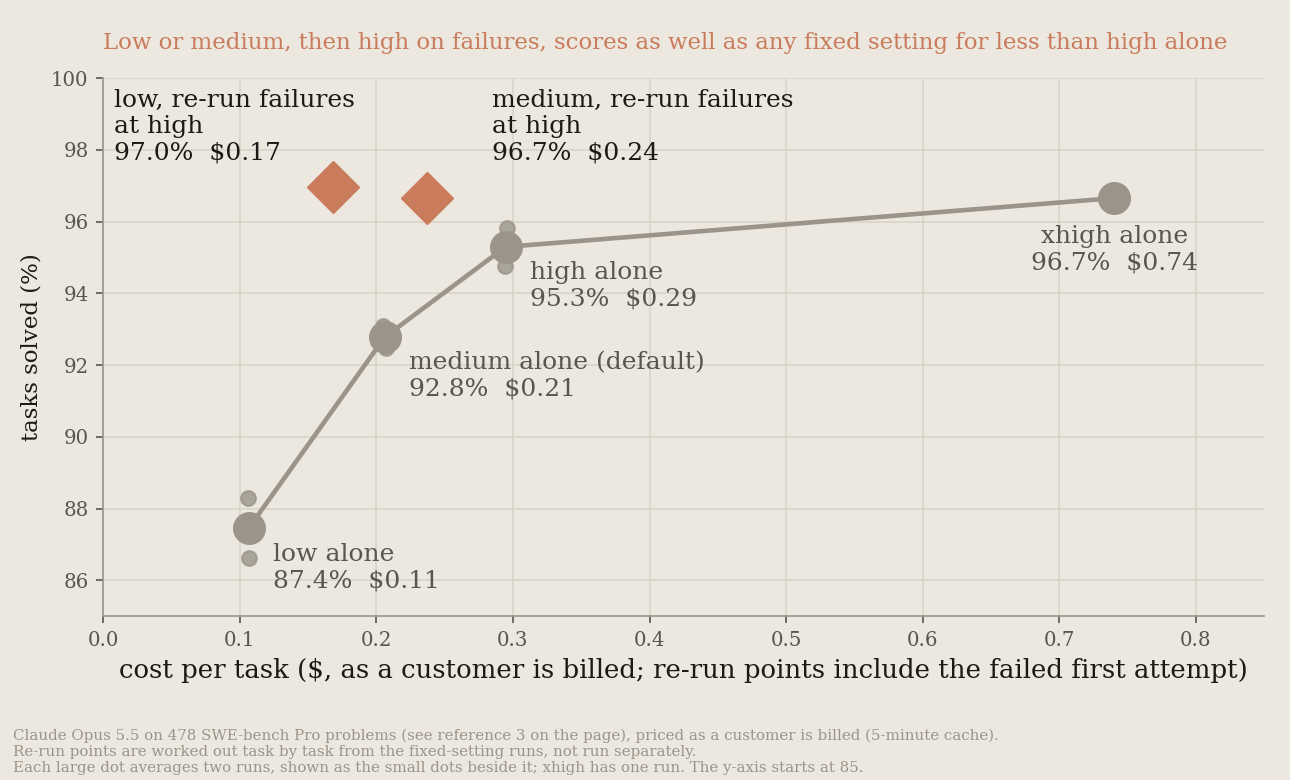
337<Frame>
338 
339</Frame>
308340
309341Two conditions apply. First, you need a failure signal (here, the benchmark's own tests); a checker that passes bad work lets those failures through. Second, every first-pass failure takes two runs' worth of wall-clock time, so the saving is paid for in latency on the failures.
310342
from line 346
314346
315347Anthropic measured pass rate and cost per task on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) with Claude Fable 5.1 as the budget tightened:
316348
317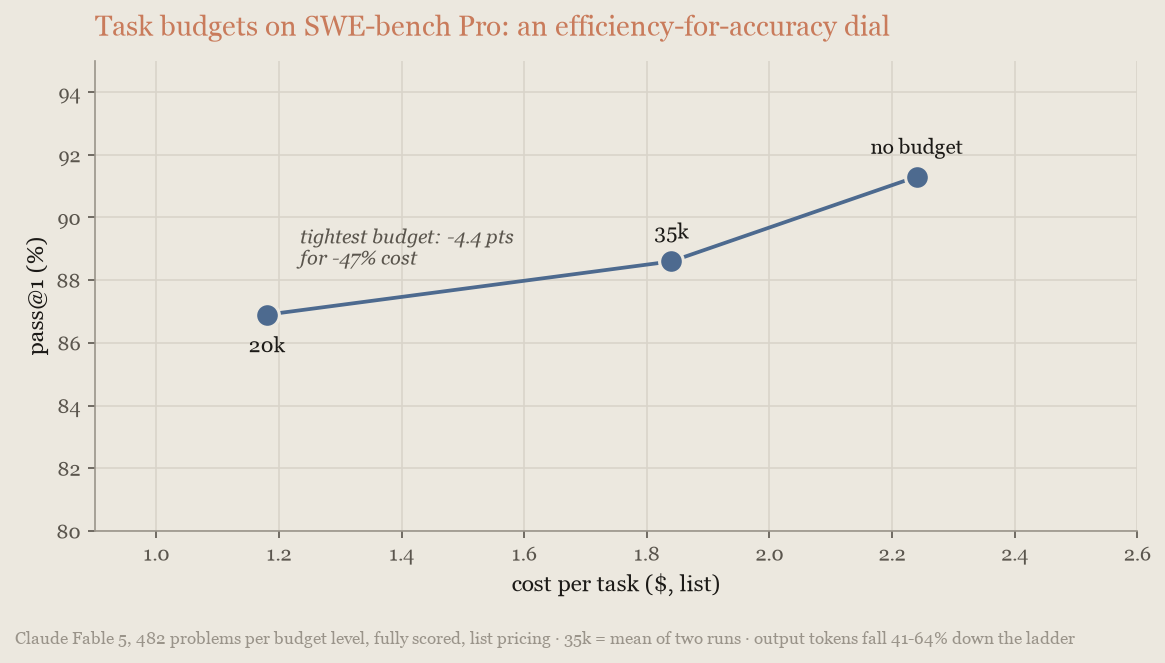
349<Frame>
350 
351</Frame>
318352
319353A generous budget cut cost per task 44% for about 3 points of pass rate, at the edge of run-to-run noise, and the tightest allowed budget cut it 58% for 6 points. Budgets bought efficiency here, at a price in pass rate that grows as the budget tightens.
320354
from line 385
351385triage-now | bug-confirmed | Clear repro steps show prompt queues indefinitely after cancelled question.
352386```
353387
354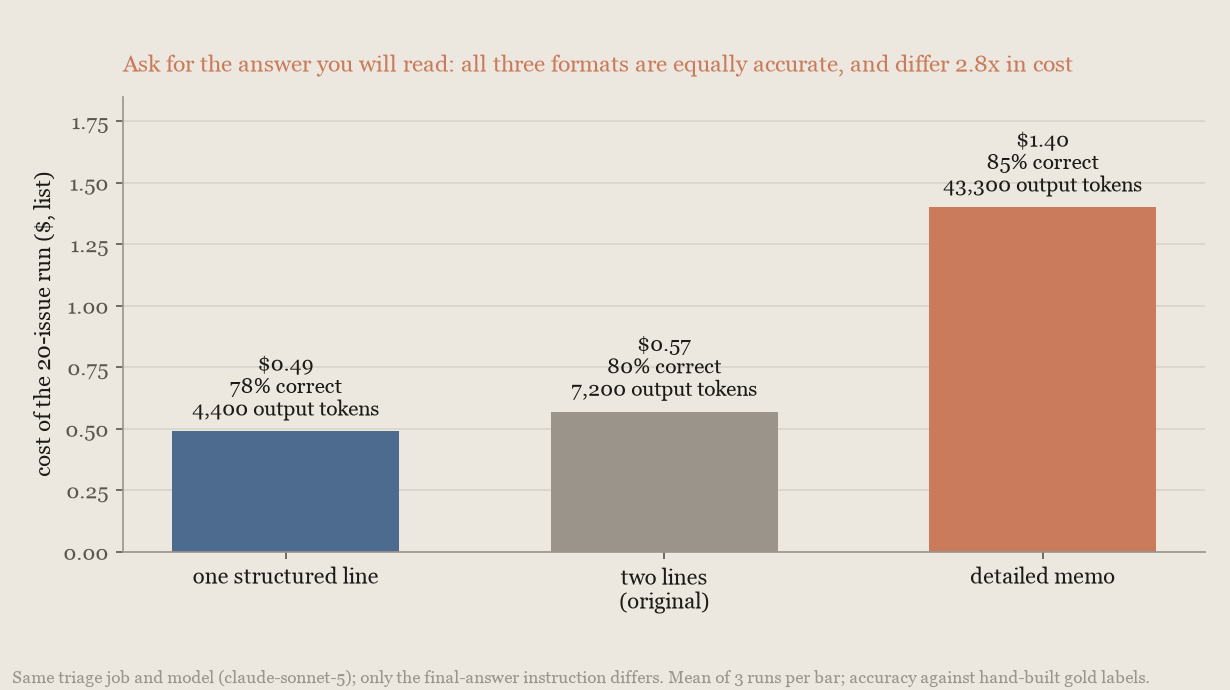
388<Frame>
389 
390</Frame>
355391
356392The one-line answer used 39% fewer output tokens than the two-line original and cost 14% less per run. The memo used six times the output tokens and cost 2.8 times the one-line answer. All three scored within run-to-run noise of each other against the gold labels, so the formats differ in what you pay far more than in what they get right. Ask for the answer you will read, not the one that looks thorough.
357393
358394At the lower `max_tokens` cap both models spend less per attempt but solve proportionally fewer tasks, so cost per solved task barely moves:
359395
360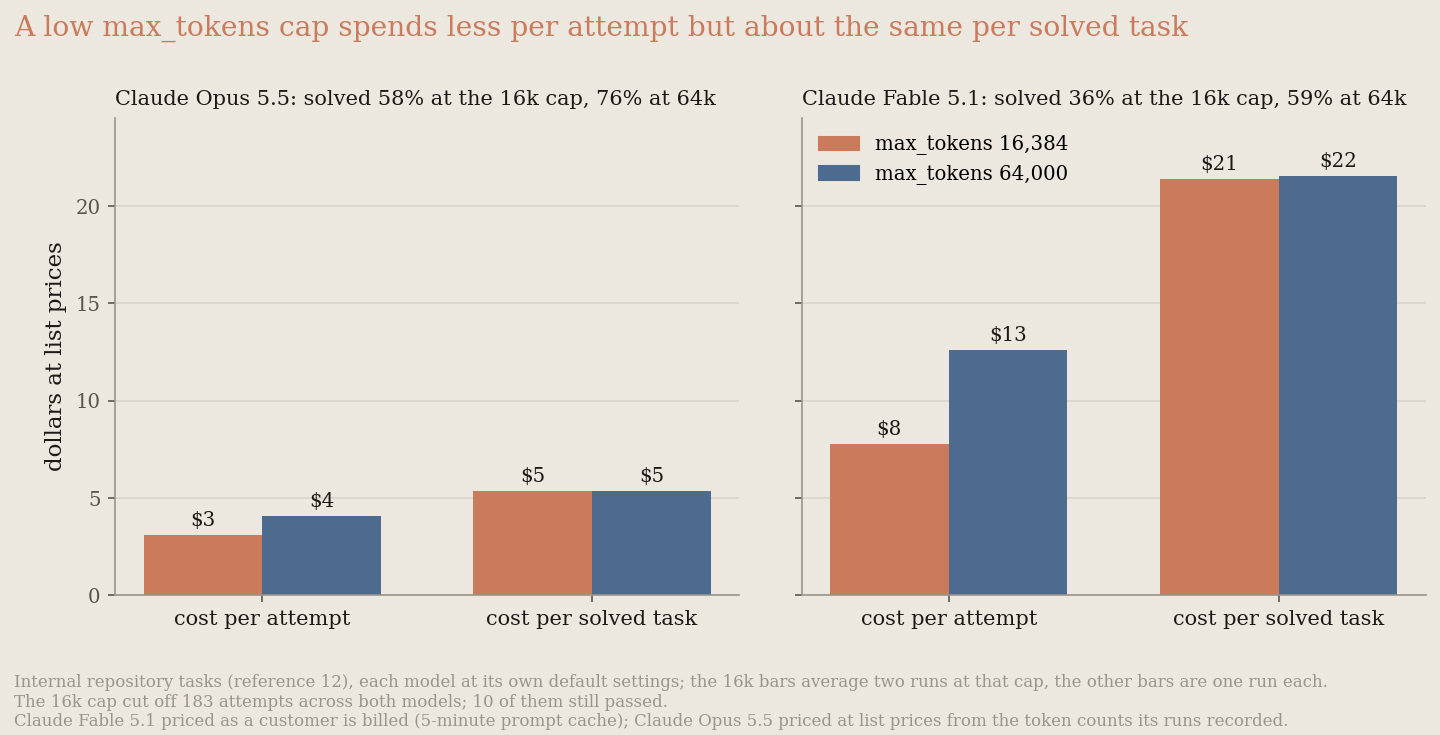
396<Frame>
397 
398</Frame>
361399
362400Almost every turn finishes far below either cap. The rare long turn is what the higher cap buys:
363401
364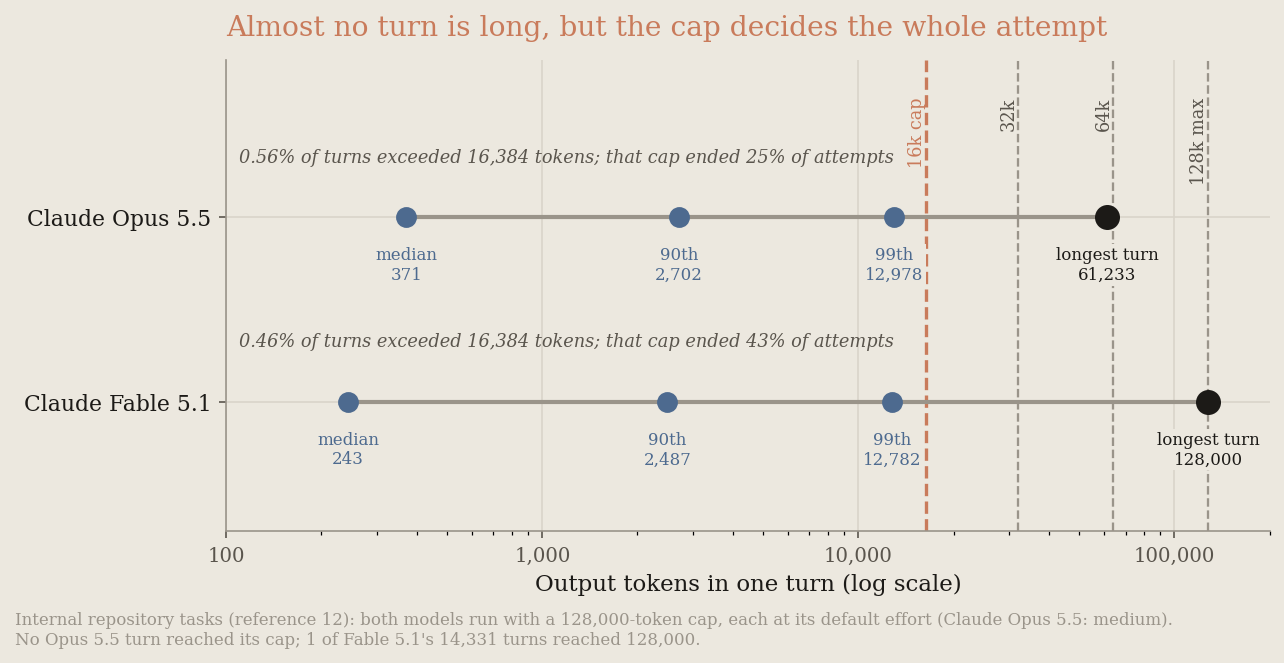
402<Frame>
403 
404</Frame>
365405
366406### Show the model elapsed time
367407
from line 409
369409
370410Anthropic measured both changes together with Claude Opus 5.5 at its default effort, `medium`, on two public benchmarks, DRACO[21](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) and HLE[22](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and on an internal set of 70 research-level physics problems, adapted from the public CritPt benchmark[23](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). This page calls that set the physics set. Each of the three ran with a single agent, with a team in which a lead agent can start any number of helper agents of the same model, and, for comparison, with a single agent at `low` effort and no changes. Unless a sentence says average, time and cost figures are for the typical task: the median, over tasks, of each task's ratio between the two configurations compared. The following chart plots average score against average cost per task for each configuration. A second row gives the typical task's time as a ratio, with both changes compared with the same setup without them, and at `low` effort compared with `medium`. A third row gives the average score change for the same comparisons, with its 95% interval:
371411
372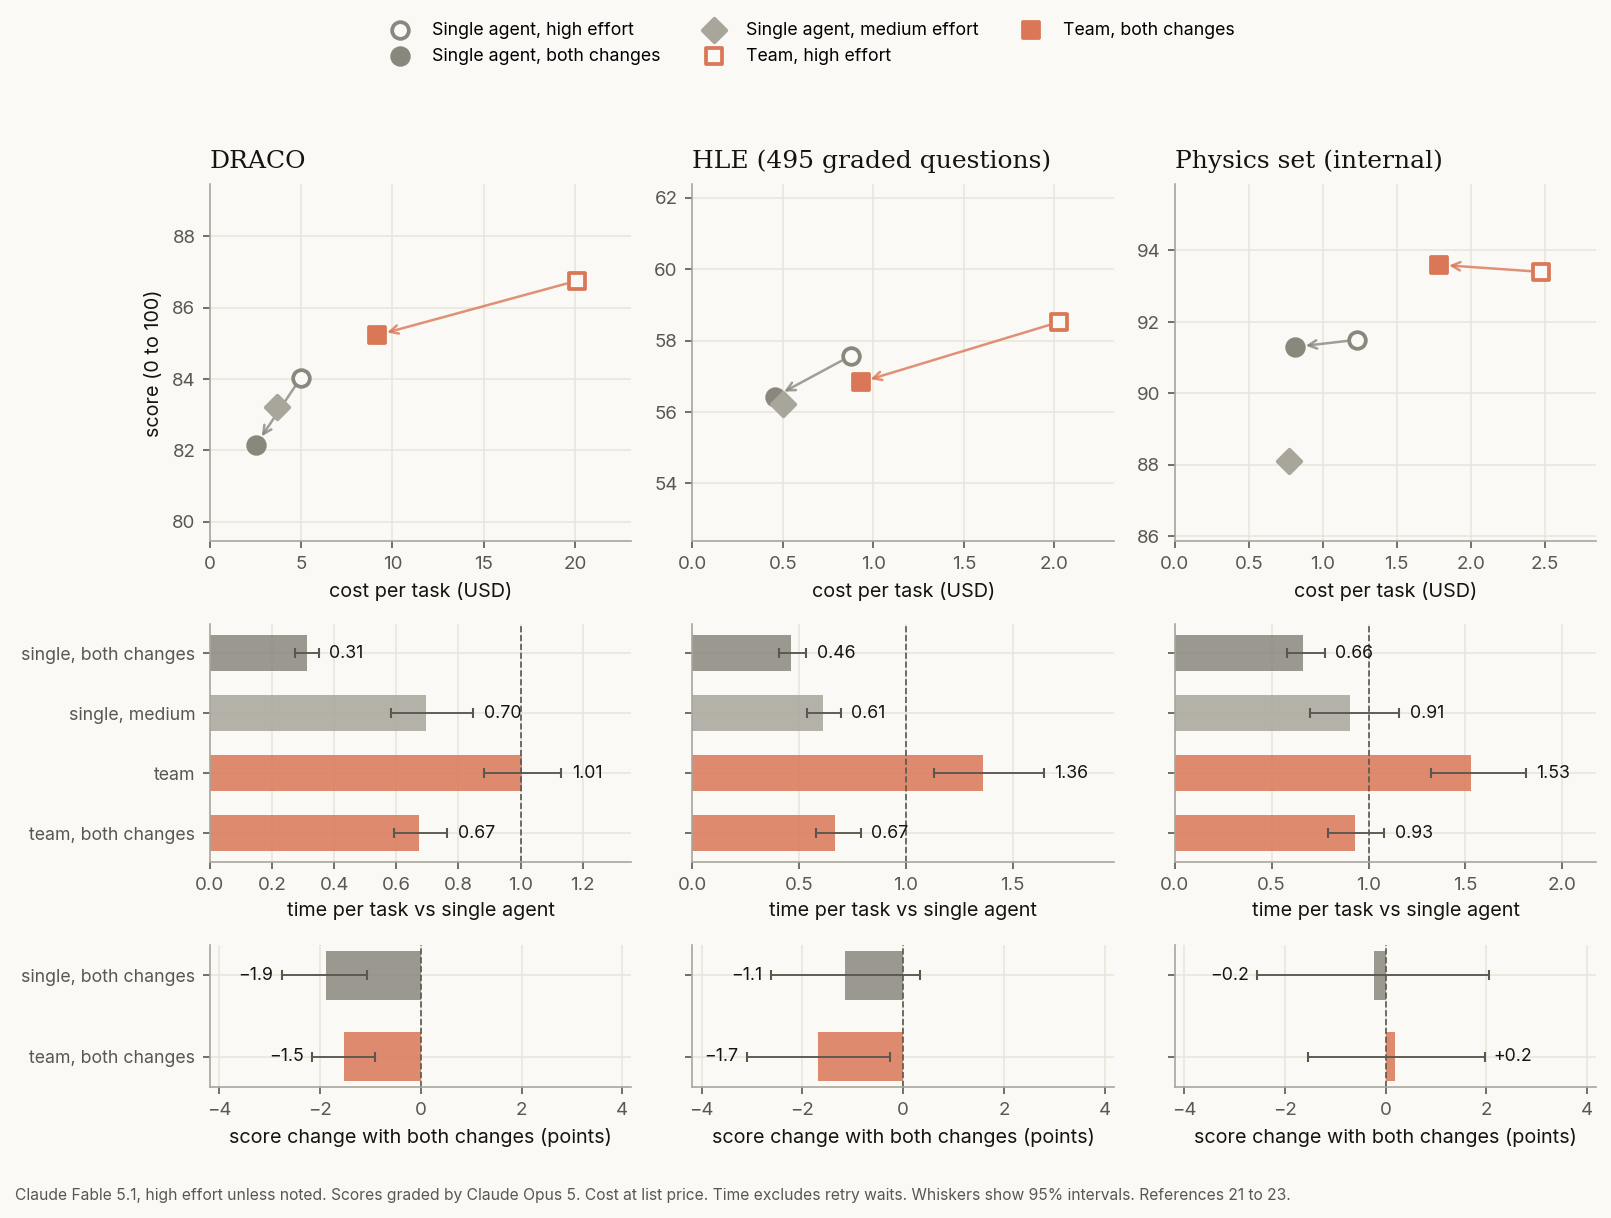
412<Frame>
413 
414</Frame>
373415
374416**On long research tasks.** On DRACO[21](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), the two changes cut a single agent's time by 47% and its cost by 60% on the typical task. Its average cost fell from $1.13 USD to $0.44 USD per task, and it made about half as many requests per attempt. Its score was 4.1 points lower (95% interval 2.9 to 5.2 lower).
375417
from line 517
475517
476518To use it, add the [advisor tool](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool) to your request. This beta feature runs the whole strategy server-side in one `/v1/messages` request: the executor emits a tool call, Anthropic runs the advisor inference, and the executor continues with the advice; you write no orchestration code. On Claude Managed Agents, [give the session an advisor](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration#give-the-session-an-advisor) by adding an `advisor` entry to the agent's `multiagent` roster; the session's primary thread consults it the same way. Claude Code supports it too; see [escalating hard decisions with the advisor tool](https://code.claude.com/docs/en/advisor).
477519
478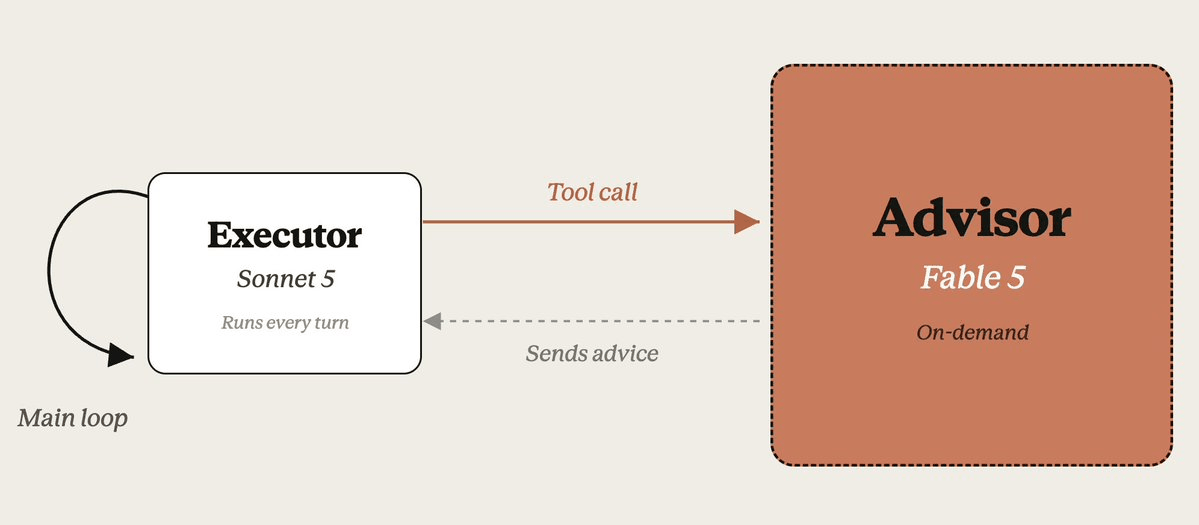
520<Frame>
521 
522</Frame>
479523
480524**What sets the payoff.** The advisor sees the task only through the executor's calls, so two things decide how much it helps.
481525
482The first is the gap between the models. The advisor can only hand over capability the executor lacks: on GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a Claude Haiku 4.5 executor gained a great deal from a Claude Opus 5 advisor, a Claude Sonnet 5 executor gained a few points, and a frontier executor almost nothing.
526The first is the gap between the models. The advisor can only hand over capability the executor lacks: on GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Sonnet 5.5 alone tied Claude Opus 5.5 alone at 91% with refusals counted as wrong, but only because Opus 5.5 refused six biology questions per run against Sonnet 5.5's one. On the questions each answered, Opus 5.5 led by about 2 points. Claude Haiku 5.5 alone scored 6 points below Opus 5.5 (85%), so an Opus 5.5 advisor had more to hand over to it.
483527
484The second, and the fragile one, is whether the executor actually asks (the consult rate). An executor at low effort can stop detecting that it is stuck: a pairing that consults on most tasks at the default effort can fall to consulting on almost none when effort is lowered, and then scores below the executor alone. The rate also varies by task: on DeepSWE[10](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a low-effort Sonnet 5 executor kept asking and gained 23 points; on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same executor stopped. When the executor does ask, it recovers much of the gap. Across the pairings in the following chart whose executor kept asking, the advisor closed at least half the gap to the stronger model (the coding pairing beat the stronger model outright), and you pay for the stronger model only on the consultations, which is what makes the cost cases possible:
528The second, and the fragile one, is whether the executor actually asks (the consult rate). Neither of those executors asked. In two runs each, Claude Haiku 5.5 and Claude Sonnet 5.5 called the Opus 5.5 advisor on none of the 198 questions, so both pairings scored within run-to-run noise of the executor alone. These runs added the advisor tool as is, without a system prompt that asks the executor to consult it, like those the [advisor tool page suggests](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#prompting-for-coding-and-agent-tasks). The advisor tool's definition, about 1,000 prompt tokens per request, still added 12% to Haiku 5.5's cost per question and 25% to Sonnet 5.5's. An executor at low effort can stop detecting that it is stuck: a pairing that consults on most tasks at the default effort can fall to consulting on almost none when effort is lowered, and then scores below the executor alone. The rate also varies by task: on DeepSWE[10](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) a low-effort Sonnet 5 executor kept asking and gained 23 points; on SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same executor stopped. In the following chart, only the coding pairing's executor consulted on most attempts, and only its gain can be credited to the advisor: 1.7 points above Opus 5.5 alone at `high`, at the edge of run-to-run noise. The executors that rarely or never consulted gained nothing beyond noise, and the one at `low` effort lost 7 points. When the executor does ask, you pay for the stronger model only on the consultations, which is what makes the cost cases possible:
485529
486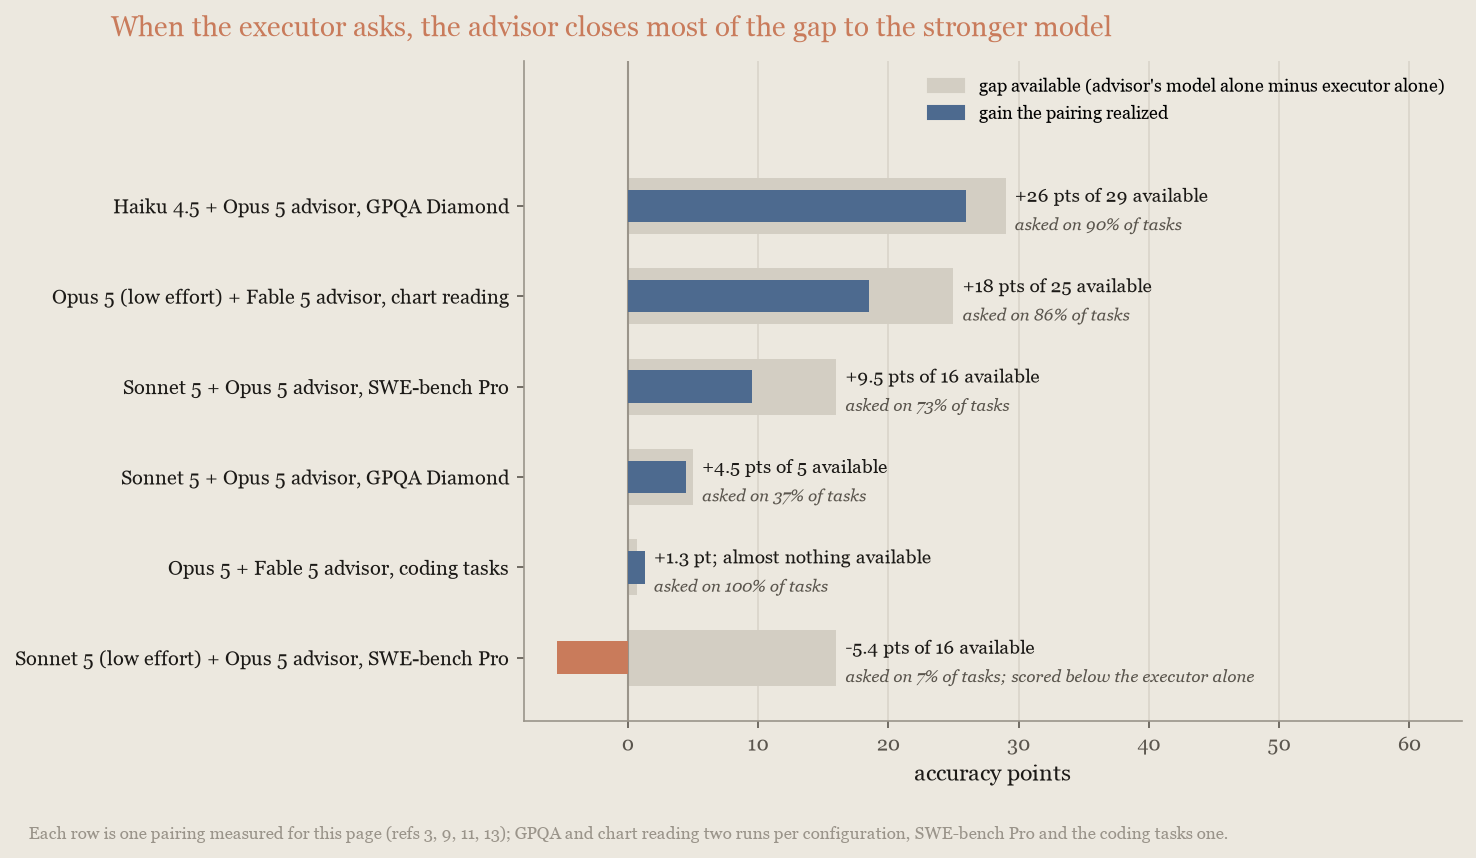
530<Frame>
531 
532</Frame>
487533
488534The consult rate responds to prompting. With only the tool's built-in description, executors under-call, especially on coding work, so the [advisor tool documentation](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#prompting-for-coding-and-agent-tasks) gives a system prompt that asks for one call before substantive work and one before finishing, about two to three calls per task. The coding pairing measured next ran at that cadence with Claude Opus 5 as the executor, about two consultations on every task; with Claude Opus 5.5 as the executor it asked for advice about 1.4 times per attempt, and 4% of its attempts received no advice. That page also covers nudging an under-calling executor and capping calls client-side to bound cost. So watch the consult rate: prompt for it, measure it, and restore the executor's effort if it collapses.
489535
from line 537
491537
492538On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5.5 executor at `high` with a Claude Fable 5.1 advisor scored 90.1% at $2.92 USD per attempt. That is 1.7 points over Opus 5.5 alone at `high`, the executor's own setting, a gap at the edge of run-to-run noise with five attempts per task, for about 2.1 times the money; against Opus 5.5 at its default, `medium`, it is 3.5 points for about 3.5 times the money. It lands about on Opus 5.5's own effort curve, so the advisor buys about what more effort does: Opus 5.5 alone at `xhigh` scored 91.1% for $4.11 USD per attempt (one attempt per task). In August, a Claude Fable 5.1 advisor over a Claude Opus 5 executor was the most accurate configuration measured, at $6.21 USD per attempt, a little over twice what the Opus 5.5 pairing costs. The chart plots the Opus 5.5 pairing against Opus 5.5's own effort curve and Claude Fable 5.1's from August:
493539
494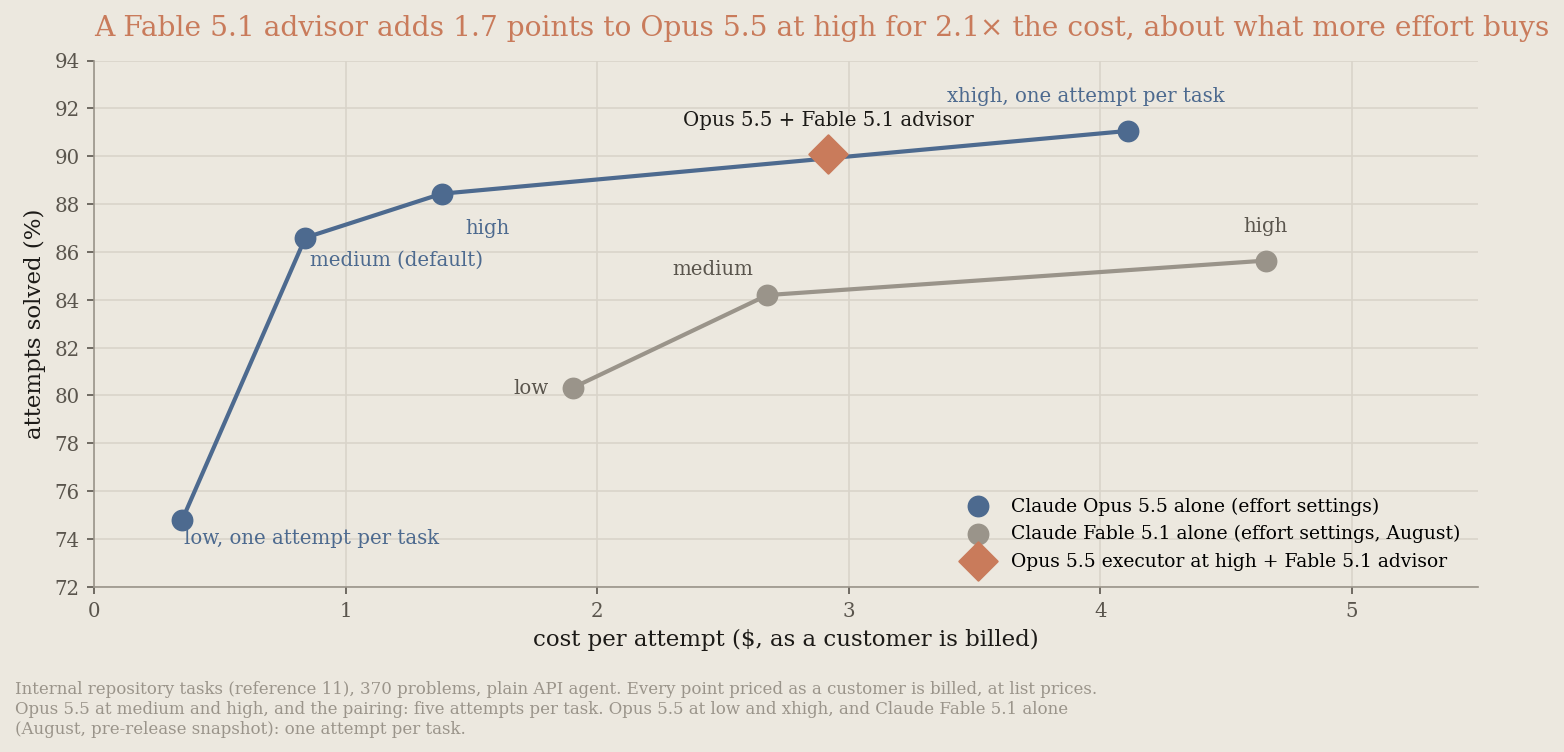
540<Frame>
541 
542</Frame>
495543
496544An earlier measurement through [Claude Code's advisor mode](https://code.claude.com/docs/en/advisor) also ranked its advisor pairing above both of its models alone. Read the Claude Opus 5.5 result as a shape to test on your workload: the advisor buys a few points for about twice what the executor costs alone. A wider capability gap does not guarantee a better deal. The latency cost is the consultations themselves: about one or two extra frontier-model calls per task on this benchmark, each on the task's critical path.
497545
from line 555
507555
508556To build one, use [multiagent orchestration](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration) in Claude Managed Agents: configure a coordinator agent (the orchestrator) and a roster of worker agents, each with its own model. For a complete working example with a frontier coordinator and Claude Sonnet 5 workers, see the Claude Cookbook recipe [Coordinator pattern: big models for planning, small models for execution](https://github.com/anthropics/claude-cookbooks/blob/main/managed_agents/CMA_plan_big_execute_small.ipynb).
509557
510
558<Frame>
559 
560</Frame>
511561
512562This pattern saves wall-clock time when workers can run in parallel: on the corpus benchmark[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), an episode took about 2.3 hours with the coordinator running the platform's documented limit of 25 concurrent workers, compared with 15 to 20 hours solo. It saved money in only two measured situations. On work a single model could handle alone, the same model at lower effort was cheaper every time.
513563
from line 565
515565
516566Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost about half as much as Claude Fable 5 alone on average and about a third as much at the 90th percentile ($12 USD compared with $33 USD), and the solo model's single most expensive run, at $84 USD, was also wrong:
517567
518
568<Frame>
569 
570</Frame>
519571
520572Delegation paid on the routine, normally solvable share of the work, the opposite of the intuition that workers are for hard problems. On the full, harder BrowseComp set, the economics reversed. If your traffic has a long cost tail on routine tasks, this is the orchestrator case to measure first.
521573
from line 575
523575
524576Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5.1 solo cost $468 USD to $552 USD per episode across the three effort settings, and only its accuracy moved. The coordinator configuration, a Claude Fable 5.1 lead over 25 Claude Sonnet 5 workers, cost about half as much as those settings (47% to 55% less) and scored 10 to 12 points below them, in about 2.3 hours per episode against 15 to 20, while beating a Claude Sonnet 5 solo baseline outright:
525577
526
578<Frame>
579 
580</Frame>
527581
528582The token accounting shows the scale of the reading: the coordinator configuration read about 560 million cached tokens per episode, about one and a half times the solo model's roughly 365 million, nearly all of them at Claude Sonnet 5's cache-read rate, and still cost about half as much overall. Fable 5.1 at `high` effort still holds peak accuracy, at about 2.2 times the coordinator configuration's cost, so delegation here buys most of the accuracy, not all of it.
529583
from line 877
8238776. **DeepWideSearch:** "DeepWideSearch: Benchmarking Depth and Width in Agentic Information Seeking," arXiv:2510.20168, 2025. The 220 questions span 15 domains, each combining many-row collection with multi-hop retrieval; measured on the benchmark's standing row set, 3 runs per configuration, run August 2, 2026 (the single-worker team point ran July 26 to 27, 2026).
8248787. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs per setting, on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with the platform's own web search and fetch tools (August 26 to 27, 2026); scored on the 33 tasks no configuration refused, with attempts the production safety classifiers cut short removed; costs are what a customer is billed, the platform's requests plus web-search fees. Scores are each model's mean on the 33-task basis with its own pre-empted tasks removed; on the 21 tasks clean in every arm, Claude Fable 5.1 holds a 2-to-3-point lead over Claude Fable 5 at every effort level and both models are flat across effort. The caching chart re-prices the same requests with every input token at the uncached rate. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Claude Opus 5 at its default effort ran on the same surface and subset, three runs, on August 28, 2026: 68.8% on the raw 50 tasks, 70.8% on the 33-task basis, and 71.1% on the 21-task set, at $6.71 USD per task ($23.72 USD without caching); none of its attempts was cut short by the safety classifiers, under a safeguards deployment newer than the one the other models ran under.
8258798. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is a run in which the Claude Fable 5.1 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers, run August 30, 2026; its three episodes scored F1 0.764, 0.825, and 0.791 after the extras audit (raw 0.751, 0.821, and 0.781) for $225 USD, $234 USD, and $283 USD. The Claude Sonnet 5 solo configuration ran August 3 to 4, 2026; the Claude Fable 5.1 solo configurations ran August 24 to 25, 2026, under the platform's launch serving settings, three seeds per effort setting, on the same corpus build. The sandbox image carried installed copies of part of the corpus, and Claude Fable 5.1's final assembly step compared against them in 7 of 9 episodes; re-grading without those additions moved the affected seeds by up to 3 points. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
8269. **GPQA Diamond:** Rein et al., "GPQA: A Graduate-Level Google-Proof Q\&A Benchmark," 2023. The 198-question Diamond subset, two runs per configuration, run August 7, 2026 (Claude Opus 5.5: September 19, 2026), model-graded against reference answers, advisor tokens metered per request. A platform safety check refused two biology questions on the Claude Sonnet 5 executors, and one of them also on Claude Opus 5; excluding them changes no comparison by more than one point. Claude Opus 5.5's 92% comes from two runs that set `fallbacks: "default"` to opt into [server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback), with any attempt that still ended in a refusal counted as wrong. In each run the safety check flagged six biology questions, Claude Opus 5 answered five of them through the fallback, and the sixth still ended in a refusal. Opus 5.5's cost per question includes those fallback answers. Without counting refusals as wrong, these runs score 93%, because the grader still assigns an answer option to a refused attempt, usually the correct one. With refusals counted as wrong, Claude Opus 5's runs score 91% (one refusal per run), as do two Claude Opus 5.5 runs with fallback off, in which Opus 5.5 refused five or six biology questions per run.
8809. **GPQA Diamond:** Rein et al., "GPQA: A Graduate-Level Google-Proof Q\&A Benchmark," 2023. The 198-question Diamond subset, two runs per configuration, run August 7, 2026 (Claude Opus 5.5: September 19, 2026), model-graded against reference answers, advisor tokens metered per request. A platform safety check refused two biology questions on the Claude Sonnet 5 executors, and one of them also on Claude Opus 5; excluding them changes no comparison by more than one point. Claude Opus 5.5's 92% comes from two runs that set `fallbacks: "default"` to opt into [server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback), with any attempt that still ended in a refusal counted as wrong. In each run the safety check flagged six biology questions, Claude Opus 5 answered five of them through the fallback, and the sixth still ended in a refusal. Opus 5.5's cost per question includes those fallback answers. Without counting refusals as wrong, these runs score 93%, because the grader still assigns an answer option to a refused attempt, usually the correct one. With refusals counted as wrong, Claude Opus 5's runs score 91% (one refusal per run), as do two Claude Opus 5.5 runs with fallback off, in which Opus 5.5 refused five or six biology questions per run. Claude Haiku 5.5 and Claude Sonnet 5.5, each alone and with a Claude Opus 5.5 advisor, ran two runs per configuration on October 7, 2026, alongside two more Claude Opus 5.5 runs, all with fallback off, at each model's default effort, and with refusals counted as wrong. The safety check refused one biology question per run on Claude Haiku 5.5 and Claude Sonnet 5.5 alone, one in two runs on Haiku 5.5 with the advisor, none on Sonnet 5.5 with the advisor, and six per run on Opus 5.5, which scored 91% with them counted as wrong and 93.5% on the questions it answered. The advisor configurations added the tool without a prompt asking for consultations, and neither executor called the advisor on any question.
82788110. **DeepSWE:** Datacurve, "DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks," arXiv:2607.07946, 2026. The set has 113 original tasks across five languages with program-based verifiers. Pairings are two runs each, run August 7, 2026, with advisor tokens metered per request, and used a client-side advisor loop rather than the advisor tool, with identical accounting. Single-model effort sweeps are single runs priced from token counts, a cache-aware approximation. Costs per task are run totals divided by 113.
82811. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures were measured with a 128,000-token output cap, one run per configuration: Opus 5 alone at the default effort August 9 to 10, 2026, and at `low` and `medium` August 10, 2026; Claude Fable 5.1 alone at five explicitly set effort values August 20, 2026 (the chart shows three of them); and the pairing August 24 to 25, 2026. Claude Opus 5.5 alone ran on all 370 tasks, September 19 to 20, 2026: at its default effort (`medium`) and at `high` with five attempts per task, and at `low` and `xhigh` with one (369 of 370 scored at each, after a setup-check failure). The Claude Opus 5.5 executor at `high` with the released Claude Fable 5.1 as advisor (the August runs used a pre-release snapshot) ran five attempts per task on the same dates; one task failed its setup check, so 1,845 attempts were scored. The 279 attempts in which the advisor was turned away under load were re-run, and attempts whose consults timed out were kept, as in August. The August runs had five attempts per task for the pairing and the Claude Opus 5 control and one for the other points. The August pairing averaged about two advisor consultations per attempt; the Claude Opus 5.5 pairing requested 1.39 and received 1.35. Costs are per attempt. Costs are priced as a customer's organization is metered: each agent-loop request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, and each advisor call, which uses no cache, from its recorded tokens, all at list prices. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
88211. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures were measured with a 128,000-token output cap, one run per configuration: Opus 5 alone at the default effort August 9 to 10, 2026, and at `low` and `medium` August 10, 2026; Claude Fable 5.1 alone at five explicitly set effort values August 20, 2026 (the chart shows three of them); and the pairing August 24 to 25, 2026. Claude Opus 5.5 alone ran on all 370 tasks, September 19 to 20, 2026: at its default effort (`medium`) and at `high` with five attempts per task, and at `low` and `xhigh` with one (369 of 370 scored at each, after a setup-check failure). The Claude Opus 5.5 executor at `high` with the released Claude Fable 5.1 as advisor (the August runs used a pre-release snapshot) ran five attempts per task on the same dates; one task failed its setup check, so 1,845 attempts were scored. The advisor chart compares that pairing with the released Claude Fable 5.1 alone at `high`, its default, one attempt per task on October 7, 2026: 85.7%, 317 of 370 tasks. The 279 attempts in which the advisor was turned away under load were re-run, and attempts whose consults timed out were kept, as in August. The August runs had five attempts per task for the pairing and the Claude Opus 5 control and one for the other points. The August pairing averaged about two advisor consultations per attempt; the Claude Opus 5.5 pairing requested 1.39 and received 1.35. Costs are per attempt. Costs are priced as a customer's organization is metered: each agent-loop request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, and each advisor call, which uses no cache, from its recorded tokens, all at list prices. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
82988312. **Internal repository-task benchmark (cap measurement):** A separate Anthropic-internal set of about 130 repository tasks, run August 20, 2026 (Claude Fable 5.1) and September 19, 2026 (Claude Opus 5.5, at its default effort, `medium`), with a plain API agent loop, one attempt per task. The Claude Fable 5.1 runs are 135 tasks per cap at the default effort set explicitly: the 16,384-token figure averages two runs (36.3% on both); the 64,000 and 128,000 figures are single runs (58.5% and 60.0%). Six problems drew a safety refusal in every run and count as failures. The Claude Opus 5.5 16,384-token figure averages two runs (134 and 135 tasks scored), and its 64,000 and 128,000 figures are single runs (135 tasks each); two attempts in each 16,384-token run ended in a safety refusal and count as failures. The SWE-bench Pro cap figures are one Claude Fable 5.1 run per cap at the default effort, run August 26, 2026, on a 100-problem subset stratified from reference 3's 482-problem set, not comparable to its scores; the two caps scored the same at the default. The chart's per-turn distributions come from the Claude Opus 5.5 and Claude Fable 5.1 runs at 128,000: no Opus 5.5 turn reached the cap (the longest was about 61,000 tokens, and 0.56% of its turns exceeded 16,384), and one Fable 5.1 turn reached 128,000 (0.46% of its turns exceeded 16,384).
83013. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 6 and 9, 2026 (Claude Opus 5 alone) and September 20, 2026 (Claude Opus 5.5), with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. They are also not comparable to the Chartography results in the Claude Opus 5.5 system card, which use a different grader and run at `max` effort. Two runs per configuration (three for Claude Opus 5.5), pooled; run-to-run spreads were up to 10 points. Costs are what a customer running the agent routinely is billed: each chart's first request reads the agent's shared system prompt and tools from the cache, as it does when another session of the same agent ran in the previous 5 minutes. A chart run on its own costs about $0.03 USD more with Claude Opus 5 or Claude Opus 5.5 and about $0.12 USD more with Claude Fable 5.1. The August figures are re-priced this way from the runs' usage records; the evaluation organization's own metering, which until September 10, 2026, billed Claude Opus 5's cache reads in 8,192-token blocks, overstated Claude Opus 5's costs. Costs exclude sandbox time, which added under 1% to the August runs. The Claude Fable 5.1 solo runs are from August 24, 2026, under the platform's launch serving settings, two runs per setting; six attempts hit the 15-minute session cap and score 0, and two charts per run were answered by Claude Opus 5 after a safety refusal. The Claude Opus 5 low-effort executor with a Claude Fable 5.1 advisor ran twice on August 30, 2026, under the same settings (63.0 and 67.0, mean 65.0, at $0.47 USD a chart; the advisor was consulted on 88% of tasks in each run, and 4 of its 219 replies came from Claude Opus 5 instead, each after a production safety filter stopped the advisor's own reply). Claude Opus 5.5 ran at `low`, with server-side fallback off and a safety classifier judging every tool call: three runs alone (70, 68, and 68) and three with a Claude Fable 5.1 advisor configured (59, 63, and 63), in which it consulted the advisor on 1 of 300 tasks. The consult-rate comparison for the earlier pairings comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
88413. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 6 and 9, 2026 (Claude Opus 5 alone) and September 20, 2026 (Claude Opus 5.5), with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. They are also not comparable to the Chartography results in the Claude Opus 5.5 system card, which use a different grader and run at `max` effort. Two runs per configuration (three for Claude Opus 5.5), pooled; run-to-run spreads were up to 10 points. Costs are what a customer running the agent routinely is billed: each chart's first request reads the agent's shared system prompt and tools from the cache, as it does when another session of the same agent ran in the previous 5 minutes. A chart run on its own costs about $0.03 USD more with Claude Opus 5 or Claude Opus 5.5 and about $0.12 USD more with Claude Fable 5.1. The August figures are re-priced this way from the runs' usage records; the evaluation organization's own metering, which until September 10, 2026, billed Claude Opus 5's cache reads in 8,192-token blocks, overstated Claude Opus 5's costs. Costs exclude sandbox time, which added under 1% to the August runs. The Claude Fable 5.1 solo runs are from August 24, 2026, under the platform's launch serving settings, two runs per setting; six attempts hit the 15-minute session cap and score 0, and two charts per run were answered by Claude Opus 5 after a safety refusal. The Claude Opus 5 low-effort executor with a Claude Fable 5.1 advisor ran twice on August 30, 2026, under the same settings (63.0 and 67.0, mean 65.0, at $0.47 USD a chart; the advisor was consulted on 88% of tasks in each run, and 4 of its 219 replies came from Claude Opus 5 instead, each after a production safety filter stopped the advisor's own reply). Claude Opus 5.5 ran at `low`, with server-side fallback off and a safety classifier judging every tool call: three runs alone (70, 68, and 68) and three with a Claude Fable 5.1 advisor configured (59, 63, and 63), in which it consulted the advisor on 1 of 300 tasks. The advisor chart compares that pairing with Claude Fable 5.1 alone at `high`, its default, run three times on October 7, 2026, with the same implementation and settings as the Claude Opus 5.5 runs: 82, 79, and 79, a mean of 80.0. The consult-rate comparison for the earlier pairings comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
83188514. **Support-desk prompt-audit evaluation:** An Anthropic-constructed set of 44 support tickets with deterministic grading, run in early August 2026 and reported on August 8, 2026, under six system prompts, each adding to the same clean prompt one pattern common in prompts written for Claude Opus 4.8 and Claude Sonnet 4.6. Each chart point is one of three cases (older model, newer model on the same prompt, newer model after the audit) averaged over the six prompts and 44 tickets. The Opus 5 accuracy gain has a 95% confidence interval of 3 to 8 points; the Sonnet accuracy differences are within noise.
83288615. **Data-file question set:** An Anthropic-constructed set of 25 aggregate questions over a 1,862-row slice of a public liquor-sales CSV, with ground truth computed by pandas and exact-match grading, run on Claude Sonnet 5 and Claude Opus 5 with thinking disabled (the in-context arm cannot complete at the default), a 4,000-token output cap, and no prompt caching, three runs per configuration, run August 19, 2026. The file arm uploads the CSV through the Files API and uses the `code_execution_20260120` tool.
83388716. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run on Claude Sonnet 5 on August 23, 2026, and on Claude Opus 5.5 on September 19 and 20, 2026, at its default effort (`medium`) and at `high`, on the Messages API with the same harness (for Claude Opus 5.5, a port of it that sends the same request bodies), the Claude Opus 5.5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute and 45-minute pauses on a 5-issue subset on both models). Claude Opus 5's keep-alive figures below come from the same job on August 23, 2026, with `max_tokens` raised to 4,096, on the same schedules except the 2-minute and 45-minute pauses. Three runs per cell, cost computed from each response's `usage` fields at list prices (for Claude Opus 5.5, $4 USD input, $5 USD 5-minute write, $8 USD 1-hour write, $0.20 USD cache read, and $20 USD output per million tokens; Claude Sonnet 5 ran on an Anthropic-internal organization whose usage is metered the same way as a customer organization's), accuracy against the same gold labels. The Claude Opus 5.5 figures on this page cover both effort levels. The crossover is about 3.3% of turns on Claude Sonnet 5 and 3.1% to 3.2% on Claude Opus 5.5: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 twenty-issue sessions and the 36 Claude Opus 5.5 twenty-issue sessions at each effort level (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). In the 5% cell the 5-minute and 1-hour settings tied on Claude Sonnet 5, because that draw's pauses fell on small prefixes; on Claude Opus 5.5 they nearly tied. The page's 1-in-20 rule sits above the measured crossover. Claude Opus 5.5's time to first token after a pause was not measured. Anthropic measured keep-alive requests that refresh the 5-minute cache on Claude Sonnet 5 and Claude Opus 5 on August 23, 2026, and on Claude Opus 5.5 in the runs above, always sent with `max_tokens: 1`. On Claude Sonnet 5 they cost 7.7% less than the 1-hour setting with 5% of turns paused and about the same with 10%; on Claude Opus 5 no difference was measurable at either share; on both they cost more with a pause of 6 minutes or more before every turn. On Claude Opus 5.5 they cost 8% to 18% less than the 1-hour setting with 5% and 10% of turns paused (about 10% to 15% once between-session noise is removed by re-billing each keep-alive session's own tokens at 1-hour cache prices), and more with a pause before every turn: 4% to 6% more at 6 minutes, 9% to 10% at 20 minutes, and 56% to 58% at 45 minutes. Keep-alive saved more on Claude Opus 5.5 because each keep-alive request re-reads the prefix at the cache-read price: 0.05x the input price, against 0.1x on Claude Sonnet 5 and Claude Opus 5; Claude Opus 5's sessions, re-billed at Claude Opus 5.5's prices, show nearly the same savings as Claude Opus 5.5. Anthropic's pre-launch API tests on Claude Opus 5.5 show that a `max_tokens: 0` request writes the cache and that the next request reads it; whether such a request refreshes an existing entry was not measured on Opus 5.5. On Claude Fable 5.1, at 0.025x, keep-alive was cheaper even with a pause before every turn, except at 45-minute pauses (reference 19).
No line in this hunk matches that.