from line 32
3232| Attempts end with `stop_reason: max_tokens` | Raise `max_tokens`; 64,000 covered all but 2 of 14,000 turns measured at the default effort, and 128,000 cost nothing extra per solved task | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
3333| You can check outputs (tests, a verifier) | Run everything at low effort and re-run failures at `high`; on the coding benchmark measured, the pass rate held at about half the cost | [Re-run failures](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#re-run-failures-at-higher-effort) |
3434| Agent loops with a few very costly runs | Set a task budget (beta; check the support table for which models), a Claude Managed Agents session budget, and a workspace spend limit | [Set budgets](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#set-budgets-and-output-caps) |
35| You want agent runs to finish sooner | Tell the model that time matters, and show it the elapsed time; on DRACO, HLE, and an internal physics set, runs took 33% to 69% less time at a 28% to 54% lower cost per task, with scores up to 1.9 points lower | [Show the model elapsed time](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#show-the-model-elapsed-time) |
35| You want agent runs to finish sooner | Tell the model that time matters, and show it the elapsed time; on DRACO research tasks with Claude Opus 5.5, a single agent took 47% less time at a 60% lower cost on the typical task, with a score 4.1 points lower; on HLE and an internal physics set, the typical task took at most 14% less time, and the physics-set score was 3.0 points lower | [Show the model elapsed time](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#show-the-model-elapsed-time) |
3636| A lower-cost model stalls only on hard decisions | Add a frontier advisor. It pays off when priced well above the executor and actually consulted, so first price the advisor's model alone at low effort and measure the consult rate | [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) |
3737| The work exceeds one context window | Delegate partitions to cheaper workers | [Orchestrator strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#orchestrator-strategy-delegate-bulk-work) |
3838
from line 52
5252
5353Across Anthropic's measured runs, cache reads are routinely the largest single component of task cost, making caching worth more than most model-choice decisions. Anthropic priced the DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) runs with and without caching:
5454
55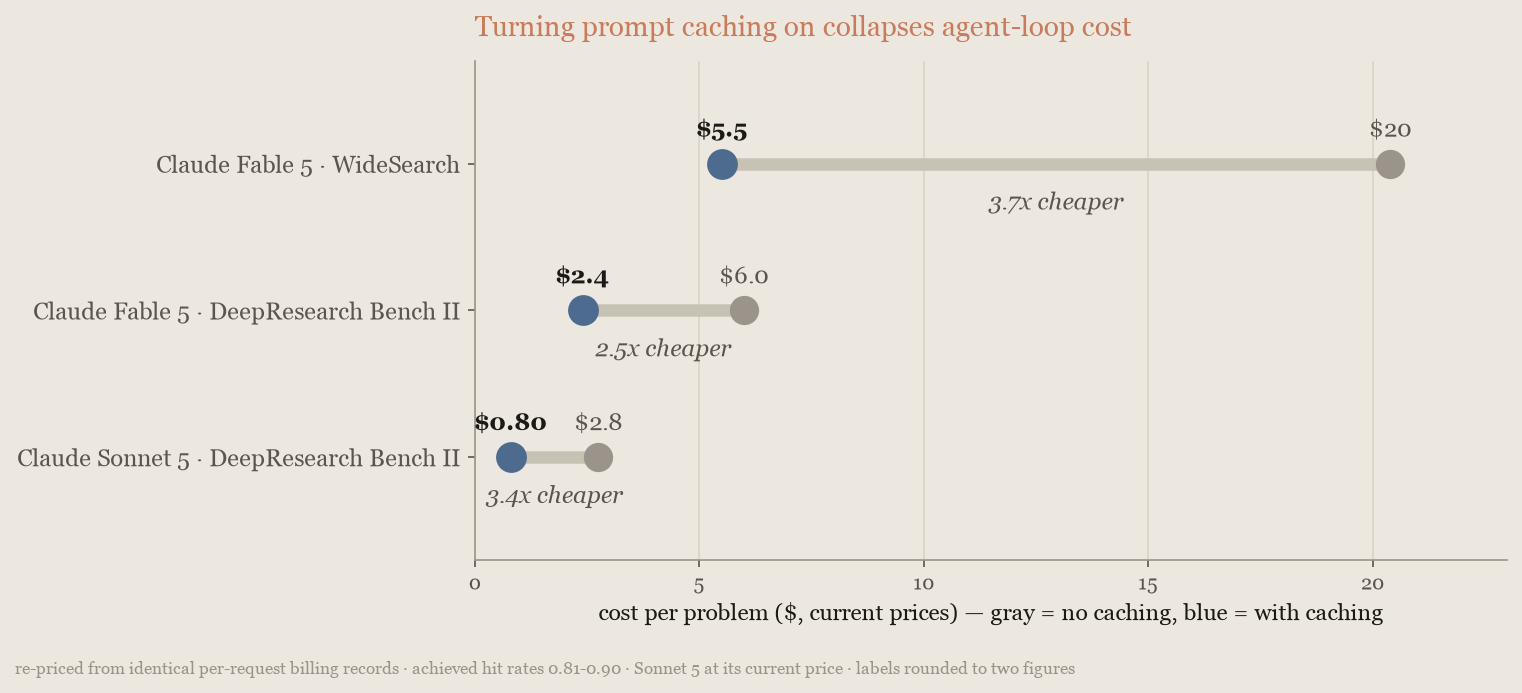
55
5656
5757The cache's default lifetime is 5 minutes and an agent loop's turns are seconds apart, so the discount applies to most tokens on every turn. The caching chart's runs read 79% to 90% of their input tokens from the cache. The saving varies with episode depth, because shorter loops re-read less, but caching stayed the largest single lever on every model and benchmark measured.
5858
from line 72
7272
7373Anthropic also measured extra requests that keep the 5-minute cache warm. On Claude Sonnet 5 they cost about 8% less than the 1-hour duration when 1 turn in 20 followed a pause, but about the same at 2 in 20; on Claude Opus 5, the previous Opus model, they saved nothing measurable. With a pause of 6 minutes or more before every turn they cost more on both models. Because the Claude Sonnet 5 saving was gone by 2 turns in 20, use the 1-hour duration instead on Claude Sonnet 5 and Claude Opus 5.
7474
75On Claude Fable 5.1 the cheapest setting is a different one. Its [cache read](https://platform.claude.com/docs/en/about-claude/pricing#prompt-caching) costs 0.025x the input price ($0.25 per million tokens) while its cache writes keep the standard multipliers, so a keep-alive request that re-reads the prefix is cheap and the 1-hour duration's write premium is the larger bill. Anthropic measured the triage job on Claude Fable 5.1 with the same three settings[19](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Keeping the 5-minute cache warm cost 13% to 20% less per session than the 1-hour cache whenever pauses ran for minutes; only with pauses near 45 minutes did the 1-hour cache win, by about 12 cents a session. On Claude Fable 5.1, keep the 5-minute cache warm while a person is away for minutes, and buy the 1-hour duration when pauses run toward an hour:
75On Claude Fable 5.1 the cheapest setting is a different one. Its [cache read](https://platform.claude.com/docs/en/about-claude/pricing#prompt-caching) costs 0.025x the input price ($0.25 USD per million tokens) while its cache writes keep the standard multipliers, so a keep-alive request that re-reads the prefix is cheap and the 1-hour duration's write premium is the larger bill. Anthropic measured the triage job on Claude Fable 5.1 with the same three settings[19](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). Keeping the 5-minute cache warm cost 13% to 20% less per session than the 1-hour cache whenever pauses ran for minutes; only with pauses near 45 minutes did the 1-hour cache win, by about $0.12 USD a session. On Claude Fable 5.1, keep the 5-minute cache warm while a person is away for minutes, and buy the 1-hour duration when pauses run toward an hour:
7676
7777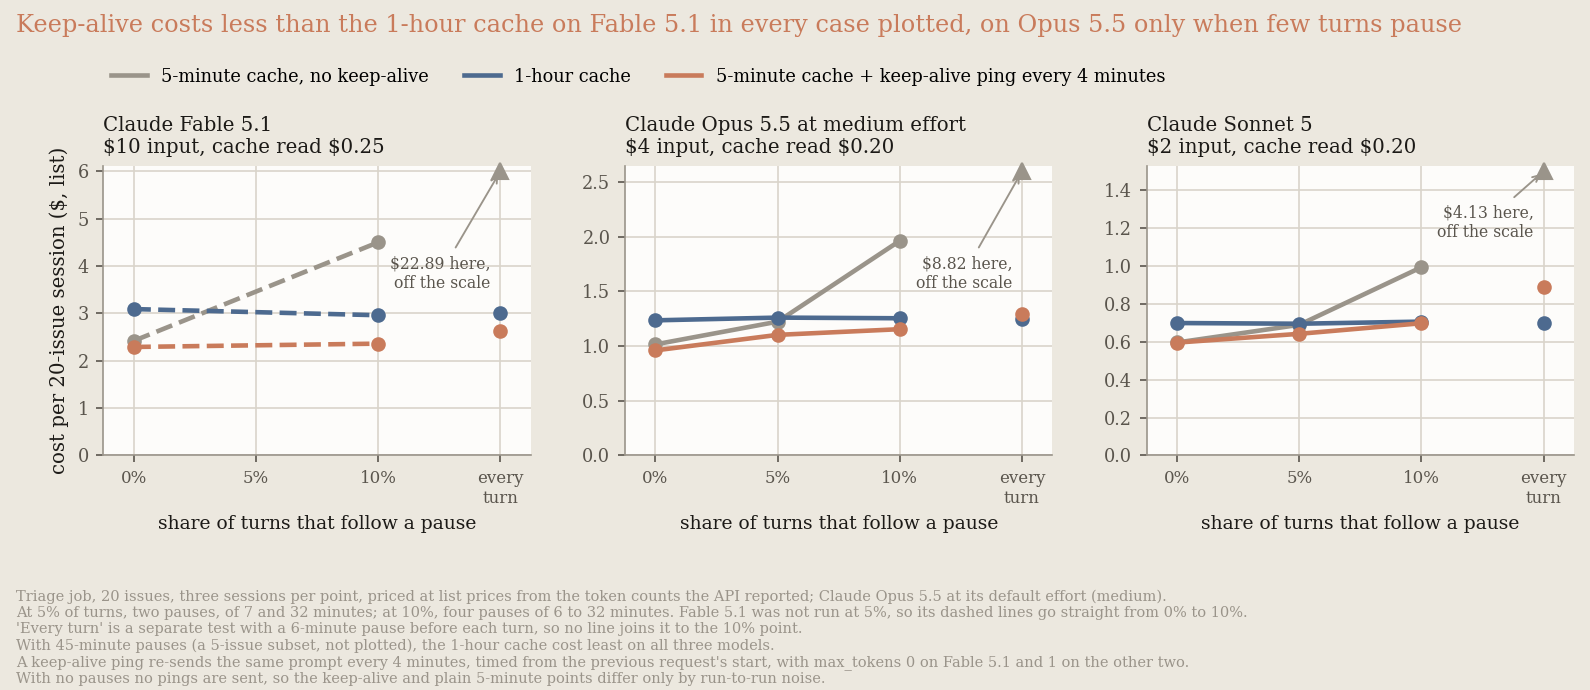
7878
from line 122
122122
123123#### What breaks the cache
124124
125Several things can break your cache during a task. Anything that changes per request, such as a timestamp or a queue position, placed ahead of the stable prefix turns every request into a full cache write: on the triage run in [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), a 25-token status line at the front of the system prompt cost $4.24 per run instead of $0.59, more than running with caching off. Keep per-request text in the newest user turn.
125Several things can break your cache during a task. Anything that changes per request, such as a timestamp or a queue position, placed ahead of the stable prefix turns every request into a full cache write: on the triage run in [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), a 25-token status line at the front of the system prompt cost $4.24 USD per run instead of $0.59 USD, more than running with caching off. Keep per-request text in the newest user turn.
126126
127The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On the most recent models, change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. Check that page for which models support it. On models that support it, a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) leaves the cached prefix intact too. The stakes are highest on Claude Fable 5.1 and Claude Mythos 5.1, where a break re-writes the prefix at 1.25x the input price instead of reading it at 0.025x. On a 100,000-token prefix, one broken turn there costs $1.25 instead of $0.03, 50 times the read; on Claude Opus 5.5 it costs $0.50 instead of $0.02, 25 times, and on the other current models 12.5 times.
127The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it. Changing [`effort`](https://platform.claude.com/docs/en/build-with-claude/effort) or the thinking configuration between requests invalidates the cache from that point onward, and on some models the tools and system prompt ahead of it as well; any edit to the system prompt invalidates the cache from that point onward; setting or changing an output format invalidates the cache for the whole conversation; adding, removing, or reordering a tool definition invalidates all of it. The [prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching#what-invalidates-the-cache) page lists these cases, apart from the output format, which [structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs#prompt-modification-and-token-costs) covers. On the most recent models, change instructions with a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages), a `{"role": "system"}` message appended to `messages`, instead of editing the top-level `system` field: the cached prefix stays intact. Check that page for which models support it. On models that support it, a [per-message effort change](https://platform.claude.com/docs/en/build-with-claude/effort#change-effort-mid-conversation-beta) leaves the cached prefix intact too. The stakes are highest on Claude Fable 5.1 and Claude Mythos 5.1, where a break re-writes the prefix at 1.25x the input price instead of reading it at 0.025x. On a 100,000-token prefix, one broken turn there costs $1.25 USD instead of $0.03 USD, 50 times the read; on Claude Opus 5.5 it costs $0.50 USD instead of $0.02 USD, 25 times, and on the other current models 12.5 times.
128128
129Anthropic measured this on the triage agent's long sessions[18](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). An effort change and an added tool made mid-session rewrote 39,000 and 60,000 cached tokens, and those sessions cost $0.95 per session. The same two changes on the first request after compaction cost $0.75, and on the request that triggered the compaction $0.92, because the compaction's summarization pass then re-processed the 81,000-token context at the cache-write price: that summarization pass cost $0.21, against $0.04 when the same changes came one request later, with accuracy within run-to-run noise in every arm:
129Anthropic measured this on the triage agent's long sessions[18](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). An effort change and an added tool made mid-session rewrote 39,000 and 60,000 cached tokens, and those sessions cost $0.95 USD per session. The same two changes on the first request after compaction cost $0.75 USD, and on the request that triggered the compaction $0.92 USD, because the compaction's summarization pass then re-processed the 81,000-token context at the cache-write price: that summarization pass cost $0.21 USD, against $0.04 USD when the same changes came one request later, with accuracy within run-to-run noise in every arm:
130130
131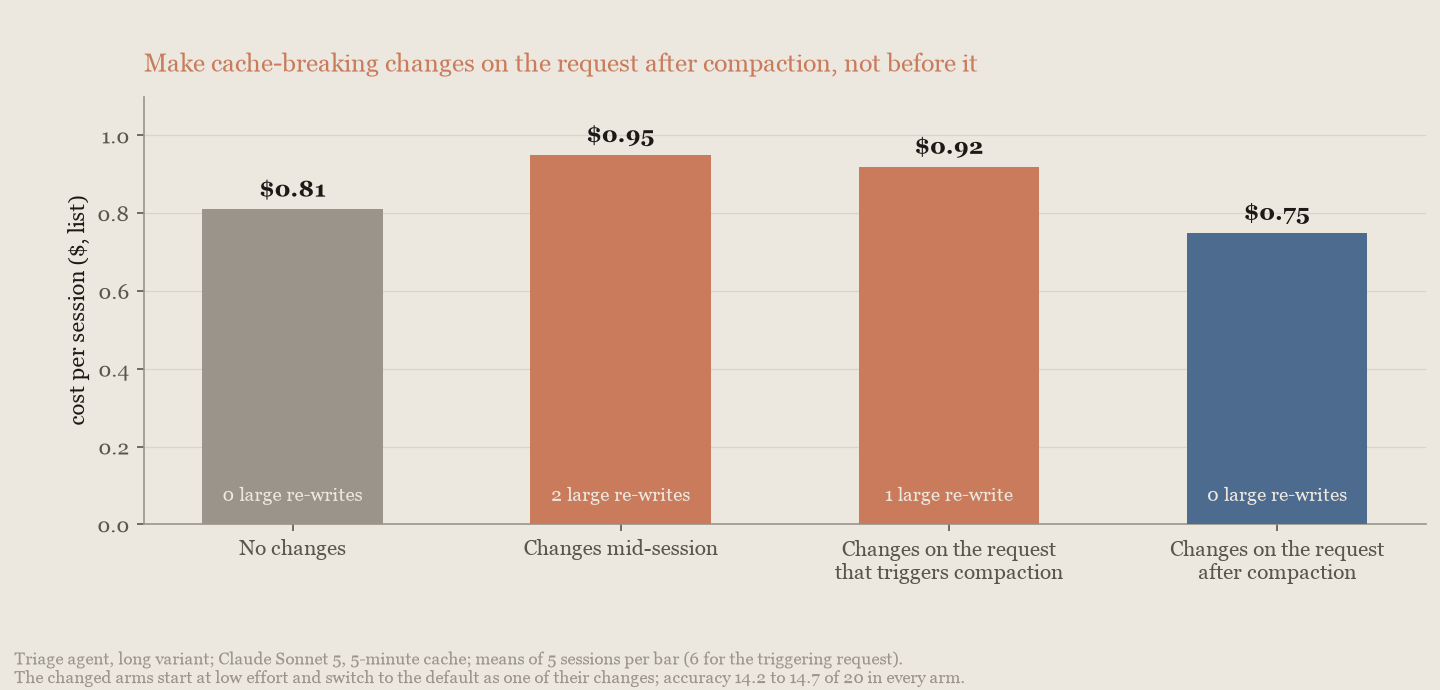
131
132132
133133Changing a [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) partway through invalidates any cached prefix that contains the budget value, so set it once, on the first request. Every [context editing](https://platform.claude.com/docs/en/build-with-claude/context-editing#context-editing-and-prompt-caching) pass invalidates the prefix from the point it clears and the next request pays to re-cache everything after it, so clear in a few large batches rather than many small ones. On Claude Fable 5.1 and Claude Mythos 5.1 each of these costs 50 times the read price per token, so they matter most there. Make every cache-invalidating change at natural breaks, then confirm cache reads have not dropped; if they have, [cache diagnostics](https://platform.claude.com/docs/en/build-with-claude/cache-diagnostics) shows where the prefix diverged.
134134
from line 145
145145
146146Every tool definition attached to a request is input on every turn, and a few MCP servers add up to hundreds of them. Anthropic ran the triage agent with its own two tools plus a catalog of real tool definitions from public MCP servers, for a total of up to 502 tools, loading all of them or marking the extras `defer_loading` behind [tool search](https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool):
147147
148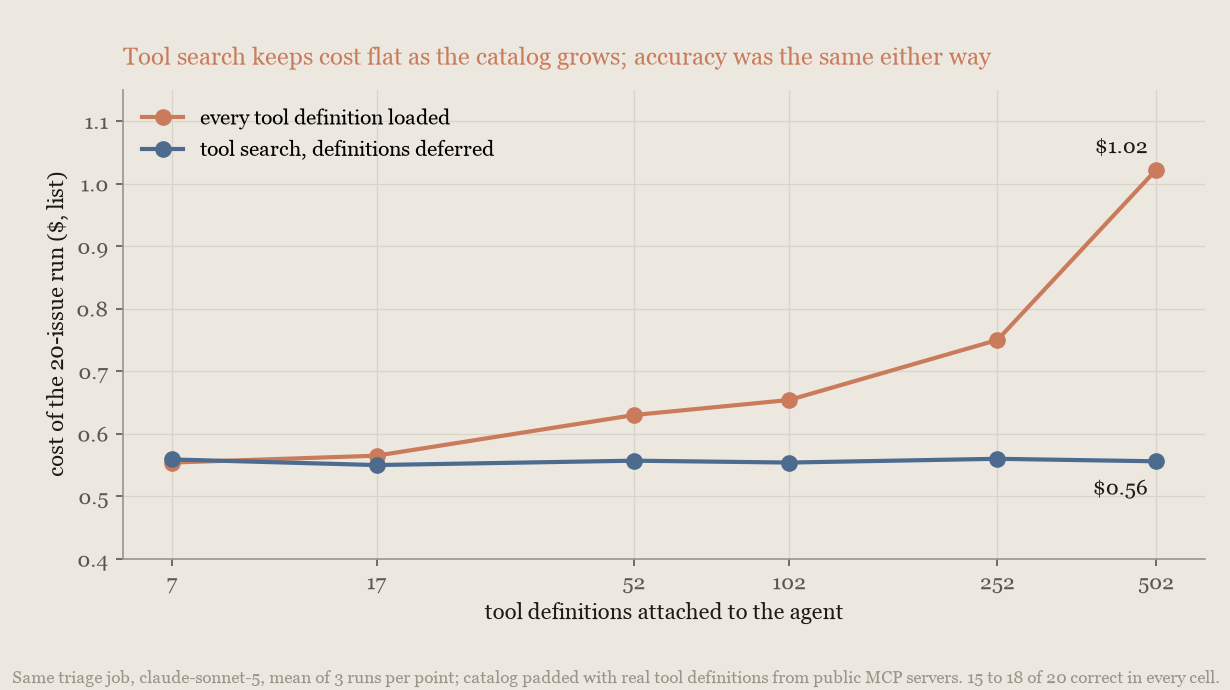
148
149149
150150With every definition loaded, the run cost nearly doubled as the catalog grew, tracking the schema tokens on each request. With tool search it stayed flat at every catalog size, 45% less at 502 tools. Accuracy was 15 to 18 of 20 in every cell either way, and the model never called a wrong tool, so at this scale the catalog costs money, not correctness. The same holds for tools that come through the [MCP connector](https://platform.claude.com/docs/en/agents-and-tools/mcp-connector): with a public GitHub MCP server attached, deferring its toolset (`default_config: {defer_loading: true}`) cut the run 20% at the same accuracy.
151151
from line 153
153153
154154When the model has to compute over a table, upload it with the [Files API](https://platform.claude.com/docs/en/build-with-claude/files) and let the model query it with [code execution](https://platform.claude.com/docs/en/agents-and-tools/tool-use/code-execution-tool) instead of pasting it in. Anthropic asked 25 aggregate questions[15](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (sums, filtered counts, group-bys, and a date filter) over a 1,862-row public CSV, with the answers computed by pandas:
155155
156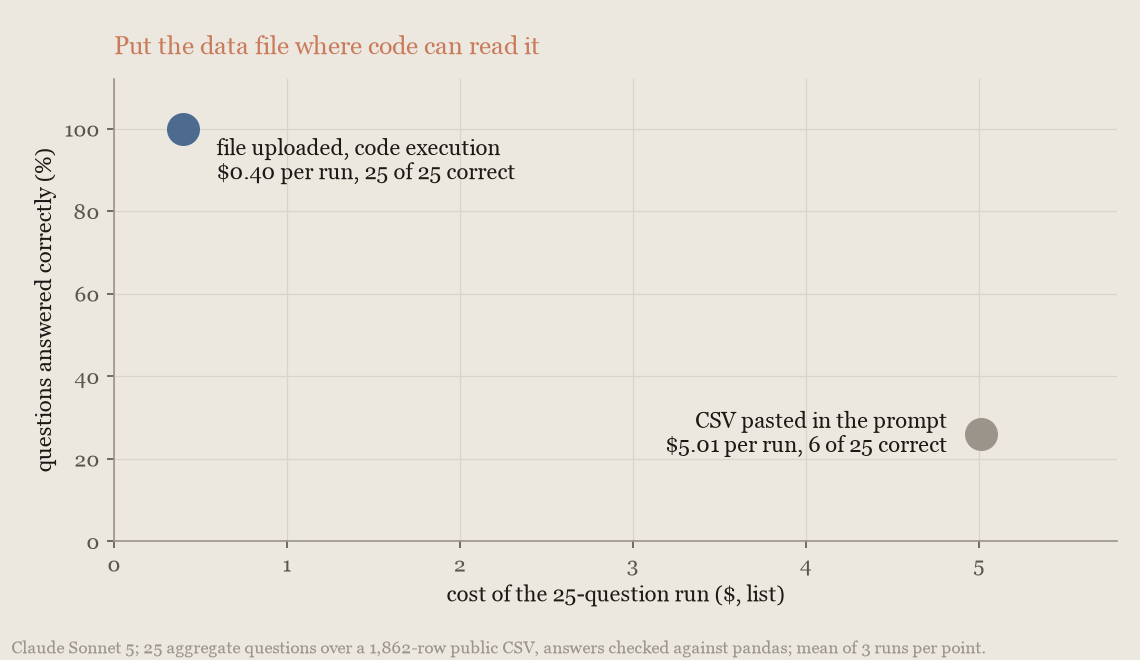
156
157157
158158Pasted into the prompt, the table is about 91,000 input tokens on every request, and Claude Sonnet 5 answered 6 of 25 questions correctly. Uploaded, with code execution, it answered all 25, and the run cost about a twelfth as much. Claude Opus 5 showed the same pattern.
159159
from line 254
254254
255255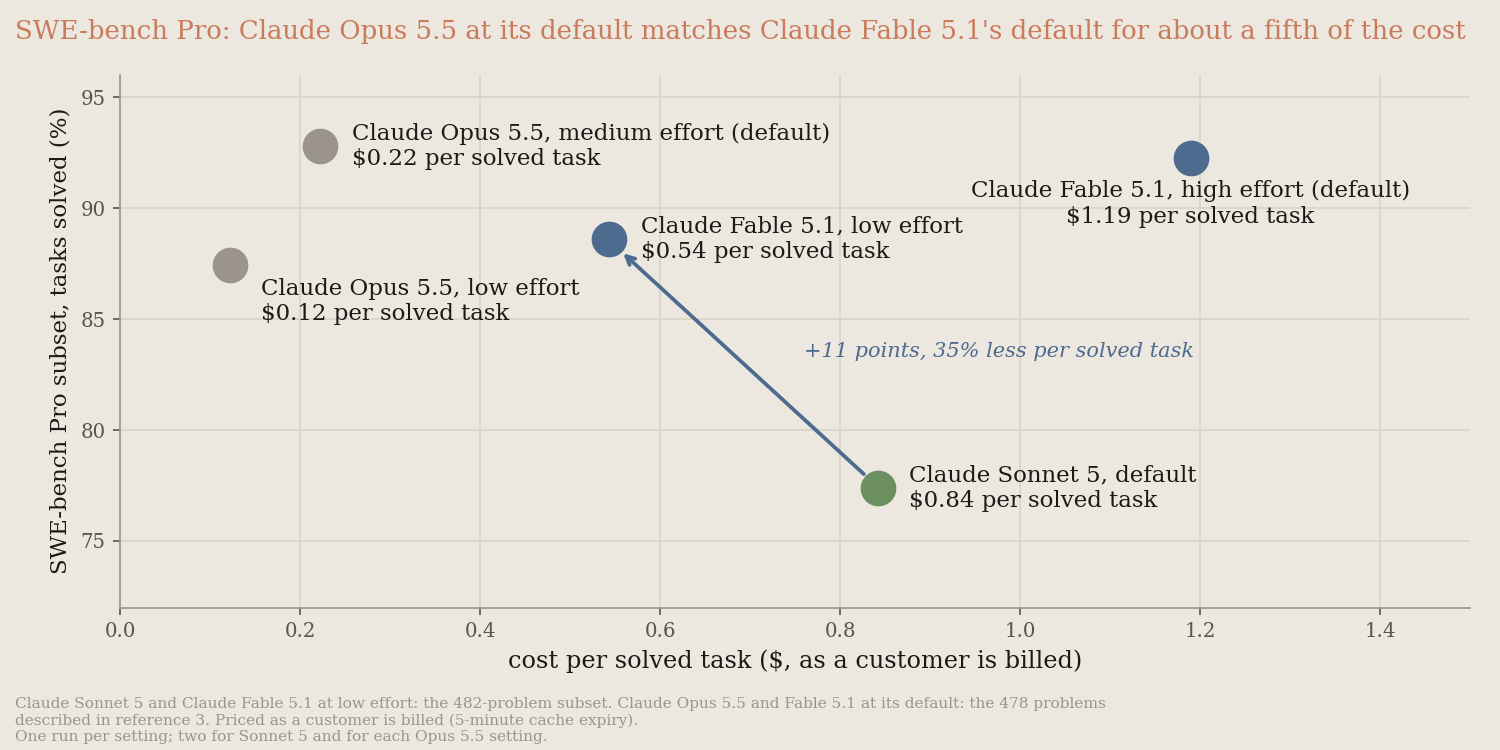
256256
257Claude Fable 5.1 at `low` effort solved 88.6% of tasks for $0.54 per solved task, against 77.4% for $0.84 from Claude Sonnet 5 at its default: 11 more points for 35% less per solved task, despite a per-token price five times higher. It does not always win, though. On the same subset, which Claude Opus 5.5 and Claude Fable 5.1 both largely saturate and whose scores are not comparable to the public leaderboard, Opus 5.5 at its default, `medium`, matched Fable 5.1 at its default (92.8% against 92.3%, inside run-to-run noise) for about a fifth of the cost per solved task ($0.22 against $1.19). At `low`, Opus 5.5 solved 87.4% for $0.12. These figures use the 478 problems described in reference 3. And on long research loops the frontier model does more work, not less: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Fable 5.1 at `low` scored 10 points above Sonnet 5 (66% against 56%) at about four times the cost per task ($4.66 against $1.20), because it runs a longer research loop over a larger context. Claude Opus 5 at its default scored 71% on the same basis for $6.71 per task, above Fable 5.1 at its default (65% for $7.12), so on research too Fable 5.1 earns its price only at `low`.
257Claude Fable 5.1 at `low` effort solved 88.6% of tasks for $0.54 USD per solved task, against 77.4% for $0.84 USD from Claude Sonnet 5 at its default: 11 more points for 35% less per solved task, despite a per-token price five times higher. It does not always win, though. On the same subset, which Claude Opus 5.5 and Claude Fable 5.1 both largely saturate and whose scores are not comparable to the public leaderboard, Opus 5.5 at its default, `medium`, matched Fable 5.1 at its default (92.8% against 92.3%, inside run-to-run noise) for about a fifth of the cost per solved task ($0.22 USD against $1.19 USD). At `low`, Opus 5.5 solved 87.4% for $0.12 USD. These figures use the 478 problems described in reference 3. And on long research loops the frontier model does more work, not less: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Fable 5.1 at `low` scored 10 points above Sonnet 5 (66% against 56%) at about four times the cost per task ($4.66 USD against $1.20 USD), because it runs a longer research loop over a larger context. Claude Opus 5 at its default scored 71% on the same basis for $6.71 USD per task, above Fable 5.1 at its default (65% for $7.12 USD), so on research too Fable 5.1 earns its price only at `low`.
258258
259For most agent workloads, start with Claude Opus 5.5 at its default effort (`medium`), and use Claude Fable 5.1 for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5.5 at higher effort still fall short. On the SWE-bench Pro subset, Opus 5.5 at its default matched Fable 5.1 at its default for about a fifth of the cost per solved task, as noted earlier. On the coding benchmark in [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions), it scored 86.6% against 84.2% for Fable 5.1 at `medium` (a single Fable 5.1 run), for under a third of the cost per attempt ($0.84 against $2.68). On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a chart-reading benchmark, Opus 5.5 at `low` scored 68.7 for about $0.03 a chart, against 62.5 for $0.15 from Fable 5.1 at `low` and 49 for $0.16 from Claude Opus 5 at `low`. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a fifth of Claude Opus 5.5's cost per question, with 63% accuracy compared with 92% for Opus 5.5, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
259For most agent workloads, start with Claude Opus 5.5 at its default effort (`medium`), and use Claude Fable 5.1 for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5.5 at higher effort still fall short. On the SWE-bench Pro subset, Opus 5.5 at its default matched Fable 5.1 at its default for about a fifth of the cost per solved task, as noted earlier. On the coding benchmark in [Advisor strategy](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions), it scored 86.6% against 84.2% for Fable 5.1 at `medium` (a single Fable 5.1 run), for under a third of the cost per attempt ($0.84 USD against $2.68 USD). On Chartography[13](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a chart-reading benchmark, Opus 5.5 at `low` scored 68.7 for about $0.03 USD a chart, against 62.5 for $0.15 USD from Fable 5.1 at `low` and 49 for $0.16 USD from Claude Opus 5 at `low`. At the other end, Claude Haiku 4.5 answered GPQA Diamond[9](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) questions at about a fifth of Claude Opus 5.5's cost per question, with 63% accuracy compared with 92% for Opus 5.5, and fell much further behind on long coding tasks. It fits high-volume work with checkable outputs, not long agentic loops.
260260
261261The ranking flips by workload, and no price list tells you which way. Price every candidate in cost per completed task on your own traffic, including Claude Opus 5.5 at its default effort and the frontier model at reduced effort.
262262
from line 270
270270
271271If you are a model or two behind, the cheapest lever is the model string. Anthropic ran recent Claude Opus, Claude Sonnet, and Claude Fable models through the same harness on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, each at its shipped defaults and priced at list rates, and ran the Opus line again on Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs):
272272
273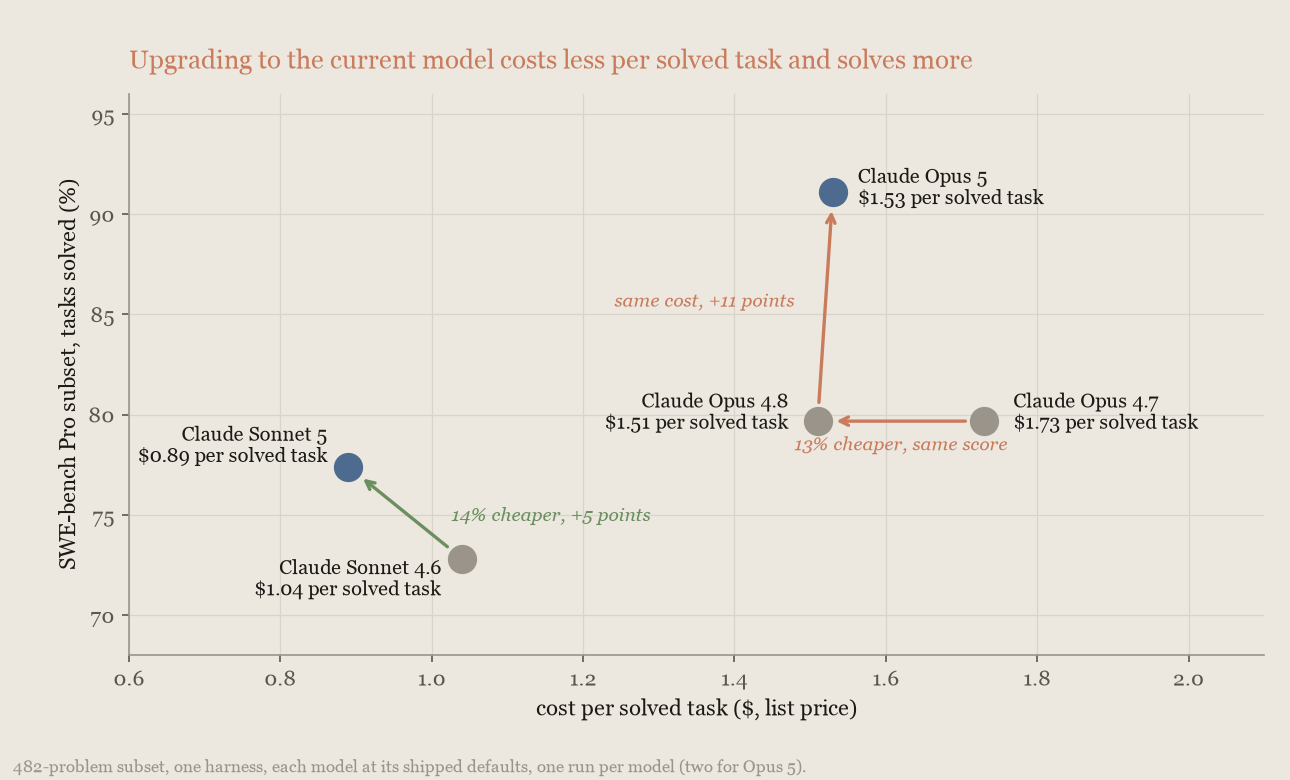
273
274274
275275Anthropic prices Claude Opus 4.7, Opus 4.8, and Opus 5 identically per token, so any difference among them comes from how much work each model does per task: priced as a customer is billed, Claude Opus 4.8 solves the same share of tasks as Claude Opus 4.7 for 14% less per solved task, and Claude Opus 5 then solves 12 more points of tasks at 21% more per solved task. Claude Opus 5 at `low` effort beats Opus 4.8's default on this benchmark for about 30% of its cost per solved task, so the cheapest upgrade is the new model at a lower setting. Sonnet 5's saving comes from its lower per-token price, which more than offsets the extra tokens it uses per task compared with Sonnet 4.6: 15% less per solved task for 5 more points. The frontier tier gained the same way: Claude Fable 5.1 matches Claude Fable 5's score for 43% less per solved task, most of it the lower cache-read price. That direction is not guaranteed: on DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) the same upgrade costs 41% more per task at `high` (79% more at `low`) for its 2 to 3 extra points on the tasks clean in every arm (reference 7), because the new model does more work per task there. The input and output prices are the same and the cache read is 4x cheaper, so measure the upgrade on your own workload before assuming it saves.
276276
277On harder work the gap widens. On Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), where the tasks are hard enough that pass rate rather than tokens sets the bill, Claude Opus 4.7, Opus 4.8, and Opus 5 each spend $8 to $15 per task but solve 7%, 15%, and 41% of tasks, so cost per solved task falls from $183 to $63 to $28 up the ladder. The 21% premium Claude Opus 5 carries over Opus 4.8 on the saturated coding subset becomes a 56% saving on Terminal-Bench 3, where the older model mostly fails: the more your workload defeats the old model, the more the upgrade saves per result.
277On harder work the gap widens. On Terminal-Bench 3[20](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), where the tasks are hard enough that pass rate rather than tokens sets the bill, Claude Opus 4.7, Opus 4.8, and Opus 5 each spend $8 USD to $15 USD per task but solve 7%, 15%, and 41% of tasks, so cost per solved task falls from $183 USD to $63 USD to $28 USD up the ladder. The 21% premium Claude Opus 5 carries over Opus 4.8 on the saturated coding subset becomes a 56% saving on Terminal-Bench 3, where the older model mostly fails: the more your workload defeats the old model, the more the upgrade saves per result.
278278
279279Compare on cost per solved task, not per token: the same text costs about 30% more tokens on Claude Opus 4.7 and later, so a per-token comparison makes the newer models look more expensive by construction.
280280
from line 292
292292
293293Two consequences follow. First, draw this curve for your own workload before you add a second model: in these internal measurements, a multi-model configuration that looked cheaper than the default single model cost more than that same model at lower effort. Second, this curve is the single-model baseline any multi-model strategy must beat, so [step 2 of measuring on your own workload](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#measure-on-your-own-workload) baselines across effort levels.
294294
295Hard work does not automatically need high effort. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Fable 5.1 scored nearly the same at `low`, `medium`, and `high` while the cost per task rose from $4.66 to $7.12, so raising the effort in this case does not increase the quality of the output noticeably; on the 21 tasks clean in every arm (reference 7), Claude Fable 5 was flat across effort too, though the chart's 33-task basis, which drops each model's own cut-short attempts, shows it climbing. Measure the curve on the model you ship, not the one you measured last:
295Hard work does not automatically need high effort. On DeepResearch Bench II[7](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), Claude Fable 5.1 scored nearly the same at `low`, `medium`, and `high` while the cost per task rose from $4.66 USD to $7.12 USD, so raising the effort in this case does not increase the quality of the output noticeably; on the 21 tasks clean in every arm (reference 7), Claude Fable 5 was flat across effort too, though the chart's 33-task basis, which drops each model's own cut-short attempts, shows it climbing. Measure the curve on the model you ship, not the one you measured last:
296296
297297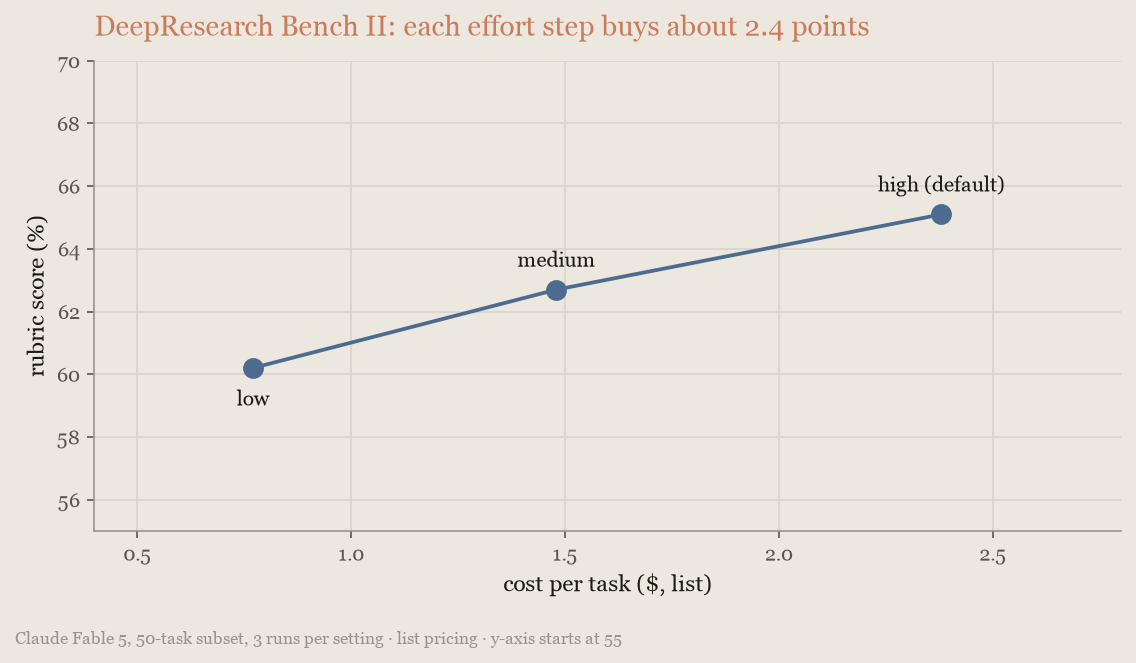
298298
from line 302
302302
303303When a task's outcome is checkable, the cheapest policy on the effort curve is not a fixed setting: run every task at a low setting and re-run only the failures at a higher one.
304304
305Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5.5 at `low`, 13% of tasks failed; with those re-run at `high`, about 97% passed for about $0.17 each, against 95.3% for $0.29 running everything at `high`: a slightly higher pass rate for a little over half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 97% for about $0.24. Most of the small lift is the second attempt (re-running the failures of one `high` run at `high` scores about the same, for more money), so use this policy for the saving, not the lift:
305Anthropic computed this policy task by task from the effort runs on the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset in [Tune effort](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#tune-effort). With Claude Opus 5.5 at `low`, 13% of tasks failed; with those re-run at `high`, about 97% passed for about $0.17 USD each, against 95.3% for $0.29 USD running everything at `high`: a slightly higher pass rate for a little over half the cost, counting the failed cheap attempts. Starting at `medium` instead solved about 97% for about $0.24 USD. Most of the small lift is the second attempt (re-running the failures of one `high` run at `high` scores about the same, for more money), so use this policy for the saving, not the lift:
306306
307307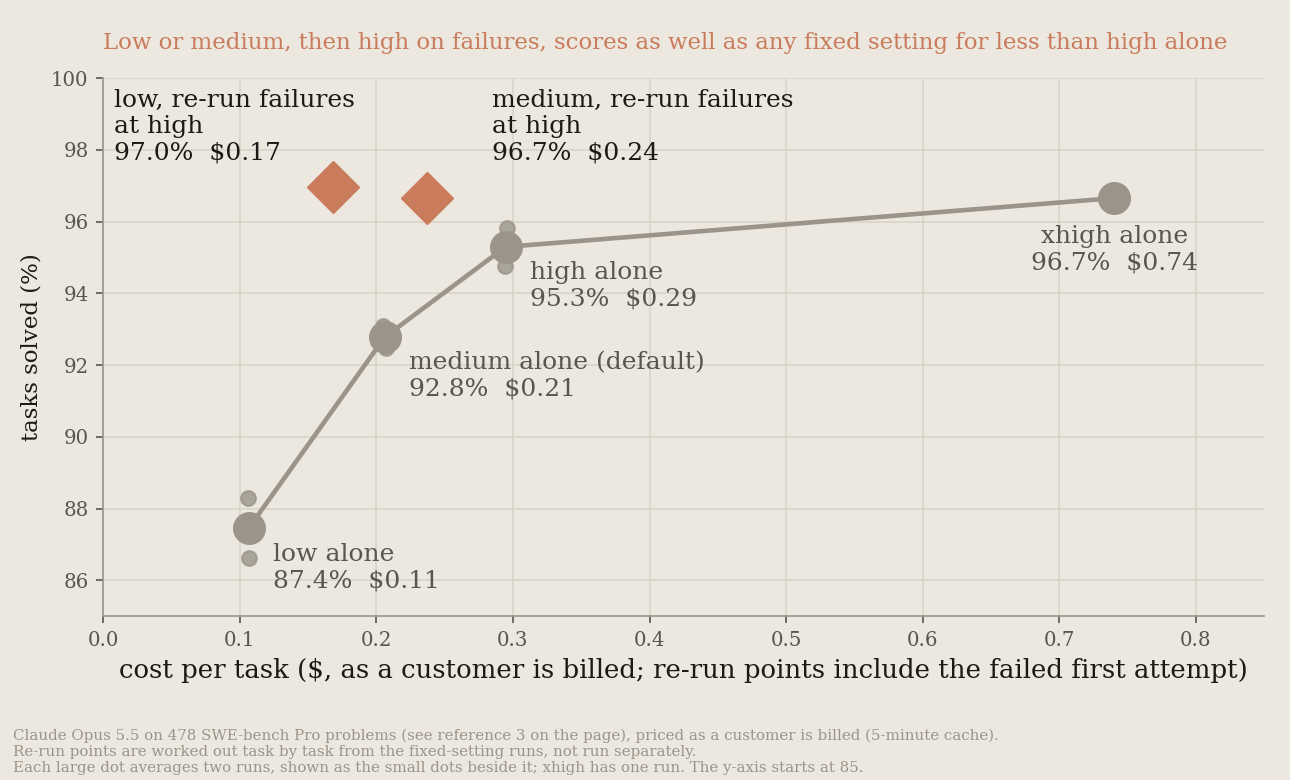
308308
from line 321
321321Three controls do three different jobs. A task budget saves money, because the model sees it. `max_tokens` is a safety cap: lowering it cut cost per attempt without lowering cost per solved task. On Claude Managed Agents, a session budget is the hard dollar stop behind both. Set all three: a task budget, a high `max_tokens`, and a session cap for the run you never want on a bill, with a [workspace spend limit](https://platform.claude.com/docs/en/api/rate-limits#setting-lower-limits-for-workspaces) as the final backstop.
322322
323323* **Task budgets** are in beta (beta header `task-budgets-2026-03-13`) on the most recent models; check the [support table](https://platform.claude.com/docs/en/build-with-claude/task-budgets#feature-support) for which. Start near your loop's 90th-percentile token usage, then tighten ([Choosing a budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets#choosing-a-budget) shows how to collect that distribution). Budgets below the current 20,000-token floor are rejected, and very tight budgets can produce refusal-like behavior. Set the budget once, on the first request, because a mid-task change [invalidates the cache](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#cache-repeated-context). The budget is advisory, steering the model rather than stopping it, so verify adherence on your workload.
324* **`max_tokens`** caps a single response, invisibly to the model, so lowering it does not make the model economize. The turns that needed the room are discarded and still billed. On an internal repository-task benchmark[12](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a 16,384-token cap ended about a quarter of Claude Opus 5.5's attempts and 43% of Claude Fable 5.1's, each at its default effort. Only 1 of the 66 capped Opus 5.5 attempts and 9 of the 117 capped Fable attempts still passed. Capped runs spent less per attempt but bought proportionally fewer solves, so cost per solved task was about the same as at 64,000 (on Fable 5.1, $21 against $22; on Opus 5.5, within 1%). At 64,000, 2 of about 14,000 Claude Fable 5.1 turns at its default effort were still cut off (no Claude Opus 5.5 turn was), and Fable 5.1 solved 58.5% of tasks instead of 36.3% (on a separate cut of the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, described in reference 12, no difference: 94 of 100 at either cap). Retrying capped attempts rarely helps: at the same cap most of them fail again, and at a higher one you also pay for the wasted attempt. Set `max_tokens` to 64,000 for agentic work, or to 128,000, the maximum, when a single cut-off attempt is costly; at 128,000 Fable 5.1 solved 60.0% for the same cost per solved task. [Stream responses](https://platform.claude.com/docs/en/build-with-claude/streaming) that large, treat [`stop_reason: max_tokens`](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#max-tokens) as a failure, and save money with effort and task budgets, which the model can see.
324* **`max_tokens`** caps a single response, invisibly to the model, so lowering it does not make the model economize. The turns that needed the room are discarded and still billed. On an internal repository-task benchmark[12](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a 16,384-token cap ended about a quarter of Claude Opus 5.5's attempts and 43% of Claude Fable 5.1's, each at its default effort. Only 1 of the 66 capped Opus 5.5 attempts and 9 of the 117 capped Fable attempts still passed. Capped runs spent less per attempt but bought proportionally fewer solves, so cost per solved task was about the same as at 64,000 (on Fable 5.1, $21 USD against $22 USD; on Opus 5.5, within 1%). At 64,000, 2 of about 14,000 Claude Fable 5.1 turns at its default effort were still cut off (no Claude Opus 5.5 turn was), and Fable 5.1 solved 58.5% of tasks instead of 36.3% (on a separate cut of the SWE-bench Pro[3](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) subset, described in reference 12, no difference: 94 of 100 at either cap). Retrying capped attempts rarely helps: at the same cap most of them fail again, and at a higher one you also pay for the wasted attempt. Set `max_tokens` to 64,000 for agentic work, or to 128,000, the maximum, when a single cut-off attempt is costly; at 128,000 Fable 5.1 solved 60.0% for the same cost per solved task. [Stream responses](https://platform.claude.com/docs/en/build-with-claude/streaming) that large, treat [`stop_reason: max_tokens`](https://platform.claude.com/docs/en/build-with-claude/handling-stop-reasons#max-tokens) as a failure, and save money with effort and task budgets, which the model can see.
325325* **Session budgets on Claude Managed Agents** are the hard stop. A [session budget](https://platform.claude.com/docs/en/managed-agents/budgets) is a dollar cap on one session at list rates for tokens, searches, and session time. At the cap, the session pauses with `stop_reason: budget_reached`; raising the budget resumes it. It is platform-enforced, works on any model with a list price, including models where task budgets are not yet available, and combines with the advisory task budget. Deployments apply the same field to every run.
326326
327327Ask for shorter answers. Output tokens cost five times input tokens on Claude Sonnet 5, and in an agent loop every token the model writes comes back as input on every later turn, so you pay for a long answer again and again. Anthropic ran the triage job under three final-answer instructions, three runs each, with the same model and tools. The original asked for two lines:
from line 351
351351triage-now | bug-confirmed | Clear repro steps show prompt queues indefinitely after cancelled question.
352352```
353353
354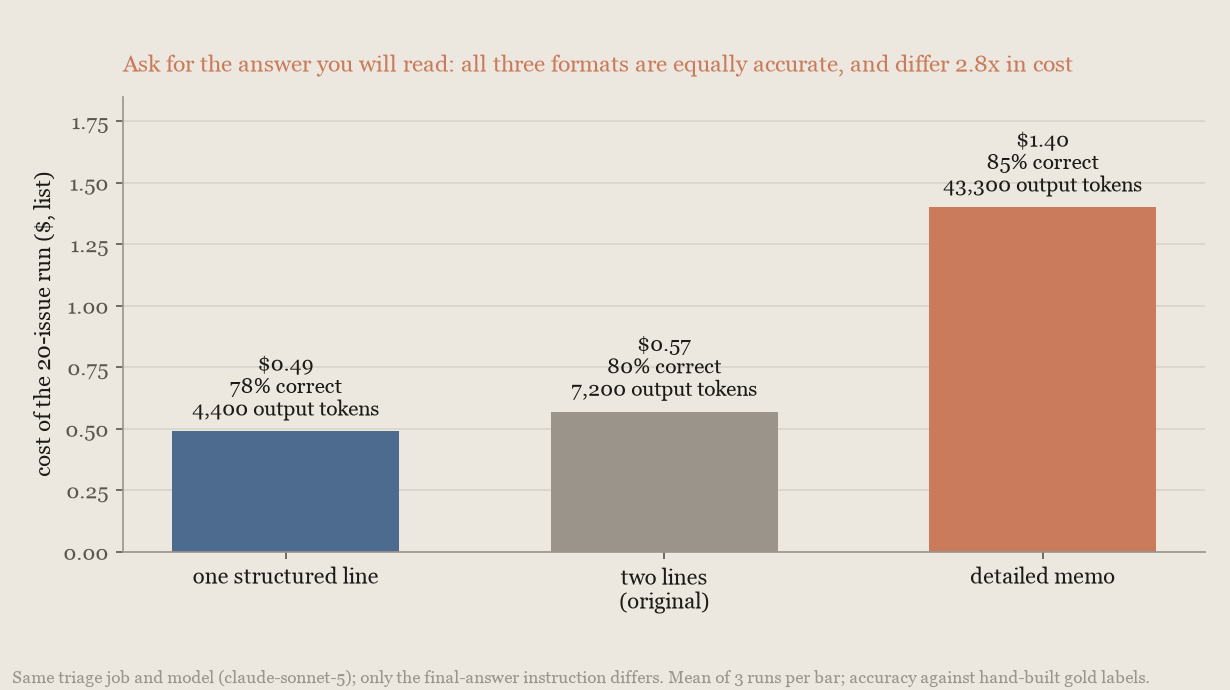
354
355355
356356The one-line answer used 39% fewer output tokens than the two-line original and cost 14% less per run. The memo used six times the output tokens and cost 2.8 times the one-line answer. All three scored within run-to-run noise of each other against the gold labels, so the formats differ in what you pay far more than in what they get right. Ask for the answer you will read, not the one that looks thorough.
357357
from line 365
365365
366366### Show the model elapsed time
367367
368A model in an agent loop can't see a clock. A [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) shows it how many tokens are left, but by default nothing in the request shows it how long the work has taken. Two small changes give it that signal. Add a two-sentence instruction to the system prompt that says time matters, and from the second request on, send the elapsed time before each of the model's turns.
368A model in an agent loop can't see a clock. A [task budget](https://platform.claude.com/docs/en/build-with-claude/task-budgets) shows it how many tokens are left, but by default nothing in the request shows it how long the work has taken. Two small changes give it that signal. The Claude Cookbook recipe [Multi-agent teams under latency pressure and budgets](https://github.com/anthropics/claude-cookbooks/blob/main/patterns/agents/latency_multi_agent.ipynb) uses the same two changes. End the task message with a sentence that says time matters, and before each request, add the elapsed time to the end of the newest `user` message.
369369
370Anthropic measured both changes together with Claude Fable 5.1 at `high` effort, on two public benchmarks, DRACO[21](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) and HLE[22](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and on an internal set of 70 research-level physics problems, adapted from the public CritPt benchmark[23](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). This page calls that set the physics set. Each of the three ran in two shapes: a single agent, and a team in which a lead agent starts helper agents of the same model that work in parallel. A score change counts as inside the margin when its 95% interval stays within a limit that Anthropic set before the runs: 1.5 points on DRACO and 2.5 points on HLE. The following chart plots score against cost per task for each configuration. A second row of bars gives each configuration's time as a ratio to the single agent at `high` effort, without retry waits. A third row gives the score change that both changes make, with its 95% interval:
370Anthropic measured both changes together with Claude Opus 5.5 at its default effort, `medium`, on two public benchmarks, DRACO[21](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) and HLE[22](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), and on an internal set of 70 research-level physics problems, adapted from the public CritPt benchmark[23](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs). This page calls that set the physics set. Each of the three ran with a single agent, with a team in which a lead agent can start any number of helper agents of the same model, and, for comparison, with a single agent at `low` effort and no changes. Unless a sentence says average, time and cost figures are for the typical task: the median, over tasks, of each task's ratio between the two configurations compared. The following chart plots average score against average cost per task for each configuration. A second row gives the typical task's time as a ratio, with both changes compared with the same setup without them, and at `low` effort compared with `medium`. A third row gives the average score change for the same comparisons, with its 95% interval:
371371
372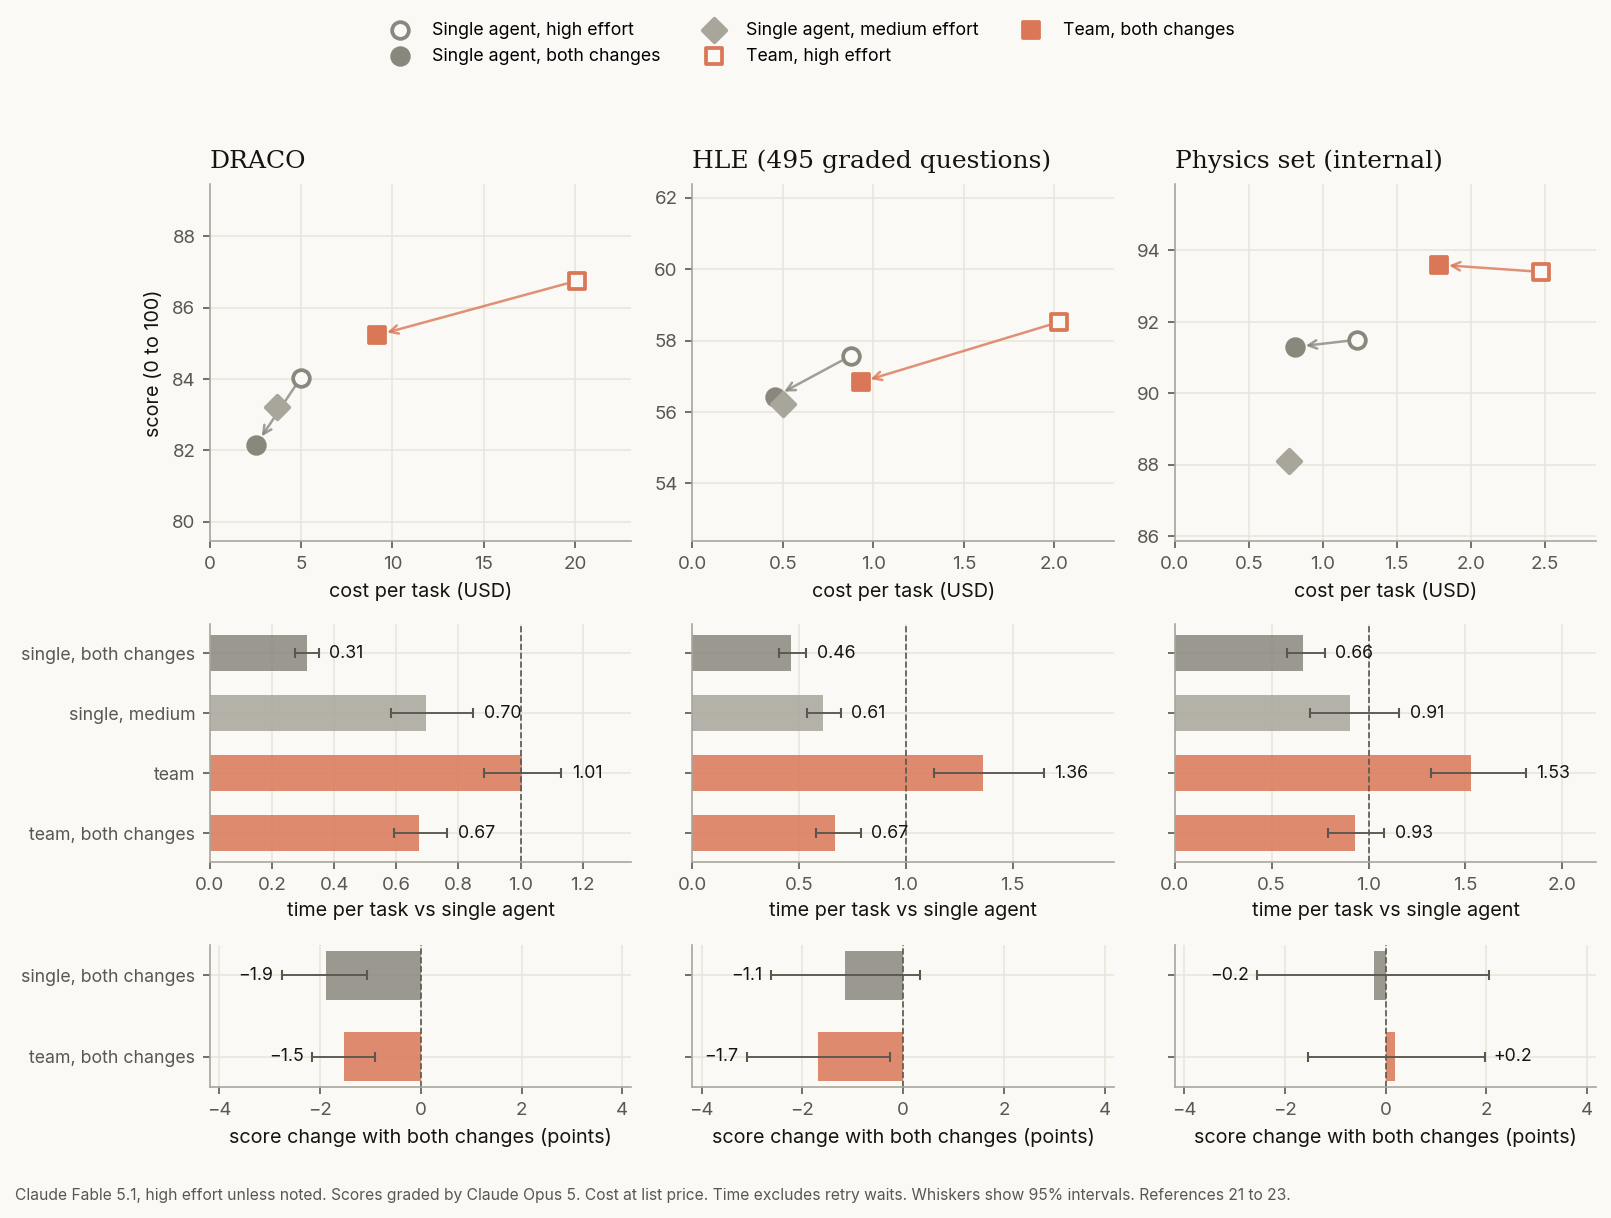
372
373373
374**With a team of agents.** A team does more work than a single agent, so by default it costs more. On DRACO, the team cost 4.0 times as much as the single agent and took about as long (95% interval 12% less to 13% more). With the instruction and the clock on every agent, the team finished in 33% less time at a 54% lower cost per task. Its score was 1.5 points lower (95% interval 0.9 to 2.1 lower), and the far end of that interval, 2.1 points lower, is past the 1.5-point margin. On HLE, the team finished in 51% less time at a 54% lower cost per task. Its score was 1.7 points lower (95% interval 0.3 to 3.1 lower), and the far end of that interval, 3.1 points lower, is past the 2.5-point margin. On the physics set[23](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), the team finished in 39% less time. Its cost per task was 28% lower, and that saving depends on how often the prompt cache expired between requests. With no expiry, it would be 23%. Its score was 0.2 points higher (95% interval 1.5 lower to 2.0 higher).
374**On long research tasks.** On DRACO[21](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), the two changes cut a single agent's time by 47% and its cost by 60% on the typical task. Its average cost fell from $1.13 USD to $0.44 USD per task, and it made about half as many requests per attempt. Its score was 4.1 points lower (95% interval 2.9 to 5.2 lower).
375375
376On DRACO, the lead started a median of 4 helpers per attempt, so the DRACO result shows a team working in parallel. On HLE and the physics set, the lead started a median of 0 helpers, so at least half of those team runs had only the lead agent. Those team results mostly show the lead agent's own behavior, not the effect of parallel helpers.
376**On HLE and the physics set.** On HLE[22](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), the same changes cut a single agent's time by 14% and its cost by 9% on the typical question. With the Claude Opus 5 judge, its score showed no clear change (0.9 points lower, 95% interval 2.5 lower to 0.7 higher). With a second grader, its score was 1.9 points lower (95% interval 0.2 to 3.7 lower). On the physics set[23](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), the changes cut its time by 7% and its cost by 4% on the typical problem, and its score was 3.0 points lower (95% interval 0.4 to 5.6 lower). Average time fell further than the typical task's. On HLE, average time fell 43% and average cost 37%, because the changes cut a few very long questions short. On the physics set, average time fell 14%, all of it on one problem.
377377
378**With a single agent.** On the physics set[23](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), the same changes cut a single agent's time by 34% and its cost per task by 34%. Its score was 0.2 points lower (95% interval 2.5 lower to 2.1 higher). On the physics set, a lower effort level saved cost but not clearly time. At `medium` effort, the single agent cost 37% less per task than at `high`, and its time was 9% less (95% interval 30% less to 16% more). It scored 3.4 points lower (95% interval 0.4 to 6.8 lower), and the interval reaches close to zero. With both changes at `high` effort, the single agent took 27% less time than at `medium` effort (95% interval 5% less to 44% less). Its cost per task was 6% more (95% interval 12% less to 27% more), and its score was 3.2 points higher (95% interval 0.1 lower to 6.5 higher).
378**With a team.** In these runs, the lead rarely started helpers. Without the changes, it started a helper in only 5 of 300 attempts on DRACO, 13 of 1,479 on HLE, and none of 280 on the physics set. So the team results mostly show the lead agent working alone, with the team's own instructions and tools. Anthropic has no measurement of the changes on a team that works in parallel. Without the changes, the team already took about half the single agent's time on the typical DRACO task, and scored 3.3 points lower (95% interval 2.1 to 4.6 lower). With the changes, the team took 17% less time at a 20% lower cost on the typical DRACO task, and scored 1.6 points lower (95% interval 0.3 to 2.8 lower). On HLE and the physics set, the team's time on the typical task changed by 3% or less, and its score didn't change clearly.
379379
380On HLE, the same changes cut a single agent's time by 54% and its cost per task by 48%. Its score was 1.1 points lower (95% interval 2.6 lower to 0.3 higher), and the far end of that interval, 2.6 points lower, is just past the 2.5-point margin. At `medium` effort, the single agent cost 43% less per task than at `high`, took 39% less time, and scored 1.3 points lower (95% interval 2.8 lower to 0.1 higher). With both changes at `high` effort, the single agent took 25% less time than at `medium` effort (95% interval 12% less to 35% less). Its cost per task was 9% less (95% interval 21% less to 6% more), and its score was 0.2 points higher (95% interval 1.3 lower to 1.7 higher).
380**Compared with a lower effort level.** Lowering a single agent's effort saved more time and cost than the changes did, and lost more score. At `low` effort, the single agent scored 13.3 points lower on DRACO, 3.4 on HLE, and 14.0 on the physics set than at `medium`, and the typical task took 84%, 30%, and 47% less time. With the changes at `medium` effort, it scored 9.2, 2.5, and 11.0 points higher than at `low`, and the typical task took longer than at `low` by a factor of 1.2 to 3.2.
381381
382On DRACO, the same changes cut a single agent's time by 69% and its cost per task by 49%. Its score was 1.9 points lower (95% interval 1.1 to 2.8 lower), and the far end of that interval, 2.8 points lower, is past the 1.5-point margin. At `medium` effort, the single agent cost 25% less per task than at `high`, took 30% less time, and scored 0.7 points lower (95% interval 0.1 to 1.3 lower). With both changes at `high` effort, the single agent took 53% less time than at `medium` effort (95% interval 42% less to 63% less), and its cost per task was 31% less (95% interval 28% less to 35% less). Its score was 1.2 points lower (95% interval 0.5 to 1.9 lower), and the far end of that interval, 1.9 points lower, is past the 1.5-point margin.
383
384On all three sets, both changes at `high` effort saved more time than `medium` effort did. On HLE and the physics set, there was no clear difference in cost, and on DRACO the cost was lower. The score was about the same on HLE. On the physics set it was 3.2 points higher, but that interval includes zero, so the difference isn't clear. So for a single agent, the clock saves more time than a lower effort level does. On DRACO, though, the single agent with both changes scored 1.2 points lower than at `medium` effort (95% interval 0.5 to 1.9 lower).
385
386382**When to use it.**
387383
388* Use both changes when an agent's time matters and a small score change is acceptable. On every configuration measured, they cut the time and cost per task, for teams and for single agents.
389* Check score on your own tasks before you adopt them. On DRACO, the score was 1.5 points lower for a team and 1.9 points lower for a single agent. On HLE, it was 1.7 points lower for a team and 1.1 points lower for a single agent. On the physics set, neither score change was clearly different from zero.
390* If you're already thinking about a lower effort level to save time, compare it with the clock. A single agent with both changes at `high` effort took less time than at `medium` effort: 53% less on DRACO, 25% less on HLE, and 27% less on the physics set. Its cost per task was 31% lower on DRACO, with no clear difference on HLE and the physics set.
384* Use both changes on research tasks like DRACO's when an agent's time matters and a few points of score are acceptable. On HLE and the physics set, the saving was much smaller.
385* Check score on your own tasks before you adopt them. For a single agent, the score was 4.1 points lower on DRACO, 3.0 points lower on the physics set, and up to 1.9 points lower on HLE, depending on the grader.
386* If you're thinking about a lower effort level to save time, compare it with the two changes. On all three sets, `low` effort was faster than the changes at `medium`, and the changes kept more of the score.
391387
392**How to add it.** Put this instruction at the start of every agent's system prompt:
388**How to add it.** Append this sentence to the end of the task in the agent's first `user` message, after a blank line. In a team, append it to each helper's brief too:
393389
394390```text wrap
395Time matters here: do not spend time that can be avoided, and the earlier a correct result is obtained, the better. The elapsed time so far is shown before each of your turns.
391Time matters here: do not spend time that can be avoided, and the earlier a correct result is obtained, the better.
396392```
397393
398The second sentence tells the model that the clock messages exist. The first request carries no clock, and the measured runs used exactly this wording.
394Then, before every request, including the first, append the elapsed time in whole seconds, such as `[elapsed 252s]`, to the end of the newest `user` message. On the first request, it goes in its own text block after the task. When the newest `user` message carries tool results, it goes at the end of the last tool result's text, after a blank line. When it's a new message of your own, it goes in its own text block at the end. Count from the start of the task, not from the start of the agent. In a team, every agent reads the same clock, so the first clock a helper sees already counts the time the team spent before the helper started. The system prompt doesn't change. The measured runs used this wording and format. Their clock started at the first token of the first response rather than at the start of the task. In the measured team runs, a helper's report reached the lead in a separate message after the clock, not inside the last tool result. To put the "Time matters here" sentence in the system prompt instead, see [Time signals for multiagent harnesses](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-opus-5-5#time-signals-for-multi-agent-harnesses) in Prompting Claude Opus 5.5.
399395
400Then, before each request after an agent's first, append a [mid-conversation system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages) that gives the elapsed time in whole seconds, such as `Elapsed time: 412 seconds`. Count from the start of the task, not from the start of the agent. In a team, every agent reads the same clock, so the first clock a helper sees already counts the time the team spent before the helper started. In a tool loop, put the message right after the `user` message that carries the tool results, as [Placement after tool results](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#placement-after-tool-results) shows. If you send the agent a new `user` message instead, put the clock after that message.
396Leave earlier clocks where they are. Each one becomes part of the conversation history, so the cached prefix still matches on the next request.
401397
402Leave earlier clock messages where they are. Each one becomes part of the conversation history, so the cached prefix still matches on the next request (see [Combining with prompt caching](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#combining-with-prompt-caching)). Anthropic measured these plain system messages, which stay visible to the model. A [turn-scoped system message](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages#turn-scoped-system-messages) would show the model only the newest clock, and Anthropic didn't measure that form.
398The following example runs one agent's tool loop with both changes. It handles client tools only, and `run_tool` returns each tool's result as a string:
403399
404The following example runs one agent's tool loop with both changes. It adds the clock after tool results, and it handles client tools only:
405
406400```python
407401import time
408402
from line 406
412406
413407TIME_MATTERS = (
414408 "Time matters here: do not spend time that can be avoided, and the earlier a "
415 "correct result is obtained, the better. The elapsed time so far is shown before "
416 "each of your turns."
409 "correct result is obtained, the better."
417410)
418411
419412
from line 415
422415 if started_at is None:
423416 # Wall-clock seconds, so helpers in other processes can share the lead's start time.
424417 started_at = time.time()
425 messages = [{"role": "user", "content": task}]
418
419 def clock():
420 return f"[elapsed {round(time.time() - started_at)}s]"
421
422 messages = [
423 {
424 "role": "user",
425 "content": [
426 {"type": "text", "text": f"{task}\n\n{TIME_MATTERS}"},
427 {"type": "text", "text": clock()},
428 ],
429 }
430 ]
426431 while True:
427432 # Stream because a 128,000-token cap is too large for a non-streaming request.
428433 with client.messages.stream(
429 model="claude-fable-5-1",
434 model="claude-opus-5-5",
430435 max_tokens=128000,
431436 cache_control={"type": "ephemeral"},
432 system=TIME_MATTERS + "\n\n" + system,
437 system=system,
433438 tools=tools,
434439 messages=messages,
435440 ) as stream:
from line 451
446451 for block in response.content
447452 if block.type == "tool_use"
448453 ]
454 # The clock goes at the end of the newest user message: the last tool result.
455 results[-1]["content"] += f"\n\n{clock()}"
449456 messages.append({"role": "user", "content": results})
450 # A system message must follow a user turn, so the clock goes after the tool results.
451 elapsed = int(time.time() - started_at)
452 messages.append(
453 {"role": "system", "content": f"Elapsed time: {elapsed} seconds"}
454 )
455457```
456458
457Claude Fable 5.1 supports mid-conversation system messages. The [list of supported models](https://platform.claude.com/docs/en/build-with-claude/mid-conversation-system-messages) covers the others. On a model without them, such as Claude Sonnet 5, you can put the same line in a text block after the last `tool_result` block in the `user` turn. Anthropic measured only the system-message form.
459On Claude Managed Agents, you can append the sentence to the task in the `user.message` event that starts the session, and the clock to each `user.message` and [`user.custom_tool_result`](https://platform.claude.com/docs/en/managed-agents/events-and-streaming#handling-custom-tool-calls) event you send. Turns that follow the platform's built-in tools, such as web search, see the last clock you sent, not the current time. In a [multiagent session](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration), the coordinator writes each worker's brief, so your client can't add the sentence to it. A worker sees a clock only in the results of custom tools that you run for it. Anthropic didn't measure the changes on Claude Managed Agents. To show the current time before every request, and to every agent in a team, run the agent loop yourself on the Messages API.
458460
459On Claude Managed Agents, you can send a [`system.message` event](https://platform.claude.com/docs/en/managed-agents/events-and-streaming#sending-system-messages) with a tool result or a user message. The message applies to that turn and every later turn. So turns that follow the platform's built-in tools, such as web search, see the last clock you sent, not the current time. A `system.message` also reaches only the session's primary thread. In a [multiagent session](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration), that is the coordinator's thread, so the worker agents never see a clock that you send this way. To show the current time before every turn, and to every agent in a team, run the agent loop yourself on the Messages API.
460
461461## Combine models
462462
463463Multi-model architectures fit workloads whose task complexity varies enough that different steps are best served by different models. When your traffic mixes routine work that a smaller model handles reliably with harder steps that need frontier capability, splitting the work keeps frontier intelligence where it matters while most tokens bill at smaller-model rates. When a workload lacks that mix, because its difficulty is uniform or it is one dependent chain, a single well-tuned model is usually the better choice. Each strategy section gives the rule for telling the two cases apart.
from line 487
487487
488488The consult rate responds to prompting. With only the tool's built-in description, executors under-call, especially on coding work, so the [advisor tool documentation](https://platform.claude.com/docs/en/agents-and-tools/tool-use/advisor-tool#prompting-for-coding-and-agent-tasks) gives a system prompt that asks for one call before substantive work and one before finishing, about two to three calls per task. The coding pairing measured next ran at that cadence with Claude Opus 5 as the executor, about two consultations on every task; with Claude Opus 5.5 as the executor it asked for advice about 1.4 times per attempt, and 4% of its attempts received no advice. That page also covers nudging an under-calling executor and capping calls client-side to bound cost. So watch the consult rate: prompt for it, measure it, and restore the executor's effort if it collapses.
489489
490**When it pays on cost.** An advisor saves money when a few short consultations, billed at the advisor's rate, replace running the advisor's model for the whole task. That works best when the advisor's model is priced well above the executor's, so the most cost-effective configuration is a frontier advisor over a mid-tier executor. A pairing at the top of the range can recover part of the advice's cost, because advice also saves executor tokens: an executor told the right approach explores fewer dead ends. In the coding pairing below with a Claude Opus 5 executor, that saving paid for about half of the advice: the executor spent $1.26 less per attempt than Opus 5 alone at its default, and the consultations cost $2.47. With a Claude Opus 5.5 executor, the advice saved almost no executor cost: $1.36 per attempt against $1.38 for Opus 5.5 alone at `high`, while the consultations cost $1.55.
490**When it pays on cost.** An advisor saves money when a few short consultations, billed at the advisor's rate, replace running the advisor's model for the whole task. That works best when the advisor's model is priced well above the executor's, so the most cost-effective configuration is a frontier advisor over a mid-tier executor. A pairing at the top of the range can recover part of the advice's cost, because advice also saves executor tokens: an executor told the right approach explores fewer dead ends. In the coding pairing below with a Claude Opus 5 executor, that saving paid for about half of the advice: the executor spent $1.26 USD less per attempt than Opus 5 alone at its default, and the consultations cost $2.47 USD. With a Claude Opus 5.5 executor, the advice saved almost no executor cost: $1.36 USD per attempt against $1.38 USD for Opus 5.5 alone at `high`, while the consultations cost $1.55 USD.
491491
492On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5.5 executor at `high` with a Claude Fable 5.1 advisor scored 90.1% at $2.92 per attempt. That is 1.7 points over Opus 5.5 alone at `high`, the executor's own setting, a gap at the edge of run-to-run noise with five attempts per task, for about 2.1 times the money; against Opus 5.5 at its default, `medium`, it is 3.5 points for about 3.5 times the money. It lands about on Opus 5.5's own effort curve, so the advisor buys about what more effort does: Opus 5.5 alone at `xhigh` scored 91.1% for $4.11 per attempt (one attempt per task). In August, a Claude Fable 5.1 advisor over a Claude Opus 5 executor was the most accurate configuration measured, at $6.21 per attempt, a little over twice what the Opus 5.5 pairing costs. The chart plots the Opus 5.5 pairing against Opus 5.5's own effort curve and Claude Fable 5.1's from August:
492On an internal agentic-coding benchmark[11](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), run with a plain API agent, a Claude Opus 5.5 executor at `high` with a Claude Fable 5.1 advisor scored 90.1% at $2.92 USD per attempt. That is 1.7 points over Opus 5.5 alone at `high`, the executor's own setting, a gap at the edge of run-to-run noise with five attempts per task, for about 2.1 times the money; against Opus 5.5 at its default, `medium`, it is 3.5 points for about 3.5 times the money. It lands about on Opus 5.5's own effort curve, so the advisor buys about what more effort does: Opus 5.5 alone at `xhigh` scored 91.1% for $4.11 USD per attempt (one attempt per task). In August, a Claude Fable 5.1 advisor over a Claude Opus 5 executor was the most accurate configuration measured, at $6.21 USD per attempt, a little over twice what the Opus 5.5 pairing costs. The chart plots the Opus 5.5 pairing against Opus 5.5's own effort curve and Claude Fable 5.1's from August:
493493
494494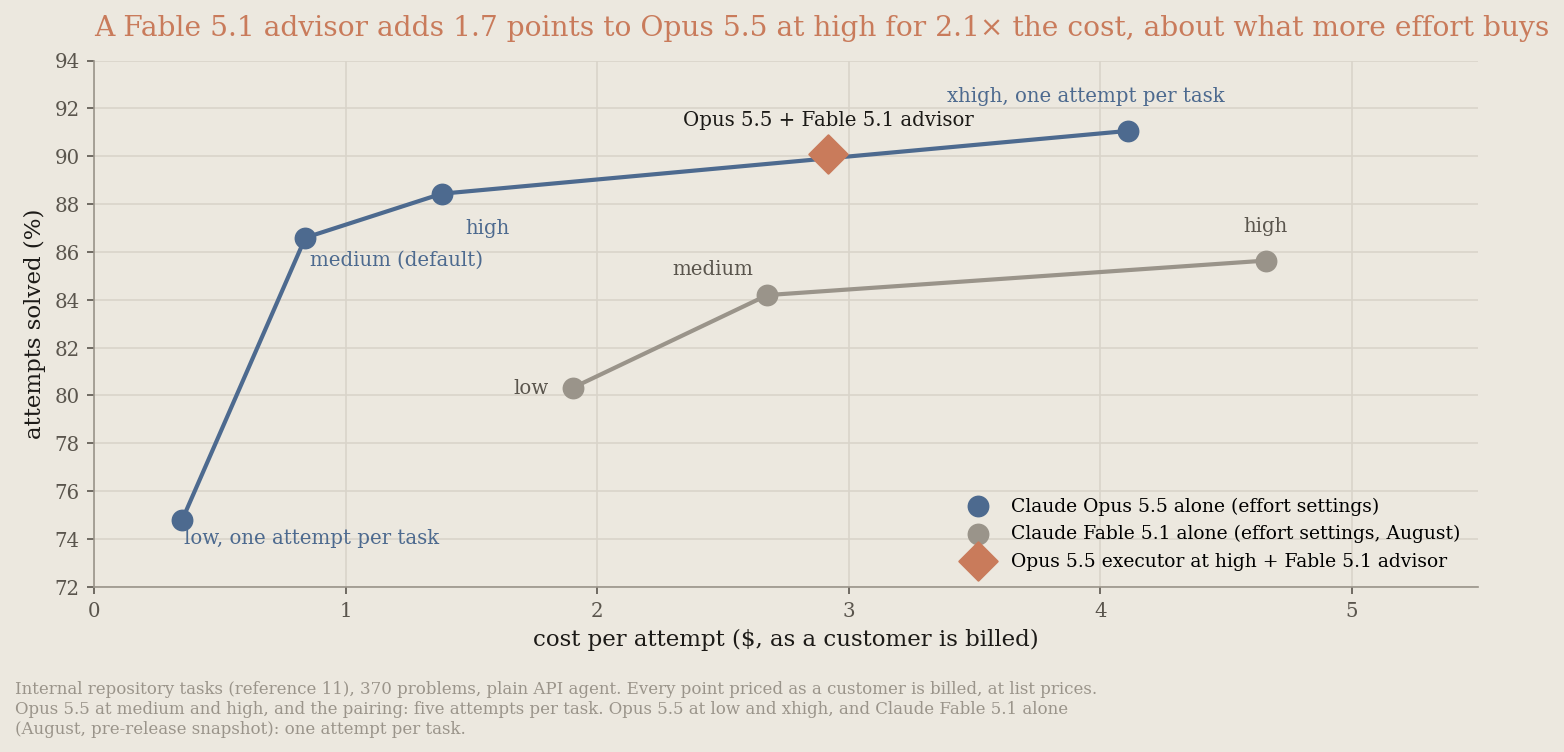
495495
from line 511
511511
512512This pattern saves wall-clock time when workers can run in parallel: on the corpus benchmark[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), an episode took about 2.3 hours with the coordinator running the platform's documented limit of 25 concurrent workers, compared with 15 to 20 hours solo. It saved money in only two measured situations. On work a single model could handle alone, the same model at lower effort was cheaper every time.
513513
514When workers run in parallel, a time instruction and an elapsed-time clock can shorten the run. On DRACO[21](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs), a team of same-model agents with the instruction and the clock finished in 33% less time at a 54% lower cost per task, and scored 1.5 points lower. Every agent in that team had the instruction and the clock. Anthropic didn't measure the clock with lower-cost workers. On Claude Managed Agents, the clock reaches only the coordinator, so the workers never see it. Anthropic didn't measure a team in which only the coordinator has the clock. The coordinator's clock is also current only on turns that follow your own tool results or messages. [Show the model elapsed time](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#show-the-model-elapsed-time) has the recipe for an agent loop that you run on the Messages API.
515
516514**Case 1: insurance against the cost tail on routine work.** A frontier model running alone occasionally spirals on a routine problem it would normally solve. Because you cannot tell in advance which those will be, a few such runs dominate the bill. A coordinator that hands routine work to a lower-cost worker caps that tail, because any spiraling now happens at worker rates.
517515
518Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost about half as much as Claude Fable 5 alone on average and about a third as much at the 90th percentile ($12 compared with $33), and the solo model's single most expensive run, at $84, was also wrong:
516Anthropic measured this on a deliberately easy slice of BrowseComp[4](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs) (10 problems the solo model reliably solves; 50 delegated and 70 solo runs). A Claude Fable 5 coordinator with one Claude Sonnet 5 worker cost about half as much as Claude Fable 5 alone on average and about a third as much at the 90th percentile ($12 USD compared with $33 USD), and the solo model's single most expensive run, at $84 USD, was also wrong:
519517
520518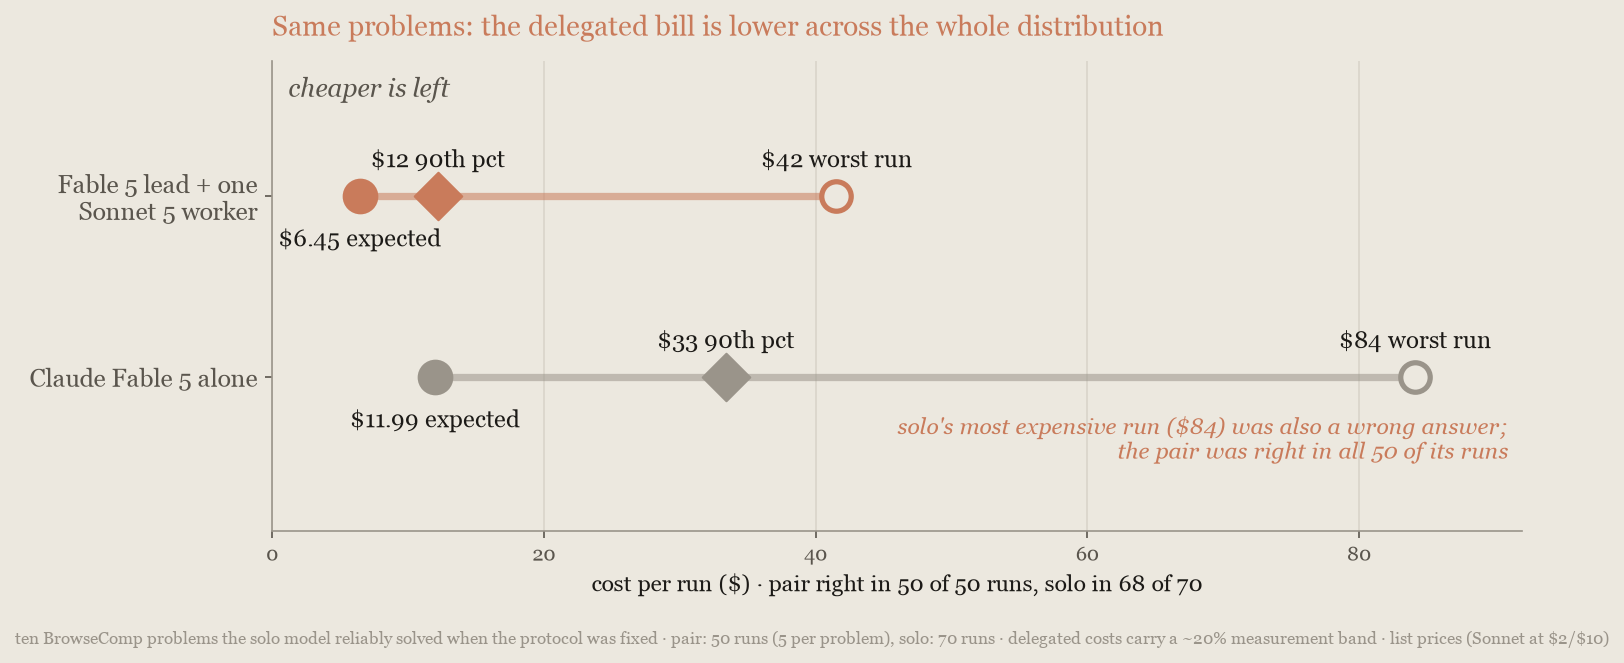
521519
from line 521
523521
524522**Case 2: work larger than one context window.** A solo model must work through an input that large serially, one context window at a time, paying to re-read its own state on every pass. Workers each read their own partition, in parallel and at worker rates. Reading-heavy work that still fits in one context window is a model-choice problem, not a delegation problem: on reading cost alone, the orchestrator comes out ahead only when no single context can hold the work.
525523
526Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5.1 solo cost $468 to $552 per episode across the three effort settings, and only its accuracy moved. The coordinator configuration, a Claude Fable 5.1 lead over 25 Claude Sonnet 5 workers, cost about half as much as those settings (47% to 55% less) and scored 10 to 12 points below them, in about 2.3 hours per episode against 15 to 20, while beating a Claude Sonnet 5 solo baseline outright:
524Anthropic built a benchmark for this case[8](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#refs): a 21.6-million-token corpus of 14 public Python packages with 130 planted defects, too large for any context window. Lowering effort cannot help, because the bill is the corpus read itself: Claude Fable 5.1 solo cost $468 USD to $552 USD per episode across the three effort settings, and only its accuracy moved. The coordinator configuration, a Claude Fable 5.1 lead over 25 Claude Sonnet 5 workers, cost about half as much as those settings (47% to 55% less) and scored 10 to 12 points below them, in about 2.3 hours per episode against 15 to 20, while beating a Claude Sonnet 5 solo baseline outright:
527525
528526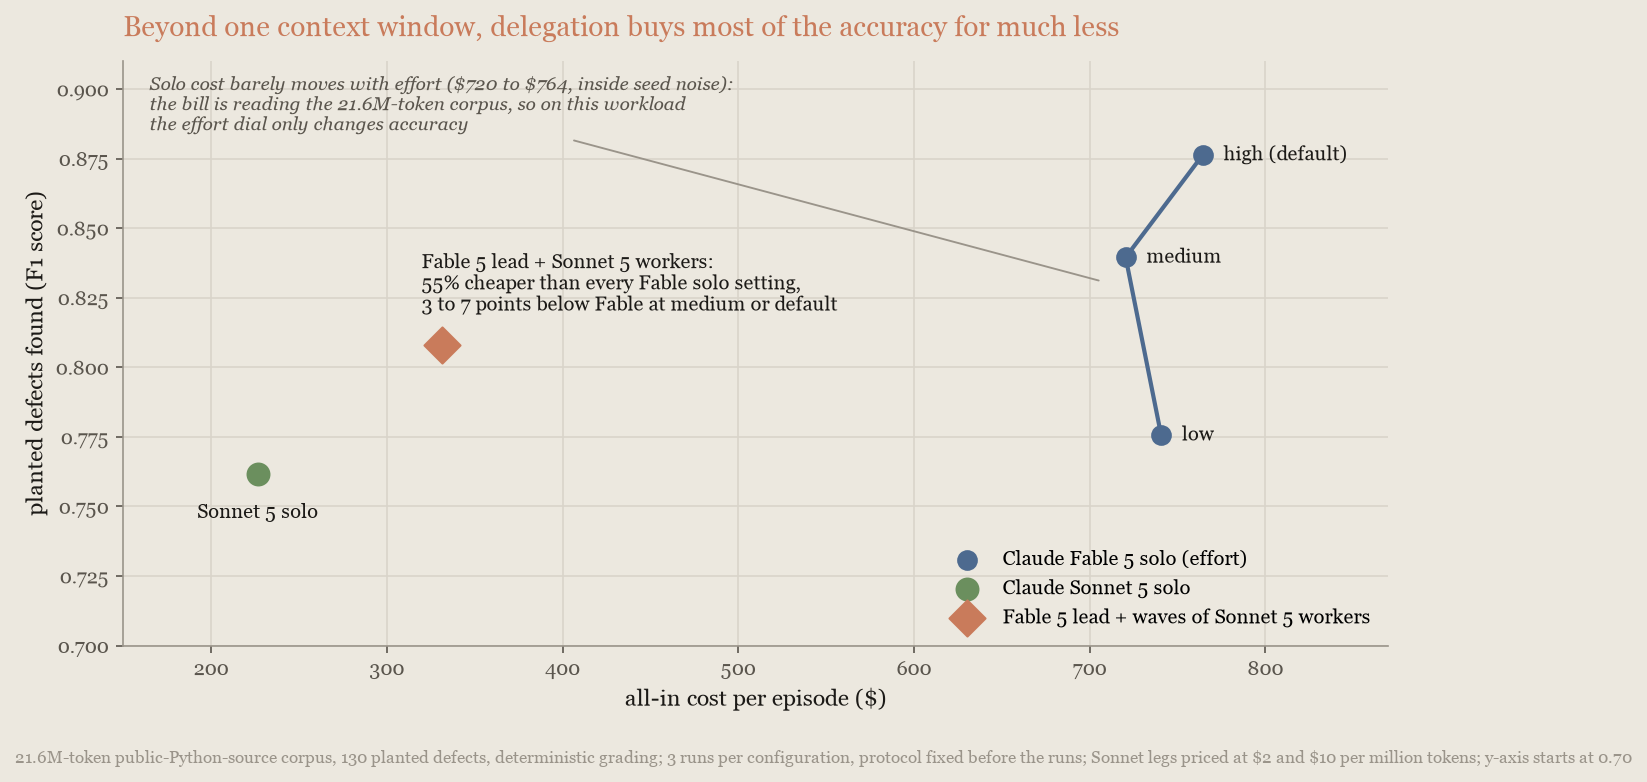
529527
from line 813
815813
816814## Benchmarks referenced
817815
818Except where a reference says otherwise, measurements are Anthropic-internal runs of these benchmarks. Unless noted, costs are USD at the list prices in effect when each benchmark ran; Claude Sonnet 5 figures use $2 and $10 per million input and output tokens. Charts labeled "notional USD" price each request's token counts at those rates rather than reporting invoices.
816Except where a reference says otherwise, measurements are Anthropic-internal runs of these benchmarks. Unless noted, costs are USD at the list prices in effect when each benchmark ran; Claude Sonnet 5 figures use $2 USD and $10 USD per million input and output tokens. Charts labeled "notional USD" price each request's token counts at those rates rather than reporting invoices.
819817
8208181. **WideSearch:** Wong et al., "WideSearch: Benchmarking Agentic Broad Info-Seeking," arXiv:2508.07999, 2025. Broad web-research tasks graded on a many-row table's completeness and accuracy; 200 problems, 3 runs per configuration, run August 1 to 2, 2026. The cost-concentration chart is a separate 20-problem run, 3 runs per problem, run August 3 to 4, 2026, costed from per-request billing records.
8218192. **GDPval:** OpenAI, "GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks," 2025. Knowledge-work deliverables graded against task rubrics; a 210-task run of the released gold set, one attempt per task, run August 2, 2026. A Claude model grades, so absolute scores may differ from published results.
8223. **SWE-bench Pro:** Scale AI, "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", 2025. A 482-problem subset selected for compatibility with Anthropic's evaluation harness; scores are not comparable to the public leaderboard. They are also not comparable to the SWE-bench Pro results in the Claude Opus 5.5 system card, which come from runs at `max` effort on a different problem set. Claude Opus 5.5 figures average two runs at `low`, `medium` (its default) and `high`, and use one run at `xhigh`, all run September 19 to 20, 2026, with the same 16,384-token cap per turn as the August Claude Opus 5 runs; the cap cut off 2 `xhigh` attempts and none at other settings. The Opus 5.5 runs used a version of the benchmark whose grading containers can reach only internal package mirrors. That version drops one problem whose test needs a live website, and on three more the reference solution fails there, so Opus 5.5 comparisons, and the Claude Fable 5.1 figures set beside them, use the remaining 478 problems. The Claude Opus 5 SWE-bench Pro figures in [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) and the [advisor pairings chart](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) average two runs at its default effort and use one run at `low`, all run August 4, 2026. Escalation figures come task by task from the Opus 5.5 runs: `low` first, then `high` on its failures, solved 96.4% to 97.5% across run pairings for about $0.17; `medium` first, 96.0% to 97.1% for about $0.24; `high` re-run on its own failures, 96.9% for $0.31; everything at `high`, 94.8% to 95.8% for $0.29. Costs on this subset are priced as a customer's organization is metered: each request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, checked against a customer ledger; the evaluation organization's own metering, which until September 10, 2026, billed cache reads in 8,192-token blocks for Claude Opus 5, Claude Fable 5, Claude Opus 4.7, and Claude Opus 4.8, gave figures 1.4 to 1.8 times higher for those models' runs; for Claude Fable 5.1, Claude Sonnet 5, and Claude Sonnet 4.6 the two differ by at most about 9%, and for the Claude Opus 5.5 figures they agree within 3% at each effort setting. The Claude Sonnet 5 executor pairings on the advisor chart come from the same measurement series on this subset: the Sonnet-plus-Opus 5 pairing was run twice (August 7 and August 8, 2026, a run and an exact replication), the low-effort pairing once (August 8, 2026), and Claude Sonnet 5 alone twice (77.4%, the baseline for both Pro rows). The Claude Fable 5 point in Upgrade the model is the mean of three runs at the default effort, run August 26, 2026, priced the same way. The Claude Fable 5.1 task-budget figures are one run per budget (two at 35,000 tokens) on the same subset at the default effort, run August 26, 2026, with an unbudgeted run the same day (92.1%, $1.10 per task) as the baseline; an earlier set at `low` effort, run August 21, 2026, scored 88.6% unbudgeted at $0.48 per task. The [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) comparison pairs that single run with the two pooled Claude Sonnet 5 runs from the same subset; at Fable 5.1's default effort the pair reads the other way, 41% more per solved task than Sonnet 5. The upgrade ladder is one run per model at its shipped defaults (two each for Opus 5 and Sonnet 5, and the Fable 5 point as described above), the Opus and Sonnet runs the same week in one harness and organization.
8234. **BrowseComp:** Wei et al., "BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents," OpenAI, 2025. Effort figures use a 500-problem cut, one to three runs per setting, run August 3, 2026, with the default point pooling two runs from July 26 to 27, 2026. The cost-insurance chart uses 10 reliably solved problems from a 26-problem slice, 50 delegated runs (August 1 to 2, 2026) and 70 solo runs (50 from August 2 to 3, 2026; 20 archived from July 12 to 13 and August 1, 2026), $6.45 compared with $11.99 per run in expectation; delegated figures carry a measurement band of about 20%.
8203. **SWE-bench Pro:** Scale AI, "SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?", 2025. A 482-problem subset selected for compatibility with Anthropic's evaluation harness; scores are not comparable to the public leaderboard. They are also not comparable to the SWE-bench Pro results in the Claude Opus 5.5 system card, which come from runs at `max` effort on a different problem set. Claude Opus 5.5 figures average two runs at `low`, `medium` (its default) and `high`, and use one run at `xhigh`, all run September 19 to 20, 2026, with the same 16,384-token cap per turn as the August Claude Opus 5 runs; the cap cut off 2 `xhigh` attempts and none at other settings. The Opus 5.5 runs used a version of the benchmark whose grading containers can reach only internal package mirrors. That version drops one problem whose test needs a live website, and on three more the reference solution fails there, so Opus 5.5 comparisons, and the Claude Fable 5.1 figures set beside them, use the remaining 478 problems. The Claude Opus 5 SWE-bench Pro figures in [Upgrade the model](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#upgrade-the-model) and the [advisor pairings chart](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#advisor-strategy-escalate-hard-decisions) average two runs at its default effort and use one run at `low`, all run August 4, 2026. Escalation figures come task by task from the Opus 5.5 runs: `low` first, then `high` on its failures, solved 96.4% to 97.5% across run pairings for about $0.17 USD; `medium` first, 96.0% to 97.1% for about $0.24 USD; `high` re-run on its own failures, 96.9% for $0.31 USD; everything at `high`, 94.8% to 95.8% for $0.29 USD. Costs on this subset are priced as a customer's organization is metered: each request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, checked against a customer ledger; the evaluation organization's own metering, which until September 10, 2026, billed cache reads in 8,192-token blocks for Claude Opus 5, Claude Fable 5, Claude Opus 4.7, and Claude Opus 4.8, gave figures 1.4 to 1.8 times higher for those models' runs; for Claude Fable 5.1, Claude Sonnet 5, and Claude Sonnet 4.6 the two differ by at most about 9%, and for the Claude Opus 5.5 figures they agree within 3% at each effort setting. The Claude Sonnet 5 executor pairings on the advisor chart come from the same measurement series on this subset: the Sonnet-plus-Opus 5 pairing was run twice (August 7 and August 8, 2026, a run and an exact replication), the low-effort pairing once (August 8, 2026), and Claude Sonnet 5 alone twice (77.4%, the baseline for both Pro rows). The Claude Fable 5 point in Upgrade the model is the mean of three runs at the default effort, run August 26, 2026, priced the same way. The Claude Fable 5.1 task-budget figures are one run per budget (two at 35,000 tokens) on the same subset at the default effort, run August 26, 2026, with an unbudgeted run the same day (92.1%, $1.10 USD per task) as the baseline; an earlier set at `low` effort, run August 21, 2026, scored 88.6% unbudgeted at $0.48 USD per task. The [Compare models](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#compare-models-on-cost-per-task) comparison pairs that single run with the two pooled Claude Sonnet 5 runs from the same subset; at Fable 5.1's default effort the pair reads the other way, 41% more per solved task than Sonnet 5. The upgrade ladder is one run per model at its shipped defaults (two each for Opus 5 and Sonnet 5, and the Fable 5 point as described above), the Opus and Sonnet runs the same week in one harness and organization.
8214. **BrowseComp:** Wei et al., "BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents," OpenAI, 2025. Effort figures use a 500-problem cut, one to three runs per setting, run August 3, 2026, with the default point pooling two runs from July 26 to 27, 2026. The cost-insurance chart uses 10 reliably solved problems from a 26-problem slice, 50 delegated runs (August 1 to 2, 2026) and 70 solo runs (50 from August 2 to 3, 2026; 20 archived from July 12 to 13 and August 1, 2026), $6.45 USD compared with $11.99 USD per run in expectation; delegated figures carry a measurement band of about 20%.
8248225. **Agent-architecture scaling:** Kim et al., "Towards a Science of Scaling Agent Systems," arXiv:2512.08296, 2025. Independent external study, cited only for the direction of the finding on when delegation does not pay, not for any figure.
8258236. **DeepWideSearch:** "DeepWideSearch: Benchmarking Depth and Width in Agentic Information Seeking," arXiv:2510.20168, 2025. The 220 questions span 15 domains, each combining many-row collection with multi-hop retrieval; measured on the benchmark's standing row set, 3 runs per configuration, run August 2, 2026 (the single-worker team point ran July 26 to 27, 2026).
8267. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs per setting, on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with the platform's own web search and fetch tools (August 26 to 27, 2026); scored on the 33 tasks no configuration refused, with attempts the production safety classifiers cut short removed; costs are what a customer is billed, the platform's requests plus web-search fees. Scores are each model's mean on the 33-task basis with its own pre-empted tasks removed; on the 21 tasks clean in every arm, Claude Fable 5.1 holds a 2-to-3-point lead over Claude Fable 5 at every effort level and both models are flat across effort. The caching chart re-prices the same requests with every input token at the uncached rate. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Claude Opus 5 at its default effort ran on the same surface and subset, three runs, on August 28, 2026: 68.8% on the raw 50 tasks, 70.8% on the 33-task basis, and 71.1% on the 21-task set, at $6.71 per task ($23.72 without caching); none of its attempts was cut short by the safety classifiers, under a safeguards deployment newer than the one the other models ran under.
8278. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is a run in which the Claude Fable 5.1 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers, run August 30, 2026; its three episodes scored F1 0.764, 0.825, and 0.791 after the extras audit (raw 0.751, 0.821, and 0.781) for $225, $234, and $283. The Claude Sonnet 5 solo configuration ran August 3 to 4, 2026; the Claude Fable 5.1 solo configurations ran August 24 to 25, 2026, under the platform's launch serving settings, three seeds per effort setting, on the same corpus build. The sandbox image carried installed copies of part of the corpus, and Claude Fable 5.1's final assembly step compared against them in 7 of 9 episodes; re-grading without those additions moved the affected seeds by up to 3 points. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
8247. **DeepResearch Bench II:** Li et al., "DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report," arXiv:2601.08536, 2026. Its 132 research tasks across 22 domains are graded against expert-derived binary rubrics; measured on a 50-task subset stratified across all themes, one attempt per task, 3 runs per setting, on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with the platform's own web search and fetch tools (August 26 to 27, 2026); scored on the 33 tasks no configuration refused, with attempts the production safety classifiers cut short removed; costs are what a customer is billed, the platform's requests plus web-search fees. Scores are each model's mean on the 33-task basis with its own pre-empted tasks removed; on the 21 tasks clean in every arm, Claude Fable 5.1 holds a 2-to-3-point lead over Claude Fable 5 at every effort level and both models are flat across effort. The caching chart re-prices the same requests with every input token at the uncached rate. Claude Opus 4.6 judges under the benchmark's rubric protocol; the original uses a different judge, and an Anthropic judge may favor the house style. Claude Opus 5 at its default effort ran on the same surface and subset, three runs, on August 28, 2026: 68.8% on the raw 50 tasks, 70.8% on the 33-task basis, and 71.1% on the 21-task set, at $6.71 USD per task ($23.72 USD without caching); none of its attempts was cut short by the safety classifiers, under a safeguards deployment newer than the one the other models ran under.
8258. **Corpus defect sweep:** Anthropic-internal, for work larger than one context window: a 21.6-million-token corpus from 14 public Python package sources with 130 planted defects and deterministic grading; protocol fixed before the runs and internally reviewed; three runs per configuration. Every configuration ran on Claude Managed Agents. The charted team configuration is a run in which the Claude Fable 5.1 coordinator ran the whole sweep inside the platform at its documented limit of 25 concurrent Claude Sonnet 5 workers, run August 30, 2026; its three episodes scored F1 0.764, 0.825, and 0.791 after the extras audit (raw 0.751, 0.821, and 0.781) for $225 USD, $234 USD, and $283 USD. The Claude Sonnet 5 solo configuration ran August 3 to 4, 2026; the Claude Fable 5.1 solo configurations ran August 24 to 25, 2026, under the platform's launch serving settings, three seeds per effort setting, on the same corpus build. The sandbox image carried installed copies of part of the corpus, and Claude Fable 5.1's final assembly step compared against them in 7 of 9 episodes; re-grading without those additions moved the affected seeds by up to 3 points. Absolute F1 is specific to this corpus build, not comparable across benchmarks; configuration comparisons are like for like.
8288269. **GPQA Diamond:** Rein et al., "GPQA: A Graduate-Level Google-Proof Q\&A Benchmark," 2023. The 198-question Diamond subset, two runs per configuration, run August 7, 2026 (Claude Opus 5.5: September 19, 2026), model-graded against reference answers, advisor tokens metered per request. A platform safety check refused two biology questions on the Claude Sonnet 5 executors, and one of them also on Claude Opus 5; excluding them changes no comparison by more than one point. Claude Opus 5.5's 92% comes from two runs that set `fallbacks: "default"` to opt into [server-side fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback#server-side-fallback), with any attempt that still ended in a refusal counted as wrong. In each run the safety check flagged six biology questions, Claude Opus 5 answered five of them through the fallback, and the sixth still ended in a refusal. Opus 5.5's cost per question includes those fallback answers. Without counting refusals as wrong, these runs score 93%, because the grader still assigns an answer option to a refused attempt, usually the correct one. With refusals counted as wrong, Claude Opus 5's runs score 91% (one refusal per run), as do two Claude Opus 5.5 runs with fallback off, in which Opus 5.5 refused five or six biology questions per run.
82982710. **DeepSWE:** Datacurve, "DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks," arXiv:2607.07946, 2026. The set has 113 original tasks across five languages with program-based verifiers. Pairings are two runs each, run August 7, 2026, with advisor tokens metered per request, and used a client-side advisor loop rather than the advisor tool, with identical accounting. Single-model effort sweeps are single runs priced from token counts, a cache-aware approximation. Costs per task are run totals divided by 113.
83082811. **Internal agentic-coding benchmark:** Anthropic-internal: 370 repository tasks graded by the repositories' own tests. The API figures were measured with a 128,000-token output cap, one run per configuration: Opus 5 alone at the default effort August 9 to 10, 2026, and at `low` and `medium` August 10, 2026; Claude Fable 5.1 alone at five explicitly set effort values August 20, 2026 (the chart shows three of them); and the pairing August 24 to 25, 2026. Claude Opus 5.5 alone ran on all 370 tasks, September 19 to 20, 2026: at its default effort (`medium`) and at `high` with five attempts per task, and at `low` and `xhigh` with one (369 of 370 scored at each, after a setup-check failure). The Claude Opus 5.5 executor at `high` with the released Claude Fable 5.1 as advisor (the August runs used a pre-release snapshot) ran five attempts per task on the same dates; one task failed its setup check, so 1,845 attempts were scored. The 279 attempts in which the advisor was turned away under load were re-run, and attempts whose consults timed out were kept, as in August. The August runs had five attempts per task for the pairing and the Claude Opus 5 control and one for the other points. The August pairing averaged about two advisor consultations per attempt; the Claude Opus 5.5 pairing requested 1.39 and received 1.35. Costs are per attempt. Costs are priced as a customer's organization is metered: each agent-loop request's prior prompt as a cache read and its new tokens as a 5-minute cache write, from the runs' own usage records, and each advisor call, which uses no cache, from its recorded tokens, all at list prices. The Claude Code figures are runs of the same tasks from July 8 to 23, 2026, one run per configuration, costs approximate.
83182912. **Internal repository-task benchmark (cap measurement):** A separate Anthropic-internal set of about 130 repository tasks, run August 20, 2026 (Claude Fable 5.1) and September 19, 2026 (Claude Opus 5.5, at its default effort, `medium`), with a plain API agent loop, one attempt per task. The Claude Fable 5.1 runs are 135 tasks per cap at the default effort set explicitly: the 16,384-token figure averages two runs (36.3% on both); the 64,000 and 128,000 figures are single runs (58.5% and 60.0%). Six problems drew a safety refusal in every run and count as failures. The Claude Opus 5.5 16,384-token figure averages two runs (134 and 135 tasks scored), and its 64,000 and 128,000 figures are single runs (135 tasks each); two attempts in each 16,384-token run ended in a safety refusal and count as failures. The SWE-bench Pro cap figures are one Claude Fable 5.1 run per cap at the default effort, run August 26, 2026, on a 100-problem subset stratified from reference 3's 482-problem set, not comparable to its scores; the two caps scored the same at the default. The chart's per-turn distributions come from the Claude Opus 5.5 and Claude Fable 5.1 runs at 128,000: no Opus 5.5 turn reached the cap (the longest was about 61,000 tokens, and 0.56% of its turns exceeded 16,384), and one Fable 5.1 turn reached 128,000 (0.46% of its turns exceeded 16,384).
83213. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 6 and 9, 2026 (Claude Opus 5 alone) and September 20, 2026 (Claude Opus 5.5), with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. They are also not comparable to the Chartography results in the Claude Opus 5.5 system card, which use a different grader and run at `max` effort. Two runs per configuration (three for Claude Opus 5.5), pooled; run-to-run spreads were up to 10 points. Costs are what a customer running the agent routinely is billed: each chart's first request reads the agent's shared system prompt and tools from the cache, as it does when another session of the same agent ran in the previous 5 minutes. A chart run on its own costs about $0.03 more with Claude Opus 5 or Claude Opus 5.5 and about $0.12 more with Claude Fable 5.1. The August figures are re-priced this way from the runs' usage records; the evaluation organization's own metering, which until September 10, 2026, billed Claude Opus 5's cache reads in 8,192-token blocks, overstated Claude Opus 5's costs. Costs exclude sandbox time, which added under 1% to the August runs. The Claude Fable 5.1 solo runs are from August 24, 2026, under the platform's launch serving settings, two runs per setting; six attempts hit the 15-minute session cap and score 0, and two charts per run were answered by Claude Opus 5 after a safety refusal. The Claude Opus 5 low-effort executor with a Claude Fable 5.1 advisor ran twice on August 30, 2026, under the same settings (63.0 and 67.0, mean 65.0, at $0.47 a chart; the advisor was consulted on 88% of tasks in each run, and 4 of its 219 replies came from Claude Opus 5 instead, each after a production safety filter stopped the advisor's own reply). Claude Opus 5.5 ran at `low`, with server-side fallback off and a safety classifier judging every tool call: three runs alone (70, 68, and 68) and three with a Claude Fable 5.1 advisor configured (59, 63, and 63), in which it consulted the advisor on 1 of 300 tasks. The consult-rate comparison for the earlier pairings comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
83013. **Chartography:** Surge AI, "Chartography," 2026. The complete released 100-question set, measured August 6 and 9, 2026 (Claude Opus 5 alone) and September 20, 2026 (Claude Opus 5.5), with Anthropic's implementation on Claude Managed Agents (standard cloud sandbox; advisor configurations use the Managed Agents advisor). Claude Sonnet 4.6 grades instead of the reference judge and the benchmark runs with tools, so scores compare across configurations here but not to the published leaderboard. They are also not comparable to the Chartography results in the Claude Opus 5.5 system card, which use a different grader and run at `max` effort. Two runs per configuration (three for Claude Opus 5.5), pooled; run-to-run spreads were up to 10 points. Costs are what a customer running the agent routinely is billed: each chart's first request reads the agent's shared system prompt and tools from the cache, as it does when another session of the same agent ran in the previous 5 minutes. A chart run on its own costs about $0.03 USD more with Claude Opus 5 or Claude Opus 5.5 and about $0.12 USD more with Claude Fable 5.1. The August figures are re-priced this way from the runs' usage records; the evaluation organization's own metering, which until September 10, 2026, billed Claude Opus 5's cache reads in 8,192-token blocks, overstated Claude Opus 5's costs. Costs exclude sandbox time, which added under 1% to the August runs. The Claude Fable 5.1 solo runs are from August 24, 2026, under the platform's launch serving settings, two runs per setting; six attempts hit the 15-minute session cap and score 0, and two charts per run were answered by Claude Opus 5 after a safety refusal. The Claude Opus 5 low-effort executor with a Claude Fable 5.1 advisor ran twice on August 30, 2026, under the same settings (63.0 and 67.0, mean 65.0, at $0.47 USD a chart; the advisor was consulted on 88% of tasks in each run, and 4 of its 219 replies came from Claude Opus 5 instead, each after a production safety filter stopped the advisor's own reply). Claude Opus 5.5 ran at `low`, with server-side fallback off and a safety classifier judging every tool call: three runs alone (70, 68, and 68) and three with a Claude Fable 5.1 advisor configured (59, 63, and 63), in which it consulted the advisor on 1 of 300 tasks. The consult-rate comparison for the earlier pairings comes from rerunning the same configurations on the Messages API with a container tool set, August 10 to 11, 2026.
83383114. **Support-desk prompt-audit evaluation:** An Anthropic-constructed set of 44 support tickets with deterministic grading, run in early August 2026 and reported on August 8, 2026, under six system prompts, each adding to the same clean prompt one pattern common in prompts written for Claude Opus 4.8 and Claude Sonnet 4.6. Each chart point is one of three cases (older model, newer model on the same prompt, newer model after the audit) averaged over the six prompts and 44 tickets. The Opus 5 accuracy gain has a 95% confidence interval of 3 to 8 points; the Sonnet accuracy differences are within noise.
83483215. **Data-file question set:** An Anthropic-constructed set of 25 aggregate questions over a 1,862-row slice of a public liquor-sales CSV, with ground truth computed by pandas and exact-match grading, run on Claude Sonnet 5 and Claude Opus 5 with thinking disabled (the in-context arm cannot complete at the default), a 4,000-token output cap, and no prompt caching, three runs per configuration, run August 19, 2026. The file arm uploads the CSV through the Files API and uses the `code_execution_20260120` tool.
83516. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run on Claude Sonnet 5 on August 23, 2026, and on Claude Opus 5.5 on September 19 and 20, 2026, at its default effort (`medium`) and at `high`, on the Messages API with the same harness (for Claude Opus 5.5, a port of it that sends the same request bodies), the Claude Opus 5.5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute and 45-minute pauses on a 5-issue subset on both models). Claude Opus 5's keep-alive figures below come from the same job on August 23, 2026, with `max_tokens` raised to 4,096, on the same schedules except the 2-minute and 45-minute pauses. Three runs per cell, cost computed from each response's `usage` fields at list prices (for Claude Opus 5.5, $4 input, $5 5-minute write, $8 1-hour write, $0.20 cache read, and $20 output per million tokens; Claude Sonnet 5 ran on an Anthropic-internal organization whose usage is metered the same way as a customer organization's), accuracy against the same gold labels. The Claude Opus 5.5 figures on this page cover both effort levels. The crossover is about 3.3% of turns on Claude Sonnet 5 and 3.1% to 3.2% on Claude Opus 5.5: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 twenty-issue sessions and the 36 Claude Opus 5.5 twenty-issue sessions at each effort level (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). In the 5% cell the 5-minute and 1-hour settings tied on Claude Sonnet 5, because that draw's pauses fell on small prefixes; on Claude Opus 5.5 they nearly tied. The page's 1-in-20 rule sits above the measured crossover. Claude Opus 5.5's time to first token after a pause was not measured. Anthropic measured keep-alive requests that refresh the 5-minute cache on Claude Sonnet 5 and Claude Opus 5 on August 23, 2026, and on Claude Opus 5.5 in the runs above, always sent with `max_tokens: 1`. On Claude Sonnet 5 they cost 7.7% less than the 1-hour setting with 5% of turns paused and about the same with 10%; on Claude Opus 5 no difference was measurable at either share; on both they cost more with a pause of 6 minutes or more before every turn. On Claude Opus 5.5 they cost 8% to 18% less than the 1-hour setting with 5% and 10% of turns paused (about 10% to 15% once between-session noise is removed by re-billing each keep-alive session's own tokens at 1-hour cache prices), and more with a pause before every turn: 4% to 6% more at 6 minutes, 9% to 10% at 20 minutes, and 56% to 58% at 45 minutes. Keep-alive saved more on Claude Opus 5.5 because each keep-alive request re-reads the prefix at the cache-read price: 0.05x the input price, against 0.1x on Claude Sonnet 5 and Claude Opus 5; Claude Opus 5's sessions, re-billed at Claude Opus 5.5's prices, show nearly the same savings as Claude Opus 5.5. Anthropic's pre-launch API tests on Claude Opus 5.5 show that a `max_tokens: 0` request writes the cache and that the next request reads it; whether such a request refreshes an existing entry was not measured on Opus 5.5. On Claude Fable 5.1, at 0.025x, keep-alive was cheaper even with a pause before every turn, except at 45-minute pauses (reference 19).
83316. **Cache duration measurement:** The 20-issue triage job from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run on Claude Sonnet 5 on August 23, 2026, and on Claude Opus 5.5 on September 19 and 20, 2026, at its default effort (`medium`) and at `high`, on the Messages API with the same harness (for Claude Opus 5.5, a port of it that sends the same request bodies), the Claude Opus 5.5 cells with `max_tokens` raised to 4,096, with pauses inserted before a randomly chosen share of turns (none, 5%, 10%, and every turn at 6 minutes on all 20 issues on both models, plus every turn at 2 minutes on Claude Sonnet 5; 20-minute and 45-minute pauses on a 5-issue subset on both models). Claude Opus 5's keep-alive figures below come from the same job on August 23, 2026, with `max_tokens` raised to 4,096, on the same schedules except the 2-minute and 45-minute pauses. Three runs per cell, cost computed from each response's `usage` fields at list prices (for Claude Opus 5.5, $4 USD input, $5 USD 5-minute write, $8 USD 1-hour write, $0.20 USD cache read, and $20 USD output per million tokens; Claude Sonnet 5 ran on an Anthropic-internal organization whose usage is metered the same way as a customer organization's), accuracy against the same gold labels. The Claude Opus 5.5 figures on this page cover both effort levels. The crossover is about 3.3% of turns on Claude Sonnet 5 and 3.1% to 3.2% on Claude Opus 5.5: the median of each session's break-even share, computed by the cost model from that session's turn-by-turn context sizes, over all 45 Claude Sonnet 5 twenty-issue sessions and the 36 Claude Opus 5.5 twenty-issue sessions at each effort level (every pause schedule run on the full job, under all three cache settings, three runs each; the 5-issue cells are not in it). In the 5% cell the 5-minute and 1-hour settings tied on Claude Sonnet 5, because that draw's pauses fell on small prefixes; on Claude Opus 5.5 they nearly tied. The page's 1-in-20 rule sits above the measured crossover. Claude Opus 5.5's time to first token after a pause was not measured. Anthropic measured keep-alive requests that refresh the 5-minute cache on Claude Sonnet 5 and Claude Opus 5 on August 23, 2026, and on Claude Opus 5.5 in the runs above, always sent with `max_tokens: 1`. On Claude Sonnet 5 they cost 7.7% less than the 1-hour setting with 5% of turns paused and about the same with 10%; on Claude Opus 5 no difference was measurable at either share; on both they cost more with a pause of 6 minutes or more before every turn. On Claude Opus 5.5 they cost 8% to 18% less than the 1-hour setting with 5% and 10% of turns paused (about 10% to 15% once between-session noise is removed by re-billing each keep-alive session's own tokens at 1-hour cache prices), and more with a pause before every turn: 4% to 6% more at 6 minutes, 9% to 10% at 20 minutes, and 56% to 58% at 45 minutes. Keep-alive saved more on Claude Opus 5.5 because each keep-alive request re-reads the prefix at the cache-read price: 0.05x the input price, against 0.1x on Claude Sonnet 5 and Claude Opus 5; Claude Opus 5's sessions, re-billed at Claude Opus 5.5's prices, show nearly the same savings as Claude Opus 5.5. Anthropic's pre-launch API tests on Claude Opus 5.5 show that a `max_tokens: 0` request writes the cache and that the next request reads it; whether such a request refreshes an existing entry was not measured on Opus 5.5. On Claude Fable 5.1, at 0.025x, keep-alive was cheaper even with a pause before every turn, except at 45-minute pauses (reference 19).
83683417. **Cache-read share in production:** Aggregated first-party Claude API usage for the 14 days ending August 23, 2026, direct API product only, Anthropic-internal organizations excluded, no organization identified. An organization-day counts as an agent loop when its requests carry tool definitions and tool results, its prompts hold 9 or more prior tool calls on average, caching was used, and it made at least 10 such requests (the API has no conversation identifier, so this stands in for conversation length): 303,003 organization-days across 106,487 organizations, median cache-read share 84.2% of all input tokens, upper quartile 91.7%. Use-case labels (the organization's declared use case, or otherwise its classified one) cover 74% of those organization-days and 99% of their tokens; coding organizations supply 87% of agentic input tokens and read a median 88.5% (90.9% at 25 or more prior tool calls), upper quartile 93.4%, with about 72% of coding organization-days at 80% or more; support, research, and data agents read 84% to 85%. The top decile of organization-days reads 95.9% or more for coding and 94.2% to 94.8% for support, research, data, and other agents. The request-level split at 25 or more prior tool calls comes from a six-hour sample: coding 92% read, 7% write, under 1% uncached. Unlabeled organizations, mostly small, read a median 11%. Organization-days with no tool definitions read a median 34.6%. An independent query over the same window that reconstructs conversations of 10 or more requests, rather than scoring organization-days, puts the median at 90.2%; the difference is scope, not data.
83718. **Compaction timing measurement:** The triage agent's long variant from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 24, 2026, on Claude Sonnet 5 with the 5-minute cache, cost from the usage fields at list prices, five sessions per arm: a no-change arm at the default effort throughout ($0.81 per session), and two arms that start at low effort and make the same two cache-breaking changes, a switch to the default effort and one added tool, either mid-session at requests 12 and 17 ($0.95) or together on the first request after the first compaction ($0.75). A fourth arm of six sessions, run August 25, 2026, made the same two changes on the request that triggered the first compaction ($0.92 per session): that request's summarization pass wrote the 81,000-token context to the cache instead of reading it, so that pass cost $0.21 against $0.04 for the same pass in the boundary arm. Sessions first compacted at request 21 to 25 (16 of the 21 sessions at request 22), once the prompt passed the 80,000-token compaction trigger, and two no-change sessions compacted a second time near the end. The boundary arm's lower total than the no-change arm reflects its low-effort requests before the change and those second compactions rather than caching: the two arms' re-write costs differ by under a cent. The mid-session arm paid $0.23 per session in cache re-writes; the difference between the mid-session and boundary arms was $0.20 with a 95% confidence interval of $0.11 to $0.29. One mid-session session ran cheap ($0.82) after its model mis-called the search tool following compaction and got empty results; it is included, and without it the arm averages $0.98. Accuracy averaged 14.2 of 20 labels in each August 24 arm and 14.7 in the August 25 arm; cache reads were 91% of prompt tokens with no changes, 85% mid-session, 91% at the boundary, and 86% with the changes on the triggering request.
83819. **Cache duration measurement on Claude Fable 5.1:** The same 20-issue triage job and harness as reference 16, run August 23 and August 26, 2026, on the Claude Fable 5.1 launch snapshot at its launch prices ($10 input, $12.50 5-minute write, $20 1-hour write, $0.25 cache read, $50 output per million tokens), three settings per schedule: the 5-minute cache, the 1-hour cache, and the 5-minute cache kept warm by a `max_tokens: 0` request on the unchanged prefix every 4 minutes, timed from the previous request's start (the August 23 runs sent keep-alive requests with `max_tokens: 1`; in the August 26 cells reported here, every keep-alive request refreshed the cache and billed no output). Schedules: no pauses, 10% of turns, and every turn at 6 minutes on all 20 issues, and 45-minute pauses on the 5-issue subset; three runs per cell (six for the August 26 keep-alive cell with 45-minute pauses), cost computed from each response's `usage` fields at list prices, accuracy against the same gold labels (12 to 17 exact labels of 20). Per-session means on August 26 for the 5-minute, 1-hour, and keep-alive settings: no pauses $2.42, $3.09, $2.29; 10% paused $4.50, $2.96, $2.36; every turn $22.89, $3.01, $2.62; the August 23 cells agree within 6%. The 45-minute figures ($1.68, $0.59, and $0.71 per 5-issue session) are from a clean re-run on August 26 after a cache-billing incident spoiled that day's first cells; the August 23 runs gave $1.67, $0.58, and $0.70. The crossover between the 5-minute and 1-hour settings is 3.1% of turns, the same measure as reference 16.
83518. **Compaction timing measurement:** The triage agent's long variant from [Trim input and context tokens](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#trim-input-and-context-tokens), run August 24, 2026, on Claude Sonnet 5 with the 5-minute cache, cost from the usage fields at list prices, five sessions per arm: a no-change arm at the default effort throughout ($0.81 USD per session), and two arms that start at low effort and make the same two cache-breaking changes, a switch to the default effort and one added tool, either mid-session at requests 12 and 17 ($0.95 USD) or together on the first request after the first compaction ($0.75 USD). A fourth arm of six sessions, run August 25, 2026, made the same two changes on the request that triggered the first compaction ($0.92 USD per session): that request's summarization pass wrote the 81,000-token context to the cache instead of reading it, so that pass cost $0.21 USD against $0.04 USD for the same pass in the boundary arm. Sessions first compacted at request 21 to 25 (16 of the 21 sessions at request 22), once the prompt passed the 80,000-token compaction trigger, and two no-change sessions compacted a second time near the end. The boundary arm's lower total than the no-change arm reflects its low-effort requests before the change and those second compactions rather than caching: the two arms' re-write costs differ by under $0.01 USD. The mid-session arm paid $0.23 USD per session in cache re-writes; the difference between the mid-session and boundary arms was $0.20 USD with a 95% confidence interval of $0.11 USD to $0.29 USD. One mid-session session ran cheap ($0.82 USD) after its model mis-called the search tool following compaction and got empty results; it is included, and without it the arm averages $0.98 USD. Accuracy averaged 14.2 of 20 labels in each August 24 arm and 14.7 in the August 25 arm; cache reads were 91% of prompt tokens with no changes, 85% mid-session, 91% at the boundary, and 86% with the changes on the triggering request.
83619. **Cache duration measurement on Claude Fable 5.1:** The same 20-issue triage job and harness as reference 16, run August 23 and August 26, 2026, on the Claude Fable 5.1 launch snapshot at its launch prices ($10 USD input, $12.50 USD 5-minute write, $20 USD 1-hour write, $0.25 USD cache read, $50 USD output per million tokens), three settings per schedule: the 5-minute cache, the 1-hour cache, and the 5-minute cache kept warm by a `max_tokens: 0` request on the unchanged prefix every 4 minutes, timed from the previous request's start (the August 23 runs sent keep-alive requests with `max_tokens: 1`; in the August 26 cells reported here, every keep-alive request refreshed the cache and billed no output). Schedules: no pauses, 10% of turns, and every turn at 6 minutes on all 20 issues, and 45-minute pauses on the 5-issue subset; three runs per cell (six for the August 26 keep-alive cell with 45-minute pauses), cost computed from each response's `usage` fields at list prices, accuracy against the same gold labels (12 to 17 exact labels of 20). Per-session means on August 26 for the 5-minute, 1-hour, and keep-alive settings: no pauses $2.42 USD, $3.09 USD, $2.29 USD; 10% paused $4.50 USD, $2.96 USD, $2.36 USD; every turn $22.89 USD, $3.01 USD, $2.62 USD; the August 23 cells agree within 6%. The 45-minute figures ($1.68 USD, $0.59 USD, and $0.71 USD per 5-issue session) are from a clean re-run on August 26 after a cache-billing incident spoiled that day's first cells; the August 23 runs gave $1.67 USD, $0.58 USD, and $0.70 USD. The crossover between the 5-minute and 1-hour settings is 3.1% of turns, the same measure as reference 16.
83983720. **Terminal-Bench 3:** the public terminal-agent benchmark's 74 tasks, run on [Claude Managed Agents](https://platform.claude.com/docs/en/managed-agents/overview) with two custom tools, a shell and a file editor that the evaluation harness runs in each task's own container, in place of the platform's built-in tools, and otherwise at the platform's default settings for external accounts, two runs per model at `high` effort, August 27 to 28, 2026. These runs used Terminal-Bench version 3.0, and their scores are not comparable with the public Terminal-Bench leaderboard or with the Terminal-Bench 4.0 results in the Claude Opus 5.5 system card, which come from runs in Claude Code at `max` effort. Each task's time limits are 2.5 times the benchmark's own, which gives the agent between 75 minutes and 20 hours per task (5 hours for the median task), and each task gets three times the memory it specifies, from 6 GiB to 96 GiB, with extra memory for the 12 tasks that run helper services. The agent had no general internet access: its containers could reach an internal package mirror, a short list of download sites including GitHub and the Python Package Index, and a few sites specific to some tasks, and eight of the tasks had no network access at all. Scores are raw pass rates over the 148 attempts per model; single runs swing by 5 to 11 points. Costs are what a customer would be billed at list prices, re-priced request by request from the runs' usage records with the 5-minute cache lifetime. Claude Opus 4.7 ended 11 of its 148 attempts at its output cap.
84021. **DRACO:** Perplexity, "DRACO: a Cross-Domain Benchmark for Deep Research Accuracy, Completeness, and Objectivity," arXiv:2602.11685, 2026. Its 100 research tasks across 10 domains are graded against expert-written rubrics, and the score is the benchmark's normalized score. Every configuration ran on the Claude API with Claude Fable 5.1, the default adaptive thinking, the production safety classifiers on, and `max_tokens` at 128,000: a single agent at `high` and at `medium` effort, the single agent at `high` with the instruction and the clock, and a team at `high` with and without them. The team is a lead agent that starts helper agents of the same model through a tool, with no cap on their number. On DRACO, the lead started a median of 4 helpers per attempt. Each configuration made three attempts at each task, run September 8 to 10, 2026. An attempt that hit the four-hour limit was run again, and the new attempt counts. The only attempts left out are all 3 attempts at one task for the single agent at `medium` effort, so that configuration covers 99 tasks. That task timed out on every attempt, in the original run and in the re-run. Scoring those 3 attempts as 0, as the benchmark's own scoring would, affects only the two comparisons with `medium` effort. The score change at `medium` effort against `high` moves from 0.7 to 1.7 points lower, and the score change with both changes against `medium` effort moves from 1.2 to 0.2 points lower. The agents used a search tool and a fetch tool that the evaluation harness hosts over a pinned web index. Those tools set part of the time, and yours will run at a different speed, so the page gives time as a ratio between configurations, not in minutes. Time is the wall-clock time per task, from the first request to the last request on any agent, minus the estimated time spent waiting to retry requests after rate-limit or overload errors. Those errors came from the test account's shared limits. All configurations of a set started together. The slower ones finished hours later, so part of their time ran under different load. Each task's cost is its requests priced at public list prices, with prompt caching billed as it would be for a customer who sets a cache breakpoint at the end of each request and uses the 5-minute cache lifetime, for model tokens only. The harness's tools add no charges. Score changes are paired differences over tasks, with 95% bootstrap intervals. A change counts as inside the margin when its interval stays within 1.5 points on DRACO and 2.5 points on HLE. Anthropic set those margins before the runs. Claude Opus 5 grades the answers. Against each set's own grader, Opus 5 scored 1.9 to 2.4 points higher on DRACO, 2.2 to 2.9 points lower on HLE (Opus 5 graded 495 of the 500 questions, and the benchmark's grader graded all 500), and 1.3 to 2.0 points lower on the physics set, whose own grader also uses the expert reference solutions, in every configuration. The two graders agree on the direction of every change.
84122. **HLE:** Phan et al., "Humanity's Last Exam," arXiv:2501.14249, 2025. Expert-written questions with exact answers, graded against the reference answers. Measured on the first 500 questions, with the benchmark's own sources blocked from search, and the same setup as reference 21. Each configuration made three attempts at each question, run September 8 to 10, 2026. Claude Opus 5 compares each answer with the reference answer, with adaptive thinking on, as it is by default. The judge graded 495 of the 500 questions in every configuration, and the scores cover those 495. For the other 5, the grading request was over the judge's 1M-token limit. An attempt that hit the four-hour limit was run again, and the new attempt counts, so every configuration has all 1,500 attempts. Scoring the 5 ungraded questions as 0, as the benchmark's own scoring would, changes no finding.
84223. **Physics set:** An internal set of 70 research-level physics problems, adapted from the public CritPt benchmark: Zhu et al., "Probing the Critical Point (CritPt) of AI Reasoning: a Frontier Physics Research Benchmark," arXiv:2509.26574, 2025. Expert reviewers corrected the problem statements. Claude Opus 5 grades each answer against expert reference solutions that aren't public, so the scores can't be compared with published results. The score is the mean grade over a problem's attempts, averaged over problems. Measured on all 70 problems, four attempts per problem, run September 8 to 9, 2026. Every agent had a Python tool, a shell, and a file editor in a sandbox container with no network access, and no search or fetch tools. Otherwise the setup is that of reference 21. No score margin was set for the physics set before the runs, so the page gives its score changes with their 95% intervals and doesn't describe them as inside a margin.
83821. **DRACO:** Perplexity, "DRACO: a Cross-Domain Benchmark for Deep Research Accuracy, Completeness, and Objectivity," arXiv:2602.11685, 2026. Its 100 research tasks across 10 domains are graded against expert-written rubrics of about 40 weighted criteria each, and the score is the weighted share of criteria met, from 0 to 100. Every configuration ran on the Claude API with Claude Opus 5.5, the default adaptive thinking, the production safety classifiers on, and `max_tokens` at 128,000 with streaming: a single agent at `medium` effort (the model's default) and at `low`, the single agent at `medium` with the sentence and the clock, and a team at `medium` with and without them. The team is a lead agent that can start helper agents of the same model through a tool, with no cap on their number. With the changes, every agent had the sentence and the clock in the form that [Show the model elapsed time](https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence#show-the-model-elapsed-time) describes. Each configuration made three attempts at each task, with a four-hour limit per attempt, run September 24, 2026, and all configurations of a set started together. The agents used search and fetch tools that the evaluation harness hosts over an Anthropic web index, and Python and a shell in a sandbox with no network access. Those tools set part of the time, and yours will run at a different speed, so the page gives time as a ratio between configurations, not in minutes. Time is the wall-clock time of an attempt, from its first request to the end of the last request by any agent, including tool runs, averaged over a task's attempts. A typical-task figure is the median, over tasks, of each task's ratio between two configurations. Each task's cost is its requests priced at Claude Opus 5.5's public list prices, with prompt caching billed as it would be for a customer who sets a cache breakpoint at the end of each request and uses the 5-minute cache lifetime. Each request reads the previous request's prompt from the cache and writes the rest. An attempt's first request, and any request that starts more than 5 minutes after the one before it, writes its whole prompt. Costs cover model tokens only; the harness's tools add no charges. All intervals are 95% bootstrap intervals over tasks, and score changes are paired differences over tasks. Claude Opus 5 grades the answers, so Claude Opus 5.5 doesn't grade its own work, and each answer's score averages five judging runs. A production safety classifier stopped three attempts in each configuration, all on one task, and those attempts score 0; leaving that task out changes no finding. The runs also passed each agent's tool use through an Anthropic-internal safety check that customer requests don't have, which adds an unmeasured amount of time to each request in every configuration. On DRACO, the single agent without the changes made about twice as many requests, and the team about a third more, so the check probably makes the DRACO time savings look slightly larger.
83922. **HLE:** Phan et al., "Humanity's Last Exam," arXiv:2501.14249, 2025. Expert-written questions with exact answers, graded against the reference answers. Measured on the first 500 questions of the September 10, 2025, release, images included, with the benchmark's own sources blocked from search, and the same setup as reference 21. Each configuration made three attempts at each question, run September 24, 2026. Claude Opus 5 compares each answer with the reference answer, using the benchmark's published judge prompt, and the majority of three judgings counts. The scores cover 493 questions in every configuration. For five of the others, the grading request was over the judge's 1M-token limit, and the other two are left out because the run of the single agent without the changes stopped before three of its attempts on them finished. Time and cost ratios cover 492 questions for the single agent and 491 for the team, because one or two questions have no timing. A production safety classifier stopped 3% to 4% of each configuration's attempts, and those attempts score 0; leaving them out changes no finding. With a second grader, Claude Opus 4.6, the single agent's score with the changes was 1.9 points lower (95% interval 0.2 to 3.7 lower), where the Claude Opus 5 judge shows no clear change.
84023. **Physics set:** An internal set of 70 research-level physics problems, adapted from the public CritPt benchmark: Zhu et al., "Probing the Critical Point (CritPt) of AI Reasoning: a Frontier Physics Research Benchmark," arXiv:2509.26574, 2025. Expert reviewers corrected the problem statements. Claude Opus 4.6 grades each answer with partial credit, using the set's grading prompt, against expert reference solutions that aren't public, so the scores can't be compared with published results. The score is the mean grade over a problem's attempts, averaged over problems, in points out of 100. Measured on all 70 problems, four attempts per problem, run September 24, 2026. Every agent had a Python tool, a shell, and a file editor in a sandbox container with no network access, and no search or fetch tools. No safety classifier stopped an attempt on the physics set. Otherwise the setup is that of reference 21. The single agent's whole average time saving comes from one problem, on which the agent without the changes ran code for about half an hour per attempt; without that problem, its average time is about the same with and without the changes.
843841
844842## Next steps
845843
